
BTW, DOWNLOAD part of Itcertkey Data-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1ET6Kp9sLqMY_oM6P-XI-HTBwWVhExu6R
Itcertkey regularly updates AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) practice exam material to ensure that it keeps in line with the test. In the same way, Itcertkey provides a free demo before you purchase so that you may know the quality of the AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) dumps. Similarly, the Itcertkey AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) practice test creates an actual exam scenario on each and every step so that you may be well prepared before your actual AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) examination time. Hence, it saves you time and money.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Security and Governance | 18% | - Enforce compliance and data governance
- Encrypt data at rest and in transit - Implement access control and authentication
|
| Topic 2: Data Ingestion and Transformation | 34% | - Transform and enrich data
|
| Topic 3: Data Operations and Support | 22% | - Automate operational tasks - Backup, restore, and disaster recovery - Ensure reliability and scalability - Monitor and troubleshoot data pipelines
|
| Topic 4: Data Store Management | 26% | - Design and implement data storage solutions
- Manage data lifecycle and storage tiers |
>> New Exam Data-Engineer-Associate Materials <<
The learning material is available in three different easy-to-use forms. The first one is a PDF form. The students can save the Data-Engineer-Associate questions by taking out their prints or can access them on their smartphones, tablets, and laptops. The PDF form can be used anywhere anytime and is essential for applicants who like to learn from their smart devices. The second form is AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) web-based practice test which can be taken from browsers.
NEW QUESTION # 93
A manufacturing company collects sensor data from its factory floor to monitor and enhance operational efficiency. The company uses Amazon Kinesis Data Streams to publish the data that the sensors collect to a data stream. Then Amazon Kinesis Data Firehose writes the data to an Amazon S3 bucket.
The company needs to display a real-time view of operational efficiency on a large screen in the manufacturing facility.
Which solution will meet these requirements with the LOWEST latency?
Answer: C
Explanation:
This solution will meet the requirements with the lowest latency because it uses Amazon Managed Service for Apache Flink to process the sensor data in real time and write it to Amazon Timestream, a fast, scalable, and serverless time series database. Amazon Timestream is optimized for storing and analyzing time series data, such as sensor data, and can handle trillions of events per day with millisecond latency. By using Amazon Timestream as a source, you can create an Amazon QuickSight dashboard that displays a real-time view of operational efficiency on a large screen in the manufacturing facility. Amazon QuickSight is a fully managed business intelligence service that can connect to various data sources, including Amazon Timestream, and provide interactive visualizations and insights123.
The other options are not optimal for the following reasons:
* A. Use Amazon Managed Service for Apache Flink (previously known as Amazon Kinesis Data Analytics) to process the sensor data. Use a connector for Apache Flink to write data to an Amazon Timestream database. Use the Timestream database as a source to create a Grafana dashboard. This option is similar to option C, but it uses Grafana instead of Amazon QuickSight to create the dashboard.
Grafana is an open source visualization tool that can also connect to Amazon Timestream, but it requires additional steps to set up and configure, such as deploying a Grafana server on Amazon EC2, installing the Amazon Timestream plugin, and creating an IAM role for Grafana to access Timestream.
These steps can increase the latency and complexity of the solution.
* B. Configure the S3 bucket to send a notification to an AWS Lambda function when any new object is created. Use the Lambda function to publish the data to Amazon Aurora. Use Aurora as a source to create an Amazon QuickSight dashboard. This option is not suitable for displaying a real-time view of operational efficiency, as it introduces unnecessary delays and costs in the data pipeline. First, the sensor data is written to an S3 bucket by Amazon Kinesis Data Firehose, which can have a buffering interval of up to 900 seconds. Then, the S3 bucket sends a notification to a Lambda function, which can incur additional invocation and execution time. Finally, the Lambda function publishes the data to Amazon Aurora, a relational database that is not optimized for time series data and can have higher storage and performance costs than Amazon Timestream .
* D. Use AWS Glue bookmarks to read sensor data from the S3 bucket in real time. Publish the data to an Amazon Timestream database. Use the Timestream database as a source to create a Grafana dashboard.
This option is also not suitable for displaying a real-time view of operational efficiency, as it uses AWS Glue bookmarks to read sensor data from the S3 bucket. AWS Glue bookmarks are a feature that helps AWS Glue jobs and crawlers keep track of the data that has already been processed, so that they can resume from where they left off. However, AWS Glue jobs and crawlers are not designed for real-time data processing, as they can have a minimum frequency of 5 minutes and a variable start-up time.
Moreover, this option also uses Grafana instead of Amazon QuickSight to create the dashboard, which can increase the latency and complexity of the solution .
References:
* 1: Amazon Managed Streaming for Apache Flink
* 2: Amazon Timestream
* 3: Amazon QuickSight
* : Analyze data in Amazon Timestream using Grafana
* : Amazon Kinesis Data Firehose
* : Amazon Aurora
* : AWS Glue Bookmarks
* : AWS Glue Job and Crawler Scheduling
NEW QUESTION # 94
A company uses Amazon S3 to store data and Amazon QuickSight to create visualizations.
The company has an S3 bucket in an AWS account named Hub-Account. The S3 bucket is encrypted with an AWS Key Management Service (AWS KMS) key. The company's Amazon QuickSight instance is in a separate AWS account named BI-Account.
The company updates the S3 bucket policy to grant access to the QuickSight service role. The company wants to enable cross-account access to allow QuickSight to interact with the S3 bucket.
Which combination of steps will meet this requirement? (Select TWO)
Answer: C,D
Explanation:
For Amazon QuickSight to access data in an Amazon S3 bucket that is encrypted with an AWS KMS key in a different AWS account, two distinct permissions are required: access to the S3 bucket and access to the KMS key.
First, the QuickSight service role in the BI-Account must be granted permission to access the S3 bucket. This is accomplished by adding the S3 bucket as a resource that the QuickSight service role can access and configuring the bucket policy in the Hub-Account to trust that role. Without explicit S3 permissions, QuickSight cannot read the objects.
Second, because the S3 bucket uses SSE-KMS encryption, QuickSight must also be authorized to use the KMS key. This requires adding an IAM policy to the QuickSight service role that allows kms:Decrypt and related permissions on the KMS key. Without KMS permissions, S3 access will fail even if the bucket policy allows access.
AWS RAM cannot be used to share S3 buckets, encryption of network connections is irrelevant to KMS permissions, and adding the KMS key as a "resource" alone is not sufficient without IAM permissions.
Therefore, Options B and D are correct.
NEW QUESTION # 95
A company stores CSV files in an Amazon S3 bucket. A data engineer needs to process the data in the CSV files and store the processed data in a new S3 bucket.
The process needs to rename a column, remove specific columns, ignore the second row of each file, create a new column based on the values of the first row of the data, and filter the results by a numeric value of a column.
Which solution will meet these requirements with the LEAST development effort?
Answer: B
Explanation:
The requirement involves transforming CSV files by renaming columns, removing rows, and other operations with minimal development effort. AWS Glue DataBrew is the best solution here because it allows you to visually create transformation recipes without writing extensive code.
* Option D: Use AWS Glue DataBrew recipes to read and transform the CSV files.DataBrew provides a visual interface where you can build transformation steps (e.g., renaming columns, filtering rows, creating new columns, etc.) as a "recipe" that can be applied to datasets, making it easy to handle complex transformations on CSV files with minimal coding.
Other options (A, B, C) involve more manual development and configuration effort (e.g., writing Python jobs or creating custom workflows in Glue) compared to the low-code/no-code approach of DataBrew.
References:
* AWS Glue DataBrew Documentation
NEW QUESTION # 96
A data engineer maintains a materialized view that is based on an Amazon Redshift database. The view has a column named load_date that stores the date when each row was loaded.
The data engineer needs to reclaim database storage space by deleting all the rows from the materialized view.
Which command will reclaim the MOST database storage space?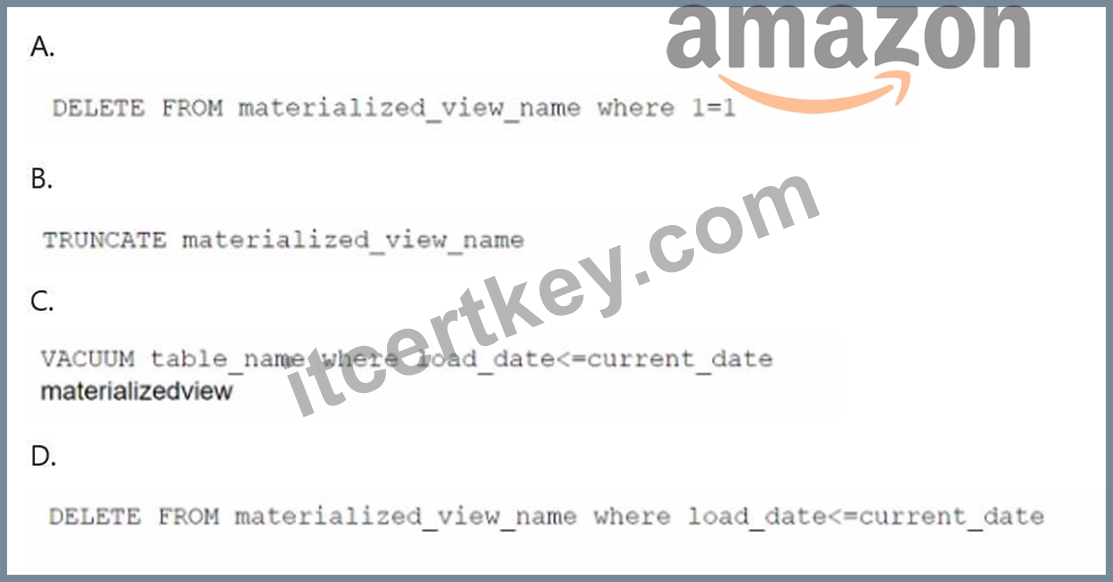
Answer: B
Explanation:
To reclaim the most storage space from a materialized view in Amazon Redshift, you should use a DELETE operation that removes all rows from the view. The most efficient way to remove all rows is to use a condition that always evaluates to true, such as 1=1. This will delete all rows without needing to evaluate each row individually based on specific column values like load_date.
* Option A: DELETE FROM materialized_view_name WHERE 1=1;This statement will delete all rows in the materialized view and free up the space. Since materialized views in Redshift store precomputed data, performing a DELETE operation will remove all stored rows.
Other options either involve inappropriate SQL statements (e.g., VACUUM in option C is used for reclaiming storage space in tables, not materialized views), or they don't remove data effectively in the context of a materialized view (e.g., TRUNCATE cannot be used directly on a materialized view).
References:
* Amazon Redshift Materialized Views Documentation
* Deleting Data from Redshift
NEW QUESTION # 97
A data engineer is optimizing query performance in Amazon Athena notebooks that use Apache Spark to analyze large datasets that are stored in Amazon S3. The data is partitioned. An AWS Glue crawler updates the partitions.
The data engineer wants to minimize the amount of data that is scanned to improve efficiency of Athena queries.
Which solution will meet these requirements?
Answer: B
NEW QUESTION # 98
......
If you want to pass your exam and get the certification in a short time, choosing the suitable Data-Engineer-Associate exam questions are very important for you. You must pay more attention to the Data-Engineer-Associate study materials. In order to provide all customers with the suitable study materials, a lot of experts from our company designed the Data-Engineer-Associate Training Materials. We can promise that if you buy our Data-Engineer-Associate exam questions, it will be very easy for you to pass your Data-Engineer-Associate exam and get the certification.
Latest Data-Engineer-Associate Dumps Pdf: https://www.itcertkey.com/Data-Engineer-Associate_braindumps.html
2026 Latest Itcertkey Data-Engineer-Associate PDF Dumps and Data-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1ET6Kp9sLqMY_oM6P-XI-HTBwWVhExu6R