Many learners feel that they have choice phobia disorder whiling they are choosing reliable AI-200 test guide on the internet. If so you can choose our AI-200 certification materials. We are the leading position in this field and our company is growing faster and faster because of our professional and high pass-rate AI-200 Exam Torrent materials. Every year more than thousands of candidates choose our reliable AI-200 test guide materials we help more than 98% of candidates clear exams, we are proud of our AI-200 exam questions.
| Section | Objectives |
|---|---|
| Topic 1: Implement Azure AI solutions | - Implement generative AI solutions using Azure OpenAI - Implement computer vision solutions - Implement natural language processing solutions - Implement knowledge mining with Azure AI Search |
| Topic 2: Implement and monitor AI workloads | - Monitor performance and troubleshoot issues - Deploy AI models and services |
| Topic 3: Plan and manage Azure AI solutions | - Select appropriate Azure AI services - Plan security and compliance requirements - Monitor and optimize AI solutions |
>> Pass4sure AI-200 Pass Guide <<
It can be said that our AI-200 study materials are the most powerful in the market at present, not only because our company is leader of other companies, but also because we have loyal users. AI-200 study materials are not only the domestic market, but also the international high-end market. We are studying some learning models suitable for high-end users. Our research materials have many advantages. Now, I will briefly introduce some details about our AI-200 Study Materials for your reference.
NEW QUESTION # 142
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
Drag and Drop Question
You need to implement the semantic retrieval workflow for the recommendation engine to meet the technical and performance requirements of Fabrikam Inc.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.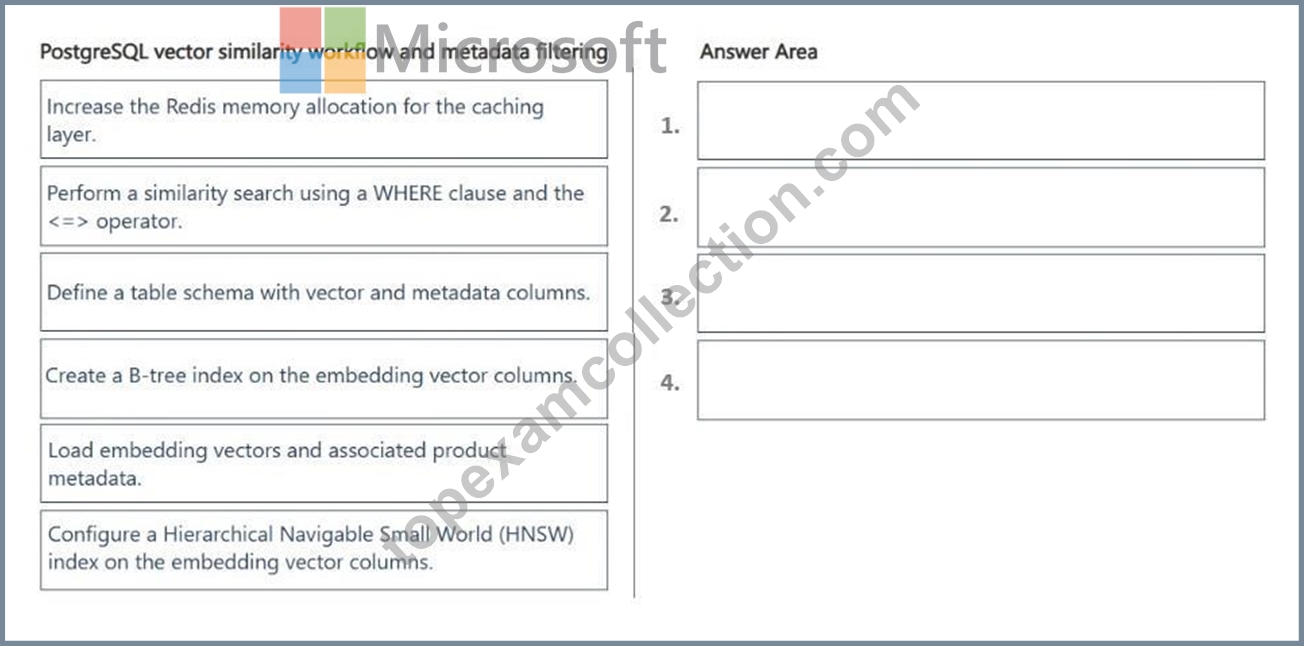
Answer:
Explanation: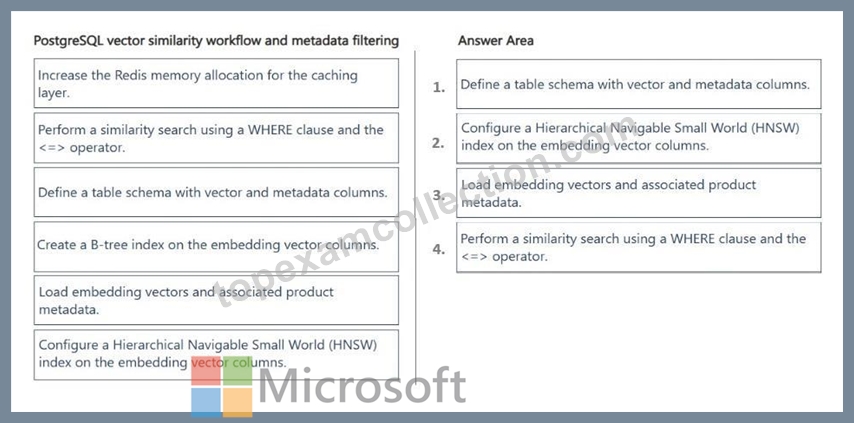
Explanation:
Scenario:
Current: The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Step 1: Define Table Schema with vector and metadata columns
Schema configuration: Establish the PostgreSQL table structure using the pgvector extension to store both the product metadata and the high-dimensional embedding vectors.
Step 2: Configure a Hierachical Navigable Small World (HNSW) index on the embedding vector columns Configure Vector Index HNSW indexing: Implement a Hierarchical Navigable Small World (HNSW) index rather than a B- tree index, as standard B-tree indexing cannot index multi-dimensional vector embeddings for similarity searches.
An HNSW (Hierarchical Navigable Small World) index is the correct choice for the embedding vector columns in this scenario, while a B-tree index is entirely unsuited for vector similarity search.
Step 3: Load embedding vectors and associated product metadata
Populate Database
Data ingestion: Load the pre-computed embedding vectors along with their corresponding product metadata into the newly indexed table.
Step 4: Perform a similarity search using a WHERE clause and the <=> operator Query Similar Items Similarity search: Execute vector similarity queries using the <=> operator (which denotes cosine distance in pgvector) to find and return the closest product recommendations.
Reference:
https://mobisoftinfotech.com/resources/blog/enhancing-rag-generative-ai-postgresql-hnsw-indexes
NEW QUESTION # 143
Hotspot Question
You are developing an event-driven system that reacts to new or updated documents in Azure Cosmos DB for NoSQL.
The application must process new or updated documents as they appear in the container by using a change feed processor. The application must also maintain processor state between runs.
You need to configure the components required for stateful change feed processing.
Which components should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.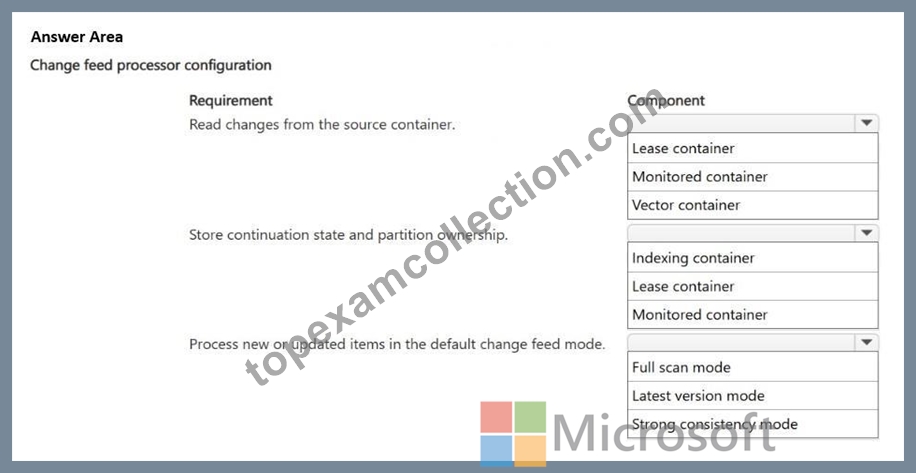
Answer:
Explanation: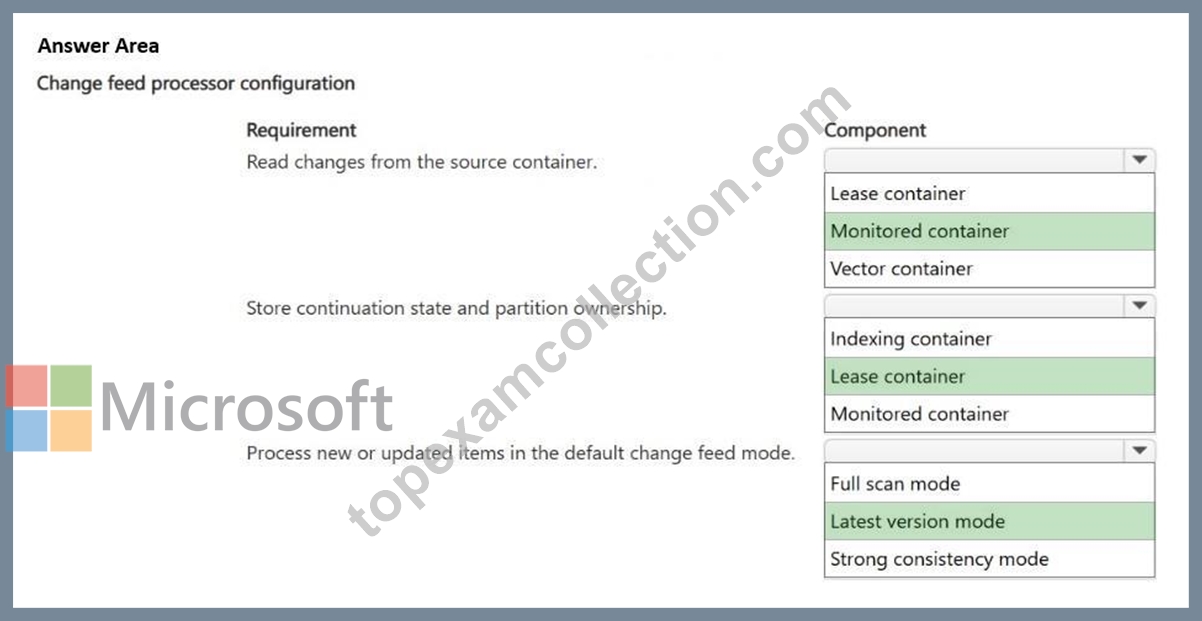
Explanation:
Box 1: Monitored container.
To read new or updated documents from the source, you need to configure the monitored container. The change feed processor listens to this container for any changes and sequentially retrieves the sorted list of modified documents.
Box 2: Lease Container
Lease Container is a separate container that acts as state storage. It maintains processing checkpoints across multiple worker instances, which allows your system to resume operations from where it left off.
Box 3: Latest version mode
To process new or updated documents, you need to use the Latest version mode of the change feed.
Latest version mode is the default change feed mode. It provides only the most recent version of each changed item (inserts and updates) in the exact order they were modified. If an item is updated multiple times in quick succession, the processor will only receive the final state after the latest update.
Reference:
https://learn.microsoft.com/en-us/azure/cosmos-db/change-feed-processor
NEW QUESTION # 144
You are developing an Azure Function that calls external APIs by providing an access token for the API. The access token is stored in a secret named token in an Azure Key Vault named mykeyvault. You need to ensure the Azure Function can access the token. Which value should you store in the Azure Functions app configuration?
Answer: B
Explanation:
To securely provide the Azure Function with access to the secret without exposing it in the application code, you should store a Key Vault reference syntax in the Azure Functions app configuration settings.
The exact value you must store depends on whether you wish to target the latest version of the secret automatically or a specific, pinned version.
Target the latest version (Recommended)
Use this syntax to ensure your Function App always fetches the most recent version of the token:
@Microsoft.KeyVault(VaultName= mykeyvault;SecretName=token)
Reference:
https://learn.microsoft.com/en-us/azure/key-vault/general/apps-api-keys-secrets
NEW QUESTION # 145
An ACA app processes messages from an Azure Storage queue.
The app must scale automatically based on messages in a specific Azure Storage queue by using a Kubernetes Event-driven Autoscaler (KEDA) custom scale rule.
You need to configure the required scale rule values.
Which two values should you configure? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: B,C
Explanation:
[A]
QeueName: The exact name of the specific Azure Storage queue your app is polling is required.
[C]
Why Trigger Type is Required
When configuring a custom scale rule in Azure Container Apps (ACA), the platform utilizes KEDA underneath. Because a custom rule can connect to many different event sources (such as Kafka, Redis, or Azure Storage), you must explicitly define the Trigger type (e.g., azure-queue) so KEDA knows which specific scaler to initiate.
Reference:
https://techcommunity.microsoft.com/blog/fasttrackforazureblog/container-apps-a-practical-scaling-with-azure-queue-scale-rule/3722075
NEW QUESTION # 146
A recommendation system stores 1 million embeddings in Azure Database for PostgreSQL During peak hours. P95 similarity-query latency increases, and the cache hit ratio drops significantly.
You suspect that the vector index working set no longer fits in memory, resulting in more disk reads.
You need to scale server resources and validate the outcome.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.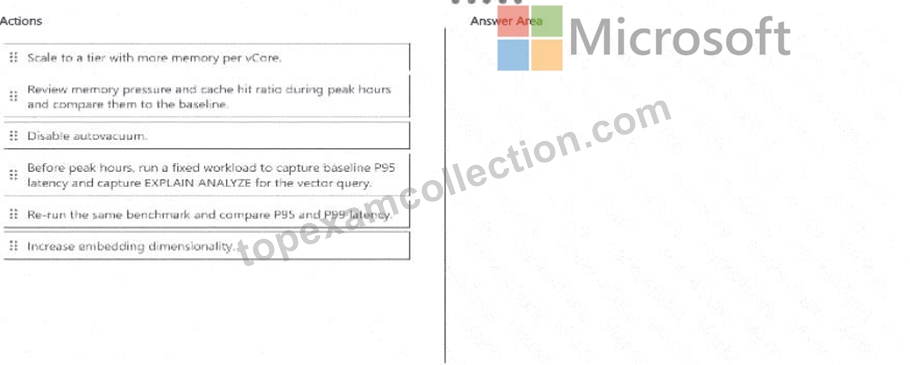
Answer:
Explanation: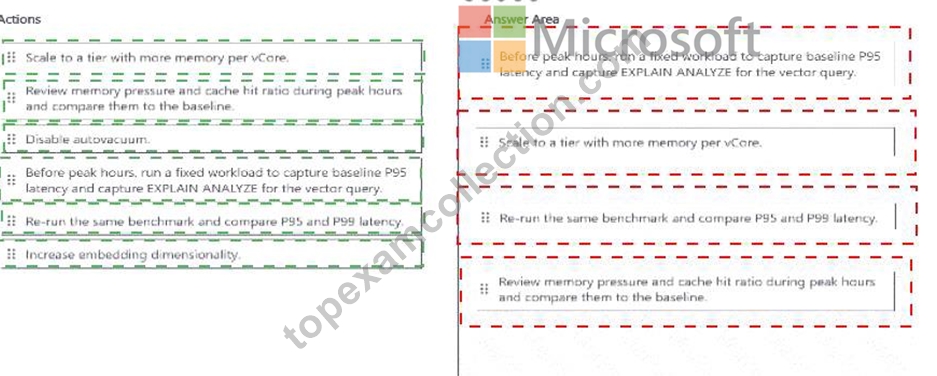
Explanation: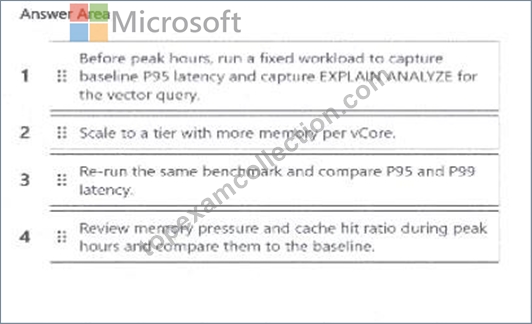
NEW QUESTION # 147
......
TopExamCollection customizable practice exams (desktop and web-based) help students know and overcome their mistakes. The customizable Microsoft AI-200 practice test means that the users can set the Developing AI Cloud Solutions on Azure (AI-200) Dumps and time according to their needs so that they can feel the real-based AI-200 exam scenario and learn to handle the pressure.
New AI-200 Test Guide: https://www.topexamcollection.com/AI-200-vce-collection.html