DOWNLOAD the newest BraindumpsPrep DP-800 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1GPXGeVwF0BPJ4fAjRJzVMyvsUZDInxrH
If you are going to purchasing the DP-800 exam bootcamp online, you may pay more attention to the pass rate. With the pass rate more than 98%, our DP-800 exam materials have gained popularity in the international market. And we have received many good feedbacks from our customers. In addition, we offer you free demo to have a try before buying DP-800 Exam Braindumps, so that you can have a deeper understanding of what you are going to buy. You can also enjoy free update for one year, and the update version for DP-800 will be sent to your email automatically.
| Section | Weight | Objectives |
|---|---|---|
| Design and develop database solutions (35–40%) | 35-40% | - Design and implement programmability objects
|
| Secure, optimize, and deploy database solutions (35–40%) | 35-40% | - Implement data platform resources
|
| Implement AI capabilities in database solutions (25–30%) | 25-30% | - Integrate Azure AI services
|
We can say that how many the DP-800 certifications you get and obtain qualification certificates, to some extent determines your future employment and development, as a result, the DP-800 exam guide is committed to helping you become a competitive workforce, let you have no trouble back at home. Actually, just think of our DP-800 Test Prep as the best way to pass the exam is myopic. They can not only achieve this, but ingeniously help you remember more content at the same time.
NEW QUESTION # 31
You have an Azure SQL database that contains a table named dbo.ManualChunks.
dbo.ManualChunks contains product manuals.
A retrieval query already returns the top five matching chunks as nvarchar (max)text.
You need to call an Azure OpenAI REST endpoint for chat completions. The request body must include both the user question and the retrieved chunks.
You write the following Transact-SQL code.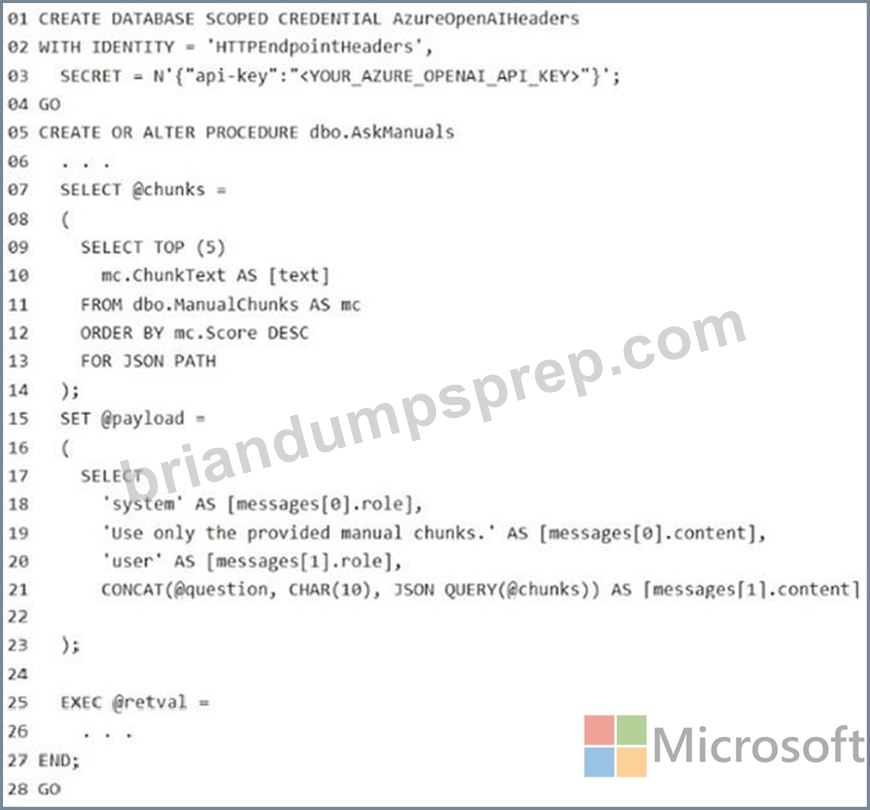
What should you insert at line 22?
Answer: A
Explanation:
To construct a payload for the Azure OpenAI REST API within Azure SQL, you can use a Common Table Expression (CTE) to structure the messages and then collapse them into a single JSON object.
T-SQL Payload Generation
Key Implementation Details
Message Hierarchy: Azure OpenAI requires a messages array. By nesting a subquery with FOR JSON PATH inside the main SELECT, SQL Server creates the required JSON array of objects.
JSON Formatting: Using FOR JSON PATH, WITHOUT_ARRAY_WRAPPER on the outer selection ensures the root of your @payload is a clean JSON object {...} rather than a single- element array [{...}].
Context Injection: It is standard practice to prepend the retrieved manual chunks to the system message or a dedicated user message to provide the model with the necessary grounding data.
Assuming you have your retrieved chunks concatenated into a single @Context variable and the user's input in @UserQuestion, use the following logic:
DECLARE @UserQuestion NVARCHAR(MAX) = 'How do I reset the device?';
DECLARE @Context NVARCHAR(MAX) = 'Manual Chunk 1... Manual Chunk 2...'; -- Your top 5 chunks DECLARE @payload NVARCHAR(MAX);
-- Define the message structure for Chat Completions
WITH ChatMessages AS (
SELECT 'system' AS [role],
'You are a helpful assistant. Use these manual excerpts: ' + @Context AS [content] UNION ALL SELECT 'user' AS [role],
@UserQuestion AS [content]
)
-- Generate the final JSON body
SELECT @payload = (
SELECT
(SELECT [role], [content] FROM ChatMessages FOR JSON PATH) AS [messages],
0.7 AS [temperature],
800 AS [max_tokens]
FOR JSON PATH, WITHOUT_ARRAY_WRAPPER
);
-- Resulting @payload is now ready for sp_invoke_external_rest_endpoint PRINT @payload; Reference:
https://devblogs.microsoft.com/azure-sql/using-openai-rest-endpoints-with-azure-sql-database
NEW QUESTION # 32
You need to enable similarity search to provide the analysts with the ability to retrieve the most relevant health summary reports. The solution must minimize latency.
What should you include in the solution?
Answer: D
Explanation:
The correct answer is D because the requirement is to enable similarity search over embedding vectors and to minimize latency . Microsoft documents that CREATE VECTOR INDEX is specifically used to create an index on vector data for approximate nearest neighbor (ANN) search , which is designed to accelerate vector similarity queries compared to exact k-nearest-neighbor scans.
This matches the scenario exactly. The VehicleHealthSummary table already includes an Embeddings (vector (1536)) column. In Microsoft SQL platforms, embeddings are stored in vector columns and queried for semantic similarity. To improve performance and reduce response time, Microsoft recommends a vector index , not a regular B-tree nonclustered index and not a full-text index. A vector index is purpose-built for finding the most similar vectors efficiently.
The other options are not appropriate:
* A would require manual comparison logic and would increase latency rather than minimize it.
* B is incorrect because a standard nonclustered index is not the index type used for vector similarity operations.
* C is incorrect because full-text indexes are for textual token-based search, not numeric vector embeddings.
Microsoft's current documentation is explicit that vector indexes support approximate nearest neighbor search , and that the optimizer can use the ANN index automatically for vector queries. That is the exam- aligned design choice when the goal is fast retrieval of the most relevant health summary reports from an embeddings column.
NEW QUESTION # 33
You have an Azure SQL database named ProductsDB.
You deploy Data API builder (DAB) to Azure Container Apps by using the [mcr.microsoft.com/azure- databases/data-api-builder:latest](https://mcr.microsoft.com/azure-databases/data-api-builder:latest) image.
The container app has the following configurations:
Secrets: mssql-connection-string, dab-config-base64
Environment variables:
MSSQL_CONNECTION_STRING=secretref:mssql-connection-string
DAB_CONFIG_BASE64=secretref:dab-config-base64
Ingress: External on port 5000
Users report that the /health endpoint returns a healthy response, but all requests that query an entity named Products fail and generate a connection error.
You confirm that the SQL login in the connection string is correct and the database exists.
You need to ensure that the container app can establish connections to the Azure SQL logical server without changing the container app deployment settings or the DAB configuration file.
What should you do on the Azure SQL logical server?
Answer: C
NEW QUESTION # 34
You have an Azure SQL database that stores sales data and contains tables named Sales and Products . Sales contains three columns named SalesDate , ProductKey , and TotalSale .
Sales is 10 TB and is loaded nightly by using a batch process. Most reporting queries scan large portions of Sales , filter on SalesDate or ProductKey , and use SUM() to aggregate TotalSale .
Products is relatively small and is used primarily for point lookups and joins to Sales .
You need to recommend which indexes to create to optimize the reporting queries. The solution must minimize storage requirements.
Which type of index should you recommend for each table? To answer, drag the appropriate index types to the correct tables. Each index type may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.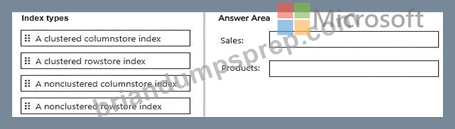
Answer:
Explanation: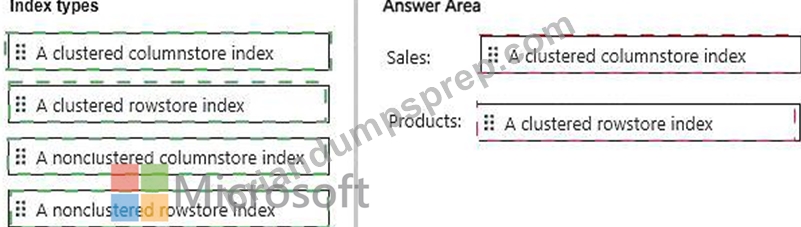
Explanation:
* Sales # A clustered columnstore index
* Products # A clustered rowstore index
For Sales , the correct choice is a clustered columnstore index . Microsoft identifies clustered columnstore indexes as the standard storage choice for large fact tables and analytical/data-warehouse workloads . The Sales table is 10 TB, loaded in nightly batches, and its reporting queries scan large portions of the table and perform aggregations such as SUM(TotalSale) . Those are exactly the workload characteristics that benefit from columnstore storage, batch-mode execution, aggregate pushdown, and high compression. Microsoft also notes that clustered columnstore indexes can provide substantial storage reduction compared with traditional uncompressed rowstore structures, which directly supports the requirement to minimize storage requirements .
For Products , the correct choice is a clustered rowstore index . Microsoft states that rowstore B-tree indexes perform best for point lookups, equality searches, and small-range retrieval , whereas columnstore is optimized for large analytical scans. Since Products is relatively small and primarily supports point lookups and joins to Sales , a rowstore structure is the better fit.
A nonclustered columnstore index would retain the underlying rowstore and add another compressed copy of selected columns, increasing storage. That is more appropriate for real-time analytics over an OLTP table, not for this dedicated large analytical fact table.
NEW QUESTION # 35
Vou have a Microsoft Fabric workspace named Workspace1 that contains a SQL database named SalesDB and an API for GraphQL tern named SalesApi.
You have a Microsoft Entra group named SqlUsers.
From Workspace1, you assign permission to SalesApi as shown in the following exhibit.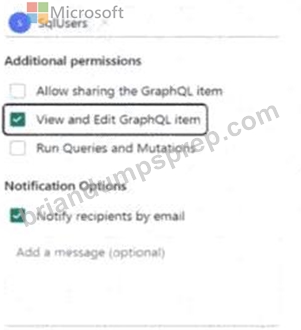
The connection to SalesDB has the connectivity option configured as shown in the following exhibit.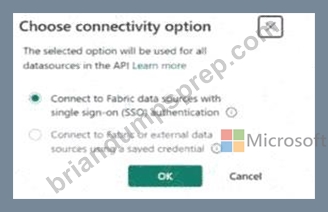
SqlUsers has the Viewer role for Workspace1.
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.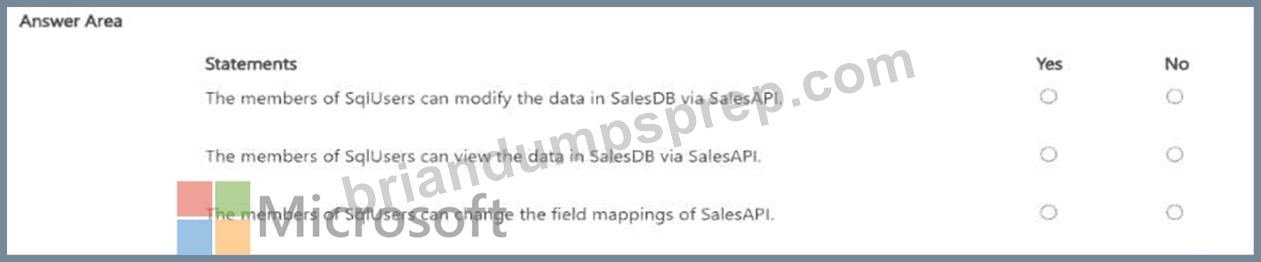
Answer:
Explanation: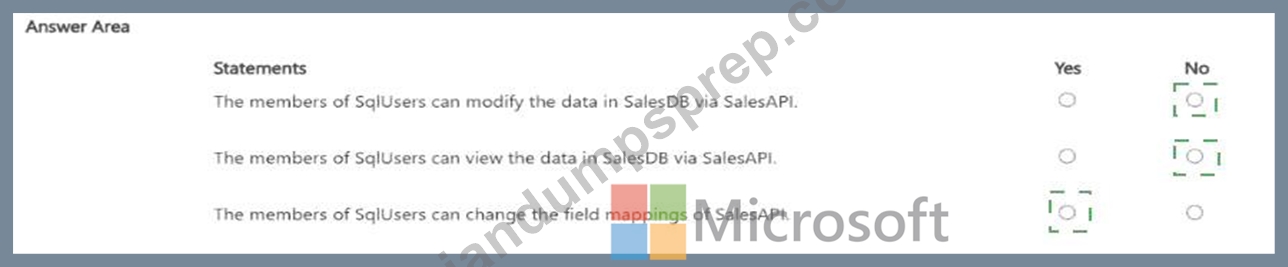
Explanation:
* The members of SqlUsers can modify the data in SalesDB via SalesApi. # No
* The members of SqlUsers can view the data in SalesDB via SalesApi. # No
* The members of SqlUsers can change the field mappings of SalesApi. # Yes For both viewing and modifying data through SalesApi, the key missing permission is Run Queries and Mutations . Microsoft's Fabric GraphQL documentation states that callers need Execute permissions for the GraphQL API , which correspond to the Run Queries and Mutations option, and with SSO connectivity they also need appropriate permissions on the underlying data source. In the exhibit, SqlUsers has View and Edit GraphQL item selected, but Run Queries and Mutations is not selected, so members cannot query or mutate data through the API.
The third statement is Yes because the group was explicitly granted View and Edit GraphQL item . That permission is the one that allows users to open and modify the GraphQL item itself, including schema-related configuration such as field mappings in the API item. The workspace Viewer role does not by itself grant query execution through the API, but the direct GraphQL item permission shown does allow editing the item.
NEW QUESTION # 36
......
To help applicants prepare successfully according to their styles, we offer three different formats of Developing AI-Enabled Database Solutions (DP-800) exam dumps. These formats include desktop-based Developing AI-Enabled Database Solutions (DP-800) practice test software, web-based Microsoft DP-800 Practice Exam, and Building Developing AI-Enabled Database Solutions (DP-800) dumps pdf format. Our customers can download a free demo to check the quality of DP-800 practice material before buying.
DP-800 Latest Braindumps Ppt: https://www.briandumpsprep.com/DP-800-prep-exam-braindumps.html
P.S. Free 2026 Microsoft DP-800 dumps are available on Google Drive shared by BraindumpsPrep: https://drive.google.com/open?id=1GPXGeVwF0BPJ4fAjRJzVMyvsUZDInxrH