Microsoft DP-750専門トレーリング & DP-750勉強時間

多分、DP-750テスト質問の数が伝統的な問題の数倍である。Microsoft DP-750試験参考書は全ての知識を含めて、全面的です。そして、DP-750試験参考書の問題は本当の試験問題とだいたい同じことであるとわかります。DP-750試験参考書があれば,ほかの試験参考書を勉強する必要がないです。
Microsoft DP-750 Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Topic 1: Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
- 1. Deploy workloads using Databricks Asset Bundles
- 2. Implement CI/CD processes
- 3. Integrate Git-based development workflows
- 4. Optimize workload performance and reliability
- 5. Maintain production data engineering solutions
- 6. Monitor and troubleshoot pipelines
- 7. Create and manage Lakeflow Jobs
|
| Topic 2: Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
- 1. Manage catalogs, schemas, and tables
- 2. Configure Unity Catalog
- 3. Implement data-sharing capabilities
- 4. Manage data lineage and auditing
- 5. Implement access control and permissions
|
| Topic 3: Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
- 1. Configure workspace settings
- 2. Manage Databricks runtimes
- 3. Configure networking and connectivity
- 4. Configure compute resources and clusters
|
| Topic 4: Prepare and process data | 30-35% | - Ingest and transform data
- 1. Apply medallion architecture patterns
- 2. Use Auto Loader and batch ingestion
- 3. Implement data quality controls
- 4. Transform data using SQL and Python
- 5. Implement Delta Lake tables
- 6. Implement streaming data processing
- 7. Model and partition data
- 8. Optimize storage and table performance
|
>> Microsoft DP-750専門トレーリング <<
DP-750勉強時間 & DP-750資格練習
Pass4Testは初めて試験を受けるあなたが一回で試験に合格して、認証資格を取ることを保証します。Pass4Testが提供して差し上げたのは高品質のMicrosoftのDP-750「Implementing Data Engineering Solutions Using Azure Databricks」模擬問題集で、あなたがステップバイステップで試験に準備する手順を指導しています。Pass4TestのMicrosoftのDP-750試験問題集は絶対あなたに成功をもたらすことを保証します。Pass4TestのMicrosoftのDP-750認定試験に準備するために色々な方法がありますが、
Microsoft Implementing Data Engineering Solutions Using Azure Databricks 認定 DP-750 試験問題 (Q18-Q23):
質問 # 18
You have an Azure Databricks workspace.
Users report that a Databricks notebook that runs each day takes longer than expected to run.
When reading the Directed Acyclic Graph (DAG), you discover the following issues concerning the Apache Spark stage:
* Most tasks in the stage finish quickly.
* A few tasks in the stage run more slowly.
* The CPU is underutilized at the end of the stage.
* The slow tasks process many more input records.
* The stage is blocked while it waits for the few slow tasks.
What is the root cause of the issues?
- A. skewing
- B. spilling
- C. shuffling
- D. caching
正解:A
質問 # 19
What improves join performance for small lookup tables?
- A. Shuffle join
- B. Broadcast join
- C. Sort merge join
- D. Cartesian join
正解:B
解説:
Broadcast joins send the small table to all worker nodes, avoiding expensive shuffling. This significantly improves performance. Shuffle and sort merge joins are heavier. Cartesian joins are inefficient and generally avoided.
質問 # 20
You need to configure the telemetry pipeline to support the planned changes for pipeline orchestration and address the resiliency issues.
What should you do?
- A. Create three separate jobs and schedule them to run at staggered times.
- B. Create a single Databricks notebook that contains all the ingestion, cleansing, and curation logic in sequential cells.
- C. Use Azure Data Factory to orchestrate three separate Databricks notebook activities and define the task dependencies between each notebook activity.
- D. Use Lakeflow Jobs and define task dependencies between the ingestion, cleansing, and curation tasks.
正解:D
解説:
Lakeflow Jobs provides native orchestration for multi-task Databricks workflows. Separate ingestion, cleansing, and curation tasks can be connected through explicit dependencies, ensuring that each stage starts only after its required upstream work succeeds. Each task can also have independent retry, notification, timeout, and compute settings, directly addressing the pipeline's resiliency requirements. Azure Data Factory could orchestrate notebooks, but it introduces another service when Lakeflow Jobs already provides the required functionality. A single notebook makes failures harder to isolate and can force successful stages to be rerun. Independently scheduled jobs rely on timing assumptions rather than actual task completion and can fail when an upstream stage runs longer than expected. Explicit Lakeflow Jobs dependencies provide reliable execution order and centralized monitoring. Microsoft Learn
質問 # 21
You have an Azure Databricks workspace that is enabled for Unity Catalog You have an Apache Spark Structured Streaming job that writes data to a Delta table.
After the cluster restarts, the streaming job reprocesses previously ingested data You need to prevent the streaming job from reprocessing the data after the cluster restarts.
What should you do?
- A. Increase the trigger interval of the streaming query.
- B. Configure a watermark for the streaming query.
- C. Configure a checkpoint location for the streaming query.
- D. Enable change data feed (CDF) for the target table.
正解:C
解説:
The correct answer is B - configure a checkpoint location.
A checkpoint is the Structured Streaming mechanism for fault tolerance. Databricks writes the committed offset (i.e., how far through the source stream the job has successfully read and processed) to a durable path in ADLS Gen2 or DBFS after each micro-batch. When the cluster restarts, the engine reads that offset and resumes from the next unprocessed record - nothing is reprocessed, nothing is skipped.
Option A (increase trigger interval) affects how frequently micro-batches run but does nothing to record progress between runs. Option C (watermark) handles late-arriving events in event-time windows but doesn't control source offset tracking. Option D (enable CDF on the target table) tracks changes made to a Delta table for downstream consumers - it has no bearing on the streaming job's own fault tolerance or offset management.
Checkpointing is a required configuration for any production streaming job. Without it, every cluster restart triggers a full replay from the source.
Reference: https://learn.microsoft.com/en-us/azure/databricks/structured-streaming/query-recovery
質問 # 22
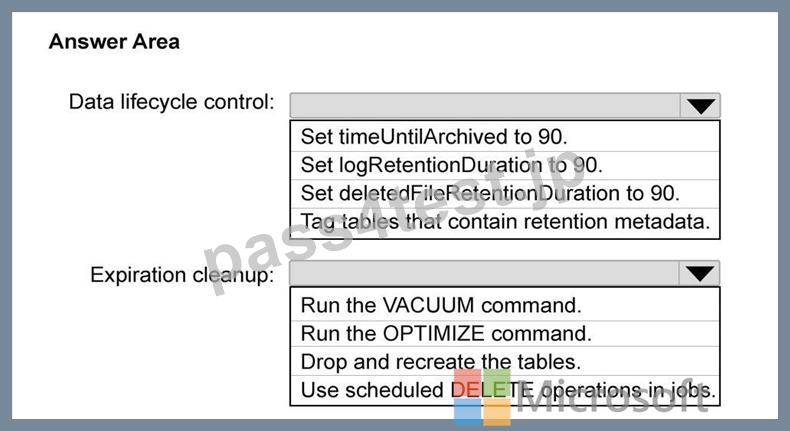
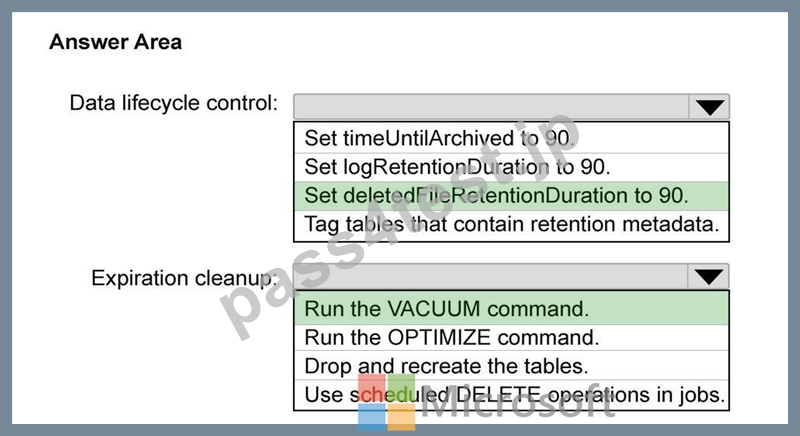
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to implement a data lifecycle and expiration solution that meets the following requirements:
- Transaction logs and deleted data files that are older than 90 days
must be removed from Delta tables to reclaim storage.
- All the tables must remain available for querying during the cleanup
process.
- Administrative effort must be minimized.
What should you do for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
正解:
解説:
質問 # 23
......
君はまずネットで無料な部分のMicrosoft認証試験をダウンロードして現場の試験の雰囲気を感じて試験に上手になりますよ。MicrosoftのDP-750認証試験に失敗したら弊社は全額で返金するのを保証いたします。
DP-750勉強時間: https://www.pass4test.jp/DP-750.html
- 効果的なDP-750専門トレーリング - 合格スムーズDP-750勉強時間 | 一番優秀なDP-750資格練習 Implementing Data Engineering Solutions Using Azure Databricks 🔚 ウェブサイト{ www.it-passports.com }を開き、( DP-750 )を検索して無料でダウンロードしてくださいDP-750過去問題
- ハイパスレートのDP-750専門トレーリング一回合格-最高のDP-750勉強時間 👖 ▶ www.goshiken.com ◀から簡単に( DP-750 )を無料でダウンロードできますDP-750認定試験トレーリング
- DP-750日本語資格取得 🥘 DP-750模擬試験問題集 📥 DP-750模擬試験問題集 🥤 最新⮆ DP-750 ⮄問題集ファイルは[ www.mogiexam.com ]にて検索DP-750トレーリングサンプル
- DP-750復習資料 🍀 DP-750受験トレーリング 🦆 DP-750復習資料 🦃 今すぐ【 www.goshiken.com 】で▷ DP-750 ◁を検索して、無料でダウンロードしてくださいDP-750認定試験トレーリング
- DP-750日本語受験教科書 📙 DP-750最新知識 📉 DP-750テスト参考書 🍲 【 www.xhs1991.com 】サイトにて最新{ DP-750 }問題集をダウンロードDP-750受験トレーリング
- DP-750試験勉強過去問 🎦 DP-750関連日本語内容 🏦 DP-750資格復習テキスト 📥 ✔ www.goshiken.com ️✔️で[ DP-750 ]を検索して、無料でダウンロードしてくださいDP-750最新知識
- 素晴らしいDP-750専門トレーリング試験-試験の準備方法-最高のDP-750勉強時間 🤒 ➤ www.mogiexam.com ⮘の無料ダウンロード[ DP-750 ]ページが開きますDP-750トレーリングサンプル
- 完璧DP-750専門トレーリング|機会を利用するImplementing Data Engineering Solutions Using Azure Databricks値するDP-750勉強時間 😝 ✔ DP-750 ️✔️の試験問題は☀ www.goshiken.com ️☀️で無料配信中DP-750トレーリングサンプル
- 信頼できるDP-750専門トレーリング | 素晴らしい合格率のDP-750: Implementing Data Engineering Solutions Using Azure Databricks | 高品質DP-750勉強時間 🧩 検索するだけで▛ www.jptestking.com ▟から「 DP-750 」を無料でダウンロードDP-750資格復習テキスト
- DP-750受験トレーリング 🥬 DP-750試験勉強過去問 🚹 DP-750関連日本語内容 🚵 Open Webサイト《 www.goshiken.com 》検索▛ DP-750 ▟無料ダウンロードDP-750問題集無料
- ハイパスレートのDP-750専門トレーリング一回合格-最高のDP-750勉強時間 🤑 ( www.mogiexam.com )サイトで▶ DP-750 ◀の最新問題が使えるDP-750認定試験トレーリング
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes