学習への関心を高めるには学習者に学習のための良い鍵を与えることが必要であり、これは学習者の内部要因の積極的な発達を促進することです。 DP-800質問トレントの最大の機能は、お客様が優れた学習習慣を身に付け、学習への関心を高め、簡単に試験に合格し、DP-800認定を取得できるようにすることです。候補者のために高品質の製品を生産するために、当社のすべての労働者が協力しています。私たちのDP-800試験トレントはあなたの将来にとって非常に役立つと信じています。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
あなたはいい仕事を見つけたい場合、DP-800参考資料を選択してください。多くのお客様はDP-800試験参考書を選択したら、DP-800認定試験資格証明書を取得しました。また、Microsoftのサービスもいいし、24時間のサービスを提供できます。だから、それは最もいい資料です。
質問 # 74
Drag and Drop Question
You have an Azure SQL database named SalesDB. SalesDB contains a table named dbo.Articles. dbo.Articles contains the following columns:
- ArticleId
- Title
- Body
- LastModifiedUtc
- EmbeddingVector
You have an application that generates embeddings from the concatenation of Title and Body and stores the results in EmbeddingVector.
You plan to implement an incremental embedding maintenance method that will use change data capture (CDC) to update embeddings only for rows that change, without scanning the entire table.
You need to ensure that only the columns required to generate the embeddings are captured.
The solution must support querying net changes.
How should you complete the Transact-SQL script? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.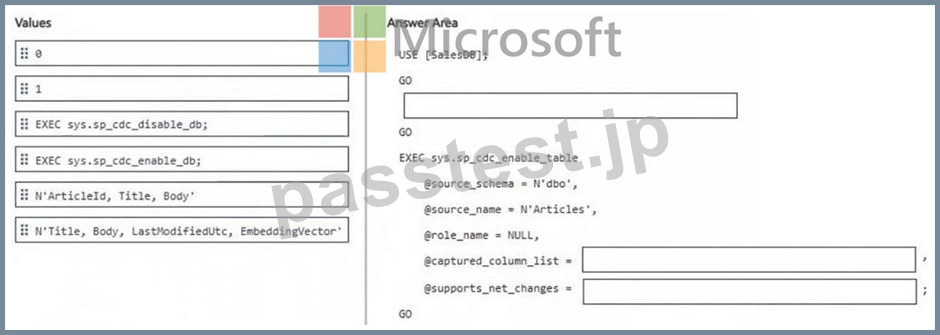
正解:
解説:
質問 # 75
Drag and Drop Question
You have an Azure SQL database that contains a table named dbo.Customers. dbo.Customers contains the following columns:
- CustomerId (int)(primary key)
- ProfileJson (nvarchar(max))
You have an application that returns phone numbers in a format of +000 000-000-0000. The phone numbers are stored in ProfileJson.
You need to write a query that returns:
- One row per customer
- A PhoneNUmerals column that contains only the digits
How should you complete the Transact-SQL query? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
正解:
解説: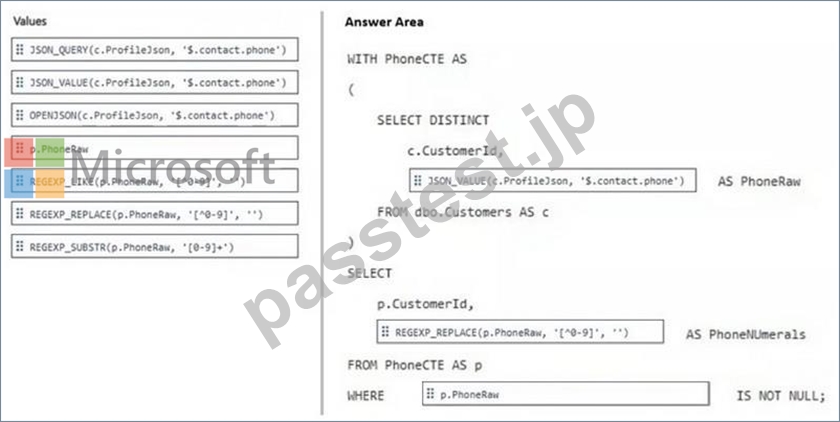
質問 # 76
Hotspot Question
You have an Azure SQL database that contains a table named Sales.Customer. Sales.Customer contains columns named CustomerId, FullName, Email, TaxID, and RegionId.
You have a database role named AppSupport that is used by a support application.
You need to implement a security solution for AppSupport that meets the following requirements:
- AppSupport must be prevented from viewing TaxID.
- AppSupport must be able to query Sales.Customer to troubleshoot
issues.
- AppSupport must be able to run a stored procedure named
Sales.usp_GetCustomerByCustomerId.
Which Transact-SQL statements should you include in the solution? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
正解:
解説:
質問 # 77
You need to recommend a solution that will resolve the ingestion pipeline failure issues. Which two actions should you recommend? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point.
正解:A、E
解説:
The two correct actions are D and E because the ingestion failures are caused by malformed JSON and duplicate payloads , and these two controls address those two problems directly. Microsoft's JSON documentation states that SQL Server and Azure SQL support validating JSON with ISJSON , and Microsoft specifically recommends using a CHECK constraint to ensure JSON text stored in a column is properly formatted.
For the duplicate-payload issue, creating a unique index on a hash of the payload is the appropriate design.
Microsoft documents using hashing functions such as HASHBYTES to hash column values, and SQL Server allows a deterministic computed column to be used as a key column in a UNIQUE constraint or unique index . That makes a persisted hash-based computed column plus a unique index a practical and exam- consistent way to reject duplicate payloads efficiently.
The other options do not solve the stated root causes:
* Snapshot isolation addresses concurrency behavior, not malformed JSON or duplicate payload detection.
* A trigger to rewrite malformed JSON is not the right integrity control and is brittle.
* Foreign key constraints enforce referential integrity, not JSON validity or duplicate-payload prevention
Topic 1, Contoso Case Study
Existing Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure. The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.
The FeedbackJson column has a full-text index and stores JSON documents in the following format.
The support staff at Contoso never has the unmask permission.
Requirements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following;
* Al workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.
SELECT VehicleTd, Lastupdatedutc, EngineStatus, BatteryHealth FROM dbo.VehicleHealthSumary where fleetld - gFleetld ORDER BV LastUpdatedUtc DESC; You review the execution plan and discover that the plan shows a clustered index scan.
vehicleincidentReports often contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support Al-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracy JSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEvents table updates the corresponding value in the LastModif reduce column to the time of the change.
* Avoid recursive updates.
AI Search, Embedding's, and Vector indexing
The development learn at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases. Contoso identifies the following requirements for querying data in the FeedbackJson column of the customer-Feedback table:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
質問 # 78
You have an Azure SQL database that contains the following SQL graph tables:
* A NODE table named dbo.Person
* An EDGE table named dbo.Knows
Each row in dbo.Person contains the following columns:
* Personid (int)
* DisplayName (nvarchar(100))
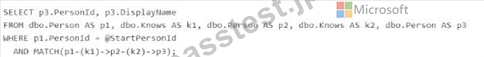
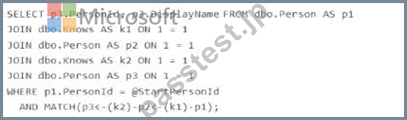
You need to use a HATCH operator and exactly two directed Knows relationships to return the Personid and DisplayName of people that are reachable from the person identified by an input parameter named
@startPersonid.
Which Transact-SQL query should you use?


正解:A
解説:
The correct query is Option D because it starts from the input person and uses exactly two directed Knows edges in a single MATCH pattern:
MATCH(p1-(k1)- > p2-(k2)- > p3)
Microsoft documents that SQL Graph uses the MATCH predicate in the WHERE clause to express graph traversal patterns over node and edge tables, and directed relationships are written with arrow syntax such as node1-(edge)- > node2.
Why D is correct:
* It anchors the starting node with p1.PersonId = @StartPersonId.
* It traverses two directed hops : p1 - > p2 - > p3.
* It returns p3.PersonId, p3.DisplayName, which are the people reachable in exactly two Knows relationships.
Why the others are wrong:
* A filters on DisplayName = DisplayName, which is unrelated to the required input parameter and does not correctly anchor the start node.
* B reverses the traversal direction in the pattern.
* C uses two separate MATCH predicates instead of the required single two-hop directed pattern. The proper graph pattern syntax supports chaining the hops directly in one MATCH expression.
Topic 1, Contoso Case Study
Existing Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure. The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.
The FeedbackJson column has a full-text index and stores JSON documents in the following format.
The support staff at Contoso never has the unmask permission.
Requirements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following;
* Al workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.
SELECT VehicleTd, Lastupdatedutc, EngineStatus, BatteryHealth FROM dbo.VehicleHealthSumary where fleetld - gFleetld ORDER BV LastUpdatedUtc DESC; You review the execution plan and discover that the plan shows a clustered index scan.
vehicleincidentReports often contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support Al-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracy JSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEvents table updates the corresponding value in the LastModif reduce column to the time of the change.
* Avoid recursive updates.
AI Search, Embedding's, and Vector indexing
The development learn at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases. Contoso identifies the following requirements for querying data in the FeedbackJson column of the customer-Feedback table:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
質問 # 79
......
PassTestはMicrosoft試験問題集を提供するウエブダイトで、ここによく分かります。最もよくて最新で資料を提供いたします。こうして、君は安心でDP-800試験の準備を行ってください。弊社の資料を使って、100%に合格を保証いたします。
DP-800日本語版復習指南: https://www.passtest.jp/Microsoft/DP-800-shiken.html