Certified-Data-Engineer-Professional Latest Test Preparation, Latest Certified-Data-Engineer-Professional Exam Camp

If you have a strong desire to get the Databricks certificate, our Certified-Data-Engineer-Professional study materials are the best choice for you. At present, the certificate has gained wide popularity. So the official test syllabus of the Certified-Data-Engineer-Professional exam begins to become complicated. So you must accept professional guidance. After all, lots of people are striving to compete with many candidates. Powerful competitiveness is crucial to pass the Certified-Data-Engineer-Professional Exam. Our company has mastered the core technology of the Certified-Data-Engineer-Professional study materials. What’s more, your main purpose is to get the certificate quickly and easily. Our goal is to aid your preparation of the Certified-Data-Engineer-Professional exam. Our study materials are an indispensable helper for you anyway. Please pay close attention to our Certified-Data-Engineer-Professional study materials.
| Section | Objectives |
|---|
| Topic 1: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 2. Analyze errors and remediate failed job runs
- 3. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
|
| Topic 2: Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Write efficient Spark SQL and PySpark transformations
- 2. Apply window functions, joins, and aggregations to large datasets
- Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
|
| Topic 3: Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Share live Lakehouse data with external computing platforms
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Configure Databricks-to-Databricks Sharing
|
| Topic 4: Cost & Performance Optimisation | - Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
- Delta Optimization
- 1. Apply data skipping and file pruning techniques
- 2. Understand deletion vectors and liquid clustering
- 3. Use Change Data Feed to address streaming table limitations and improve latency
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
|
| Topic 5: Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Configure environments, dependencies, memory, and retry behavior
- 2. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 3. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 4. Use control flow operators in pipeline components
- 5. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 6. Compare streaming tables and materialized views
- 7. Use APPLY CHANGES APIs for change data capture
- 8. Develop unit and integration tests for data processing code
- Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDFs
- 2. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 3. Manage and troubleshoot third-party library installations and dependencies
|
| Topic 6: Ensuring Data Security and Compliance | - Compliance
- 1. Develop data purging solutions according to data retention policies
- 2. Implement pipelines that detect and mask personally identifiable information
- Data Security
- 1. Use ACLs to secure workspace objects and enforce least privilege
- 2. Apply anonymization and pseudonymization techniques
- 3. Use row filters and column masks for sensitive data
|
| Topic 7: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Build append-only pipelines for batch and streaming data using Delta
- 2. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 3. Ingest data from message buses and cloud storage
|
| Topic 8: Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Topic 9: Monitoring and Alerting | - Monitoring
- 1. Use system tables for resource, cost, audit, and workload monitoring
- 2. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 3. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 4. Use Query Profiler and Spark UI to monitor workloads
- Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
|
| Topic 10: Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Optimize data layout using Liquid Clustering
- 2. Design and implement scalable data models using Delta Lake
- 3. Understand Liquid Clustering versus partitioning and Z-Ordering
|
>> Certified-Data-Engineer-Professional Latest Test Preparation <<
Trustable Certified-Data-Engineer-Professional Latest Test Preparation & Leading Provider in Qualification Exams & Correct Latest Certified-Data-Engineer-Professional Exam Camp
The design of our Certified-Data-Engineer-Professional guide training is ingenious and delicate. Every detail is perfect. For example, if you choose to study our Certified-Data-Engineer-Professional learning materials on our windows software, you will find the interface our Certified-Data-Engineer-Professional earning materials are concise and beautiful, so it can allow you to study Certified-Data-Engineer-Professional Exam Questions in a concise and undisturbed environment. In addition, you will find a lot of small buttons, which can give you a lot of help. If you are satisfied with our Certified-Data-Engineer-Professional exam questions, you can make a choice to purchase them.
Databricks Certified Data Engineer Professional Sample Questions (Q64-Q69):
NEW QUESTION # 64
An upstream system has been configured to pass the date for a given batch of data to the Databricks Jobs API as a parameter. The notebook to be scheduled will use this parameter to load data with the following code:
df = spark.read.format("parquet").load(f"/mnt/source/(date)")
Which code block should be used to create the date Python variable used in the above code block?
- A. date = dbutils.notebooks.getParam("date")
- B. date = spark.conf.get("date")
- C. dbutils.widgets.text("date", "null")
date = dbutils.widgets.get("date") - D. input_dict = input()
date= input_dict["date"] - E. import sys
date = sys.argv[1]
Answer: C
Explanation:
The code block that should be used to create the date Python variable used in the above code block is:
dbutils.widgets.text("date", "null") date = dbutils.widgets.get("date") This code block uses the dbutils.widgets API to create and get a text widget named "date" that can accept a string value as a parameter. The default value of the widget is "null", which means that if no parameter is passed, the date variable will be "null". However, if a parameter is passed through the Databricks Jobs API, the date variable will be assigned the value of the parameter.
For example, if the parameter is "2021-11-01", the date variable will be "2021-11-01". This way, the notebook can use the date variable to load data from the specified path.
NEW QUESTION # 65
A junior data engineer on your team has implemented the following code block.
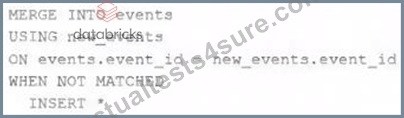
The view new_events contains a batch of records with the same schema as the events Delta table. The event_id field serves as a unique key for this table.
When this query is executed, what will happen with new records that have the same event_id as an existing record?
- A. They are ignored.
- B. They are deleted.
- C. They are merged.
- D. They are updated.
- E. They are inserted.
Answer: A
Explanation:
This is the correct answer because it describes what will happen with new records that have the same event_id as an existing record when the query is executed. The query uses the INSERT INTO command to append new records from the view new_events to the table events. However, the INSERT INTO command does not check for duplicate values in the primary key column (event_id) and does not perform any update or delete operations on existing records. Therefore, if there are new records that have the same event_id as an existing record, they will be ignored and not inserted into the table events.
NEW QUESTION # 66
A Delta table of weather records is partitioned by date and has the below schema:
date DATE, device_id INT, temp FLOAT, latitude FLOAT, longitude FLOAT
To find all the records from within the Arctic Circle, you execute a query with the below filter:
latitude > 66.3
Which statement describes how the Delta engine identifies which files to load?
- A. The Delta log is scanned for min and max statistics for the latitude column
- B. All records are cached to attached storage and then the filter is applied
- C. The Parquet file footers are scanned for min and max statistics for the latitude column
- D. All records are cached to an operational database and then the filter is applied
- E. The Hive metastore is scanned for min and max statistics for the latitude column
Answer: A
Explanation:
This is the correct answer because Delta Lake uses a transaction log to store metadata about each table, including min and max statistics for each column in each data file. The Delta engine can use this information to quickly identify which files to load based on a filter condition, without scanning the entire table or the file footers. This is called data skipping and it can improve query performance significantly. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; [Databricks Documentation], under "Optimizations - Data Skipping" section.
In the Transaction log, Delta Lake captures statistics for each data file of the table. These statistics indicate per file:
- Total number of records
- Minimum value in each column of the first 32 columns of the table
- Maximum value in each column of the first 32 columns of the table
- Null value counts for in each column of the first 32 columns of the table When a query with a selective filter is executed against the table, the query optimizer uses these statistics to generate the query result. it leverages them to identify data files that may contain records matching the conditional filter.
For the SELECT query in the question, The transaction log is scanned for min and max statistics for the price column.
NEW QUESTION # 67
A data engineering team is migrating off its legacy Hadoop platform. As part of the process, they are evaluating storage formats for performance comparison. The legacy platform uses ORC and RCFile formats. After converting a subset of data to Delta Lake, they noticed significantly better query performance. Upon investigation, they discovered that queries reading from Delta tables leveraged a Shuffle Hash Join, whereas queries on legacy formats used Sort Merge Joins. The queries reading Delta Lake data also scanned less data. Which reason could be attributed to the difference in query performance?
- A. Delta Lake enables data skipping and file pruning using a vectorized Parquet reader.
- B. Shuffle Hash Joins are always more efficient than Sort Merge Joins.
- C. The queries against the Delta Lake tables were able to leverage the dynamic file pruning optimization.
- D. The queries against the ORC tables leveraged the dynamic data skipping optimization but not the dynamic file pruning optimization.
Answer: A
Explanation:
Delta Lake outperforms legacy Hadoop formats because it leverages Parquet-based storage, data skipping, and file pruning. According to Databricks documentation, Delta Lake automatically stores detailed statistics (min/max values and file-level metadata) in the transaction log. During query planning, the engine uses these statistics to skip entire files that do not match query filters, a process called data skipping and file pruning. Additionally, Delta uses a vectorized Parquet reader, which reduces I/O and CPU overhead. Together, these optimizations allow Delta to scan significantly less data and produce more efficient physical query plans (e.g., Shuffle Hash Join instead of Sort Merge Join). The performance gain is due to efficient data skipping, not the inherent superiority of join type.
NEW QUESTION # 68
Assuming that the Databricks CLI has been installed and configured correctly, which Databricks CLI command can be used to upload a custom Python Wheel to object storage mounted with the DBFS for use with a production job?
- A. workspace
- B. fs
- C. configure
- D. libraries
- E. jobs
Answer: B
Explanation:
https://docs.databricks.com/en/archive/dev-tools/cli/dbfs-cli.html
NEW QUESTION # 69
......
We are one of the largest and the most confessional dealer of Certified-Data-Engineer-Professional practice materials for we have been professional in this career for over ten years. And we have enough strenght on this filed. That is why our Certified-Data-Engineer-Professional actual exam outreaches others greatly among substantial suppliers of the exam. Getting place great orders with competitive prices and unquestionable quality for your information, the excellency of our Certified-Data-Engineer-Professional Exam Questions is obvious. Just come and buy them!
Latest Certified-Data-Engineer-Professional Exam Camp: https://www.actualtests4sure.com/Certified-Data-Engineer-Professional-test-questions.html
- Certified-Data-Engineer-Professional Study Questions - Certified-Data-Engineer-Professional Free Demo - Certified-Data-Engineer-Professional Valid Torrent 🪒 Easily obtain free download of ▶ Certified-Data-Engineer-Professional ◀ by searching on { www.examdiscuss.com } 🔋New Certified-Data-Engineer-Professional Dumps Book
- Guaranteed Certified-Data-Engineer-Professional Success 🗻 Valid Certified-Data-Engineer-Professional Exam Camp 📐 Certified-Data-Engineer-Professional Test Braindumps ⛷ Search for ➤ Certified-Data-Engineer-Professional ⮘ and download it for free on ⇛ www.pdfvce.com ⇚ website 🎾Certified-Data-Engineer-Professional Test Simulator
- 100% Pass Certified-Data-Engineer-Professional - Professional Databricks Certified Data Engineer Professional Latest Test Preparation 🎠 Download ✔ Certified-Data-Engineer-Professional ️✔️ for free by simply entering ➽ www.torrentvce.com 🢪 website 🔼Certified-Data-Engineer-Professional Test Simulator
- 2026 Updated Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Latest Test Preparation ⬅️ Go to website ☀ www.pdfvce.com ️☀️ open and search for “ Certified-Data-Engineer-Professional ” to download for free 🕝Certified-Data-Engineer-Professional Test Cram
- Certified-Data-Engineer-Professional Test Braindumps 🌵 Certified-Data-Engineer-Professional Valid Exam Simulator 🚨 New Certified-Data-Engineer-Professional Dumps Book 🌞 Search for ➡ Certified-Data-Engineer-Professional ️⬅️ and download exam materials for free through 《 www.dumpsquestion.com 》 🚰Guaranteed Certified-Data-Engineer-Professional Success
- New Certified-Data-Engineer-Professional Dumps Book 📷 Test Certified-Data-Engineer-Professional Questions Answers ⤴ Authorized Certified-Data-Engineer-Professional Exam Dumps 🐊 Search for ➠ Certified-Data-Engineer-Professional 🠰 and download it for free immediately on ⇛ www.pdfvce.com ⇚ 🪐Valid Certified-Data-Engineer-Professional Exam Camp
- Valid Certified-Data-Engineer-Professional Exam Camp 😒 Certified-Data-Engineer-Professional Latest Demo ⏏ New Certified-Data-Engineer-Professional Dumps Book 😤 Search for ⇛ Certified-Data-Engineer-Professional ⇚ and download it for free on ➽ www.pass4test.com 🢪 website 🐻Certified-Data-Engineer-Professional Latest Demo
- Valid Certified-Data-Engineer-Professional Exam Camp 🌗 Test Certified-Data-Engineer-Professional Questions Answers 🚟 High Certified-Data-Engineer-Professional Quality 📩 Download 【 Certified-Data-Engineer-Professional 】 for free by simply entering 《 www.pdfvce.com 》 website 👐Practice Test Certified-Data-Engineer-Professional Fee
- Efficient Certified-Data-Engineer-Professional Latest Test Preparation | Easy To Study and Pass Exam at first attempt - Professional Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional 🚡 Open website ( www.examcollectionpass.com ) and search for ➡ Certified-Data-Engineer-Professional ️⬅️ for free download 🚛Practice Test Certified-Data-Engineer-Professional Fee
- Authorized Certified-Data-Engineer-Professional Exam Dumps ⏹ Test Certified-Data-Engineer-Professional Questions Answers 🥓 Certified-Data-Engineer-Professional Free Exam Dumps 👏 Simply search for ➡ Certified-Data-Engineer-Professional ️⬅️ for free download on ⮆ www.pdfvce.com ⮄ 👮Valid Certified-Data-Engineer-Professional Exam Camp
- Certified-Data-Engineer-Professional Latest Test Preparation 100% Pass | The Best Databricks Latest Databricks Certified Data Engineer Professional Exam Camp Pass for sure 📦 Search for 《 Certified-Data-Engineer-Professional 》 and obtain a free download on ➥ www.troytecdumps.com 🡄 ✊Certified-Data-Engineer-Professional Pass4sure Study Materials
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes