DOWNLOAD the newest RealVCE DY0-001 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1FoMNeBINuB2PEGz_9OmC5T52f6Sj0ydv
These practice exams are customizable and help you counter exam anxiety. You can use CompTIA DY0-001 desktop practice test software and web-based practice test software to assess your knowledge, test-taking skills, and readiness for the actual DY0-001 exam. With both DY0-001 exam practice test software you can familiarize yourself with the types of questions, and overall exam environment and improve your exam time management skills. So choose your desired DY0-001 Exam Practice test software and start exam preparation today. The desktop software runs on Windows computers and the web-based is supported by all operating systems.
| Certification Vendor: | CompTIA |
|---|---|
| Exam Name: | CompTIA DataAI Certification Exam (V1) |
| Exam Number: | DY0-001 |
| Exam Duration: | 165 minutes |
| Related Certifications: | CompTIA DataX |
| Available Languages: | English, Japanese |
| Exam Format: | Performance-based questions, Multiple-choice |
| Passing Score: | Pass/Fail (no scaled score) |
| Real Exam Qty: | Up to 90 |
| Certificate Validity Period: | Approximately 3 years from launch (retirement expected around 2027) |
| Recommended Training: | CompTIA Official Training Partners CompTIA CertMaster Learn (DataAI) |
| Exam Registration: | Pearson VUE CompTIA Registration CompTIA DataAI Official Page |
| Sample Questions: | CompTIA DY0-001 Sample Questions |
| Exam Way: | Test center or online proctored exam (Pearson VUE) |
| Pre Condition: | Recommended: 5+ years experience in data science, analytics, or related technical roles |
| Official Syllabus URL: | https://www.comptia.org/en-us/certifications/dataai/ |
The DY0-001 practice materials are a great beginning to prepare your exam. Actually, just think of our DY0-001 practice materials as the best way to pass the exam is myopic. They can not only achieve this, but ingeniously help you remember more content at the same time. It is estimated conservatively that the passing rate of the exam is over 98 percent with our DY0-001 Study Materials as well as considerate services. We not only provide all candidates with high pass rate study materials, but also provide them with good service.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 43
A data scientist receives an update on a business case about a machine that has thousands of error codes. The data scientist creates the following summary statistics profile while reviewing the logs for each machine: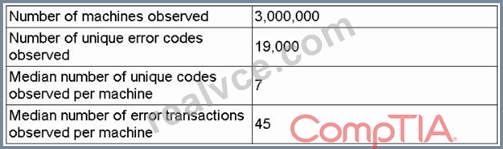
| Number of machines observed | 3,000,000
| Number of unique error codes observed | 19,000
| Median number of unique codes per machine | 7
| Median number of error transactions | 45
Which of the following is the most likely concern with respect to data design for model ingestion?
Answer: B
Explanation:
# With 19,000 unique error codes and only 7 codes per machine (on median), the data structure will likely consist of a very large number of binary features (e.g., one-hot encoded error codes), most of which will be 0 for any given machine. This leads to a sparse matrix-where the majority of elements are zero-which poses computational and modeling challenges.
Why the other options are incorrect:
* B: Granularity misalignment would mean mismatched levels (e.g., mixing daily and hourly data), which is not the issue here.
* C: There are many features (error codes), not too few.
* D: Multivariate outliers involve unusual combinations across features, not sparsity.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 3.3:"High-cardinality categorical features can result in sparse matrices, especially when one-hot encoded for models."
NEW QUESTION # 44
A data scientist is building an inferential model with a single predictor variable. A scatter plot of the independent variable against the real-number dependent variable shows a strong relationship between them. The predictor variable is normally distributed with very few outliers. Which of the following algorithms is the best fit for this model, given the data scientist wants the model to be easily interpreted?
Answer: C
NEW QUESTION # 45
Given these business requirements:
Which of the following is the most likely optimization technique a data scientist would apply?
Answer: A
Explanation:
You must optimize boat trips subject to strict resource limits (fuel, boat capacity, travel distance), making this a constrained optimization problem (e.g., solvable via linear programming).
NEW QUESTION # 46
A data scientist is developing a model to predict the outcome of a vote for a national mascot. The choice is between tigers and lions. The full data set represents feedback from individuals representing 17 professions and 12 different locations. The following rank aggregation represents 80% of the data set: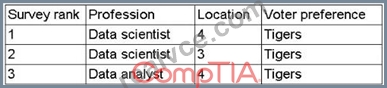
(Screenshot shows survey rankings for just two professions and a few locations, all voting for "Tigers") Which of the following is the most likely concern about the model's ability to predict the outcome of the vote?
Answer: C
Explanation:
# Extrapolated data refers to making predictions about data points that fall outside the observed range or distribution. Since the sample data (80%) is heavily skewed toward a small subset of professions and locations, predicting results for the remaining, unrepresented professions and regions involves extrapolation.
Why the other options are incorrect:
* A: Interpolation occurs within the bounds of observed data - not the issue here.
* C: In-sample data refers to training data, which is overrepresented in this case.
* D: Out-of-sample data is a concern in generalization but extrapolation is more specific here.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 3.2:"Extrapolation introduces risk when models are used outside the range of data they were trained on, especially if certain subgroups are underrepresented."
-
NEW QUESTION # 47
A data scientist is building a proof of concept for a commercialized machine-learning model. Which of the following is the best starting point?
Answer: C
Explanation:
# In the proof-of-concept phase, the first practical step is model selection - identifying which modeling technique is most appropriate based on the nature of the problem, data, and business goal. Literature reviews are helpful but usually precede model experimentation.
Why the other options are incorrect:
* A: Literature review informs planning but isn't the first hands-on step.
* B: Performance evaluation comes after models are built.
* C: Hyperparameter tuning applies after a model is chosen.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 5.1:"Model selection is a critical step during early prototyping when evaluating different algorithms for feasibility."
* CRISP-DM Framework - Modeling Phase:"Selecting candidate models is the first step in model development after understanding the data."
NEW QUESTION # 48
......
DY0-001 Latest Test Simulations: https://www.realvce.com/DY0-001_free-dumps.html
2026 Latest RealVCE DY0-001 PDF Dumps and DY0-001 Exam Engine Free Share: https://drive.google.com/open?id=1FoMNeBINuB2PEGz_9OmC5T52f6Sj0ydv