참고: PassTIP에서 Google Drive로 공유하는 무료, 최신 CT-AI 시험 문제집이 있습니다: https://drive.google.com/open?id=1MiJPjidStrPAz7SqLLSbQV6BnXfkw2a8
자신을 부단히 업그레이드하려면 많은 노력이 필요합니다. IT업종 종사자라면 국제승인 IT인증자격증을 취득하는것이 자신을 업그레이드하는것과 같습니다. ISTQB인증 CT-AI시험을 패스하여 원하는 자격증을 취득하려면PassTIP의ISTQB인증 CT-AI덤프를 추천해드립니다. 하루빨리 덤프를 공부하여 자격증 부자가 되세요.
| Section | Objectives |
|---|---|
| Introduction to AI Testing | - Challenges in AI testing
|
| Testing AI-Based Systems | - Test levels for AI systems
|
| AI Quality Characteristics | - Quality attributes
|
| AI System Lifecycle and Operations | - Deployment and monitoring
|
| Data Quality and Bias | - Bias and fairness
|
| Machine Learning Fundamentals for Testing | - ML lifecycle
|
| Ethics and Risk in AI Testing | - Risk-based testing for AI
|
지금 사회에 능력자들은 아주 많습니다.it인재들도 더욱더 많아지고 있습니다.많은 it인사들은 모두 관연 it인증시험에 참가하여 자격증취득을 합니다.자기만의 자리를 확실히 지키고 더 높은 자리에 오르자면 필요한 스펙이니까요.CT-AI시험은ISTQB인증의 중요한 시험이고 또 많은 it인사들은ISTQB자격증을 취득하려고 노력하고 있습니다.
질문 # 155
Before deployment of an AI based system, a developer is expected to demonstrate in a test environment how decisions are made. Which of the following characteristics does decision making fall under?
정답:B
설명:
The syllabus definesexplainabilityas the ability to understand how the AI-based system comes up with a particular result:
"Explainability is considered to be the ease with which users can determine how the AI-based system comes up with a particular result."
질문 # 156
Which ONE of the following requirements for an AI based system is MOST likely to cause a challenge for testing?
정답:A
설명:
The correct answer is C . A requirement that an AI-based system be 100% accurate with no tolerance for failure creates a major testing challenge because many AI-based systems are probabilistic and may require accuracy tolerances rather than absolute expected outcomes. The CT-AI syllabus states that the probabilistic nature of many AI-based systems can make it necessary to specify tolerances for quality requirements such as prediction accuracy.
Option A is also challenging because natural language interfaces increase flexibility and make it difficult to document all possible interactions, but it is not as absolute as requiring perfect accuracy. Option B is a conventional performance efficiency requirement and can normally be tested using timing and resource measurements. Option D relates to autonomy and may require scenario-based testing, but it is still testable if the operational envelope and failure conditions are well specified. The decisive issue with option C is that it provides no tolerance range, no probabilistic acceptance model, and no practical allowance for statistical uncertainty. This creates both a specification problem and a test oracle problem.
References/topics: CT-AI Syllabus Chapter 7, Section 7.1 "Specification of AI-Based Systems"; Chapter
8, Section 8.4 "Challenges Testing Probabilistic and Non-Deterministic AI-Based Systems."
=========
질문 # 157
Which ONE of the following models BEST describes a way to model defect prediction by looking at the history of bugs in modules by using code quality metrics of modules of historical versions as input?
SELECT ONE OPTION
정답:D
설명:
Defect prediction models aim to identify parts of the software that are likely to contain defects by analyzing historical data and code quality metrics. The primary goal is to use this predictive information to allocate testing and maintenance resources effectively. Let's break down why option D is the correct choice:
Understanding Classification Models:
Classification models are a type of supervised learning algorithm used to categorize or classify data into predefined classes or labels. In the context of defect prediction, the classification model would classify parts of the code as either "defective" or "non-defective" based on the input features.
Input Data - Code Quality Metrics:
The input data for these classification models typically includes various code quality metrics such as cyclomatic complexity, lines of code, number of methods, depth of inheritance, coupling between objects, etc. These metrics help the model learn patterns associated with defects.
Historical Data:
Historical versions of the code along with their defect records provide the labeled data needed for training the classification model. By analyzing this historical data, the model can learn which metrics are indicative of defects.
Why Option D is Correct:
Option D specifies using a classification model to predict the presence of defects by using code quality metrics as input data. This accurately describes the process of defect prediction using historical bug data and quality metrics.
Eliminating Other Options:
A . Identifying the relationship between developers and the modules developed by them: This does not directly involve predicting defects based on code quality metrics and historical data.
B . Search of similar code based on natural language processing: While useful for other purposes, this method does not describe defect prediction using classification models and code metrics.
C . Clustering of similar code modules to predict based on similarity: Clustering is an unsupervised learning technique and does not directly align with the supervised learning approach typically used in defect prediction models.
Reference:
ISTQB CT-AI Syllabus, Section 9.5, Metamorphic Testing (MT), describes various testing techniques including classification models for defect prediction.
"Using AI for Defect Prediction" (ISTQB CT-AI Syllabus, Section 11.5.1).
질문 # 158
Written requirements are given in text documents, which ONE of the following options is the BEST way to generate test cases from these requirements?
SELECT ONE OPTION
정답:C
설명:
When written requirements are given in text documents, the best way to generate test cases is by using Natural Language Processing (NLP). Here's why:
Natural Language Processing (NLP): NLP can analyze and understand human language. It can be used to process textual requirements to extract relevant information and generate test cases. This method is efficient in handling large volumes of textual data and identifying key elements necessary for testing.
Why Not Other Options:
Analyzing source code for generating test cases: This is more suitable for white-box testing where the code is available, but it doesn't apply to text-based requirements.
Machine learning on logs of execution: This approach is used for dynamic analysis based on system behavior during execution rather than static textual requirements.
GUI analysis by computer vision: This is used for testing graphical user interfaces and is not applicable to text-based requirements.
질문 # 159
Upon testing a model used to detect rotten tomatoes, the following data was observed by the test engineer, based on certain number of tomato images.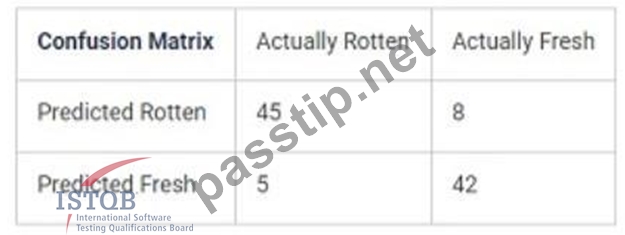
For this confusion matrix which combinations of values of accuracy, recall, and specificity respectively is CORRECT?
정답:B
설명:
To calculate the accuracy, recall, and specificity from the confusion matrix provided, we use the following formulas:
Confusion Matrix:
Actually Rotten: 45 (True Positive), 8 (False Positive)
Actually Fresh: 5 (False Negative), 42 (True Negative)
Accuracy:
Accuracy is the proportion of true results (both true positives and true negatives) in the total population.
Formula: Accuracy=TP+TNTP+TN+FP+FN\text{Accuracy} = \frac{TP + TN}{TP + TN + FP + FN}Accuracy=TP+TN+FP+FNTP+TN Calculation: Accuracy=45+4245+42+8+5=87100=0.87\text{Accuracy} = \frac{45 + 42}{45 + 42 + 8
+ 5} = \frac{87}{100} = 0.87Accuracy=45+42+8+545+42=10087=0.87
Recall (Sensitivity):
Recall is the proportion of true positive results in the total actual positives.
Formula: Recall=TPTP+FN\text{Recall} = \frac{TP}{TP + FN}Recall=TP+FNTP Calculation: Recall=4545+5=4550=0.9\text{Recall} = \frac{45}{45 + 5} = \frac{45}{50} =
0.9Recall=45+545=5045=0.9
Specificity:
Specificity is the proportion of true negative results in the total actual negatives.
Formula: Specificity=TNTN+FP\text{Specificity} = \frac{TN}{TN + FP}Specificity=TN+FPTN Calculation: Specificity=4242+8=4250=0.84\text{Specificity} = \frac{42}{42 + 8} = \frac{42}{50} =
0.84Specificity=42+842=5042=0.84
Therefore, the correct combinations of accuracy, recall, and specificity are 0.87, 0.9, and 0.84 respectively.
질문 # 160
......
PassTIP에서 출시한 ISTQB CT-AI덤프만 있으면 학원다닐 필요없이 시험패스 가능합니다. ISTQB CT-AI덤프를 공부하여 시험에서 떨어지면 불합격성적표와 주문번호를 보내오시면 덤프비용을 환불해드립니다.구매전 데모를 받아 덤프문제를 체험해보세요. 데모도 pdf버전과 온라인버전으로 나뉘어져 있습니다.pdf버전과 온라인버전은 문제는 같은데 온라인버전은 pdf버전을 공부한후 실력테스트 가능한 프로그램입니다.
CT-AI퍼펙트 공부자료: https://www.passtip.net/CT-AI-pass-exam.html
그 외, PassTIP CT-AI 시험 문제집 일부가 지금은 무료입니다: https://drive.google.com/open?id=1MiJPjidStrPAz7SqLLSbQV6BnXfkw2a8