What's more, part of that DumpsReview Mule-Arch-201 dumps now are free: https://drive.google.com/open?id=1pPi9w9MGUrPccZfRdPPWnx484R6vuaI7
If you want to get some achievement in the IT field Salesforce certifications will be a stepping-stone. In fact high senior positions have a large demand. Mule-Arch-201 new test braindumps will pave the way for you to clear exam and obtain a certification. If you are an experienced IT test engine, owing one certification under the help of Mule-Arch-201 new test braindumps will improve your value; companies may have more cooperation opportunities.
| Section | Objectives |
|---|---|
| Topic 1: API Management and Governance | - API security policies and enforcement - Governance frameworks and best practices - API lifecycle management |
| Topic 2: Security and Compliance | - Secure API exposure and threat protection - Authentication and authorization mechanisms |
| Topic 3: Integration Architecture Strategy | - API-led connectivity principles - System, process, and experience APIs - Designing enterprise integration architecture |
| Topic 4: Performance and Scalability | - Scaling Mule applications - High availability design patterns |
| Topic 5: Anypoint Platform Architecture | - Anypoint Platform components and capabilities - Runtime Fabric architecture overview - Deployment models (CloudHub, hybrid, on-premises) |
| Topic 6: Data Integration and Transformation | - Batch vs real-time integration patterns - Data mapping and transformation strategies |
>> Reliable Mule-Arch-201 Dumps Book <<
With the Salesforce Mule-Arch-201 practice test, users can reduce stress, and improve their confidence to succeed. The desktop-based Salesforce Certified MuleSoft Platform Architect (Mule-Arch-201) practice test software is compatible with Windows only. But the web-based Mule-Arch-201 Practice Test is compatible with all operating systems.
NEW QUESTION # 97
What is the most performant out-of-the-box solution in Anypoint Platform to track transaction state in an asynchronously executing long-running process implemented as a Mule application deployed to multiple CloudHub workers?
Answer: A
Explanation:
Correct Answe r: Persistent Object Store
*****************************************
>> Redis distributed cache is performant but NOT out-of-the-box solution in Anypoint Platform
>> File-storage is neither performant nor out-of-the-box solution in Anypoint Platform
>> java.util.WeakHashMap needs a completely custom implementation of cache from scratch using Java code and is limited to the JVM where it is running. Which means the state in the cache is not worker aware when running on multiple workers. This type of cache is local to the worker. So, this is neither out-of-the-box nor worker-aware among multiple workers on cloudhub. https://www.baeldung.com/java-weakhashmap
>> Persistent Object Store is an out-of-the-box solution provided by Anypoint Platform which is performant as well as worker aware among multiple workers running on CloudHub. https://docs.mulesoft.com/object-store/ So, Persistent Object Store is the right answer.
NEW QUESTION # 98
A new upstream API Is being designed to offer an SLA of 500 ms median and 800 ms maximum (99th percentile) response time. The corresponding API implementation needs to sequentially invoke 3 downstream APIs of very similar complexity.
The first of these downstream APIs offers the following SLA for its response time: median: 100 ms, 80th percentile: 500 ms, 95th percentile: 1000 ms.
If possible, how can a timeout be set in the upstream API for the invocation of the first downstream API to meet the new upstream API's desired SLA?
Answer: D
Explanation:
Correct Answe r: Set a timeout of 100ms; that leaves 400ms for other two downstream APIs to complete
*****************************************
Key details to take from the given scenario:
>> Upstream API's designed SLA is 500ms (median). Lets ignore maximum SLA response times.
>> This API calls 3 downstream APIs sequentially and all these are of similar complexity.
>> The first downstream API is offering median SLA of 100ms, 80th percentile: 500ms; 95th percentile: 1000ms.
Based on the above details:
>> We can rule out the option which is suggesting to set 50ms timeout. Because, if the median SLA itself being offered is 100ms then most of the calls are going to timeout and time gets wasted in retried them and eventually gets exhausted with all retries. Even if some retries gets successful, the remaining time wont leave enough room for 2nd and 3rd downstream APIs to respond within time.
>> The option suggesting to NOT set a timeout as the invocation of this API is mandatory and so we must wait until it responds is silly. As not setting time out would go against the good implementation pattern and moreover if the first API is not responding within its offered median SLA 100ms then most probably it would either respond in 500ms (80th percentile) or 1000ms (95th percentile). In BOTH cases, getting a successful response from 1st downstream API does NO GOOD because already by this time the Upstream API SLA of 500 ms is breached. There is no time left to call 2nd and 3rd downstream APIs.
>> It is NOT true that no timeout is possible to meet the upstream APIs desired SLA.
As 1st downstream API is offering its median SLA of 100ms, it means MOST of the time we would get the responses within that time. So, setting a timeout of 100ms would be ideal for MOST calls as it leaves enough room of 400ms for remaining 2 downstream API calls.
NEW QUESTION # 99
Which APIs can be used with DataGraph to create a unified schema?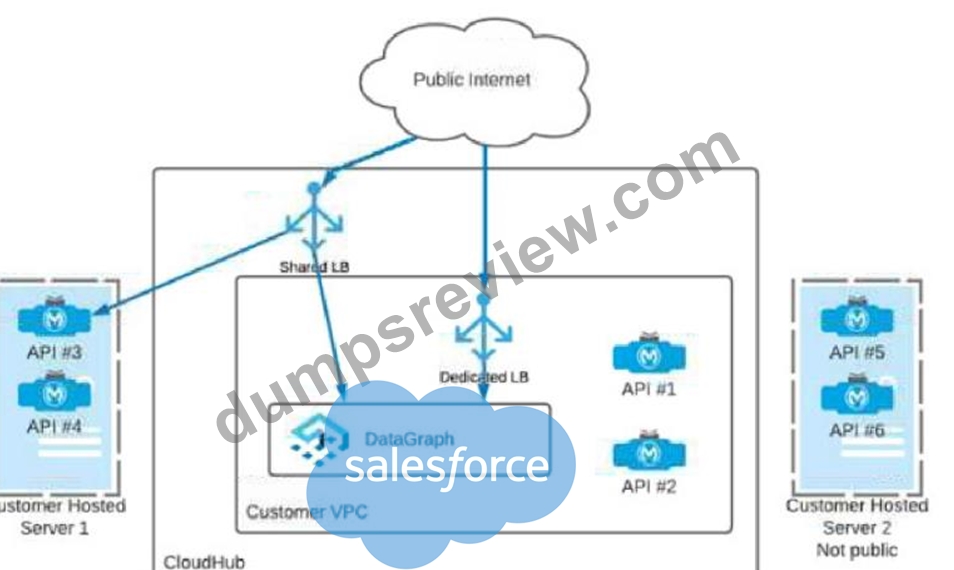
Answer: C
Explanation:
To create a unified schema in MuleSoft's DataGraph, APIs must be exposed in a way that allows DataGraph to pull and consolidate data from these APIs into a single schema accessible to consumers. DataGraph provides a federated approach, combining multiple APIs to form a single, unified API endpoint.
In this setup:
APIs 1, 2, 3, and 4 are suitable candidates for DataGraph because they are hosted within the Customer VPC on CloudHub and are accessible either through a Shared Load Balancer (LB) or a Dedicated Load Balancer (DLB). Both of these load balancers provide public access, which is a necessary condition for DataGraph as it must access the APIs to aggregate data.
APIs 5 and 6 are hosted on Customer Hosted Server 2, which is explicitly marked as "Not public". Since DataGraph requires API access through a publicly reachable endpoint to aggregate them into a unified schema, APIs 5 and 6 cannot be used with DataGraph in this configuration.
APIs 3 and 4 on Customer Hosted Server 1 appear accessible through a Shared LB, implying public accessibility that meets DataGraph's requirements.
By combining APIs 1, 2, 3, and 4 within DataGraph, you can create a unified schema that enables clients to query data seamlessly from all these APIs as if it were from a single source.
This setup allows for efficient data retrieval and can simplify API consumption by reducing the need to call multiple APIs individually, thus optimizing performance and developer experience.
Reference
For more detailed information on setting up and managing unified schemas in DataGraph, refer to the DataWeave documentation and MuleSoft DataGraph resources which provide in-depth guidelines on schema aggregation and API federation.
NEW QUESTION # 100
A REST API is being designed to implement a Mule application.
What standard interface definition language can be used to define REST APIs?
Answer: B
NEW QUESTION # 101
An API is protected with a Client ID Enforcement policy and uses the default configuration. Access is requested for the client application to the API, and an approved contract now exists between the client application and the API How can a consumer of this API avoid a 401 error "Unauthorized or invalid client application credentials"?
Answer: C
Explanation:
When using the Client ID Enforcement policy with default settings, MuleSoft expects the client_id and client_secret to be provided in the URI parameters of each request. This policy is typically used to control and monitor access by validating that each request has valid credentials. Here's how to avoid a 401 Unauthorized error:
URI Parameters Requirement:
The default configuration for the Client ID Enforcement policy requires the client_id and client_secret to be included in each request's URI parameters. This is a straightforward way to authenticate API requests without additional configurations.
Why Option C is Correct:
Providing client_id and client_secret in the URI parameters meets the policy's requirements for each request, ensuring authorized access and avoiding the 401 error.
of Incorrect Options:
Option A (sending a token in the header) would be applicable for token-based authentication (like OAuth 2.0), not Client ID Enforcement.
Option B (request body) and Option D (header) are not valid locations for client_id and client_secret under the default configuration of Client ID Enforcement, which expects them in the URI.
Reference
For more details, consult MuleSoft's documentation on Client ID Enforcement policies and expected request configurations
NEW QUESTION # 102
......
You many face many choices of attending the certificate exams and there are a variety of certificates for you to get. You want to get the most practical and useful certificate which can reflect your ability in some area. If you choose to attend the test Mule-Arch-201 certification buying our Mule-Arch-201 exam guide can help you pass the test and get the valuable certificate. Our company has invested a lot of personnel, technology and capitals on our products and is always committed to provide the top-ranking Mule-Arch-201 Study Material to the clients and serve for the client wholeheartedly.
Mule-Arch-201 Paper: https://www.dumpsreview.com/Mule-Arch-201-exam-dumps-review.html
BTW, DOWNLOAD part of DumpsReview Mule-Arch-201 dumps from Cloud Storage: https://drive.google.com/open?id=1pPi9w9MGUrPccZfRdPPWnx484R6vuaI7