P.S. Free 2026 Google Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by PassReview: https://drive.google.com/open?id=1oR5QZmzmvjY-OdAIU--AMRzxgvbCFAAp
May be you will meet some difficult or problems when you prepare for your Professional-Machine-Learning-Engineer exam, you even want to give it up. That is why I suggest that you must try our study materials. Because Professional-Machine-Learning-Engineer guide torrent can help you to solve all the problems encountered in the learning process, Professional-Machine-Learning-Engineer study tool will provide you with very flexible learning time so that you can easily pass the exam. Even if you fail to pass the exam, as long as you are willing to continue to use our Professional-Machine-Learning-Engineer Study Tool, we will still provide you with the benefits of free updates within a year.
| Section | Weight | Objectives |
|---|---|---|
| Train and deploy models | 20% | - Configure training jobs and environments - Use Vertex AI deployment features and infrastructure - Deploy models for online, batch, and streaming prediction - Implement generative AI deployment patterns |
| Monitor and optimize AI solutions | 16% | - Monitor model performance, fairness, and drift - Optimize cost, latency, and resource usage - Monitor data quality and pipeline health - Troubleshoot and maintain production systems |
| Automate and orchestrate ML pipelines | 18% | - Design end-to-end ML workflows - Use Vertex AI Pipelines, TFX, and other orchestration tools - Implement CI/CD for ML systems - Automate retraining and model updates |
| Architect low-code AI solutions | 12% | - Design solutions using Vertex AI Studio, Model Garden, and Agent Builder - Identify use cases for low-code/no-code AI tools - Apply responsible AI principles to low-code designs |
| Collaborate to manage data and models | 16% | - Address data privacy, compliance, and governance - Organize and prepare enterprise data
|
| Scale prototypes into AI models | 18% | - Optimize model performance and generalization - Design and run experiments - Work with foundation models and generative AI techniques - Select appropriate model architectures and frameworks |
>> New Professional-Machine-Learning-Engineer Exam Cram <<
By selecting our Professional-Machine-Learning-Engineer training material, you will be able to pass the Professional-Machine-Learning-Engineer exam in the first attempt. You will be able to get the desired results in Professional-Machine-Learning-Engineer certification exam by checking out the unique self-assessment features of our Professional-Machine-Learning-Engineer Practice Test software. You can easily get the high paying job if you are passing the Professional-Machine-Learning-Engineer exam in the first attempt, and our Professional-Machine-Learning-Engineer study guides can help you do so.
NEW QUESTION # 170
You work on a team that builds state-of-the-art deep learning models by using the TensorFlow framework.
Your team runs multiple ML experiments each week which makes it difficult to track the experiment runs.
You want a simple approach to effectively track, visualize and debug ML experiment runs on Google Cloud while minimizing any overhead code. How should you proceed?
Answer: B
Explanation:
Vertex AI Experiments is a service that allows you to track, compare, and optimize your ML experiments on Google Cloud. You can use Vertex AI Experiments to log metrics and parameters from your TensorFlow models, and then visualize them in Vertex AI TensorBoard. Vertex AI TensorBoard is a managed service that provides a web interface for viewing and debugging your ML experiments. You can use Vertex AI TensorBoard to compare different runs, inspect model graphs, analyze scalars, histograms, images, and more.
By using Vertex AI Experiments and Vertex AI TensorBoard, you can simplify your ML experiment tracking and visualization workflow, and avoid the overhead of setting up and maintaining your own Cloud Functions, Cloud Storage buckets, or VMs. References:
* [Vertex AI Experiments documentation]
* [Vertex AI TensorBoard documentation]
* Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate
NEW QUESTION # 171
You recently developed a deep learning model using Keras, and now you are experimenting with different training strategies. First, you trained the model using a single GPU, but the training process was too slow.
Next, you distributed the training across 4 GPUs using tf.distribute.MirroredStrategy (with no other changes), but you did not observe a decrease in training time. What should you do?
Answer: A
Explanation:
* Option A is incorrect because distributing the dataset with tf.distribute.Strategy.
experimental_distribute_dataset is not the most effective way to decrease the training time. This method allows you to distribute yo ur dataset across multiple devices or machines, by creating a tf.data.
Dataset instance that can be iterated over in parallel 1 . However, this option may not improve the training time significantly, as it does not change the amount of data or computation that each device or machine has to process. Moreover, this option may introduce add itional overhead or complexity, as it requires you to handle the data sharding, replication, and synchronization across the devices or machines 1 .
* Option B is incorrect because creating a custom training loop is not the easiest way to decrease the training time. A custom training loop is a way to implement your own logic for training your model, by using low-level TensorFlow APIs, such as tf.GradientTape, tf.Variable, or tf.function 2 . A custom training loop may give you more flexibility and control over the training process, but it also requir es more effort and expertise, as you have to write and debug the code for each step of the training loop, such as computing the gradients, applying the optimizer, or updating the metrics 2 . Moreover, a custom training loop may not improve the training time significantly, as it does not change the amount of data or computation that each device or machine has to process.
* Option C is incorrect because using a TPU with tf.distribute.TPUStrategy is not a valid way to decrease the training time. A TPU (Tensor Processing Unit) is a custom hardware accelerator designed for high- performance ML workloads 3 . A tf.distribute.TPUStrategy is a distribution strategy that allows you to distribute your training across multiple TPUs, by creating a tf.distribute.TPUStrategy instance that can be used with high-level TensorFlow APIs, such as Keras 4 . However, this option is not feasible, as Vertex AI Training does not support TPUs as accelerators for custom training jobs 5 . Moreover, this option may require significant code changes, as TPUs have different requirements and limitations than GPUs.
* Option D is correct because increasing the batch size is the best way to decrease the training time. The batch size is a hyperparameter that determines how many samples of data are processed in each iteration of the training loop. Increasing the batch size may reduce the training time, as it reduces the number of iterations needed to train the model, and it allows each device or machine to process more data in parallel. Increasing the batch size is also easy to implement, as it only requires changing a single hyperparameter. However, increasing the batch size may also affect the convergence and the accuracy of the model, so it is important to find the optimal batch size that balances the trade-off between the training time and the model performance.
References:
tf.distribute.Strategy.experimental_distribute_dataset
Custom training loop
TPU overview
tf.distribute.TPUStrategy
Vertex AI Training accelerators
[TPU programming model]
[Batch size and learning rate]
[Keras overview]
[tf.distribute.MirroredStrategy]
[Vertex AI Training overview]
[TensorFlow overview]
NEW QUESTION # 172
You want to migrate a scikrt-learn classifier model to TensorFlow. You plan to train the TensorFlow classifier model using the same training set that was used to train the scikit-learn model and then compare the performances using a common test set. You want to use the Vertex Al Python SDK to manually log the evaluation metrics of each model and compare them based on their F1 scores and confusion matrices. How should you log the metrics?


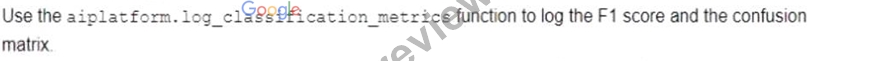

Answer: D
Explanation:
To log the metrics of a machine learning model in TensorFlow using the Vertex AI Python SDK, you should utilize the aiplatform.log_metrics function to log the F1 score and aiplatform.log_classification_metrics function to log the confusion matrix. These functions allow users to manually record and store evaluation metrics for each model, facilitating an efficient comparison based on specific performance indicators like F1 scores and confusion matrices. References: The answer can be verified from official Google Cloud documentation and resources related to Vertex AI and TensorFlow.
* Vertex AI Python SDK reference | Google Cloud
* Logging custom metrics | Vertex AI
* Migrating from scikit-learn to TensorFlow | TensorFlow
NEW QUESTION # 173
A Machine Learning Specialist deployed a model that provides product recommendations on a company's website. Initially, the model was performing very well and resulted in customers buying more products on average. However, within the past few months, the Specialist has noticed that the effect of product recommendations has diminished and customers are starting to return to their original habits of spending less.
The Specialist is unsure of what happened, as the model has not changed from its initial deployment over a year ago.
Which method should the Specialist try to improve model performance?
Answer: A
NEW QUESTION # 174
You are an ML engineer at a bank. You have developed a binary classification model using AutoML Tables to predict whether a customer will make loan payments on time. The output is used to approve or reject loan requests. One customer's loan request has been rejected by your model, and the bank's risks department is asking you to provide the reasons that contributed to the model's decision. What should you do?
Answer: D
NEW QUESTION # 175
......
To solve all these problems, PassReview offers actual Professional-Machine-Learning-Engineer Questions to help candidates overcome all the obstacles and difficulties they face during Professional-Machine-Learning-Engineer examination preparation. With vast experience in this field, PassReview always comes forward to provide its valued customers with authentic, actual, and genuine Professional-Machine-Learning-Engineer Exam Dumps at an affordable cost. All the Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) questions given in the product are based on actual examination topics.
Professional-Machine-Learning-Engineer Exam Quizzes: https://www.passreview.com/Professional-Machine-Learning-Engineer_exam-braindumps.html
What's more, part of that PassReview Professional-Machine-Learning-Engineer dumps now are free: https://drive.google.com/open?id=1oR5QZmzmvjY-OdAIU--AMRzxgvbCFAAp