私たちのサービス理念は、クライアントが最高のユーザー体験を得て満足することです。調査、編集、制作から販売、アフターサービスまで、お客様に利便性を提供し、AI-300ガイド資料を最大限に活用できるように最善を尽くします。エキスパートチームを編成してAI-300実践ガイドを精巧にまとめ、常に更新しています。クライアントがAI-300トレーニング資料を基本的に理解できるように、購入前にAI-300試験問題の無料トライアルを提供しています。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Design and implement a GenAIOps infrastructure | 20–25% | - Set up Microsoft Foundry environment
|
| Topic 2: Implement machine learning model lifecycle and operations | 25–30% | - Orchestrate model training and experimentation
|
| Topic 3: Implement generative AI quality assurance and observability | 10–15% | - Monitor generative AI systems
|
| Topic 4: Optimize generative AI systems and model performance | 15–20% | - Optimize model selection and configuration
|
| Topic 5: Design and implement an MLOps infrastructure | 15–20% | - Create and manage Machine Learning workspace resources and assets
|
AI-300試験問題を購入する前に、無料でダウンロードして試してみることができます。また、WebサイトのAI-300学習ガイドのページにアクセスして、AI-300試験問題を理解することができます。 Pass4TestのAI-300ガイドトレントのページはデモを提供し、タイトルの一部とソフトウェアの形式を理解できます。そのため、購入する前にAI-300試験問題を理解し、AI-300試験問題を購入するかどうかを決定できます。
質問 # 61
You deploy a new model version to a managed online endpoint. You must test it with 10% traffic and automatically roll back if latency or error rate increases beyond threshold. What should you configure?
正解:A
解説:
Traffic splitting enables controlled rollout of a new model version by directing a percentage of requests to it. Combined with monitoring alerts, it supports automated rollback when performance degrades. Separate endpoints lack built-in traffic management and do not provide seamless or automated rollback capabilities.
質問 # 62
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have an Azure Machine Learning workspace. You connect to a terminal session from the Notebooks page in Azure Machine Learning studio.
You plan to add a new Jupyter kernel that will be accessible from the same terminal session.
You need to perform the task that must be completed before you can add the new kernel.
Solution: Delete the Python 3.6 - AzureML kernel.
Does the solution meet the goal?
正解:A
解説:
Correct:
* Create an environment.
Incorrect:
* Delete the Python 3.6 - AzureML kernel.
* Delete the Python 3.8 - AzureML kernel.
Note:
Before you can add a new Jupyter kernel on an Azure Machine Learning compute instance terminal, you must create a Conda environment.
Required Workflow
To officially provision and expose the new kernel to your Azure Machine Learning studio Notebooks, you need to execute the following full process from your terminal session:
Create the environment: Provision a new isolated environment (e.g., using conda create -n newenv python=3.10).
Activate the environment: Run conda activate newenv.
Install dependencies: Add the required ipykernel package using conda install ipykernel or pip install ipykernel.
Register the kernel: Bind the new environment configuration to the global Jupyter directory by running:
python -m ipykernel install --user --name newenv --display-name "My New Kernel" Reference:
https://docs.azure.cn/en-us/machine-learning/how-to-access-terminal
質問 # 63
You have an Azure subscription named Sub1 that contains an Azure Machine Learning workspace named Workspace1. Workspace1 contains the following assets:
- a registered MLflow model named Model1
- an online endpoint named Endpoint1
Outbound network connectivity from Endpoint1 is blocked.
You need to deploy Model1 to Endpoint1.
What should you do first?
正解:D
解説:
To successfully deploy the registered MLflow model to an online endpoint that lacks outbound internet connectivity, you must use model packaging to build a deployment package before deploying.
By default, Azure Machine Learning deploys MLflow models using a "no-code deployment" approach, which requires an outbound internet connection during container runtime to dynamically download and install Python dependencies listed in the model's conda.yaml file.
Because outbound connectivity is blocked, this process fails. Packaging the model bundles the model binaries, dependencies, and environment ahead of time, entirely removing the requirement for runtime internet access.
Reference:
https://docs.azure.cn/en-us/machine-learning/how-to-deploy-mlflow-models-online-endpoints
質問 # 64
You have an Azure Machine Learning workspace.
You have the following code: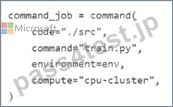
You plan to rely on serverless compute to train a model by using Azure Machine Learning Python SDK v2.
The serverless compute must use a designated number of nodes of a specific virtual machine type.
You need to modify the code to run the training job according to the plan.
How should you modify the command object? To answer, select the appropriate oations in the answer area.
NOTE: Each correct selection is worth one point.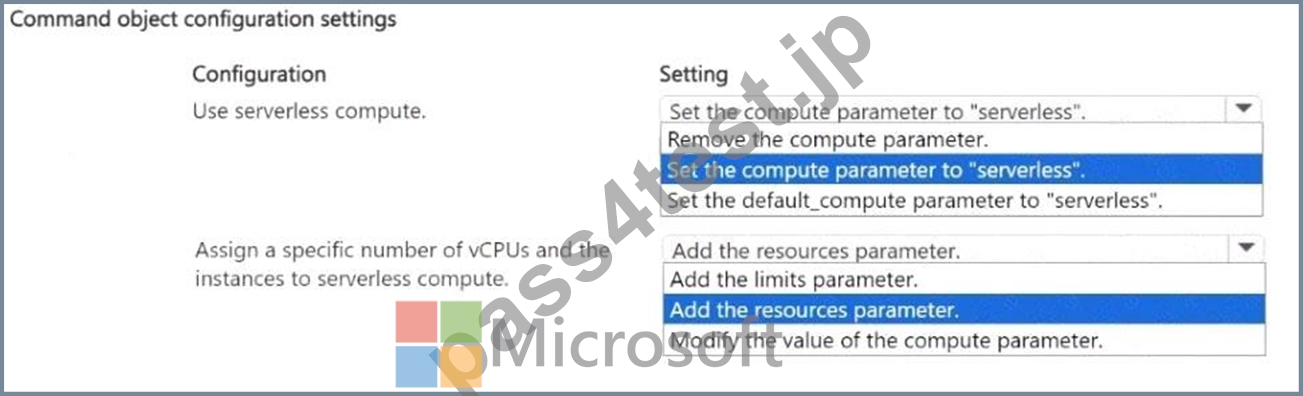
正解:
解説: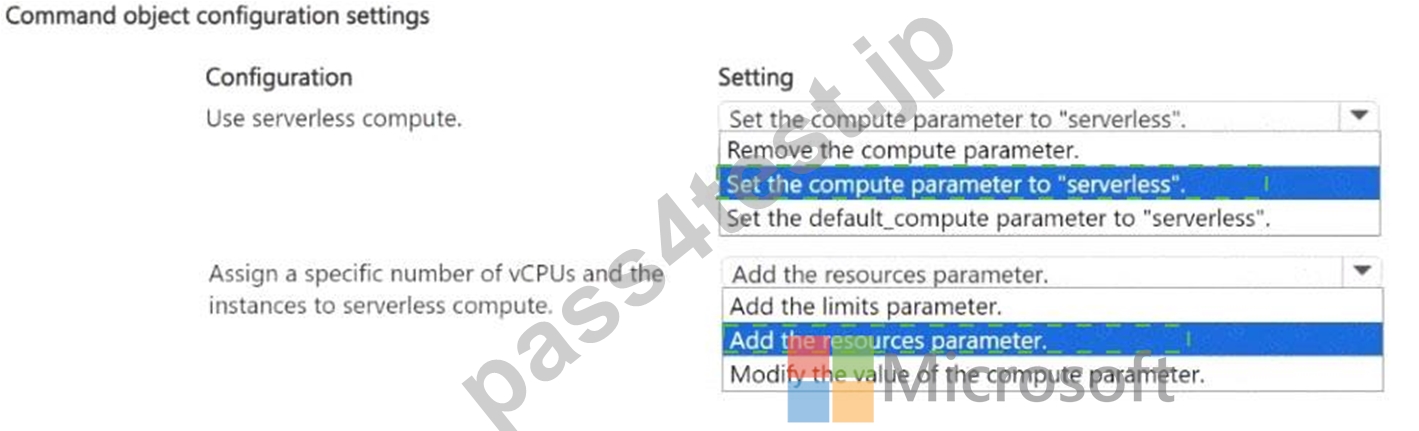
Explanation: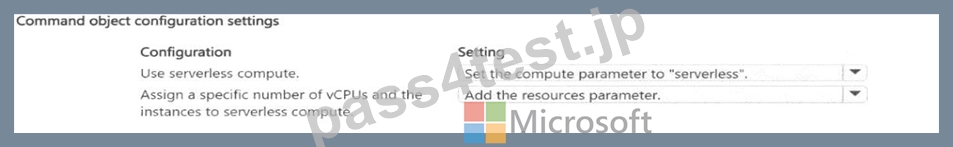
質問 # 65
A team deploys a classification model to production and scores incoming customer data daily.
After several weeks, business stakeholders report unexpected changes in prediction behavior, even though the endpoint remains healthy.
You need to determine whether data drift is occurring and if it is, identify the appropriate actions.
Which action should you perform for each observed signal? To answer, move the appropriate actions to the correct observed signals. You may use each action once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.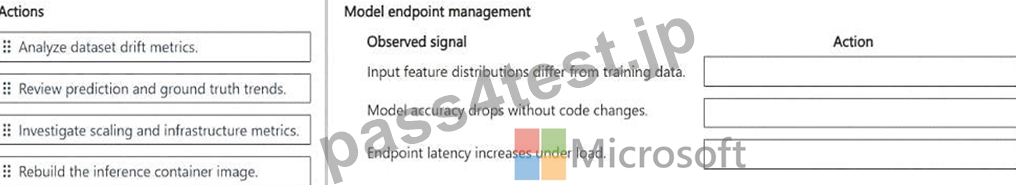
正解:
解説: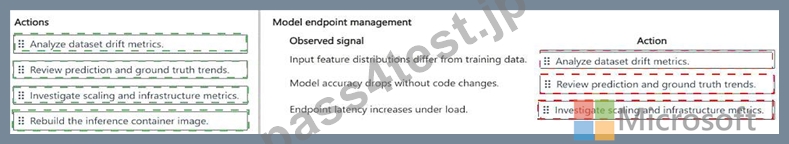
Explanation:
Input feature distributions differ from training data: Analyze dataset drift metrics Model accuracy drops without code changes: Review prediction and ground truth trends Endpoint latency increases under load: Investigate scaling and infrastructure metrics When input feature distributions differ from training data , the correct action is to analyze dataset drift metrics . Azure Machine Learning model monitoring detects data drift by comparing the statistical distributions of production model inputs against reference data, commonly the original training dataset.
Supported measures include Population Stability Index, Jensen-Shannon distance, normalized Wasserstein distance, and statistical tests such as Kolmogorov-Smirnov.
When model accuracy drops without code changes , the next investigation should focus on prediction and ground-truth trends . Azure Machine Learning model-performance monitoring compares production predictions with collected actual outcomes and can calculate classification metrics such as accuracy, precision, and recall. A declining score without deployment changes may indicate concept drift, prediction drift, or changing relationships between input features and target outcomes.
When endpoint latency increases under load , the issue is operational rather than primarily statistical. The team should investigate scaling and infrastructure metrics , including request latency, requests per minute, CPU/memory utilization, throttling, and replica capacity. Microsoft recommends using endpoint metrics to determine whether compute must scale up or out.
Rebuild the inference container image is not indicated by any of the observed signals.
Study Guide Reference: Implement machine learning model lifecycle and operations - production monitoring, data drift, model-performance monitoring, endpoint observability, and scaling.
質問 # 66
......
AI-300試験に合格することが、最高のキャリアの機会です。 関連する証明書の豊富な経験は、企業があなたの選択のために一連の専門的な空席を開くために重要です。 当社のウェブサイトのAI-300学習クイズバンクおよび教材は、選択したトピックに基づいて最新の質問と回答を検索します。 この選択は、あなたのキャリア全体の突破口となるので、AI-300スタディガイドの高い品質と正確性に驚かされるでしょう。
AI-300認定資格試験問題集: https://www.pass4test.jp/AI-300.html