To be well-prepared, you require trust worthy and reliable Exams4Collection practice material. You also require accurate Exams4Collection study material to polish your capabilities and improve your chances of passing the Databricks-Certified-Professional-Data-Engineer certification exam. Exams4Collection facilitates your study with updated Databricks Databricks-Certified-Professional-Data-Engineer Exam Dumps. This Databricks-Certified-Professional-Data-Engineer exam prep material has been prepared under the expert surveillance of 90,000 highly experienced Exams4Collection professionals worldwide.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Professional Data Engineer Exam |
| Exam Number: | Databricks-Certified-Professional-Data-Engineer |
| Passing Score: | 70% |
| Real Exam Qty: | 60 |
| Related Certifications: | Databricks Certified Data Analyst Associate Databricks Certified Associate Developer |
| Exam Price: | $200 USD |
| Available Languages: | English |
| Exam Duration: | 90 minutes |
| Exam Format: | Multiple Choice, Multiple Select |
| Certificate Validity Period: | 2 years |
| Sample Questions: | Databricks Databricks-Certified-Professional-Data-Engineer Sample Questions |
| Exam Way: | Online proctored exam (Pearson VUE) |
| Pre Condition: | Recommended: 6+ months of hands-on experience with Databricks and data engineering concepts; familiarity with Python or Scala and SQL is strongly recommended |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/professional-data-engineer |
>> Exam Databricks-Certified-Professional-Data-Engineer Revision Plan <<
Our Databricks-Certified-Professional-Data-Engineer exam torrent is available in PDF, software, and online three modes, which allowing you to switch learning materials on paper, on your phone or on your computer, and to study anywhere and anytime with the according version of Databricks-Certified-Professional-Data-Engineer practice test. Before you purchase the system, Databricks-Certified-Professional-Data-Engineer Practice Test provides you with a free trial service, so that customers can fully understand our system before buying; after the online payment is successful, you can receive mail from customer service in 5 to 10 minutes, and then immediately begin to learn Databricks-Certified-Professional-Data-Engineer training prep.
Databricks, a unified analytics platform provider that helps organizations process and analyze large data sets, offers a certification exam for data engineers called the Databricks Certified Professional Data Engineer. Databricks-Certified-Professional-Data-Engineer Exam is designed to test the skills and knowledge of data engineers in building and managing data pipelines, ETL processes, and data architectures within the Databricks platform. Databricks Certified Professional Data Engineer Exam certification is intended to validate the expertise of data engineers in implementing and managing data projects, and to demonstrate their competency in using the Databricks platform.
NEW QUESTION # 159
A junior data engineer is migrating a workload from a relational database system to the Databricks Lakehouse.
The source system uses a star schema, leveraging foreign key constrains and multi-table inserts to validate records on write.
Which consideration will impact the decisions made by the engineer while migrating this workload?
Answer: D
Explanation:
In Databricks and Delta Lake, transactions are indeed ACID-compliant, but this compliance is limited to single table transactions. Delta Lake does not inherently enforce foreign key constraints, which are a staple in relational database systems for maintaining referential integrity between tables. This means that when migrating workloads from a relational database system to Databricks Lakehouse, engineers need to reconsider how to maintain data integrity and relationships that were previously enforced by foreign key constraints.
Unlike traditional relational databases where foreign key constraints help in maintaining the consistency across tables, in Databricks Lakehouse, the data engineer has to manage data consistency and integrity at the application level or through careful design of ETL processes.References:
* Databricks Documentation on Delta Lake: Delta Lake Guide
* Databricks Documentation on ACID Transactions in Delta Lake: ACID Transactions in Delta Lake
NEW QUESTION # 160
A streaming video analytics team ingests billions of events daily into a Unity Catalog-managed Delta table video_events . Analysts run ad-hoc point-lookup queries on columns like user_id, campaign_id, and region.
The team manually runs OPTIMIZE video_events ZORDER BY (user_id, campaign_id, region), but still sees poor performance on recent data and dislikes the operational overhead. The team wants a hands-off way to keep hot columns co-located as query patterns evolve.
Answer: C
Explanation:
According to Databricks Delta Lake optimization documentation, Liquid Clustering is a next-generation file organization capability that automatically manages file co-location without requiring explicit partitioning or manual Z-ORDERing. When combined with Predictive Optimization , Databricks automatically maintains clustering across frequently filtered or queried columns, adapting dynamically as query workloads evolve.
This approach eliminates the need for manual maintenance (such as periodic OPTIMIZE or Z-ORDER commands) while improving query performance on large tables-particularly for high-ingest streaming workloads.
Delta caching (B) only improves performance for cached queries and does not address file layout issues, and (D) handles file size optimization but not clustering. Thus, C is the most efficient, modern, and low- maintenance solution recommended by Databricks.
NEW QUESTION # 161
A data governance team at a large enterprise is improving data discoverability across its organization. The team has hundreds of tables in their Databricks Lakehouse with thousands of columns that lack proper documentation. Many of these tables were created by different teams over several years, with missing context about column meanings and business logic. The data governance team needs to quickly generate comprehensive column descriptions for all existing tables to meet compliance requirements and improve data literacy across the organization. They want to leverage modern capabilities to automatically generate meaningful descriptions rather than manually documenting each column, which would take months to complete.
Which approach should the team use in Databricks to automatically generate column comments and descriptions for existing tables?
Answer: C
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
Databricks Catalog Explorer provides a feature called AI Generate that automatically produces intelligent comments for columns. This feature uses metadata such as column names, types, patterns, and sampled values to generate human-readable documentation. According to the documentation, this is the recommended method to rapidly enrich schema metadata and improve data discoverability, especially at enterprise scale. Unlike DESCRIBE HISTORY or DESCRIBE TABLE, which only surface technical schema details, AI Generate directly produces business-oriented descriptions. PySpark statistical functions (df.describe) only return numeric statistics and cannot generate descriptive metadata. Thus, AI Generate in Catalog Explorer is the correct approach.
NEW QUESTION # 162
A nightly job ingests data into a Delta Lake table using the following code: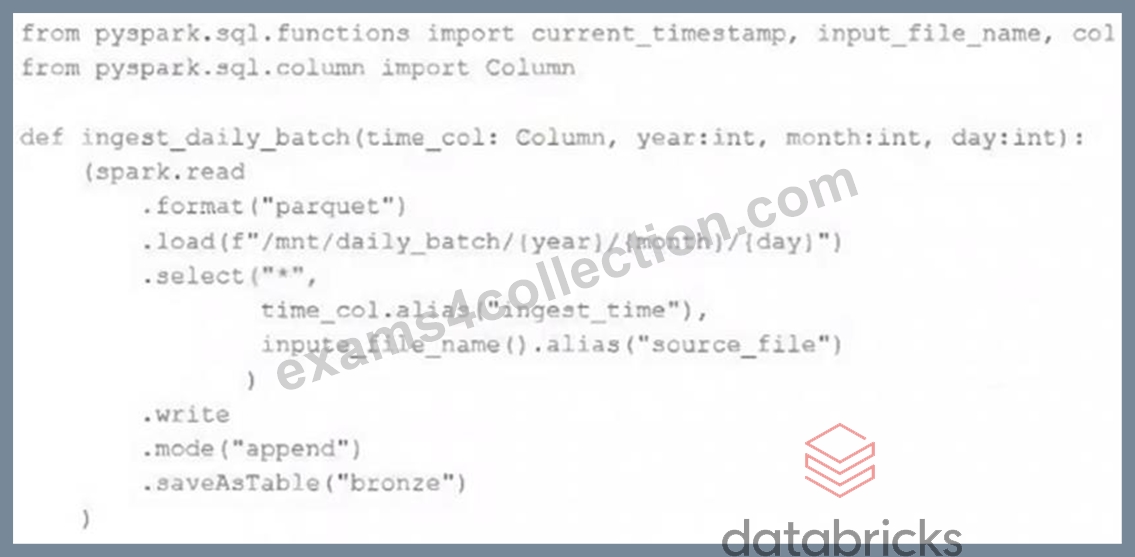
The next step in the pipeline requires a function that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline.
Which code snippet completes this function definition?
def new_records():
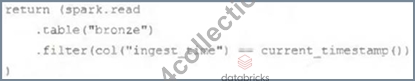
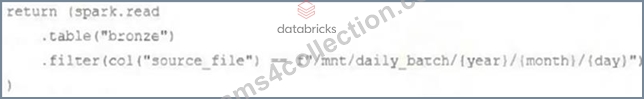
Answer: E
Explanation:
https://docs.databricks.com/en/delta/delta-change-data-feed.html
NEW QUESTION # 163
The following table consists of items found in user carts within an e-commerce website.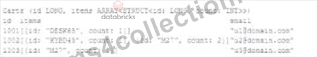
The following MERGE statement is used to update this table using an updates view, with schema evaluation enabled on this table.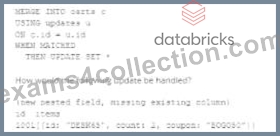
How would the following update be handled?
Answer: C
Explanation:
With schema evolution enabled in Databricks Delta tables, when a new field is added to a record through a MERGE operation, Databricks automatically modifies the table schema to include the new field. In existing records where this new field is not present, Databricks will insert NULL values for that field. This ensures that the schema remains consistent across all records in the table, with the new field being present in every record, even if it is NULL for records that did not originally include it.
References:
* Databricks documentation on schema evolution in Delta Lake:
https://docs.databricks.com/delta/delta-batch.html#schema-evolution
NEW QUESTION # 164
......
Latest Databricks-Certified-Professional-Data-Engineer Braindumps: https://www.exams4collection.com/Databricks-Certified-Professional-Data-Engineer-latest-braindumps.html