The Microsoft AI-200 exam questions on the platform have been gathered by subject matter experts to ensure that they accurately reflect the format and difficulty level of the actual Microsoft AI-200 exam. This makes these Developing AI Cloud Solutions on Azure PDF Questions ideal for individuals looking to pass the Microsoft AI-200 Exam on their first try. You can evaluate the product with a free AI-200 demo.
| Section | Objectives |
|---|---|
| Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
| Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Develop containerized solutions on Azure | - Implement containerized applications
|
| Connect to and consume Azure services | - Integrate Azure services
|
>> Hot Microsoft AI-200 Spot Questions <<
How you can gain the AI-200 certification with ease in the least time? The answer is our AI-200 study materials for we have engaged in this field for over ten years and we have become the professional standard over all the exam materials. You can free download the demos which are part of our AI-200 Exam Braindumps, you will find that how good they are for our professionals devote of themselves on compiling and updating the most accurate content of our AI-200 exam questions.
NEW QUESTION # 61
You are building a RAG (retrieval-augmented generation) solution using Azure AI Foundry. The knowledge base consists of 50,000 PDF documents stored in Azure Blob Storage. You need to make the document content searchable by the language model with minimal custom code. What should you use?
Answer: D
Explanation:
Azure AI Search's integrated vectorization feature lets you point a skillset directly at a blob data source, and it handles chunking, embedding generation (via an Azure OpenAI embedding model), and indexing automatically -- minimizing custom code compared to manually building a chunking/embedding pipeline.
NEW QUESTION # 62
You have an existing AKS cluster and a container image stored in Azure Container Registry.
You must deploy a new version by using a Deployment manifest that supports rolling updates without interrupting traffic.
You need to perform a rolling update by using a manifest file.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.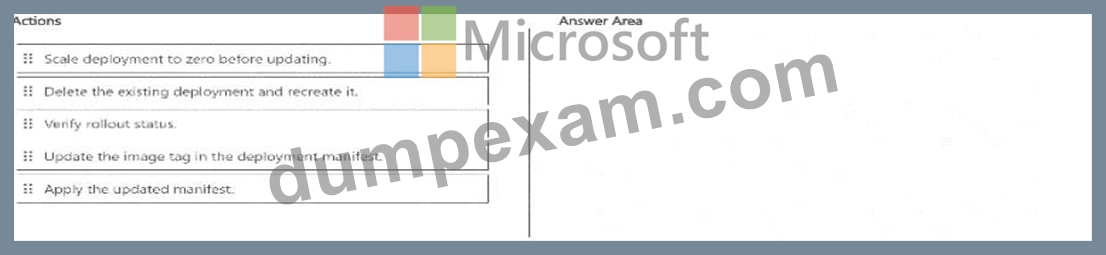
Answer:
Explanation: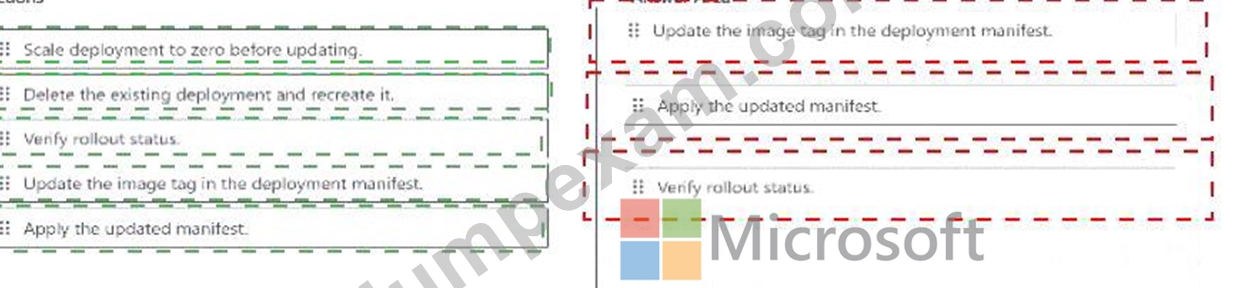
Explanation: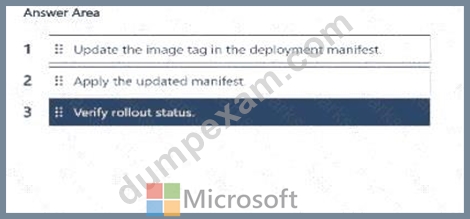
NEW QUESTION # 63
An application performs similarity search across 5 million embeddings stored in Azure Database for PostgreSQL with pgvector. Queries often filter by department before ranking by cosine distance.
P95 latency for vector similarity queries exceeds the SLA target. Monitoring shows sustained high CPU use during query execution.
You need to reduce P95 latency for filtered vector similarity queries.
What should you do?
Answer: A
Explanation:
Creating a B-tree index on the department column will help, but only if you use the correct indexing strategy, as a standard B-tree index alone is often ignored during vector searches.
When you run a query that filters by metadata before performing a vector similarity search, PostgreSQL must choose between filtering the rows first or searching the vector index first. In many cases, a standard B-tree index on the metadata column combined with an HNSW/IVFFlat index on the vector column results in pre-filtering that defaults to a sequential scan, or post- filtering that returns fewer results than requested.
Reference:
https://learn.microsoft.com/en-us/azure/horizondb/ai/vector-search-pgvector
NEW QUESTION # 64
You are configuring sampling for a distributed application that sends traces to Azure Monitor. The solution must:
* Preserve upstream sampling decisions across distributed traces
* Capture all spans during local testing.
* Sample 10 percent of traces in production.
You need to apply the appropriate sampling configuration for each requirement.
What should you do? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once or not at all. You may need to move the split bar Between panes or scroll to view content.
NOTE: Each correct selection is worth one point.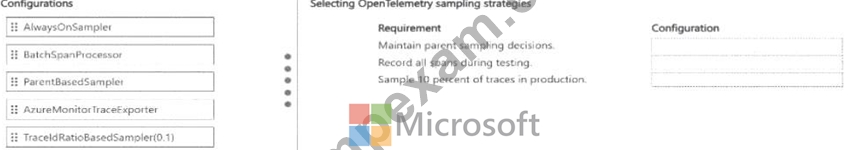
Answer:
Explanation: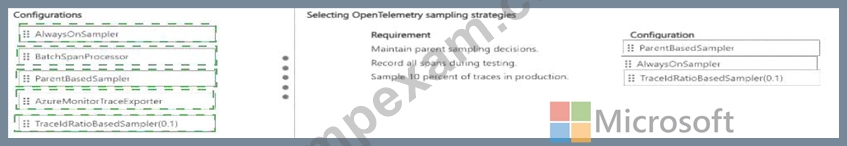
Explanation: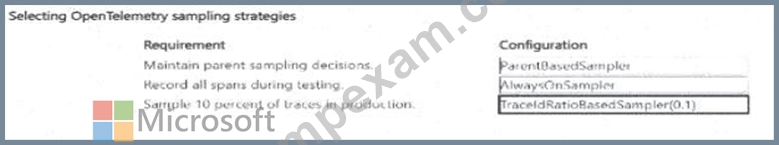
Verified answer: Preserve parent sampling decisions: ParentBasedSampler. Capture all spans locally:
AlwaysOnSampler. Sample 10% in production: TraceIdRatioBasedSampler(0.1).
Detailed Explanation: Parent-based sampling propagates the sampling decision from the upstream parent, preventing broken sampling decisions across a distributed trace. AlwaysOnSampler records every span, which is suitable for local test environments where complete trace visibility is more important than telemetry volume. TraceIdRatioBasedSampler with 0.1 selects approximately ten percent of traces based on trace identifiers, providing deterministic fixed-ratio sampling for production. A batch span processor and an exporter control processing/export, not the sampling decision itself.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | OpenTelemetry sampling in Azure Monitor | Enable Azure Monitor OpenTelemetry
NEW QUESTION # 65
You are developing an AI application that retrieves database credentials from Key Vault by using the Azure SDK for Python.
The application must use managed identity for authentication.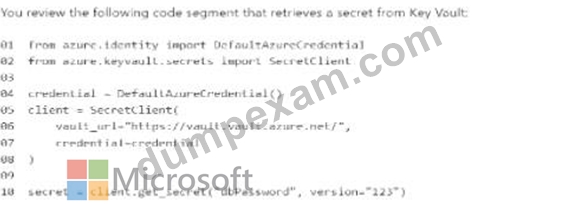
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.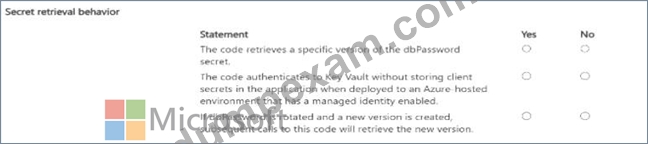
Answer:
Explanation: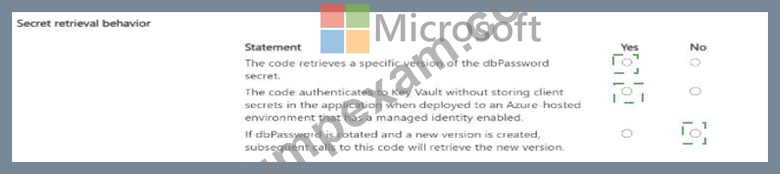
Explanation: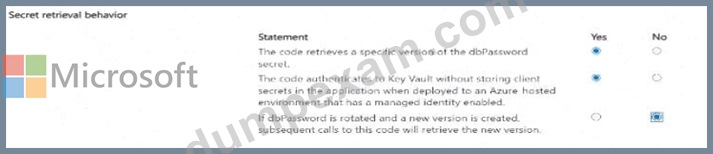
Verified answer: Yes; Yes; No.
Detailed Explanation: The get_secret call supplies an explicit version value, so it retrieves that particular version of dbPassword. DefaultAzureCredential can authenticate to Key Vault by using the Azure-hosted application's managed identity without embedding a client secret in the application. Because the code requests a fixed version, later secret rotation creates a newer version but subsequent executions of this exact code continue to request the specified old version. To follow the latest version automatically, the version parameter must be omitted.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | Managed identities for Azure resources | Use Key Vault references for App Service and Functions
NEW QUESTION # 66
......
It is indeed not easy to make a decision. AI-200 study engine is willing to give you a free trial. If you have some knowledge of our AI-200 training materials, but are not sure whether it is suitable for you, you can email us to apply for a free trial version. You know, we have provided three versions of AI-200 practice quiz: the PDF, Software and APP online. Accordingly, we have three free trial versions as well.
AI-200 Questions Exam: https://www.dumpexam.com/AI-200-valid-torrent.html