Reliable Certified-Data-Engineer-Professional Exam Blueprint | Certified-Data-Engineer-Professional Valid Test Topics

Elaborately designed and developed Certified-Data-Engineer-Professional test guide as well as good learning support services are the key to assisting our customers to realize their dreams. Our Certified-Data-Engineer-Professional study braindumps have a variety of self-learning and self-assessment functions to detect learners’ study outcomes, and the statistical reporting function of our Certified-Data-Engineer-Professional Test Guide is designed for students to figure out their weaknesses and tackle the causes, thus seeking out specific methods dealing with them. Our Certified-Data-Engineer-Professional exam guide have also set a series of explanation about the complicated parts certificated.
| Section | Objectives |
|---|
| Topic 1: Monitoring and Alerting | - Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
- Monitoring
- 1. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 2. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 3. Use Query Profile and Spark UI to monitor workloads
- 4. Use system tables for observability of resource utilization, cost, auditing, and workloads
|
| Topic 2: Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 2. Apply Change Data Feed to address streaming table limitations and improve latency
- 3. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 4. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 5. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
|
| Topic 3: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Topic 4: Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 2. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 3. Develop User-Defined Functions using Pandas/Python UDF
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 2. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 3. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 4. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 5. Create pipeline components using control flow operators such as if/else and foreach
- 6. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 7. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 8. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
|
| Topic 5: Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 2. Use row filters and column masks to protect sensitive table data
- 3. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
|
| Topic 6: Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Configure Lakehouse Federation with appropriate governance across supported source systems
|
| Topic 7: Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Topic 8: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Topic 9: Data Modeling | - Design and optimize data models
- 1. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 2. Simplify data layout decisions and optimize query performance using liquid clustering
- 3. Design and implement scalable data models using Delta Lake to manage large datasets
- 4. Design dimensional models for analytical workloads with efficient querying and aggregation
|
| Topic 10: Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- Debugging and Troubleshooting
- 1. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 2. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 3. Analyze errors and remediate failed job runs using job repairs and parameter overrides
|
>> Reliable Certified-Data-Engineer-Professional Exam Blueprint <<
Certified-Data-Engineer-Professional Valid Test Topics | Certified-Data-Engineer-Professional Reliable Test Objectives
The Certified Production and Certified-Data-Engineer-Professional certification is a valuable credential earned by individuals to validate their skills and competence to perform certain job tasks. Your Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional Certification is usually displayed as proof that you’ve been trained, educated, and prepared to meet the specific requirement for your professional role.
Databricks Certified Data Engineer Professional Sample Questions (Q87-Q92):
NEW QUESTION # 87
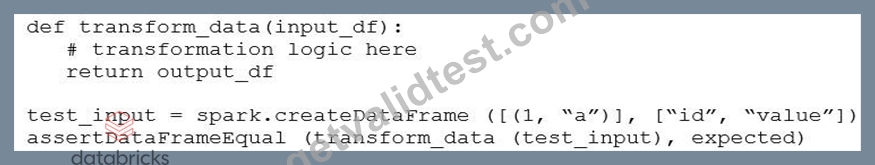
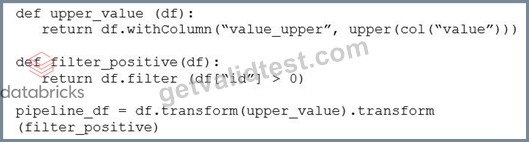
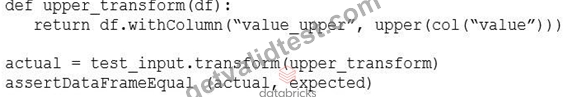
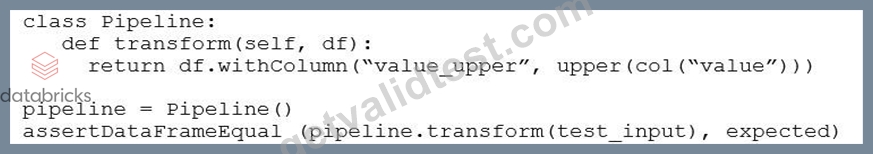
Which approach demonstrates a modular and testable way to use DataFrame transform for ETL code in PySpark?
Answer: C
Explanation:
Using DataFrame.transform with a pure transformation function promotes modular, reusable, and easily testable ETL logic. Each transformation is encapsulated as a standalone function, can be independently unit tested, and composed cleanly in a pipeline without coupling to orchestration or class state.
NEW QUESTION # 88
A data team is working to optimize an existing large, fast-growing table 'orders' with high cardinality columns, which experiences significant data skew and requires frequent concurrent writes. The team notice that the columns 'user_id', 'event_timestamp' and 'product_id' are heavily used in analytical queries and filters, although those keys may be subject to change in the future due to different business requirements. Which partitioning strategy should the team choose to optimize the table for immediate data skipping, incremental management over time, and flexibility?
- A. Partition the table with: ALTER TABLE orders PARTITION BY user_id, product_id, event_timestamp
- B. Z-order the table with OPTIMIZE orders ZORDER BY (user_id, product_id, event_timestamp)
- C. Cluster the table with: ALTER TABLE orders CLUSTER BY user_id, product_id, event_timestamp
- D. Use z-order after partitiing the table: OPTIMIZE orders ZORDER BY (user_id, product_id) WHERE event_timestamp = current date () - 1 DAY
Answer: B
Explanation:
Z-ordering optimizes data skipping for selective queries on high-cardinality columns without physically repartitioning the table, making it flexible if query patterns change. Using OPTIMIZE ...
ZORDER BY (user_id, product_id, event_timestamp) improves query performance for filters and joins while allowing incremental writes, avoiding the data skew and maintenance overhead that explicit partitioning or clustering could introduce.
NEW QUESTION # 89
Incorporating unit tests into a PySpark application requires upfront attention to the design of your jobs, or a potentially significant refactoring of existing code.
Which statement describes a main benefit that offset this additional effort?
- A. Ensures that all steps interact correctly to achieve the desired end result
- B. Improves the quality of your data
- C. Troubleshooting is easier since all steps are isolated and tested individually
- D. Validates a complete use case of your application
- E. Yields faster deployment and execution times
Answer: C
Explanation:
Unit tests are small, isolated tests that are used to check specific parts of the code, such as functions or classes.
NEW QUESTION # 90
A data engineer needs to create an application that will collect information about the latest job run including the repair history. How should the data engineer format the request?
- A. Call/api/2.1/jobs/runs/list with the job_id and include_history parameters
- B. Call/api/2.1/jobs/runs/list with the run_id and include_history parameters
- C. Call/api/2.1/jobs/runs/get with the run_id and include_history parameters
- D. Call/api/2.1/jobs/runs/get with the job_id and include_history parameters
Answer: A
Explanation:
To retrieve information about the latest job runs along with their repair history, you use the jobs/runs/list endpoint with the job_id and include_history=true. This endpoint returns a list of runs for a specific job, including details about retries and repair attempts, which is not available via runs/get that retrieves a single run by run_id.
NEW QUESTION # 91
A view is registered with the following code:
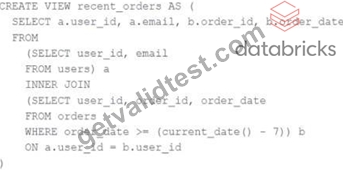
Both users and orders are Delta Lake tables.
Which statement describes the results of querying recent_orders?
- A. All logic will execute when the view is defined and store the result of joining tables to the DBFS; this stored data will be returned when the view is queried.
- B. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query finishes.
- C. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query began.
- D. Results will be computed and cached when the view is defined; these cached results will incrementally update as new records are inserted into source tables.
Answer: C
NEW QUESTION # 92
......
Our company has employed a lot of leading experts in the field to compile the Certified-Data-Engineer-Professional exam question. Our system of team-based working is designed to bring out the best in our people in whose minds and hands the next generation of the best Certified-Data-Engineer-Professional exam torrent will ultimately take shape. Our company has a proven track record in delivering outstanding after sale services and bringing innovation to the guide torrent. Your success is guaranteed for our experts can produce world class Certified-Data-Engineer-Professional Guide Torrent for our customers. You will be bound to pass the Certified-Data-Engineer-Professional exam.
Certified-Data-Engineer-Professional Valid Test Topics: https://www.getvalidtest.com/Certified-Data-Engineer-Professional-exam.html
- 2026 Databricks Certified-Data-Engineer-Professional Realistic Reliable Exam Blueprint 🦝 Search for ▛ Certified-Data-Engineer-Professional ▟ and download it for free on ✔ www.dumpsmaterials.com ️✔️ website 📹Certified-Data-Engineer-Professional Brain Dump Free
- 2026 Databricks Certified-Data-Engineer-Professional Realistic Reliable Exam Blueprint 🏥 ⏩ www.pdfvce.com ⏪ is best website to obtain ➥ Certified-Data-Engineer-Professional 🡄 for free download 🍵Certified-Data-Engineer-Professional Training Solutions
- Certified-Data-Engineer-Professional Reliable Exam Questions 💳 Certified-Data-Engineer-Professional Reliable Exam Questions 🤳 Exam Certified-Data-Engineer-Professional Registration ⛲ Simply search for ⏩ Certified-Data-Engineer-Professional ⏪ for free download on ( www.prep4away.com ) 🚅Certified-Data-Engineer-Professional Useful Dumps
- Top Certified-Data-Engineer-Professional Questions 🙎 Certified-Data-Engineer-Professional Trusted Exam Resource ⚽ Certified-Data-Engineer-Professional Trusted Exam Resource 🦨 Simply search for “ Certified-Data-Engineer-Professional ” for free download on ➠ www.pdfvce.com 🠰 💁Certified-Data-Engineer-Professional Reliable Exam Questions
- Certified-Data-Engineer-Professional Useful Dumps 🔚 Certified-Data-Engineer-Professional Exam Quick Prep 👄 Test Certified-Data-Engineer-Professional Dumps.zip 🚥 Download { Certified-Data-Engineer-Professional } for free by simply entering “ www.vce4dumps.com ” website ⏺Certified-Data-Engineer-Professional Useful Dumps
- Top Certified-Data-Engineer-Professional Questions 🌤 Certified-Data-Engineer-Professional Valid Test Voucher 🌍 Certified-Data-Engineer-Professional Reliable Study Materials ⚡ Open website ▷ www.pdfvce.com ◁ and search for ( Certified-Data-Engineer-Professional ) for free download 💗Certified-Data-Engineer-Professional Reliable Study Materials
- Official Certified-Data-Engineer-Professional Practice Test 🚝 Pass Leader Certified-Data-Engineer-Professional Dumps ⬆ Certified-Data-Engineer-Professional Useful Dumps 🧖 Search for 「 Certified-Data-Engineer-Professional 」 and obtain a free download on 「 www.exam4labs.com 」 🍘Certified-Data-Engineer-Professional Exam Quick Prep
- 2026 Databricks Certified-Data-Engineer-Professional Realistic Reliable Exam Blueprint 🥬 Search for ☀ Certified-Data-Engineer-Professional ️☀️ and obtain a free download on ( www.pdfvce.com ) 😴Certified-Data-Engineer-Professional Exam Quick Prep
- Certified-Data-Engineer-Professional Reliable Study Materials 🔩 Exam Certified-Data-Engineer-Professional Registration 👮 Top Certified-Data-Engineer-Professional Questions 👣 Open website ( www.vce4dumps.com ) and search for ➽ Certified-Data-Engineer-Professional 🢪 for free download 📪Exam Certified-Data-Engineer-Professional Registration
- Pass Guaranteed 2026 Databricks Certified-Data-Engineer-Professional: Trustable Reliable Databricks Certified Data Engineer Professional Exam Blueprint 🦕 Search for “ Certified-Data-Engineer-Professional ” and download it for free immediately on ✔ www.pdfvce.com ️✔️ 💏Certified-Data-Engineer-Professional Brain Dump Free
- Certified-Data-Engineer-Professional Trusted Exam Resource 💸 Certified-Data-Engineer-Professional Useful Dumps 📚 Certified-Data-Engineer-Professional Reliable Exam Camp 🦞 Search for { Certified-Data-Engineer-Professional } and download exam materials for free through ⮆ www.exam4labs.com ⮄ 😎Exam Certified-Data-Engineer-Professional Demo
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, blogfreely.net, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes