What's more, part of that VCETorrent ARA-C01 dumps now are free: https://drive.google.com/open?id=1exB38YaYWrCTmmAcAuXXCNg_aSPAs3LD
Our Snowflake ARA-C01 practice exam software will record all the attempts you have made in the past and display any modifications or improvements made in each attempt. This SnowPro Advanced Architect Certification (ARA-C01) exam simulation software enables you to track your progress and quantify how much you have improved.
| Section | Objectives |
|---|---|
| Topic 1: Performance and Optimization | - Cost optimization
|
| Topic 2: Data Pipelines and Data Engineering | - Data ingestion and transformation
|
| Topic 3: Data Architecture and Design | - Design scalable Snowflake architectures
|
| Topic 4: Data Sharing and Collaboration | - Secure data sharing
|
| Topic 5: Security, Governance, and Compliance | - Access control and security model
|
>> Snowflake ARA-C01 Valid Test Notes <<
When you decide to buy a product, you definitely want to use it right away. Our staffs who are working on the ARA-C01 exam questions certainly took this into consideration. Many of our worthy customers worried that it will take a long time to get our ARA-C01 study braindumps, but in fact as long as your payment is successful, we will send a link of the ARA-C01 learning guide to your e-mail within five to ten minutes. You can download and study with our ARA-C01 practice engine immediately.
NEW QUESTION # 40
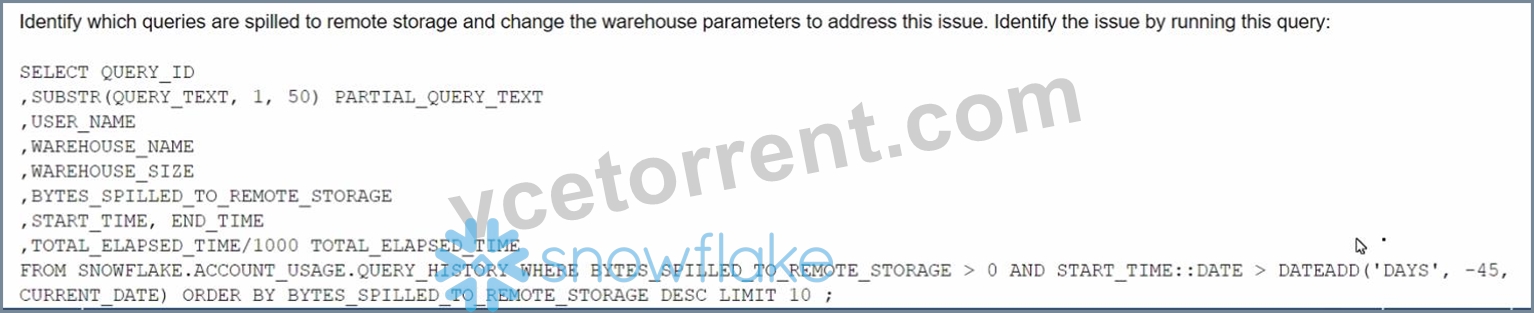
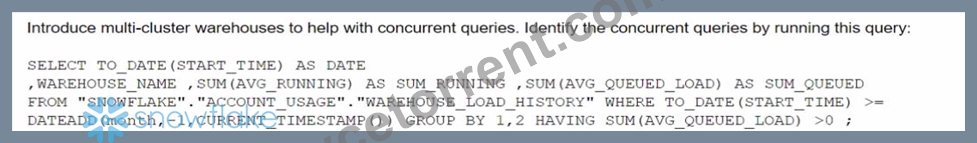
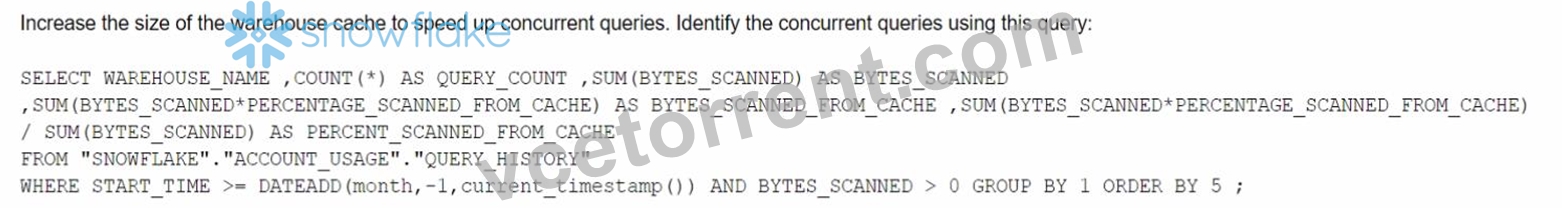
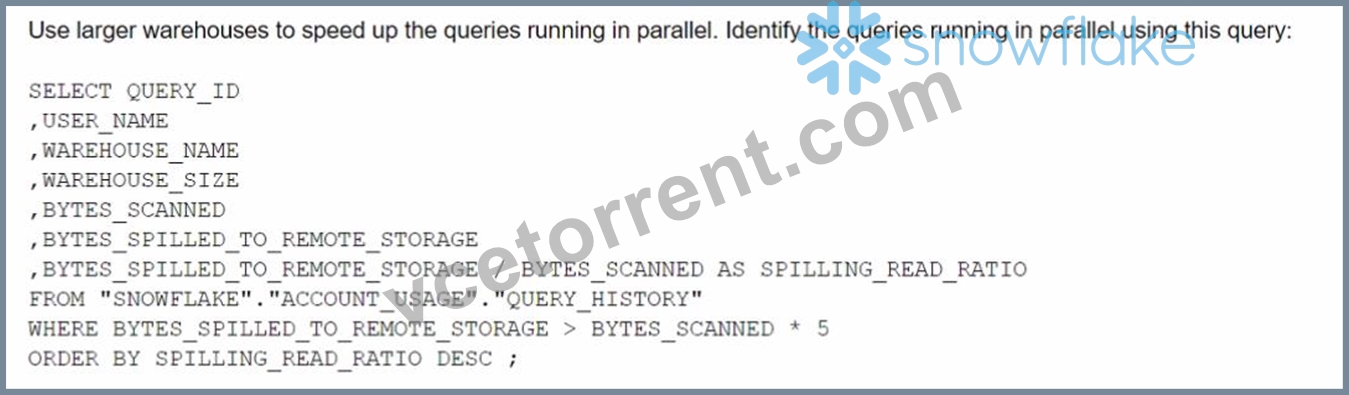
The Business Intelligence team reports that when some team members run queries for their dashboards in parallel with others, the query response time is getting significantly slower What can a Snowflake Architect do to identify what is occurring and troubleshoot this issue?
Answer: D
Explanation:
The image shows a SQL query that can be used to identify which queries are spilled to remote storage and suggests changing the warehouse parameters to address this issue. Spilling to remote storage occurs when the memory allocated to a warehouse is insufficient to process a query, and Snowflake uses disk or cloud storage as a temporary cache. This can significantly slow down the query performance and increase the cost. To troubleshoot this issue, a Snowflake Architect can run the query shown in the image to find out which queries are spilling, how much data they are spilling, and which warehouses they are using. Then, the architect can adjust the warehouse size, type, or scaling policy to provide enough memory for the queries and avoid spilling12. Reference:
Recognizing Disk Spilling
Managing the Kafka Connector
NEW QUESTION # 41
You have an inventory table. You created two views on this table. The views look like as below
CREATE VIEW NON_SECURE_INVENTORY AS
SELECT BIBNUMBER, TITLE, AUTHOR,ISBN
FROM INVENTORY
WHERE BIBNUMBER IN(511784,511805,511988,512044,512052,512063);
CREATE SECURE VIEW SECURE_INVENTORY AS
SELECT BIBNUMBER, TITLE, AUTHOR,ISBN
FROM INVENTORY
WHERE BIBNUMBER IN(511784,511805,511988,512044,512052,512063);
You ran the below queries
ALTER SESSION SET USE_CACHED_RESULT=FALSE;--This is to ensure that we do not retrieve from query cache
SELECT * FROM NON_SECURE_INVENTORY WHERE BIBNUMBER =511784; SELECT * FROM SECURE_INVENTORY WHERE BIBNUMBER =511784;
The query profile for the first query looks as below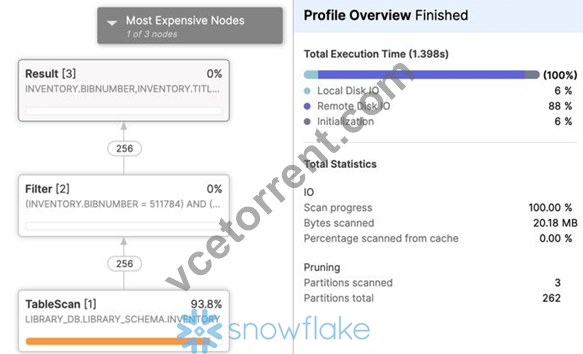
However, the query profile for the second one looks like as below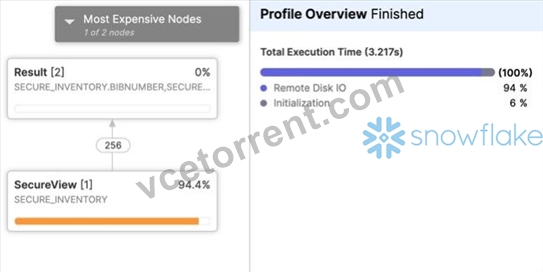
Both the views use the same columns from the same underlying view. So, why is this difference in query profiles.
Answer: B
NEW QUESTION # 42
A media company needs a data pipeline that will ingest customer review data into a Snowflake table, and apply some transformations. The company also needs to use Amazon Comprehend to do sentiment analysis and make the de-identified final data set available publicly for advertising companies who use different cloud providers in different regions.
The data pipeline needs to run continuously and efficiently as new records arrive in the object storage leveraging event notifications. Also, the operational complexity, maintenance of the infrastructure, including platform upgrades and security, and the development effort should be minimal.
Which design will meet these requirements?
Answer: D
Explanation:
Option B is the best design to meet the requirements because it uses Snowpipe to ingest the data continuously and efficiently as new records arrive in the object storage, leveraging event notifications. Snowpipe is a service that automates the loading of data from external sources into Snowflake tables1. It also uses streams and tasks to orchestrate transformations on the ingested data. Streams are objects that store the change history of a table, and tasks are objects that execute SQL statements on a schedule or when triggered by another task2. Option B also uses an external function to do model inference with Amazon Comprehend and write the final records to a Snowflake table. An external function is a user-defined function that calls an external API, such as Amazon Comprehend, to perform computations that are not natively supported by Snowflake3.
Finally, option B uses the Snowflake Marketplace to make the de-identified final data set available publicly for advertising companies who use different cloud providers in different regions. The Snowflake Marketplace is a platform that enables data providers to list and share their data sets with data consumers, regardless of the cloud platform or region they use4.
Option A is not the best design because it uses copy into to ingest the data, which is not as efficient and continuous as Snowpipe. Copy into is a SQL command that loads data from files into a table in a single transaction. It also exports the data into Amazon S3 to do model inference with Amazon Comprehend, which adds an extra step and increases the operational complexity and maintenance of the infrastructure.
Option C is not the best design because it uses Amazon EMR and PySpark to ingest and transform the data, which also increases the operational complexity and maintenance of the infrastructure. Amazon EMR is a cloud service that provides a managed Hadoop framework to process and analyze large-scale data sets.
PySpark is a Python API for Spark, a distributed computing framework that can run on Hadoop. Option C also develops a python program to do model inference by leveraging the Amazon Comprehend text analysis API, which increases the development effort.
Option D is not the best design because it is identical to option A, except for the ingestion method. It still exports the data into Amazon S3 to do model inference with Amazon Comprehend, which adds an extra step and increases the operational complexity and maintenance of the infrastructure.
References: 1: Snowpipe Overview 2: Using Streams and Tasks to Automate Data Pipelines 3: External Functions Overview 4: Snowflake Data Marketplace Overview : [Loading Data Using COPY INTO] : [What is Amazon EMR?] : [PySpark Overview]
NEW QUESTION # 43
What is a valid object hierarchy when building a Snowflake environment?
Answer: C
Explanation:
This is the valid object hierarchy when building a Snowflake environment, according to the Snowflake documentation and the web search results. Snowflake is a cloud data platform that supports various types of objects, such as databases, schemas, tables, views, stages, warehouses, and more. These objects are organized in a hierarchical structure, as follows:
* Organization: An organization is the top-level entity that represents a group of Snowflake accounts that are related by business needs or ownership. An organization can have one or more accounts, and can enable features such as cross-account data sharing, billing and usage reporting, and single sign-on across accounts12.
* Account: An account is the primary entity that represents a Snowflake customer. An account can have one or more databases, schemas, stages, warehouses, and other objects. An account can also have one or more users, roles, and security integrations. An account is associated with a specific cloud platform, region, and Snowflake edition34.
* Database: A database is a logical grouping of schemas. A database can have one or more schemas, and can store structured, semi-structured, or unstructured data. A database can also have properties such as retention time, encryption, and ownership56.
* Schema: A schema is a logical grouping of tables, views, stages, and other objects. A schema can have one or more objects, and can define the namespace and access control for the objects. A schema can also have properties such as ownership and default warehouse .
* Stage: A stage is a named location that references the files in external or internal storage. A stage can be used to load data into Snowflake tables using the COPY INTO command, or to unload data from Snowflake tables using the COPY INTO LOCATION command. A stage can be created at the account, database, or schema level, and can have properties such as file format, encryption, and credentials .
The other options listed are not valid object hierarchies, because they either omit or misplace some objects in the structure. For example, option A omits the organization level and places the warehouse under the schema level, which is incorrect. Option C omits the organization, account, and stage levels, and places the table under the schema level, which is incorrect. Option D omits the database level and places the stage and table under the account level, which is incorrect.
References:
* Snowflake Documentation: Organizations
* Snowflake Blog: Introducing Organizations in Snowflake
* Snowflake Documentation: Accounts
* Snowflake Blog: Understanding Snowflake Account Structures
* Snowflake Documentation: Databases
* Snowflake Blog: How to Create a Database in Snowflake
* [Snowflake Documentation: Schemas]
* [Snowflake Blog: How to Create a Schema in Snowflake]
* [Snowflake Documentation: Stages]
* [Snowflake Blog: How to Use Stages in Snowflake]
NEW QUESTION # 44
An Architect Is designing a data lake with Snowflake. The company has structured, semi-structured, and unstructured dat a. The company wants to save the data inside the data lake within the Snowflake system. The company is planning on sharing data among Its corporate branches using Snowflake data sharing.
What should be considered when sharing the unstructured data within Snowflake?
Answer: B
Explanation:
According to the Snowflake documentation, unstructured data files can be shared by using a secure view and Secure Data Sharing. A secure view allows the result of a query to be accessed like a table, and a secure view is specifically designated for data privacy. A scoped URL is an encoded URL that permits temporary access to a staged file without granting privileges to the stage. The URL expires when the persisted query result period ends, which is currently 24 hours. A scoped URL is recommended for file administrators to give scoped access to data files to specific roles in the same account. Snowflake records information in the query history about who uses a scoped URL to access a file, and when. Therefore, a scoped URL is the best option to share unstructured data within Snowflake, as it provides security, accountability, and control over the data access. Reference:
Sharing unstructured Data with a secure view
Introduction to Loading Unstructured Data
NEW QUESTION # 45
......
If you don't prepare with real Snowflake ARA-C01 questions, you fail, lose time and money. VCETorrent product is specially designed to help you pass the exam on the first try. The study material is easy to use. You can choose from 3 different formats available according to your needs. The 3 formats are Snowflake ARA-C01 desktop practice test software, browser based practice exam, and PDF.
Braindumps ARA-C01 Downloads: https://www.vcetorrent.com/ARA-C01-valid-vce-torrent.html
DOWNLOAD the newest VCETorrent ARA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1exB38YaYWrCTmmAcAuXXCNg_aSPAs3LD