For candidates who are going to buy DP-750 exam bootcamp online, they may pay more attention to privacy protection, and if you are choose us, we can ensure that your personal information will be protected well. Once the order finishes, your personal information such as your name and email address will be protected well. In addition, DP-750 Exam Dumps contain both questions and answers, and you can have a quickly check after practicing. Online and offline service are available for DP-750 exam bootcamp, if you have any questions, don’t hesitate to consult us.
| Section | Weight | Objectives |
|---|---|---|
| Deploy and manage data pipelines and workloads | 30-35% | - Pipeline design and orchestration
|
| Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
| Prepare and process data | 30-35% | - Data quality and validation
|
| Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
>> Reliable Test DP-750 Test <<
you can stand out in your work and impressed others with professional background certified by DP-750exam and feel self-fulfillment, get sense of satisfaction in personal perspective, and have stand a better chance of getting better working condition with the DP-750 Certification. Therefore, our affordable DP-750 study guide will definitely be gainful opportunity. Come and buy our DP-750 exam materials, and you will be grateful for your wise decision.
NEW QUESTION # 41
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.filter(df.order_amount.isNotNull())
Does this meet the goal?
Answer: A
Explanation:
The correct answer is A - Yes.
df.filter(df.order_amount.isNotNull()) is the correct PySpark pattern for excluding null rows. The isNotNull() method is a Column method that returns True for every row where order_amount has a value and False for rows where it is null. Spark ' s filter keeps only the rows where the condition evaluates to True, producing a DataFrame with all null order_amount rows removed.
This works correctly because isNotNull() is explicitly null-aware - unlike the != None comparison in Q52, it doesn ' t rely on Python equality semantics. Under the hood it maps to the SQL expression order_amount IS NOT NULL, which is unambiguous in both SQL and Spark.
Both df.filter(df.order_amount.isNotNull()) and df.dropna(subset=[ ' order_amount ' ]) produce identical results. The choice between them is stylistic - isNotNull() reads more explicitly as a filter condition, while dropna is more compact when handling multiple columns.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 42
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named catalog1.
You have a group named group1.
You plan to create a schema named schema1 in catalog1.
You need to ensure that group1 meets the following requirements:
- Can create tables in schema1
- Can modify and query tables
- Cannot grant permissions for the schema and its objects
How should you complete the SQL statements? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.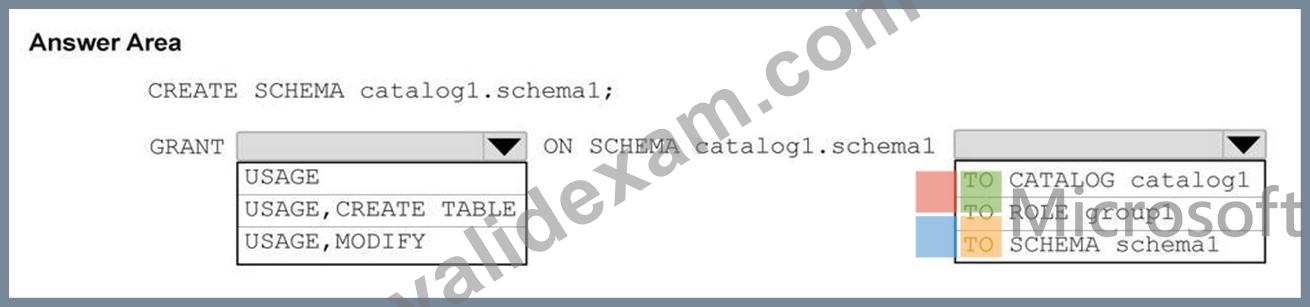
Answer:
Explanation: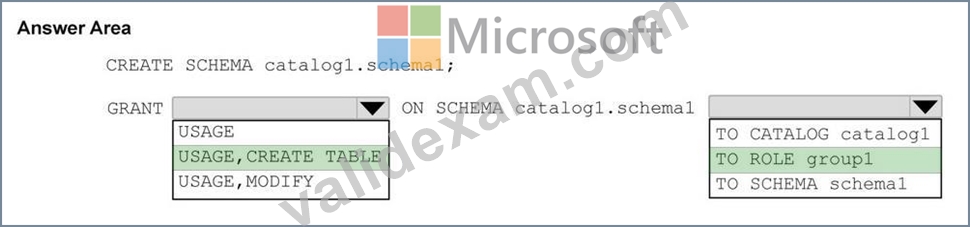
NEW QUESTION # 43
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two Delta tables named Table1 and Table2 of the same data type.
Table1 contains a column named Columnl. Table2 contains a column named Column2. You run the following query.
SELECT Column1
FROM Table1
GROUP BY Column1
HAVING COUNT(") > 1
INTERSECT
SELECT C0lumn2
FROM Table2
GROUP BY Column2
HAVING COUNT(') > 1;
What occurs when you run the query?
Answer: D
Explanation:
The correct answer is B - values appear in both tables more than once.
Reading the query from the inside out: each subquery identifies values that appear more than once within their own table. The first subquery returns Column1 values that are duplicated in Table1. The second returns Column2 values that are duplicated in Table2. INTERSECT then returns only the values that appear in both result sets - meaning values that are duplicated in Table1 AND also duplicated in Table2.
Option A describes a UNION result (values in either table), not INTERSECT. Option C only considers duplicates in Table1, ignoring the Table2 condition - that would be the first subquery in isolation. Option D describes values exclusive to Table2 (EXCEPT or MINUS), the opposite of INTERSECT's requirement that values appear in both sets.
INTERSECT always requires membership in both operands - that's its fundamental definition in standard SQL.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/sql-ref-syntax-qry-select- setops
NEW QUESTION # 44
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You discover that out of- memory (OOM) errors intermittently cause jobs running on Cluster1 to fail.
You need to identify the root cause of the failures by analyzing the runtime execution behavior. What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.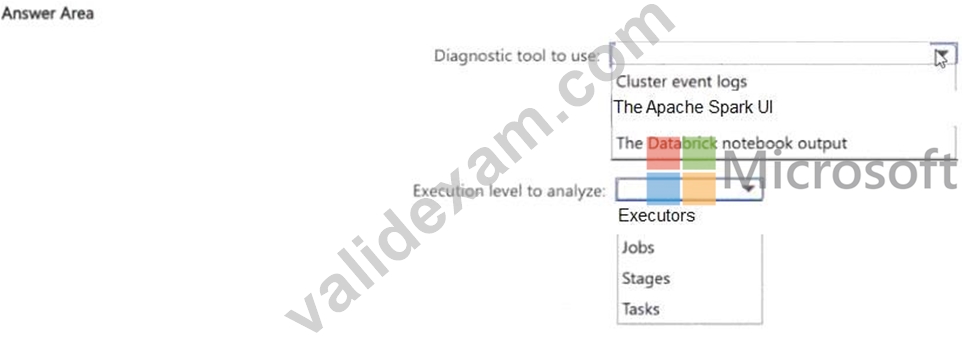
Answer:
Explanation: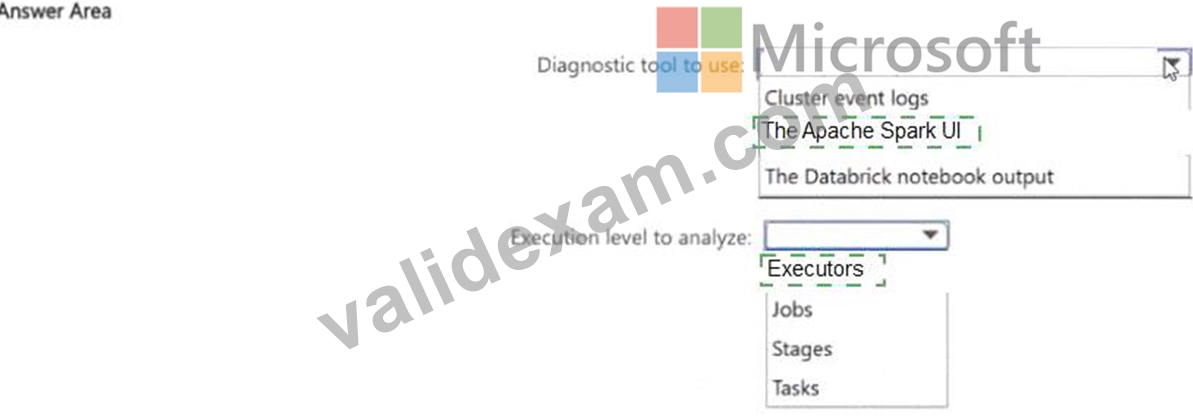
Explanation:
Diagnosing OOM errors requires analysing actual runtime execution behaviour. The Spark UI is the primary tool - it's accessible from the cluster detail page and captures rich per-stage and per-task metrics without any extra setup.
In the Executors tab, look at storage memory used, execution memory used, memory spill to disk, and GC time per executor. An executor showing high memory spill is a strong indicator that it's processing more data than it can hold in memory - often caused by data skew, where one partition is far larger than the others.
The Stages tab shows task distribution - if one task in a stage is processing 10x more data than its peers, that's data skew causing memory pressure on that specific executor. Ganglia (available on older runtimes) provides node-level OS metrics like heap usage over time, which can confirm whether memory pressure is sustained or spiky.
These built-in tools give a complete picture of the root cause before making any configuration changes.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/monitor-cluster
NEW QUESTION # 45
You have an Azure Databricks workspace named Workspace1.
You create a compute cluster named Cluser1 that will be used to ingest data.
You need to install the required libraries on Cluster1. The solution must use Unity Catalog for access control.
What should you do?
Answer: D
Explanation:
A Unity Catalog volume is the appropriate location because it provides governed file storage with permissions managed through Unity Catalog. After uploading the library package to the volume, it can be configured as a cluster library on Cluster1. This approach permits centralized access control, auditing, and lifecycle management. Option A installs the library without placing its source under Unity Catalog governance. Option B provides notebook-scoped dependency management but does not, by itself, satisfy the requirement that Unity Catalog control access to the library artifact. A schema is a logical container for tables, views, functions, models, and volumes; a library file cannot be uploaded directly to the schema itself, eliminating option D. Unity Catalog volumes explicitly support storing cluster libraries and job dependencies. Microsoft Learn
NEW QUESTION # 46
......
ValidExam offers verified, authentic Microsoft DP-750 Real Questions and answers, which are essential for passing the Implementing Data Engineering Solutions Using Azure Databricks (DP-750). These questions and answers have been designed by Sitecore experts and can be easily downloaded on a PC, MacBook, or smartphone for comfortable and convenient learning.
DP-750 Valid Braindumps Free: https://www.validexam.com/DP-750-latest-dumps.html