P.S. Free 2026 CompTIA DY0-001 dumps are available on Google Drive shared by Test4Engine: https://drive.google.com/open?id=1nh_4ZUjBiTuGvC4uTvIl9HQKy-EIdyi5
Experts at Test4Engine strive to provide applicants with valid and updated CompTIA DY0-001 exam questions to prepare from, as well as increased learning experiences. We are confident in the quality of the CompTIA DY0-001 preparational material we provide and back it up with a money-back guarantee. Test4Engine provides CompTIA DY0-001 desktop-based practice software for you to test your knowledge and abilities. The DY0-001 desktop-based practice software has an easy-to-use interface.
| Certification Vendor: | CompTIA |
|---|---|
| Exam Name: | CompTIA DataAI Certification Exam (V1) |
| Exam Number: | DY0-001 |
| Related Certifications: | CompTIA DataX |
| Passing Score: | Pass/Fail (no scaled score) |
| Available Languages: | Japanese, English |
| Exam Duration: | 165 minutes |
| Certificate Validity Period: | Approximately 3 years from launch (retirement expected around 2027) |
| Exam Format: | Performance-based questions, Multiple-choice |
| Real Exam Qty: | Up to 90 |
| Recommended Training: | CompTIA Official Training Partners CompTIA CertMaster Learn (DataAI) |
| Exam Registration: | Pearson VUE CompTIA Registration CompTIA DataAI Official Page |
| Sample Questions: | CompTIA DY0-001 Sample Questions |
| Exam Way: | Test center or online proctored exam (Pearson VUE) |
| Pre Condition: | Recommended: 5+ years experience in data science, analytics, or related technical roles |
| Official Syllabus URL: | https://www.comptia.org/en-us/certifications/dataai/ |
>> DY0-001 Reliable Exam Simulator <<
Useful DY0-001 exam prep is subservient to your development. To add up your interests and simplify some difficult points, our experts try their best to design our DY0-001 training material and help you understand the DY0-001 study guide better. And our experts generalize the knowledge of the exam into our products showing in three versions: the PDF, the Software and the APP online. You can choose your most desirable way to practice our DY0-001 Preparation engine on the daily basis.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 41
Which of the following types of machine learning is a GPU most commonly used for?
Answer: C
Explanation:
GPUs excel at the massive parallelism required for the matrix and tensor operations at the heart of deep neural network training and inference, making them the go-to hardware for deep learning workloads.
NEW QUESTION # 42
A data scientist is using the following confusion matrix to assess model performance:
Actually Fails
Actually Succeeds
Predicted to Fail
80%
20%
Predicted to Succeed
15%
85%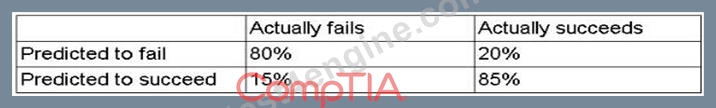
The model is predicting whether a delivery truck will be able to make 200 scheduled delivery stops.
Every time the model is correct, the company saves 1 hour in planning and scheduling.
Every time the model is wrong, the company loses 4 hours of delivery time.
Which of the following is the net model impact for the company?
Answer: C
Explanation:
First, we assume 100 trucks (or 100 predictions), as the percentages are easiest to scale on a base of 100.
Using the confusion matrix:
* True Positives (Predicted Fail & Actually Fails): 80 trucks - correct # +1 hr each = +80 hrs
* False Positives (Predicted Fail & Actually Succeeds): 20 trucks - incorrect # -4 hrs each = -80 hrs
* False Negatives (Predicted Succeed & Actually Fails): 15 trucks - incorrect # -4 hrs each = -60 hrs
* True Negatives (Predicted Succeed & Actually Succeeds): 85 trucks - correct # +1 hr each = +85 hrs Now calculate net hours:
Total gain: 80 hrs (TP) + 85 hrs (TN) = +165 hrs
Total loss: 80 hrs (FP) + 60 hrs (FN) = -140 hrs
Net Impact: 165 - 140 = +25 hours saved
So the correct answer is:
B : (25 hours saved)
However, based on the table provided (which appears to be normalized as percentages), the values apply to a total of 100 predictions. Let's recalculate carefully and validate.
Breakdown:
* TP = 80% # 80 × +1 hr = +80 hrs
* FP = 20% # 20 × -4 hrs = -80 hrs
* FN = 15% # 15 × -4 hrs = -60 hrs
* TN = 85% # 85 × +1 hr = +85 hrs
Total hours = +80 + 85 - 80 - 60 = +25 hrs
Final answer: B. 25 hours saved
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 4.3:"Business cost/benefit analysis based on confusion matrix performance is critical for evaluating model ROI."
NEW QUESTION # 43
A data scientist is attempting to identify sentences that are conceptually similar to each other within a set of text files. Which of the following is the best way to prepare the data set to accomplish this task after data ingestion?
Answer: A
Explanation:
# Embeddings (e.g., word2vec, sentence transformers) are vector representations of text that capture semantic similarity. They allow comparison of conceptual meaning between sentences in a high-dimensional space, which is essential for tasks like semantic similarity or clustering.
Why the other options are incorrect:
* B: Extrapolation predicts values beyond a dataset's range - not relevant here.
* C: Sampling reduces data volume but doesn't aid in similarity analysis.
* D: One-hot encoding captures presence of words but lacks semantic understanding.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 6.3:"Embeddings transform text into numeric vectors, enabling similarity computation and semantic analysis."
-
NEW QUESTION # 44
A data scientist is creating a responsive model that will update a product's daily pricing based on the previous day's sales volume. Which of the following resource constraints is the data scientist's greatest concern?
Answer: A
Explanation:
# Since the model must update daily based on new data, retraining must be fast enough to meet daily deadlines. Therefore, training time is the critical constraint - it determines whether pricing updates can be executed promptly.
Why the other options are incorrect:
* A: Deployment time is a one-time or infrequent process.
* C: Development time is less critical once the model is built.
* D: Data is already collected daily - assumed to be available.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 5.4:"Time-sensitive applications such as daily pricing require fast model retraining, making training time a critical factor."
* Real-Time ML Deployment Handbook, Chapter 6:"Retraining time is the bottleneck in time- constrained systems that adapt to fresh inputs regularly."
-
NEW QUESTION # 45
A company created a very popular collectible card set. Collectors attempt to collect the entire set, but the availability of each card varies, because some cards have higher production volumes than others. The set contains a total of 12 cards. The attributes of the cards are shown.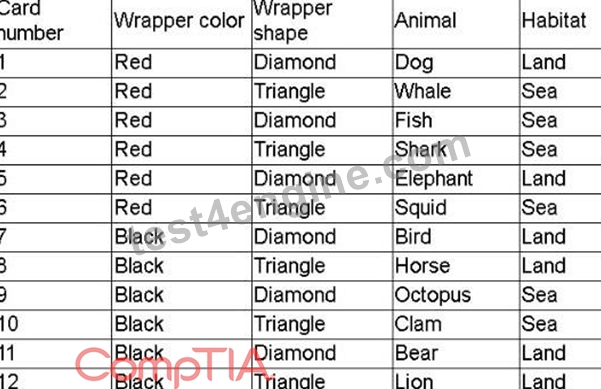
The data scientist is tasked with designing an initial model iteration to predict whether the animal on the card lives in the sea or on land, given the card's features: Wrapper color, Wrapper shape, and Animal.
Which of the following is the best way to accomplish this task?
Answer: C
Explanation:
# Decision trees are supervised classification models that can be used to predict a categorical target variable (e.
g., Habitat: Land or Sea) based on input features (e.g., Wrapper color, Wrapper shape, Animal type). They are interpretable, require minimal preprocessing, and are ideal for structured categorical data like this.
Why the other options are incorrect:
* A: ARIMA (AutoRegressive Integrated Moving Average) is used for time-series forecasting, not classification.
* B: Linear regression is used for predicting continuous numeric values, not categorical variables like
"Land" or "Sea".
* C: Association rules (like in market basket analysis) are used to discover relationships or co-occurrence among variables, not to build predictive models.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 4.1 & 4.2:"Decision trees are powerful classifiers for categorical output variables and allow for interpretable models based on feature splits."
* Machine Learning Textbook, Chapter 6:"Decision trees are ideal for early-stage model prototyping when the output is categorical and the data structure is tabular."
NEW QUESTION # 46
......
Lab DY0-001 Questions: https://www.test4engine.com/DY0-001_exam-latest-braindumps.html
DOWNLOAD the newest Test4Engine DY0-001 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1nh_4ZUjBiTuGvC4uTvIl9HQKy-EIdyi5