What's more, part of that GetValidTest 3V0-24.25 dumps now are free: https://drive.google.com/open?id=1Xogq4EQAmHIT3wH0n56NA7ZEPwYIm2Rt
Do you feel VMware 3V0-24.25 exam preparation is tough? GetValidTest desktop and web-based online VMware 3V0-24.25 practice test software will give you a clear idea about the final 3V0-24.25 Test Pattern. Practicing with the VMware 3V0-24.25 practice test, you can evaluate your VMware 3V0-24.25 exam preparation.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
>> Practice 3V0-24.25 Online <<
Using our products does not take you too much time but you can get a very high rate of return. Our 3V0-24.25 quiz guide is of high quality, which mainly reflected in the passing rate. We can promise higher qualification rates for our 3V0-24.25 exam question than materials of other institutions. Because our products are compiled by experts from various industries and they are based on the true problems of the past years and the development trend of the industry. What's more, according to the development of the time, we will send the updated materials of 3V0-24.25 Test Prep to the customers soon if we update the products. Under the guidance of our study materials, you can gain unexpected knowledge. Finally, you will pass the exam and get a VMware certification.
NEW QUESTION # 82
A VKS Administrator is troubleshooting a stalled upgrade of the prod-cluster. The upgrade has halted during the worker node rollout.
The administrator inspects the Machine object for the node currently being deleted (worker-node-02) and finds the following event:
Events:
Type Reason Age From Message
---- ------ ---- ---- -------
Warning DrainFailed 10m machine-controller Failed to drain node: Cannot evict pod "payment- service-5d4f7c" in namespace "finance": PodDisruptionBudget "payment-pdb" is blocking eviction.
Review the PodDisruptionBudget (PDB) status:
NAME MIN AVAILABLE MAX UNAVAILABLE ALLOWED DISRUPTIONS AGE
payment-pdb 2 N/A 50d 0
The deployment payment-service currently has 2 replicas running.
What is the correct procedure to resolve this blockage and allow the upgrade to proceed? (Choose 2.)
Answer: A,B
NEW QUESTION # 83
An administrator is maintaining several Kubernetes clusters deployed through a Supervisor Namespace in a vSphere Kubernetes Service environment. One of the microservices, a containerized API gateway, has started failing intermittently after a recent configuration update. Initial investigation shows that the pod is entering a CrashLoopBackOff state. The administrator needs to collect detailed runtime information directly from the pod, including both the standard output (STDOUT) and standard error (STDERR) streams, to analyze the application ' s behavior before the crash. Which command produces the required output?
Answer: B
Explanation:
In VMware Cloud Foundation (VCF) 9.0 and vSphere Kubernetes Service (VKS) environments, the kubectl logs command is the essential tool for retrieving the standard output (STDOUT) and standard error (STDERR) streams from containers within a pod. When a microservice like an API gateway enters a CrashLoopBackOff state, it signifies that the container is starting, failing, and being restarted by the kubelet in an exponential back-off loop. To diagnose the root cause-such as a syntax error in a configuration file or a failed connection to a backend database-the administrator must inspect the application ' s internal execution logs.
The kubectl logs command is particularly powerful in this scenario when used with the -p (or --previous) flag.
This flag allows the administrator to retrieve logs from the specific container instance that just crashed, rather than the one currently attempting to restart. While kubectl describe provides critical metadata about the pod ' s lifecycle events, resource constraints, and status, it does not capture the internal application stream. In VCF
9.0, where the vSphere Supervisor manages the lifecycle of these clusters, utilizing the standard Kubernetes toolset ensures that platform operators have a consistent and familiar troubleshooting experience. This logging mechanism is a core part of the observability stack in VKS, enabling rapid identification of application-level failures within the software-defined data center.
NEW QUESTION # 84
A Platform Engineer is troubleshooting a Pending PersistentVolumeClaim (PVC) in a Zonal Supervisor environment. The pod requesting the volume is scheduled in Zone-A.
Review the kubectl describe pvc data-vol output:
Name: data-vol
Namespace: zonal-app
Status: Pending
Volume:
StorageClass: zone-a-policy
Events:
Type Reason Age From Message
---- ------ ---- ---- -------
Warning ProvisioningFailed 15s (x9 over 2m) csi.vsphere.vmware.com failed to provision volume with StorageClass "zone-a-policy":
No compatible datastore found in topology
"topology.kubernetes.io/zone=zone-a".
The vSphere Administrator confirms that zone-a-policy exists and is assigned to the namespace.
What is the most likely configuration error causing this failure? (Choose 2.)
Answer: B,D
NEW QUESTION # 85
A VMware Administrator is tasked with implementing a backup and restore strategy using Velero and external object storage for the namespace 'myapp1. Arrange the steps In the correct order of operations to enable Vetero.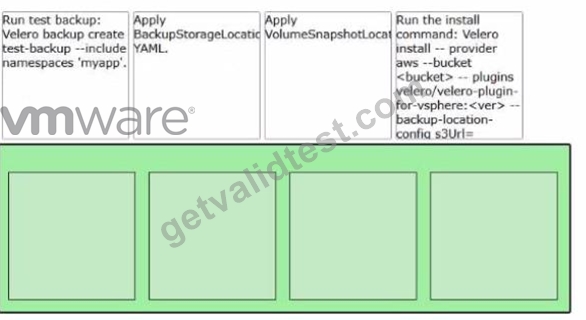
Answer:
Explanation: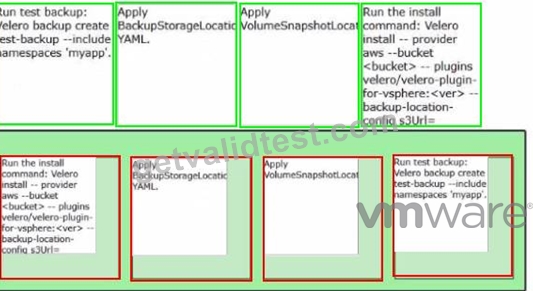
NEW QUESTION # 86
An administrator upgrades a VMware Cloud Foundation (VCF) Supervisor and the upgrade fails. Order the steps the administrator should take to determine the cause of the failure.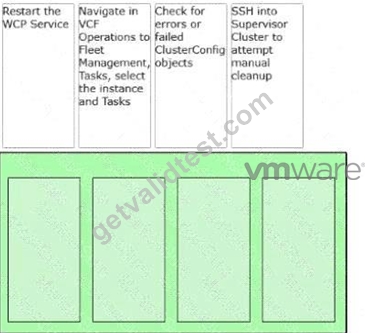
Answer:
Explanation: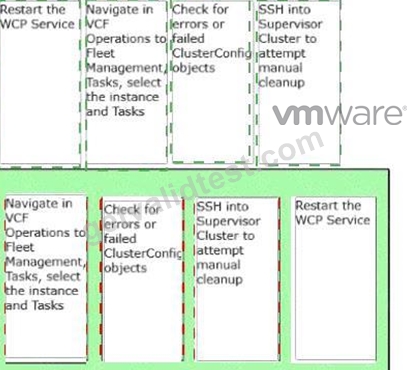
Explanation:
Answer (Correct Order):
* Navigate in VCF Operations to Fleet Management # Tasks, select the instance and review Tasks
* Check for errors or failed ClusterConfig objects
* SSH into the Supervisor Cluster to review logs / attempt manual cleanup if required
* Restart the WCP Service
To determinewhya Supervisor upgrade failed, you start where the platform records the most actionable failure context: themanagement-plane task history. The Fleet/Task view surfaces the upgrade workflow steps, timestamps, and the specific operation that failed, which gives you the fastest pointer to the failing phase (precheck, image staging, reconciliation, add-on updates, etc.). Next, you validate the Kubernetes-side reconciliation state by checking forfailed ClusterConfigobjects, because Supervisor enablement/upgrade actions commonly drive configuration via controller reconciliation; a failed ClusterConfig often contains the clearest "reason" and "message" fields that explain what blocked progress (validation errors, dependency issues, unreachable endpoints, incompatible components).
If the management-plane/task view and ClusterConfig status still don't isolate the root cause, the next escalation is toSSH into the Supervisorto inspect component logs/events and identify low-level failures that may not bubble up cleanly (for example, admission failures, controller crashes, or connectivity/auth issues).
Finally,restarting WCPis a remediation step that can clear stuck states, but it's placed last because it can alter evidence and should not be your first action when you're still trying to identify the original failure cause.
NEW QUESTION # 87
......
Life is full of choices. Selection does not necessarily bring you happiness, but to give you absolute opportunity. Once missed selection can only regret. GetValidTest's VMware 3V0-24.25 exam training materials are necessary to every IT person. With this materials, all of the problems about the VMware 3V0-24.25 will be solved. GetValidTest's VMware 3V0-24.25 exam training materials have wide coverage, and update speed. This is the most comprehensive training materials. With it, all the IT certifications need not fear, because you will pass the exam.
Relevant 3V0-24.25 Exam Dumps: https://www.getvalidtest.com/3V0-24.25-exam.html
P.S. Free 2026 VMware 3V0-24.25 dumps are available on Google Drive shared by GetValidTest: https://drive.google.com/open?id=1Xogq4EQAmHIT3wH0n56NA7ZEPwYIm2Rt