As for candidates who will attend the exam, choosing the practicing materials may be a difficult choice. Then just trying AI-500 learning materials of us, with the pass rate is 98.95%, we help the candidates to pass the exam successfully. Many candidates have sent their thanks to us for helping them to pass the exam by using the AI-500 Learning Materials. The reason why we gain popularity in the customers is the high-quality of AI-500 exam dumps. In addition, we provide you with free update for one year after purchasing. Our system will send the latest version to you email address automatically.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure, govern, and deploy multi-agent solutions | 20-25% | - Deploy multi-agent solutions to Azure
|
| Topic 2: Develop multi-agent solutions in Azure | 30-35% | - Implement multi-agent orchestration
|
| Topic 3: Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
| Topic 4: Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Implement observability and monitoring
|
To get better condition of life, we all need impeccable credentials of different exams to prove individual’s capacity. However, weak AI-500 practice materials may descend and impair your ability and flunk you in the real exam unfortunately. And the worst condition is all that work you have paid may go down the drain for those AI-500 question torrent lack commitments and resolves to help custAI-500omers. Moreover, only need toAI-500 spend 20-30 is it enough for you to grasp whole content of AI-500 practice materials that you can pass the exam easily, this is simply unimaginable.
NEW QUESTION # 59
You have a Microsoft Foundry multi-agent solution. The solution includes a parent agent that can call an Azure logic app and delegate to two subagents.
You need to implement a review process for flagged interactions. The solution must meet the following requirements;
* Identify requests that call third-party services.
* Moderate the prompts, steps, and tool calls.
* Include a governance review.
What should you do?
Answer: B
Explanation:
The review process must cover the full sensitive interaction, including third-party calls, prompts, intermediate steps, and tool actions, and it must feed a governance review process. A centralized sensitive-use intake combined with guardrails and tracing provides the required evidence, while human reviewers must be able to approve, edit, or reject flagged interactions rather than reviewing only the final message. Content Safety alone does not provide full process governance over tool use. Routing only subagent findings or requiring approval only for the final response misses earlier third-party actions. CI/CD evaluation is important for release quality but does not control individual flagged production interactions. The source duplicated the label C for the final option; that final option should be labeled D. With that label correction, D is the best answer. From a security and governance perspective, the control should be enforced at the narrowest platform boundary that can deterministically block or constrain the action. Relying only on prompt text is weaker because the model can still be induced to behave unexpectedly.
Official Microsoft reference: AI-500 Study Guide - governance, guardrails, tracing, and HITL
NEW QUESTION # 60
You have a Microsoft Foundry agent that completes benefits enrollment during a single user conversation The agent collects the required enrollment fields during 15 turns. Users can correct earlier values before final submission. The current implementation sends the complete transcript with every model request.
You need to change the context accumulation strategy for the active enrollment. The solution must meet the following requirements:
* Preserve the latest value for each required enrollment field until submission.
* Bound the maximum number of tokens sent with each model request
* Preserve user corrections until submission.
* Prevent durable cross-session memory.
What should you do?
Answer: B
Explanation:
The application must preserve the latest authoritative value of each enrollment field even when the user corrects an earlier value, while also placing a firm bound on prompt size. A session-scoped enrollment-state snapshot provides deterministic structured state: each correction overwrites the previous field value. A recent- turn sliding window then preserves enough conversational context for natural interaction without resending the full 15-turn transcript. Response chaining with a fixed number of prior turns can lose an important field once it falls outside the retained history. Summarization can omit or distort corrected values, and automatic truncation likewise offers no guarantee that the latest value of every required field survives. Because the state is scoped only to the active enrollment and is not written to long-term memory, the design also avoids durable cross-session memory. Therefore A is correct. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Microsoft Agent Framework - workflow state and context management
NEW QUESTION # 61
You need to implement an advanced prompt engineering strategy to resolve the Patient Intake agent issues.
The solution must prevent hardcoding new logic into the agent ' s core prompt.
What should you do?
Answer: B
Explanation:
The intake problem involves verbose, variable patient narratives and a requirement to avoid hardcoding new logic into the core prompt. Injecting dynamic context with curated few-shot examples gives the model representative demonstrations of how to identify clinically relevant symptoms while ignoring irrelevant narrative details. Microsoft AI-500 objectives explicitly include examples and dynamic context injection as advanced prompt-engineering techniques. Removing defensive guidance would weaken safety. Reducing the context window would not teach the model what information matters and could simply discard useful details.
Frequent full-model fine-tuning is operationally heavier and unnecessary for a behavior that can be demonstrated through curated examples. Dynamic few-shot context also allows the examples to be versioned and updated without rewriting the agent ' s base persona or application logic. Therefore C best addresses the extraction problem while preserving prompt lifecycle flexibility. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: AI-500 Study Guide - advanced prompt engineering
NEW QUESTION # 62
You have a multi-agent customer support solution in a Microsoft Foundry project.
You have a dataset that contains query, context, and response without document relevance labels.
You need to implement built-in evaluators that provide 1 to-5 scores with pass/fail labels for the following metrics:
* The quality of the retrieved context
* How directly a response answers a query
Which evaluator should you use for each metric? To answer, drag the appropriate evaluators to the correct metrics. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.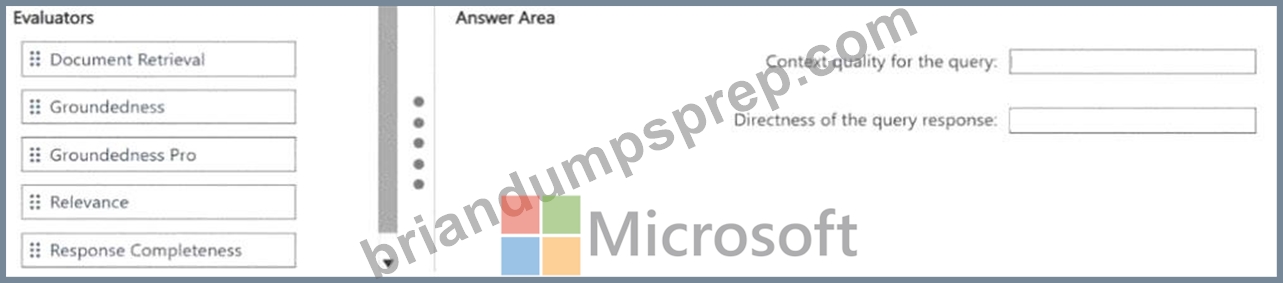
Answer:
Explanation: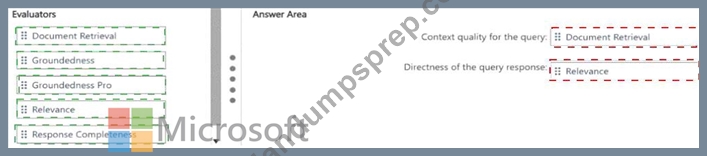
Explanation:
Quality of retrieved context: Retrieval evaluator; Directness of response to query: Relevance evaluator.
The dataset contains query, context, and response but does not contain document relevance labels. Microsoft ' s Retrieval evaluator is designed for exactly that situation: it uses an LLM judge to rate how relevant the retrieved context chunks are to the query and returns a 1-to-5 score with pass/fail behavior. The Relevance evaluator operates on the final response and measures whether the answer accurately, completely, and directly addresses the query. Document Retrieval is not appropriate because it requires retrieval ground truth such as known relevant documents or qrels. Groundedness answers a different question: whether response claims are supported by the provided context. Therefore the correct mapping is Retrieval for context quality and Relevance for response directness. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators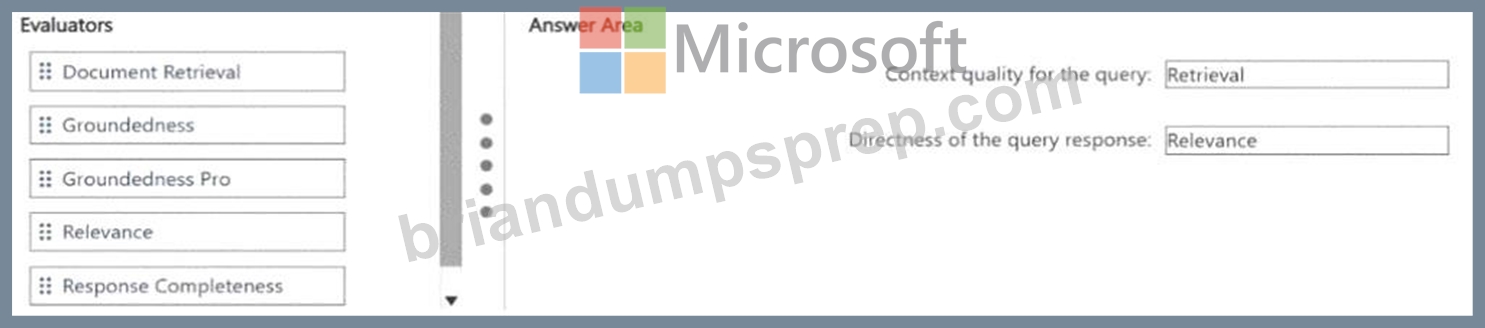
NEW QUESTION # 63
You have a Microsoft Foundry multi-agent solution. The agents contain the CI/CD evaluation gates shown in the following table.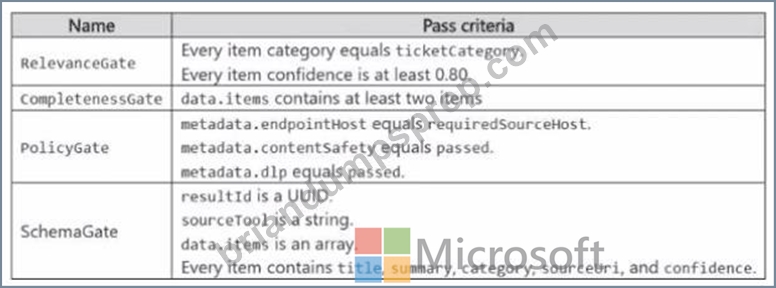
You call one of the agents by using the request context in the evaluation process as shown in the following table.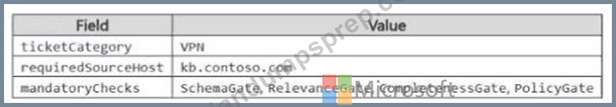
The agent receives the following results for the tool.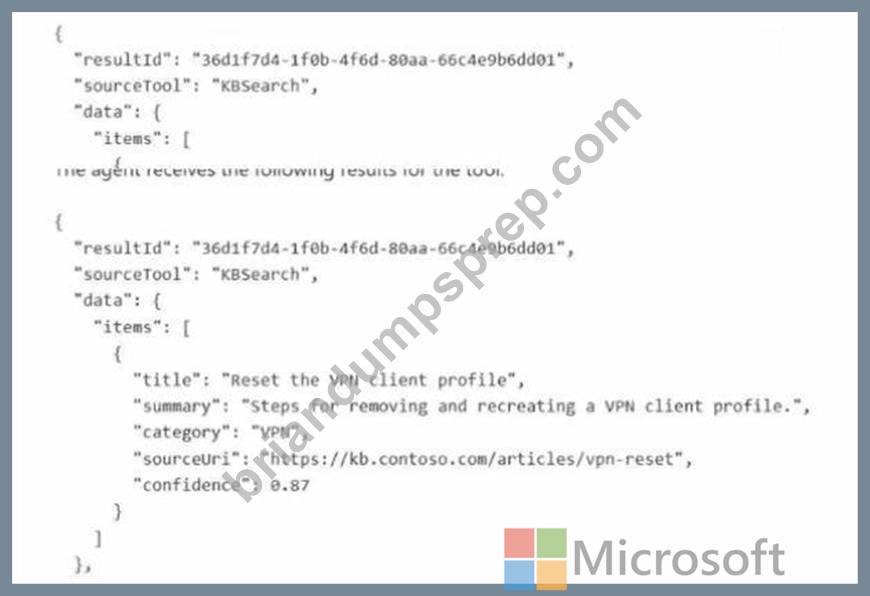
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.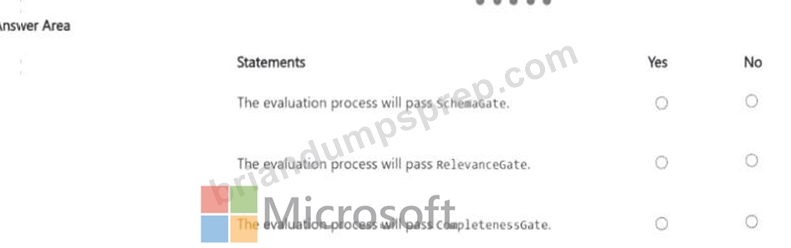
Answer:
Explanation: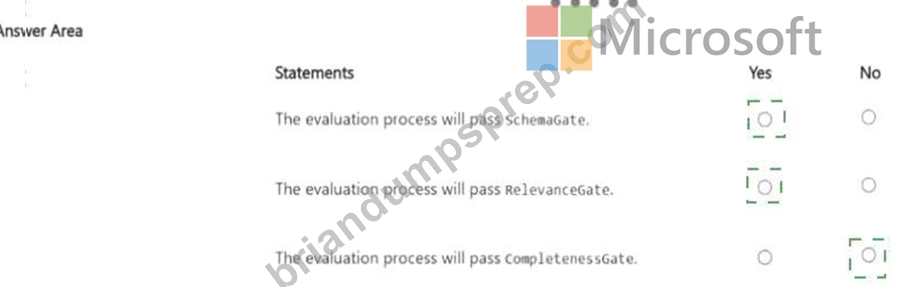
Explanation:
SchemaGate: Yes; RelevanceGate: Yes; CompletenessGate: No.
The supplied tool result satisfies the structural requirements of SchemaGate: it includes a valid-looking UUID result identifier, a string sourceTool value, an items array, and the required fields on the item. RelevanceGate also passes because the request category is VPN, the returned item category is VPN, and its confidence value of 0.87 is above the required 0.80 threshold. CompletenessGate fails because the rule requires at least two items while the response contains only one. This is a deterministic gate evaluation rather than an LLM-judge interpretation, so the values should be checked directly against the declared criteria. Microsoft Foundry evaluation datasets and CI/CD quality gates are designed to make exactly these regression checks repeatable before release. Therefore the correct sequence is Yes, Yes, No. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Microsoft Foundry - evaluation datasets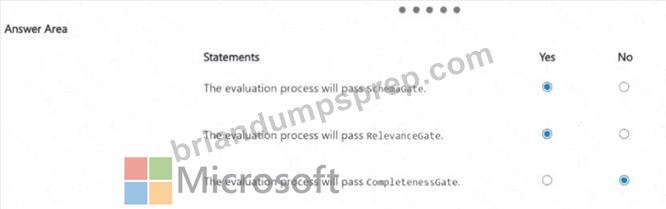
NEW QUESTION # 64
......
Now Microsoft AI-500 certification test is very popular. Not having got AI-500 certificate, you must want to take the exam. Indeed, Microsoft AI-500 test is very difficult exam, but this is not suggested that you cannot get high marks and pass your exam with ease. Without knowing the shortcut of Microsoft AI-500 Exam, do you want to know the testing technique? As for the point, I can tell you that BraindumpsPrep Microsoft AI-500 study guide is your unique choice.
AI-500 Valid Exam Cram: https://www.briandumpsprep.com/AI-500-prep-exam-braindumps.html