100% Pass 2026 Databricks The Best Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Examinations Actual Questions

There is a group of experts in our company which is especially in charge of compiling our Certified-Data-Engineer-Professional exam engine. There is no doubt that we will never miss any key points in our Certified-Data-Engineer-Professional training materials. As it has been proven by our customers that with the help of our Certified-Data-Engineer-Professional Test Prep you can pass the exam as well as getting the related Certified-Data-Engineer-Professional certification only after 20 to 30 hours' preparation, which means you can only spend the minimum of time and efforts to get the maximum rewards.
| Section | Objectives |
|---|
| Topic 1: Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
- Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
|
| Topic 2: Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Compare streaming tables and materialized views
- 2. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 3. Configure environments, dependencies, memory, and retry behavior
- 4. Use control flow operators in pipeline components
- 5. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 6. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 7. Use APPLY CHANGES APIs for change data capture
- 8. Develop unit and integration tests for data processing code
- Using Python and Tools for Development
- 1. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 2. Manage and troubleshoot third-party library installations and dependencies
- 3. Develop User-Defined Functions using Pandas/Python UDFs
|
| Topic 3: Ensuring Data Security and Compliance | - Data Security
- 1. Apply anonymization and pseudonymization techniques
- 2. Use row filters and column masks for sensitive data
- 3. Use ACLs to secure workspace objects and enforce least privilege
- Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
|
| Topic 4: Data Sharing and Federation | - Delta Sharing
- 1. Configure sharing with external platforms using the open sharing protocol
- 2. Share live Lakehouse data with external computing platforms
- 3. Configure Databricks-to-Databricks Sharing
- Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
|
| Topic 5: Data Modelling | - Scalable Data Models
- 1. Design and implement scalable data models using Delta Lake
- 2. Understand Liquid Clustering versus partitioning and Z-Ordering
- 3. Optimize data layout using Liquid Clustering
- Dimensional Modelling
- 1. Design dimensional models for analytical workloads
|
| Topic 6: Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
- Debugging and Troubleshooting
- 1. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 2. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 3. Analyze errors and remediate failed job runs
|
| Topic 7: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 2. Build append-only pipelines for batch and streaming data using Delta
- 3. Ingest data from message buses and cloud storage
|
| Topic 8: Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Topic 9: Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts for data quality monitoring
- 2. Configure Lakeflow Jobs notifications for job status and performance issues
- Monitoring
- 1. Use Query Profiler and Spark UI to monitor workloads
- 2. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 3. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 4. Use system tables for resource, cost, audit, and workload monitoring
|
| Topic 10: Cost & Performance Optimisation | - Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Delta Optimization
- 1. Understand deletion vectors and liquid clustering
- 2. Apply data skipping and file pruning techniques
- 3. Use Change Data Feed to address streaming table limitations and improve latency
- Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
|
>> Certified-Data-Engineer-Professional Examinations Actual Questions <<
Get 1 year Itcertmaster Databricks Certified-Data-Engineer-Professional Exam Questions Free Updates
Under the dominance of knowledge-based economy, we should keep pace with the changeable world and renew our knowledge in pursuit of a decent job and higher standard of life. In this circumstance, possessing a Certified-Data-Engineer-Professional certification in your pocket can totally increase your competitive advantage in the labor market and make yourself distinguished from other job-seekers. Therefore our Certified-Data-Engineer-Professional Study Guide can help you with dedication to realize your dream. And only after studying with our Certified-Data-Engineer-Professional exam questions for 20 to 30 hours, you will be able to pass the Certified-Data-Engineer-Professional exam.
Databricks Certified Data Engineer Professional Sample Questions (Q98-Q103):
NEW QUESTION # 98
A user new to Databricks is trying to troubleshoot long execution times for some pipeline logic they are working on. Presently, the user is executing code cell-by-cell, using display() calls to confirm code is producing the logically correct results as new transformations are added to an operation. To get a measure of average time to execute, the user is running each cell multiple times interactively.
Which of the following adjustments will get a more accurate measure of how code is likely to perform in production?
- A. Production code development should only be done using an IDE; executing code against a local build of open source Spark and Delta Lake will provide the most accurate benchmarks for how code will perform in production.
- B. The Jobs Ul should be leveraged to occasionally run the notebook as a job and track execution time during incremental code development because Photon can only be enabled on clusters launched for scheduled jobs.
- C. Scala is the only language that can be accurately tested using interactive notebooks; because the best performance is achieved by using Scala code compiled to JARs. all PySpark and Spark SQL logic should be refactored.
- D. Calling display () forces a job to trigger, while many transformations will only add to the logical query plan; because of caching, repeated execution of the same logic does not provide meaningful results.
- E. The only way to meaningfully troubleshoot code execution times in development notebooks Is to use production-sized data and production-sized clusters with Run All execution.
Answer: E
NEW QUESTION # 99
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impressions led to monetizable clicks.
In the code below, Impressions is a streaming DataFrame with a watermark ("event_time", "10 minutes")
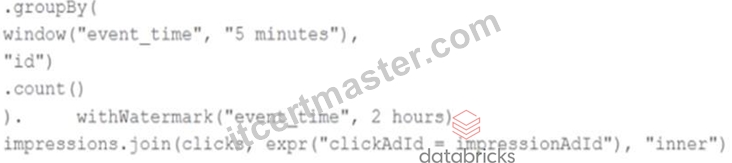
The data engineer notices the query slowing down significantly.
Which solution would improve the performance?
- A. Joining on event time constraint: clickTime >= impressionTime - interval 3 hours and removing watermarks
- B. Joining on event time constraint: clickTime + 3 hours < impressionTime - 2 hours
- C. Joining on event time constraint: clickTime >= impressionTime AND clickTime <= impressionTime interval 1 hour
- D. Joining on event time constraint: clickTime == impressionTime using a leftOuter join
Answer: C
NEW QUESTION # 100
A data governance team at a large enterprise is improving data discoverability across its organization. The team has hundreds of tables in their Databricks Lakehouse with thousands of columns that lack proper documentation. Many of these tables were created by different teams over several years, with missing context about column meanings and business logic. The data governance team needs to quickly generate comprehensive column descriptions for all existing tables to meet compliance requirements and improve data literacy across the organization. They want to leverage modern capabilities to automatically generate meaningful descriptions rather than manually documenting each column, which would take months to complete. Which approach should the team use in Databricks to automatically generate column comments and descriptions for existing tables?
- A. Write custom PySpark code using df.describe() and df.schema to programmatically generate basic statistical descriptions for each column.
- B. Use the DESCRIBE TABLE command to extract existing schema information and manually write descriptions based on column names and data types.
- C. Use Delta Lake's DESCRIBE HISTORY command to analyze table evolution and infer column purposes from historical changes.
- D. Navigate to the table in Databricks Catalog Explorer, select the table schema view, and use the AI Generate option which leverages artificial intelligence to automatically create meaningful column descriptions based on column names, data types, sample values, and data patterns.
Answer: D
Explanation:
The Catalog Explorer provides an AI-powered "AI Generate" capability that automatically creates intelligent column descriptions by analyzing column names, data types, sample values, and observed data patterns. This approach enables rapid, scalable documentation of existing tables, significantly improving data discoverability and compliance without manual effort.
NEW QUESTION # 101
A data engineer is implementing liquid clustering on a Delta Lale table and needs to understand how it affects data management operations. The table will be updated frequently with new data.
The table is an external table and not managed by Unity Catalog. How does liquid clustering in Delta Lake handle new data that is inserted after the initial table creation?
- A. New data is written to a staging area and clustered during scheduled maintenance.
- B. New data remains unclustered until the next OPTIMIZE operation.
- C. New data is automatically clustered during write operations.
- D. New data is rejected if it doesn't match the clustering pattern.
Answer: B
Explanation:
With liquid clustering, newly inserted data is written without being immediately reclustered. The clustering layout is applied incrementally during subsequent OPTIMIZE operations, which reorganize both existing and newly added data to maintain an efficient data layout as the table evolves.
NEW QUESTION # 102
A junior data engineer seeks to leverage Delta Lake's Change Data Feed functionality to create a Type 1 table representing all of the values that have ever been valid for all rows in a bronze table created with the property delta.enableChangeDataFeed = true. They plan to execute the following code as a daily job:
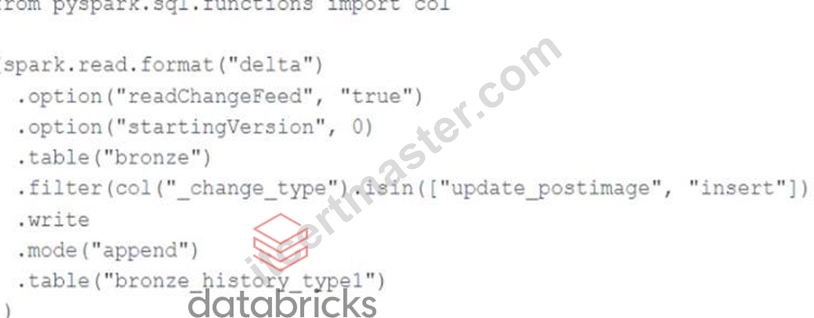
Which statement describes the execution and results of running the above query multiple times?
- A. Each time the job is executed, the differences between the original and current versions are calculated; this may result in duplicate entries for some records.
- B. Each time the job is executed, newly updated records will be merged into the target table, overwriting previous values with the same primary keys.
- C. Each time the job is executed, only those records that have been inserted or updated since the last execution will be appended to the target table giving the desired result.
- D. Each time the job is executed, the entire available history of inserted or updated records will be appended to the target table, resulting in many duplicate entries.
- E. Each time the job is executed, the target table will be overwritten using the entire history of inserted or updated records, giving the desired result.
Answer: D
Explanation:
Reading table's changes, captured by CDF, using spark.read means that you are reading them as a static source. So, each time you run the query, all table's changes (starting from the specified startingVersion) will be read.
NEW QUESTION # 103
......
Different from the common question bank on the market, Certified-Data-Engineer-Professional exam guide is a scientific and efficient learning system that is recognized by many industry experts. In normal times, you may take months or even a year to review a professional exam, but with Certified-Data-Engineer-Professional exam guide you only need to spend 20-30 hours to review before the exam. And with Certified-Data-Engineer-Professional learning question, you will no longer need any other review materials, because our study materials already contain all the important test sites. At the same time, Certified-Data-Engineer-Professional test prep helps you to master the knowledge in the course of the practice.
Exam Certified-Data-Engineer-Professional Braindumps: https://www.itcertmaster.com/Certified-Data-Engineer-Professional.html
- Composite Test Certified-Data-Engineer-Professional Price 😢 Certified-Data-Engineer-Professional Valid Cram Materials 🏏 Certified-Data-Engineer-Professional Practice Exams Free 🕷 Download ➠ Certified-Data-Engineer-Professional 🠰 for free by simply searching on ➽ www.dumpsquestion.com 🢪 🥭Valid Certified-Data-Engineer-Professional Practice Questions
- New Certified-Data-Engineer-Professional Dumps Ppt 😍 New Certified-Data-Engineer-Professional Test Topics 🔬 New Certified-Data-Engineer-Professional Dumps Ppt 🏭 Easily obtain ➤ Certified-Data-Engineer-Professional ⮘ for free download through ▶ www.pdfvce.com ◀ 🐸Certified-Data-Engineer-Professional Practice Exams Free
- In How Many Ways You Can Prepare Through www.troytecdumps.com Databricks Certified-Data-Engineer-Professional Exam Questions? 🏂 Go to website ☀ www.troytecdumps.com ️☀️ open and search for [ Certified-Data-Engineer-Professional ] to download for free 😗Fresh Certified-Data-Engineer-Professional Dumps
- Certified-Data-Engineer-Professional Learning Materials: Databricks Certified Data Engineer Professional - Certified-Data-Engineer-Professional Actual Lab Questions 🦃 Enter “ www.pdfvce.com ” and search for 「 Certified-Data-Engineer-Professional 」 to download for free 🔔Certified-Data-Engineer-Professional Exam Online
- Latest Certified-Data-Engineer-Professional Test Camp 👌 Test Certified-Data-Engineer-Professional Questions Fee 🤬 Composite Test Certified-Data-Engineer-Professional Price 🤣 Copy URL ⏩ www.prep4away.com ⏪ open and search for ➡ Certified-Data-Engineer-Professional ️⬅️ to download for free 🗨Certified-Data-Engineer-Professional Exam Bootcamp
- Real Certified-Data-Engineer-Professional Questions With Free Updates – Start Exam Preparation Today 🃏 Search for ⏩ Certified-Data-Engineer-Professional ⏪ on ➥ www.pdfvce.com 🡄 immediately to obtain a free download 💲Certified-Data-Engineer-Professional Valid Dump
- Certified-Data-Engineer-Professional Valid Dump 🤟 Fresh Certified-Data-Engineer-Professional Dumps 🧒 Certified-Data-Engineer-Professional Valid Dumps Files 💹 Search for { Certified-Data-Engineer-Professional } on ➠ www.dumpsquestion.com 🠰 immediately to obtain a free download 🈺Certified-Data-Engineer-Professional Exam Online
- Certified-Data-Engineer-Professional Exam Review 📋 Composite Test Certified-Data-Engineer-Professional Price 🍪 Vce Certified-Data-Engineer-Professional Free 🥑 Search for ⏩ Certified-Data-Engineer-Professional ⏪ on ⮆ www.pdfvce.com ⮄ immediately to obtain a free download 💈Composite Test Certified-Data-Engineer-Professional Price
- New Certified-Data-Engineer-Professional Test Topics 🤕 Certified-Data-Engineer-Professional Latest Braindumps Ppt 🐜 Vce Certified-Data-Engineer-Professional Free 🕕 Search for ➽ Certified-Data-Engineer-Professional 🢪 and download it for free on “ www.prepawayexam.com ” website 🕓Test Certified-Data-Engineer-Professional King
- Certified-Data-Engineer-Professional Valid Dumps Files 🔃 New Certified-Data-Engineer-Professional Dumps Ppt ⬛ Certified-Data-Engineer-Professional Valid Dump 🅿 Search for ⮆ Certified-Data-Engineer-Professional ⮄ and download exam materials for free through { www.pdfvce.com } 🧿Valid Certified-Data-Engineer-Professional Practice Questions
- Certified-Data-Engineer-Professional Learning Materials: Databricks Certified Data Engineer Professional - Certified-Data-Engineer-Professional Actual Lab Questions 🤙 Search for ⇛ Certified-Data-Engineer-Professional ⇚ on ➽ www.dumpsmaterials.com 🢪 immediately to obtain a free download ⏏Certified-Data-Engineer-Professional Exam Online
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes