BONUS!!! Download part of DumpsMaterials DP-700 dumps for free: https://drive.google.com/open?id=1AGJLZ0dIT__NNZbDd_0v3t02N_P4uT4u
Our DP-700 exam question will be constantly updated every day. The IT experts of our company will be responsible for checking whether our DP-700 exam prep is updated or not. Once our DP-700 test questions are updated, our system will send the message to our customers immediately. If you use our DP-700 exam prep, you will have the opportunity to enjoy our updating system. You will get the newest information about your exam in the shortest time. It not only can help you protect your eyes, but also it will be very convenient for you to make notes. We believe that you will like our DP-700 Exam Prep.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Implementing Data Engineering Solutions Using Microsoft Fabric |
| Exam Number: | DP-700 |
| Certificate Validity Period: | 12 Months (Renewable annually) |
| Available Languages: | Portuguese (Brazil), French, Spanish, Simplified Chinese, Japanese, English, German |
| Related Certifications: | Microsoft Certified: Fabric Data Engineer Associate |
| Exam Price: | $165 USD |
| Real Exam Qty: | 50 - 60 |
| Passing Score: | 700 / 1000 |
| Exam Duration: | 100 minutes |
| Exam Format: | Drag-and-drop, Multiple choice, Case studies, Scenario-based |
| Sample Questions: | Microsoft DP-700 Sample Questions |
| Exam Way: | Online proctored or Test center |
| Pre Condition: | No specific prior certification required. |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/certifications/exams/dp-700/ |
The hit rate for DP-700 exam guide is as high as 99%. Obviously such positive pass rate will establish you confidence as well as strengthen your will to pass your DP-700 exam. No other vendors can challenge our data in this market. At the same time, by studying with our DP-700 practice materials, you avoid wasting your precious time on randomly looking for the key point information. We provide a smooth road for you to success.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 71
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a KQL database that contains two tables named Stream and Reference. Stream contains streaming data in the following format.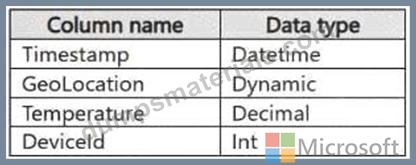
Reference contains reference data in the following format.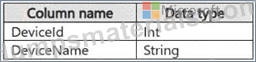
Both tables contain millions of rows.
You have the following KQL queryset.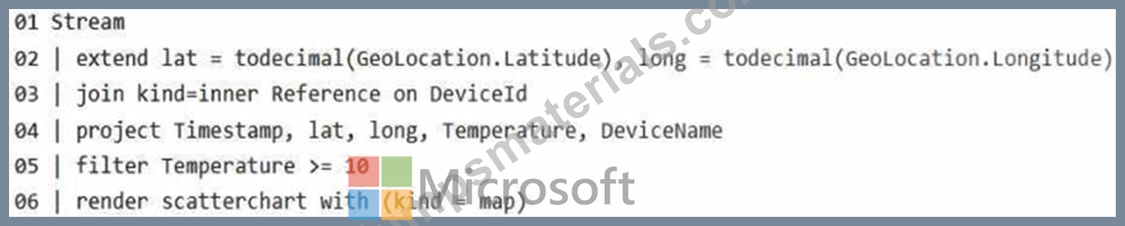
You need to reduce how long it takes to run the KQL queryset.
Solution: You change project to extend.
Does this meet the goal?
Answer: B
Explanation:
Using extend retains all columns in the table, potentially increasing the size of the output unnecessarily.
project is more efficient because it selects only the required columns.
NEW QUESTION # 72
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a KQL database that contains two tables named Stream and Reference. Stream contains streaming data in the following format.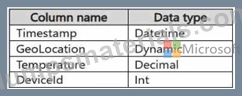
Reference contains reference data in the following format.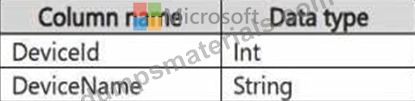
Both tables contain millions of rows.
You have the following KQL queryset.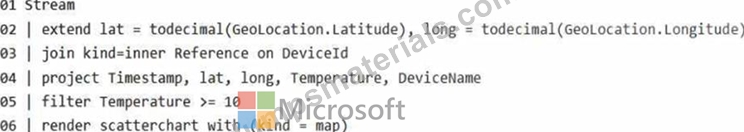
You need to reduce how long it takes to run the KQL queryset.
Solution: You move the filter to line 02.
Does this meet the goal?
Answer: A
Explanation:
Moving the filter to line 02: Filtering the Stream table before performing the join operation reduces the number of rows that need to be processed during the join. This is an effective optimization technique for queries involving large datasets.
NEW QUESTION # 73
You have a Fabric lakehouse that contains the resources shown in the following table.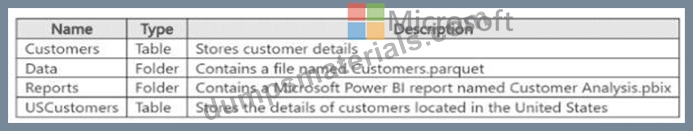
You need to use a notebook to query for customers in the United States and load the filtered data into USCustomers. The solution must minimize the number of scripts used.
Which statement should you use?
Answer: A
NEW QUESTION # 74
HOTSPOT
You are processing streaming data from an external data provider.
You have the following code segment.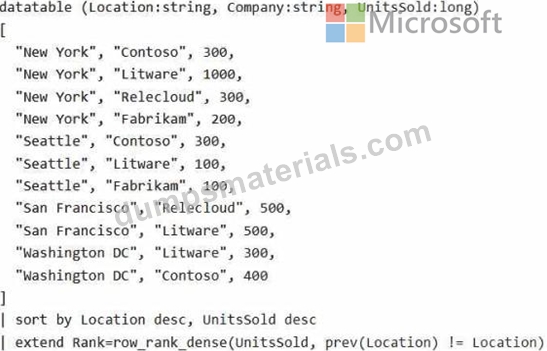
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.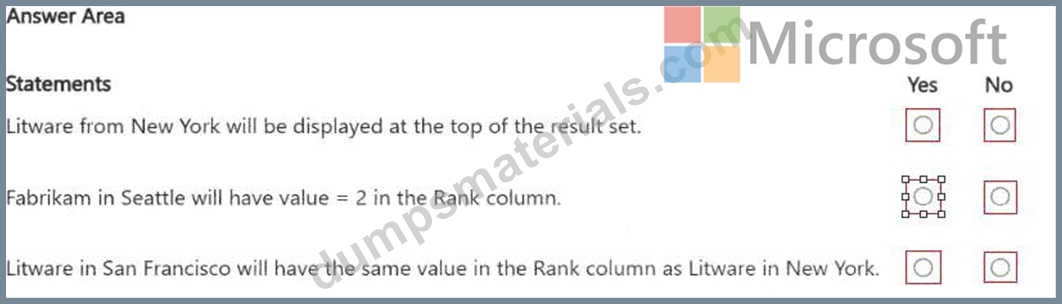
Answer:
Explanation: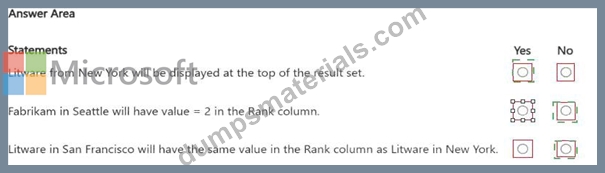
Explanation: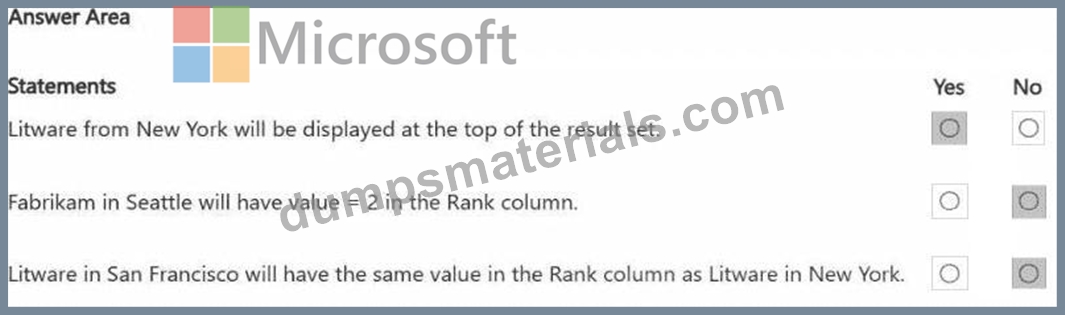
Litware from New York will be displayed at the top of the result set - Yes The data is sorted first by Location in descending order and then by UnitsSold in descending order. Since " New York " is alphabetically the last Location, it will appear first in the result set. Within " New York " , Litware has the highest UnitsSold (1000), so it will be displayed at the top.
Fabrikam in Seattle will have value = 2 in the Rank column - No
The row_rank_dense function assigns dense ranks based on UnitsSold within each location. In " Seattle " :
Contoso has UnitsSold = 300 # Rank 1
Litware has UnitsSold = 100 # Rank 2
Fabrikam also has UnitsSold = 100, so it shares the same rank (2) as Litware.
Litware in San Francisco will have the same value in the Rank column as Litware in New York - No The rank is calculated separately for each location. In " San Francisco " :
Both Relecloud and Litware have UnitsSold = 500, so they share the same rank (1).
In " New York " , Litware has the highest UnitsSold = 1000 # Rank 1.
Since ranks are calculated independently for each location, Litware in San Francisco does not share the same rank as Litware in New York.
NEW QUESTION # 75
HOTSPOT
You have a Fabric workspace that contains a warehouse named Warehouse1. Warehouse1 contains the following tables and columns.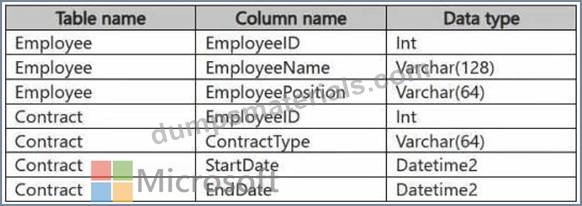
You need to denormalize the tables and include the ContractType and StartDate columns in the Employee table. The solution must meet the following requirements:
Ensure that the StartDate column is of the date data type.
Ensure that all the rows from the Employee table are preserved and include any matching rows from the Contract table.
Ensure that the result set displays the total number of employees per contract type for all the contract types that have more than two employees.
How should you complete the statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.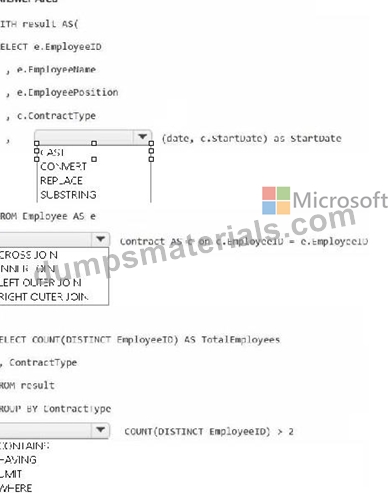
Answer:
Explanation: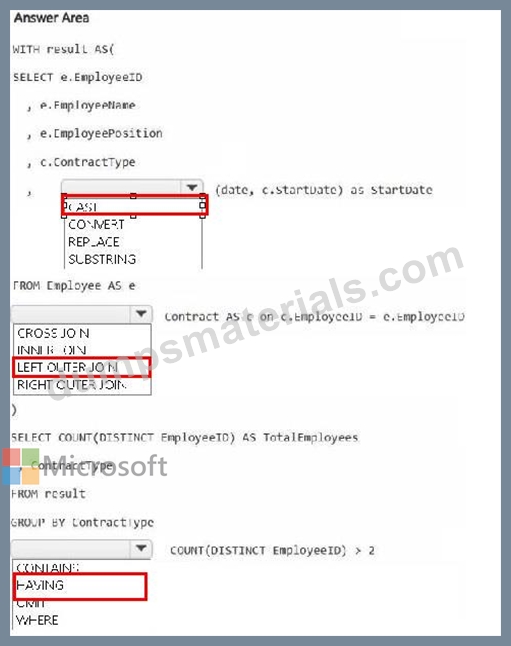
NEW QUESTION # 76
......
DP-700 Test Valid: https://www.dumpsmaterials.com/DP-700-real-torrent.html
What's more, part of that DumpsMaterials DP-700 dumps now are free: https://drive.google.com/open?id=1AGJLZ0dIT__NNZbDd_0v3t02N_P4uT4u