Databricks-Certified-Data-Engineer-Professional New Practice Materials & Valid Databricks-Certified-Data-Engineer-Professional Exam Dumps

What's more, part of that CramPDF Databricks-Certified-Data-Engineer-Professional dumps now are free: https://drive.google.com/open?id=1C02F0WV4inMx8P9RaEZXtjYYTZJUbcwo
Professionals who hold Databricks-Certified-Data-Engineer-Professional certification demonstrate to their employers and clients that they have the knowledge and skills necessary to succeed in the industry. To meet the growing demand for Databricks Databricks-Certified-Data-Engineer-Professional certification exam, preparation platforms have emerged in recent years. CramPDF offers candidates actual Databricks-Certified-Data-Engineer-Professional Questions Pdf, practice exams, and 24/7 support to ensure they have the best possible preparation for the exam.
| Section | Weight | Objectives |
|---|
| Data Transformation, Cleansing, and Quality | 10% | - Apply data cleansing and validation rules
- Enforce data quality standards
- Implement schema evolution and management
|
| Ensuring Data Security and Compliance | 10% | - Secure data at rest and in transit
- Implement access control and permissions
- Ensure data privacy and compliance
|
| Monitoring and Alerting | 10% | - Monitor pipeline performance and health
- Track data lineage and metrics
- Set up alerts and notifications
|
| Debugging and Deploying | 10% | - Deploy using Asset Bundles, CLI, and APIs
- Implement CI/CD and DevOps practices
- Troubleshoot and debug pipelines
|
| Data Ingestion & Acquisition | 7% | - Use Auto Loader and structured streaming
- Ingest data from diverse sources
- Handle incremental and batch data loads
|
| Cost & Performance Optimisation | 13% | - Improve query and pipeline performance
- Optimize compute and storage resources
- Apply cost management best practices
|
| Developing Code for Data Processing using Python and SQL | 22% | - Implement complex data processing logic
- Write efficient and maintainable code
- Use Databricks-specific libraries and APIs
|
| Data Modelling | 6% | - Implement dimensional and relational models
- Design Medallion Architecture
- Optimize table design and partitioning
|
| Data Sharing and Federation | 5% | - Use Delta Sharing for secure data sharing
- Implement Lakehouse Federation
- Manage cross-platform data access
|
| Data Governance | 7% | - Manage data assets and metadata
- Use Unity Catalog for governance
- Enforce data policies and standards
|
>> Databricks-Certified-Data-Engineer-Professional New Practice Materials <<
Pass Guaranteed Quiz 2026 Databricks Databricks-Certified-Data-Engineer-Professional: Useful Databricks Certified Data Engineer Professional Exam New Practice Materials
The Databricks Databricks-Certified-Data-Engineer-Professional certification can play a crucial role in career advancement and increase your earning potential. By obtaining Databricks Databricks-Certified-Data-Engineer-Professional certification, you can demonstrate to employers your expertise and knowledge. The Databricks world is constantly changing its dynamics. With the Databricks Databricks-Certified-Data-Engineer-Professional Certification Exam you can learn these changes and stay updated with the latest technologies and trends.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q236-Q241):
NEW QUESTION # 236
The view updates represents an incremental batch of all newly ingested data to be inserted or updated in the customers table.
The following logic is used to process these records.
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
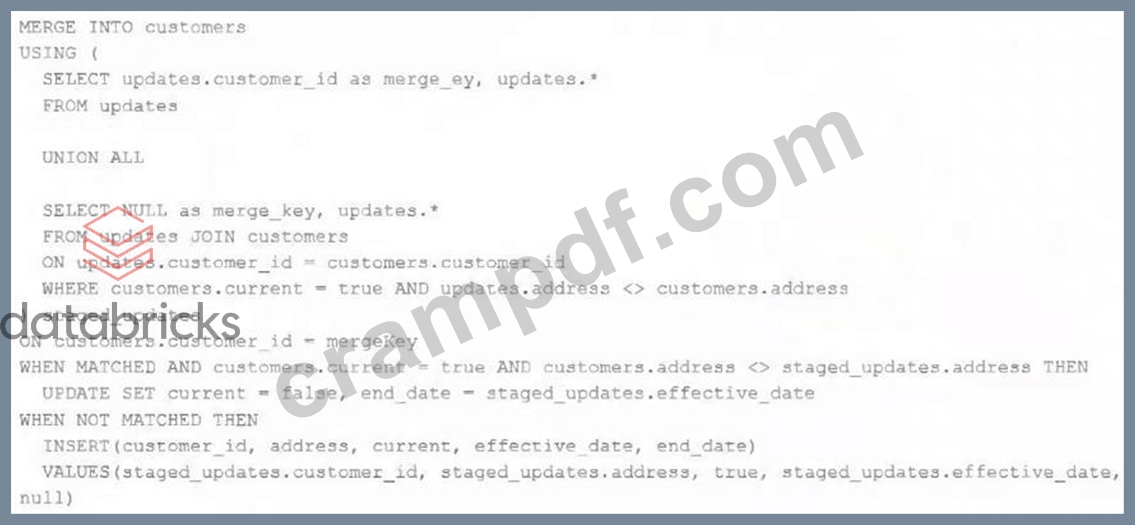
Which statement describes this implementation?
- A. The customers table is implemented as a Type 2 table; old values are overwritten and new customers are appended.
- B. The customers table is implemented as a Type 0 table; all writes are append only with no changes to existing values.
- C. The customers table is implemented as a Type 2 table; old values are maintained but marked as no longer current and new values are inserted.
- D. The customers table is implemented as a Type 3 table; old values are maintained as a new column alongside the current value.
- E. The customers table is implemented as a Type 1 table; old values are overwritten by new values and no history is maintained.
Answer: C
NEW QUESTION # 237
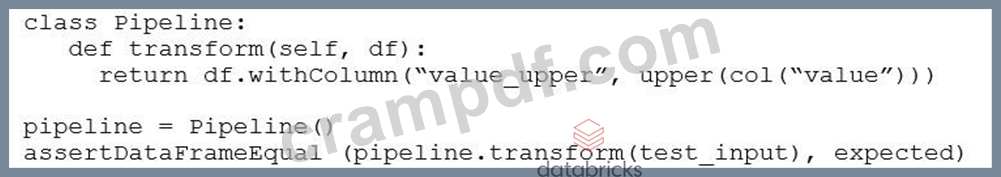
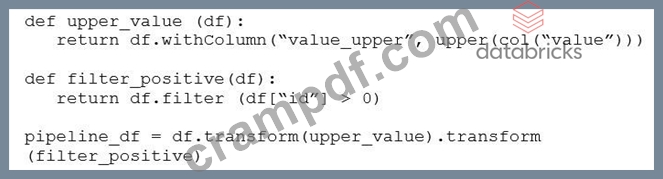
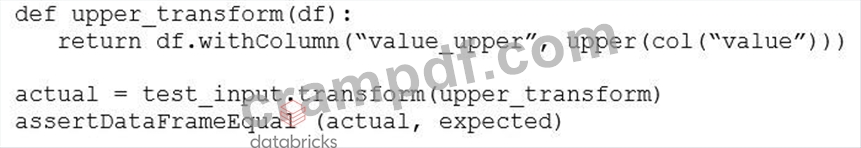
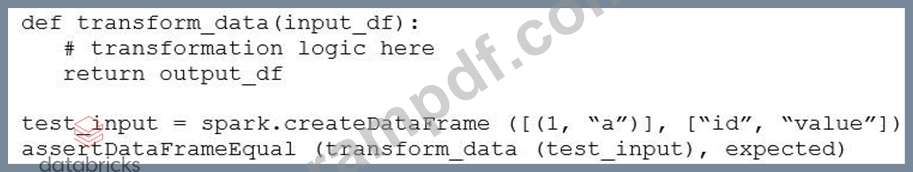
Which approach demonstrates a modular and testable way to use DataFrame transform for ETL code in PySpark?
Answer: C
Explanation:
Using DataFrame.transform with a pure transformation function promotes modular, reusable, and easily testable ETL logic. Each transformation is encapsulated as a standalone function, can be independently unit tested, and composed cleanly in a pipeline without coupling to orchestration or class state.
NEW QUESTION # 238
Why are Pandas UDFs often preferred over traditional PySpark UDFs in performance-critical applications involving large datasets?
- A. They leverage Apache Arrow to enable vectorized operations between the JVM and Python runtimes, reducing serialization costs and improving computational efficiency.
- B. They allow row-level execution of functions in Python with native Spark optimization, removing the need for columnar execution.
- C. They minimize memory usage by streaming each row individually through a lightweight Python wrapper, avoiding batch processing overhead.
- D. They eliminate the JVM-Python boundary by bypassing serialization entirely, thereby avoiding data conversion overhead.
Answer: A
Explanation:
Pandas UDFs use Apache Arrow to transfer data between the JVM and Python in a columnar, vectorized format. This significantly reduces serialization overhead and enables efficient batch processing, resulting in much better performance than traditional row-by-row PySpark UDFs on large datasets.
NEW QUESTION # 239
A data organization has adopted Delta Sharing to securely distribute curated datasets from a Unity Catalog-enabled workspace. The data engineering team shares large Delta tables internally via Databricks-to-Databricks and externally via Open Sharing for aggregated reports. While testing, they encounter challenges related to access control, data update visibility, and shareable object types. What is a limitation of the Delta Sharing protocol or implementation when used with Databricks-to-Databricks or Open Sharing?
- A. Delta Sharing does not support Unity Catalog-enabled tables; only legacy Hive Metastore tables are shareable.
- B. Delta Sharing (both Databricks-to-Databricks and Open Sharing) allows recipients to modify the source data if they have select privileges.
- C. With Databricks-to-Databricks sharing, Unity Catalog recipients must re-ingest data manually using COPY INTO or REST APIs.
- D. With Open Sharing, recipients cannot access Volumes, Models, or notebooks -- only static Delta tables are supported.
Answer: D
Explanation:
According to Databricks' documentation, Open Sharing allows secure sharing of Delta tables to any recipient via a REST-based protocol without requiring a Databricks account. However, the Open Sharing protocol is limited to static Delta tables--it does not support sharing of Unity Catalog objects like Volumes, Machine Learning models, or notebooks. Only Databricks-to- Databricks sharing supports dynamic data sharing with update visibility and streaming reads.
Thus, the inability to share non-table objects in Open Sharing represents a known limitation of the protocol. Option A accurately reflects this constraint as described in Delta Sharing design principles and documentation.
NEW QUESTION # 240
A Data Engineer is building a simple data pipeline using Lakeflow Declarative Pipelines (LDP) in Databricks to ingest customer data. The raw customer data is stored in a cloud storage location in JSON format. The task is to create Lakeflow Declarative Pipelines that read the raw JSON data and write it into a Delta table for further processing. Which code snippet will correctly ingest the raw JSON data and create a Delta table using LDP?
- A. import dlt
@dlt.table
def raw_customers():
return spark.read.format("parquet").load("s3://my-bucket/raw-customers/") - B. import dlt
@dlt.table
def raw_customers():
return spark.read.json("s3://my-bucket/raw-customers/") - C. import dlt
@dlt.view
def raw_customers():
return spark.format.json("s3://my-bucket/raw-customers/") - D. import dlt
@dlt.table
def raw_customers():
return spark.read.format("csv").load("s3://my-bucket/raw-customers/")
Answer: B
Explanation:
The correct method to define a table using Lakeflow Declarative Pipelines (LDP) is with the
@dlt.table decorator, which persists the output as a managed Delta table. When ingesting raw JSON data, spark.read.json() or spark.read.format("json").load() is the standard approach. This reads JSON- formatted files from the source and stores them in Delta format automatically managed by Databricks.
NEW QUESTION # 241
......
You shall prepare yourself for the Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) exam, take the Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) practice exams well, and then attempt the final Databricks-Certified-Data-Engineer-Professional test. So, start your journey by today, get the CramPDF Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) study material, and study well. No one can keep you from rising as a star in the sky.
Valid Databricks-Certified-Data-Engineer-Professional Exam Dumps: https://www.crampdf.com/Databricks-Certified-Data-Engineer-Professional-exam-prep-dumps.html
- Databricks-Certified-Data-Engineer-Professional Test Assessment 🕦 New Databricks-Certified-Data-Engineer-Professional Exam Pdf 👋 Databricks-Certified-Data-Engineer-Professional Latest Test Report 🤟 Search for ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ and download it for free on ➠ www.pdfdumps.com 🠰 website 🛅Valid Databricks-Certified-Data-Engineer-Professional Exam Syllabus
- Latest Databricks-Certified-Data-Engineer-Professional Exam Cost 🦏 New Databricks-Certified-Data-Engineer-Professional Study Plan 🛒 Databricks-Certified-Data-Engineer-Professional Test Guide 🤜 Search on ( www.pdfvce.com ) for ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ to obtain exam materials for free download 🛺Authentic Databricks-Certified-Data-Engineer-Professional Exam Questions
- Databricks-Certified-Data-Engineer-Professional Test Objectives Pdf 🎮 Reliable Databricks-Certified-Data-Engineer-Professional Real Test 🕡 Databricks-Certified-Data-Engineer-Professional Latest Test Report 🌾 Search on ⇛ www.vce4dumps.com ⇚ for ➠ Databricks-Certified-Data-Engineer-Professional 🠰 to obtain exam materials for free download 🏪Databricks-Certified-Data-Engineer-Professional Practice Test Engine
- Databricks-Certified-Data-Engineer-Professional Sure-Pass Learning Materials: Databricks Certified Data Engineer Professional Exam - Databricks-Certified-Data-Engineer-Professional Pass-Sure Torrent - Databricks-Certified-Data-Engineer-Professional Exam Braindumps 🤧 Open ▷ www.pdfvce.com ◁ enter ➠ Databricks-Certified-Data-Engineer-Professional 🠰 and obtain a free download 🍈Reliable Databricks-Certified-Data-Engineer-Professional Real Test
- Free PDF Databricks - Databricks-Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Exam –Efficient New Practice Materials 🦉 The page for free download of ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ on ➤ www.exam4labs.com ⮘ will open immediately 📍Valid Study Databricks-Certified-Data-Engineer-Professional Questions
- Databricks Databricks-Certified-Data-Engineer-Professional New Practice Materials - Pdfvce - Leader in Qualification Exams 🕦 Open website ➥ www.pdfvce.com 🡄 and search for ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ for free download 💆Databricks-Certified-Data-Engineer-Professional Test Objectives Pdf
- Reliable Databricks-Certified-Data-Engineer-Professional New Practice Materials Covers the Entire Syllabus of Databricks-Certified-Data-Engineer-Professional 🕠 Search for ⇛ Databricks-Certified-Data-Engineer-Professional ⇚ and download exam materials for free through ➤ www.prepawaypdf.com ⮘ 💯Databricks-Certified-Data-Engineer-Professional Test Guide
- Databricks-Certified-Data-Engineer-Professional Exam Simulations 🦇 Authentic Databricks-Certified-Data-Engineer-Professional Exam Questions 🖼 New Databricks-Certified-Data-Engineer-Professional Exam Pdf 👟 Search for ➽ Databricks-Certified-Data-Engineer-Professional 🢪 and download it for free on ➡ www.pdfvce.com ️⬅️ website 🐫New Databricks-Certified-Data-Engineer-Professional Exam Format
- Databricks-Certified-Data-Engineer-Professional Practice Test Engine 🍹 Authentic Databricks-Certified-Data-Engineer-Professional Exam Questions ➿ Practice Databricks-Certified-Data-Engineer-Professional Exams Free 🥨 Easily obtain ⇛ Databricks-Certified-Data-Engineer-Professional ⇚ for free download through [ www.prepawaypdf.com ] 🛺Databricks-Certified-Data-Engineer-Professional Test Guide
- Practice Databricks-Certified-Data-Engineer-Professional Exams Free 🦂 Databricks-Certified-Data-Engineer-Professional Latest Test Report 🦗 Valid Databricks-Certified-Data-Engineer-Professional Exam Syllabus 🌁 Immediately open ⇛ www.pdfvce.com ⇚ and search for ⇛ Databricks-Certified-Data-Engineer-Professional ⇚ to obtain a free download 😛Practice Databricks-Certified-Data-Engineer-Professional Exams Free
- Pass Guaranteed Databricks - Databricks-Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Exam –High-quality New Practice Materials 👻 The page for free download of [ Databricks-Certified-Data-Engineer-Professional ] on ▶ www.prepawayexam.com ◀ will open immediately 🥘Databricks-Certified-Data-Engineer-Professional Exam Simulations
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.fotor.com, rare-books.library.sites.carleton.edu, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
DOWNLOAD the newest CramPDF Databricks-Certified-Data-Engineer-Professional PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1C02F0WV4inMx8P9RaEZXtjYYTZJUbcwo