Avail High-quality Dumps Certified-Data-Engineer-Professional Discount to Pass Certified-Data-Engineer-Professional on the First Attempt

In order to serve you better, we have a complete service system for you if you purchasing Certified-Data-Engineer-Professional learning materials. We offer you free demo to have a try before buying, so that you can have a better understanding of what you are going to buy. After your payment for Certified-Data-Engineer-Professional exam dumps, you can receive your downloading link and password within ten minutes, if you don’t receive, you can contact with us, and we will solve it for you. You can enjoy free update for 365 days after buying Certified-Data-Engineer-Professional Exam Dumps, and the update version will be sent to your email automatically. If you have any questions about Certified-Data-Engineer-Professional exam dumps after buying, you can contact with our after-sale service.
| Section | Objectives |
|---|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 2. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDF
- 2. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 3. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 2. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 3. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 4. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 5. Create pipeline components using control flow operators such as if/else and foreach
- 6. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 7. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 8. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
|
| Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Configure Lakehouse Federation with appropriate governance across supported source systems
- 3. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
|
| Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Monitoring and Alerting | - Monitoring
- 1. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 2. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 3. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 4. Use Query Profile and Spark UI to monitor workloads
- Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
- Applying Data Security Mechanisms
- 1. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 2. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 3. Use row filters and column masks to protect sensitive table data
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 2. Apply Change Data Feed to address streaming table limitations and improve latency
- 3. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 4. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 5. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
|
| Data Modeling | - Design and optimize data models
- 1. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 2. Simplify data layout decisions and optimize query performance using liquid clustering
- 3. Design dimensional models for analytical workloads with efficient querying and aggregation
- 4. Design and implement scalable data models using Delta Lake to manage large datasets
|
>> Dumps Certified-Data-Engineer-Professional Discount <<
Certified-Data-Engineer-Professional Cert Guide & Latest Certified-Data-Engineer-Professional Exam Notes
You will get your hands on the international Certified-Data-Engineer-Professional certificate you want. Perhaps you can ask the people around you that Certified-Data-Engineer-Professional study engine have really helped many people pass the exam. Of course, you can also experience it yourself. Next, allow me to introduce our Certified-Data-Engineer-Professional Training Materials. First, our Certified-Data-Engineer-Professional practice briandumps have varied versions as the PDF, software and APP online which can satify different needs of our customers. Secondly, the price is quite favourable.
Databricks Certified Data Engineer Professional Sample Questions (Q84-Q89):
NEW QUESTION # 84
Two data engineers are working on the same Databricks notebook in separate branches. Both have edited the same section of code. When one tries to merge the other's branch into their own using the Databricks Git folders UI, a merge conflict occurs on that notebook file. The UI highlights the conflict and presents options for resolution. How should the data engineers resolve this merge conflict using Databricks Git folders?
- A. Abort the merge, discard all local changes, and try the merge operation again without reviewing the conflicting code.
- B. Delete the conflicted notebook file via the Databricks workspace UI, commit the deletion, and recreate the notebook from scratch in a new commit to bypass the conflict entirely.
- C. Use the Git CLI in the cluster's web terminal to force-push the conflicted merge (git push -force), overriding the remote branch with the local version and discarding changes.
- D. Use the Git folders UI to manually edit the notebook file, selecting the desired lines from both versions and removing the conflict markers, then mark the conflict as resolved.
Answer: D
Explanation:
In the Databricks Git folders integration, when merge conflicts arise in notebooks, the UI provides a visual diff editor that highlights conflicting code segments. Users can manually choose which changes to keep from each branch, edit directly in the notebook UI, and remove conflict markers.
After resolving, the engineer must mark the conflict as resolved, save, and commit the final version.
This process ensures that both contributors' valid code segments are merged correctly and version history is maintained.
Forcing a push (C) or deleting notebooks (B) introduces data loss or versioning issues. Aborting without review (A) violates collaborative best practices. Therefore, D is the only correct and Databricks-approved way to resolve notebook merge conflicts.
NEW QUESTION # 85
A data engineer is using Auto Loader to read incoming JSON data as it arrives. They have configured Auto Loader to quarantine invalid JSON records but notice that over time, some records are being quarantined even though they are well-formed JSON.
The code snippet is:
df = (spark.readStream
.format("cloudFiles")
.option("cloudFiles.format", "json")
.option("badRecordsPath", "/tmp/somewhere/badRecordsPath")
.schema("a int, b int")
.load("/Volumes/catalog/schema/raw_data/"))
What is the cause of the missing data?
- A. The badRecordsPath location is accumulating many small files.
- B. The engineer forgot to set the option "cloudFiles.quarantineMode" = "rescue".
- C. At some point, the upstream data provider switched everything to multi-line JSON.
- D. The source data is valid JSON but does not conform to the defined schema in some way.
Answer: D
Explanation:
Auto Loader quarantines records that cannot be parsed according to the specified schema, even if the JSON itself is well formed. If incoming records contain additional fields, missing fields, or incompatible data types compared to the declared schema, they are treated as invalid and routed to the bad records path.
NEW QUESTION # 86
A data engineer is configuring a Databricks Asset Bundle to deploy a job with granular permissions.
The requirements are:
- Grant the data-engineers group CAN_MANAGE access to the job.
- Ensure the auditors' group can view the job but not modify/run it.
- Avoid granting unintended permissions to other users/groups.
How should the data engineer deploy the job while meeting the requirements?
- A. permissions:
- group_name: data-engineers
level: CAN_MANAGE
- group_name: auditors
level: CAN_VIEW
resources:
jobs:
my-job:
name: data-pipeline
tasks: [...]
job_clusters: [...] - B. resources:
jobs:
my-job:
name: data-pipeline
tasks: [...]
job_clusters: [...]
permissions:
- group_name: data-engineers
level: CAN_MANAGE
- group_name: auditors
level: CAN_VIEW - C. resources:
jobs:
my-job:
name: data-pipeline
tasks: [...]
job_clusters: [...]
permissions:
- group_name: data-engineers
level: CAN_MANAGE
- group_name: auditors
level: CAN_VIEW
- group_name: admin-team
level: IS_OWNER - D. resources:
jobs:
my-job:
name: data-pipeline
tasks: [...]
job: [...]
permissions:
- group_name: data-engineers
level: CAN_MANAGE
permissions:
- group_name: auditors
level: CAN_VIEW
Answer: B
Explanation:
Databricks Asset Bundles (DABs) allow jobs, clusters, and permissions to be defined as code in YAML configuration files. According to the Databricks documentation on job permissions and bundle deployment, when defining permissions within a job resource, they must be scoped directly under that specific job's definition. This ensures that permissions are applied only to the intended job resource and not inadvertently propagated to other jobs or resources.
In this scenario, the data engineer must grant the data-engineers group CAN_MANAGE access, allowing them to configure, edit, and manage the job, while the auditors group should only have CAN_VIEW, giving them read-only access to see configurations and results without the ability to modify or execute. Importantly, no additional groups should be granted permissions, in order to follow the principle of least privilege.
Options A and B introduce unnecessary or unintended groups (like admin-team in A) or define permissions outside of the job scope (as in B). Option C improperly separates the permissions block outside the job resource, which is not aligned with Databricks bundle best practices.
Option D is the correct approach because it defines the job resource my-job with its name, tasks, clusters, and the exact intended permissions (CAN_MANAGE for data-engineers and CAN_VIEW for auditors). This aligns with Databricks' principle of least privilege and ensures compliance with governance standards in Unity Catalog-enabled workspaces.
NEW QUESTION # 87
In order to prevent accidental commits to production data, a senior data engineer has instituted a policy that all development work will reference clones of Delta Lake tables. After testing both deep and shallow clone, development tables are created using shallow clone. A few weeks after initial table creation, the cloned versions of several tables implemented as Type 1 Slowly Changing Dimension (SCD) stop working. The transaction logs for the source tables show that vacuum was run the day before.
Why are the cloned tables no longer working?
- A. Because Type 1 changes overwrite existing records, Delta Lake cannot guarantee data consistency for cloned tables.
- B. Running vacuum automatically invalidates any shallow clones of a table; deep clone should always be used when a cloned table will be repeatedly queried.
- C. The data files compacted by vacuum are not tracked by the cloned metadata; running refresh on the cloned table will pull in recent changes.
- D. The metadata created by the clone operation is referencing data files that were purged as invalid by the vacuum command
- E. Tables created with SHALLOW CLONE are automatically deleted after their default retention threshold of 7 days.
Answer: D
Explanation:
In Delta Lake, a shallow clone creates a new table by copying the metadata of the source table without duplicating the data files. When the vacuum command is run on the source table, it removes old data files that are no longer needed to maintain the transactional log's integrity, potentially including files referenced by the shallow clone's metadata. If these files are purged, the shallow cloned tables will reference non-existent data files, causing them to stop working properly. This highlights the dependency of shallow clones on the source table's data files and the impact of data management operations like vacuum on these clones.
NEW QUESTION # 88
The data governance team is reviewing user for deleting records for compliance with GDPR. The following logic has been implemented to propagate deleted requests from the user_lookup table to the user aggregate table.
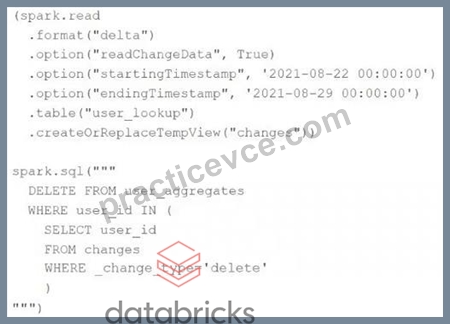
Assuming that user_id is a unique identifying key and that all users have requested deletion have been removed from the user_lookup table, which statement describes whether successfully executing the above logic guarantees that the records to be deleted from the user_aggregates table are no longer accessible and why?
- A. Yes; the change data feed uses foreign keys to ensure delete consistency throughout the Lakehouse.
- B. Yes; Delta Lake ACID guarantees provide assurance that the DELETE command successed fully and permanently purged these records.
- C. No; the change data feed only tracks inserts and updates not deleted records.
- D. No; the Delta Lake DELETE command only provides ACID guarantees when combined with the MERGE INTO command
- E. No; files containing deleted records may still be accessible with time travel until a BACUM command is used to remove invalidated data files.
Answer: E
Explanation:
The DELETE operation in Delta Lake is ACID compliant, which means that once the operation is successful, the records are logically removed from the table. However, the underlying files that contained these records may still exist and be accessible via time travel to older versions of the table. To ensure that these records are physically removed and compliance with GDPR is maintained, a VACUUM command should be used to clean up these data files after a certain retention period. The VACUUM command will remove the files from the storage layer, and after this, the records will no longer be accessible.
NEW QUESTION # 89
......
It might be time-consuming and tired to prepare for the Certified-Data-Engineer-Professional exam without a specialist study material. So it's would be the best decision to choose our Certified-Data-Engineer-Professional study tool as your learning partner. Our Certified-Data-Engineer-Professional study tool also gives numerous candidates a better perspective on the real exam. Having been specializing in the research of Certified-Data-Engineer-Professional Latest Practice Materials, we now process a numerous of customers with our endless efforts, and we believe that our Certified-Data-Engineer-Professional exam guide will percolate to your satisfaction.
Certified-Data-Engineer-Professional Cert Guide: https://www.practicevce.com/Databricks/Certified-Data-Engineer-Professional-practice-exam-dumps.html
- Download Certified-Data-Engineer-Professional Pdf 🐼 Certified-Data-Engineer-Professional Reliable Braindumps Files ⭐ Certified-Data-Engineer-Professional Latest Exam Pass4sure 👷 Go to website ▶ www.prepawayete.com ◀ open and search for ( Certified-Data-Engineer-Professional ) to download for free ☔New Braindumps Certified-Data-Engineer-Professional Book
- Certified-Data-Engineer-Professional Latest Exam Pass4sure 🔱 Certified-Data-Engineer-Professional Reliable Braindumps Files 📻 New Certified-Data-Engineer-Professional Dumps 💫 ➽ www.pdfvce.com 🢪 is best website to obtain ☀ Certified-Data-Engineer-Professional ️☀️ for free download 🤐Certified-Data-Engineer-Professional Trusted Exam Resource
- Exam Dumps Certified-Data-Engineer-Professional Demo 🍀 Download Certified-Data-Engineer-Professional Pdf 🥀 Certified-Data-Engineer-Professional New Dumps Pdf 🏺 Search on ➽ www.prep4away.com 🢪 for ➤ Certified-Data-Engineer-Professional ⮘ to obtain exam materials for free download 🩱Certified-Data-Engineer-Professional Latest Exam Pass4sure
- Updated Certified-Data-Engineer-Professional CBT 🙎 Certified-Data-Engineer-Professional Exam Questions Answers 🚜 Updated Certified-Data-Engineer-Professional CBT 🦡 Immediately open ➤ www.pdfvce.com ⮘ and search for 【 Certified-Data-Engineer-Professional 】 to obtain a free download 🌤Certified-Data-Engineer-Professional Latest Exam Pass4sure
- Frequent Certified-Data-Engineer-Professional Updates 🐨 New Certified-Data-Engineer-Professional Dumps 🐞 Certified-Data-Engineer-Professional Trusted Exam Resource 🤶 Search for ☀ Certified-Data-Engineer-Professional ️☀️ and download it for free on ➠ www.prepawaypdf.com 🠰 website 🎲New Braindumps Certified-Data-Engineer-Professional Book
- 100% Pass 2026 Databricks Certified-Data-Engineer-Professional: First-grade Dumps Databricks Certified Data Engineer Professional Discount 😄 Search on ➥ www.pdfvce.com 🡄 for ▷ Certified-Data-Engineer-Professional ◁ to obtain exam materials for free download 🦢Certified-Data-Engineer-Professional Practice Exam
- Databricks Certified-Data-Engineer-Professional Exam | Dumps Certified-Data-Engineer-Professional Discount - Useful Tips - Questions for your Certified-Data-Engineer-Professional Learning 🛫 Open { www.verifieddumps.com } and search for [ Certified-Data-Engineer-Professional ] to download exam materials for free 😾Certified-Data-Engineer-Professional Trusted Exam Resource
- Certified-Data-Engineer-Professional Reliable Braindumps Files ✍ Test Certified-Data-Engineer-Professional Cram Pdf 🏌 Valid Test Certified-Data-Engineer-Professional Testking 📕 Enter ▛ www.pdfvce.com ▟ and search for ➠ Certified-Data-Engineer-Professional 🠰 to download for free 🏭Certified-Data-Engineer-Professional Practice Exam
- Actual Exam Questions in Databricks Certified-Data-Engineer-Professional PDF for Quick Preparation 🐅 Simply search for ▶ Certified-Data-Engineer-Professional ◀ for free download on ( www.examdiscuss.com ) 🧕Exam Dumps Certified-Data-Engineer-Professional Demo
- Databricks Certified-Data-Engineer-Professional Exam | Dumps Certified-Data-Engineer-Professional Discount - Useful Tips - Questions for your Certified-Data-Engineer-Professional Learning ⛽ Open ( www.pdfvce.com ) and search for ▶ Certified-Data-Engineer-Professional ◀ to download exam materials for free 🟩New Certified-Data-Engineer-Professional Dumps
- 2026 Authoritative Dumps Certified-Data-Engineer-Professional Discount | Certified-Data-Engineer-Professional 100% Free Cert Guide 🏗 Search for ➤ Certified-Data-Engineer-Professional ⮘ and download it for free on ( www.torrentvce.com ) website 🗜Exam Dumps Certified-Data-Engineer-Professional Demo
- vrcmods.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.notebook.ai, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes