After a short time's studying and practicing with our Databricks-Certified-Professional-Data-Engineer exam questions, you will easily pass the examination. We can claim that if you study with our Databricks-Certified-Professional-Data-Engineer learning quiz for 20 to 30 hours, then you will be confident to attend the exam. God helps those who help themselves. If you choose our Databricks-Certified-Professional-Data-Engineer Study Materials, you will find God just by your side. The only thing you have to do is just to make your choice and study. Isn't it very easy? So know more about our Databricks-Certified-Professional-Data-Engineer practice guide right now!
Databricks Databricks-Certified-Professional-Data-Engineer is a certification that validates the skills and knowledge of professionals who work with big data and data engineering. Databricks-Certified-Professional-Data-Engineer exam is designed for individuals who have experience in designing, building, and maintaining data pipelines on the Databricks platform. Databricks Certified Professional Data Engineer Exam certification confirms that the candidate has proficiency in building robust, scalable, and efficient big data solutions in the cloud.
Databricks Certified Professional Data Engineer certification is designed for data engineers who work with the Databricks platform and have a deep understanding of data engineering concepts. Databricks Certified Professional Data Engineer Exam certification exam tests the candidate’s ability to design, build, and maintain data pipelines using Databricks, as well as their knowledge of data modeling, data warehousing, and data governance. Databricks Certified Professional Data Engineer Exam certification is recognized globally and indicates that the candidate has the skills and expertise needed to work with Databricks.
>> Databricks-Certified-Professional-Data-Engineer Latest Mock Exam <<
The Databricks Certified Professional Data Engineer Exam Databricks-Certified-Professional-Data-Engineer certification provides both novices and experts with a fantastic opportunity to show off their knowledge of and proficiency in carrying out a particular task. With the Databricks Databricks-Certified-Professional-Data-Engineer exam, you will have the chance to update your knowledge while obtaining dependable evidence of your proficiency. You can also get help from actual Databricks Certified Professional Data Engineer Exam Databricks-Certified-Professional-Data-Engineer Exam Questions and pass your dream Databricks Certified Professional Data Engineer Exam Databricks-Certified-Professional-Data-Engineer certification exam.
Achieving the Databricks Certified Professional Data Engineer certification is a valuable asset for data professionals. It demonstrates that the individual has the necessary knowledge and skills to work with big data and cloud computing technologies, specifically with Databricks Unified Analytics Platform. Databricks Certified Professional Data Engineer Exam certification is recognized by leading organizations and can help individuals advance their careers in the field of data engineering. It also provides a competitive advantage over other candidates while applying for jobs in the field of big data and cloud computing.
NEW QUESTION # 55
A data architect has heard about lake's built-in versioning and time travel capabilities. For auditing purposes they have a requirement to maintain a full of all valid street addresses as they appear in the customers table.
The architect is interested in implementing a Type 1 table, overwriting existing records with new values and relying on Delta Lake time travel to support long-term auditing. A data engineer on the project feels that a Type 2 table will provide better performance and scalability.
Which piece of information is critical to this decision?
Answer: D
Explanation:
Setting multiple fields in a single update.
Explanation:
Delta Lake's time travel feature allows users to access previous versions of a table, providing a powerful tool for auditing and versioning. However, using time travel as a long-term versioning solution for auditing purposes can be less optimal in terms of cost and performance, especially as the volume of data and the number of versions grow. For maintaining a full history of valid street addresses as they appear in a customers table, using a Type 2 table (where each update creates a new record with versioning) might provide better scalability and performance by avoiding the overhead associated with accessing older versions of a large table. While Type 1 tables, where existing records are overwritten with new values, seem simpler and can leverage time travel for auditing, the critical piece of information is that time travel might not scale well in cost or latency for long-term versioning needs, making a Type 2 approach more viable for performance and scalability.
Reference:
Databricks Documentation on Delta Lake's Time Travel: Delta Lake Time Travel Databricks Blog on Managing Slowly Changing Dimensions in Delta Lake: Managing SCDs in Delta Lake
NEW QUESTION # 56
A data engineer wants to create a cluster using the Databricks CLI for a big ETL pipeline. The cluster should have five workers, one driver of type i3.xlarge, and should use the '14.3.x-scala2.12' runtime.
Which command should the data engineer use?
Answer: A
Explanation:
The Databricks CLI allows users to manage clusters using command-line commands. The correct command for creating a cluster follows a specific format.
Key Components in the Command:
* Command Type: databricks compute create is the correct syntax for creating a new compute resource (cluster).
* Runtime Version: '14.3.x-scala2.12' specifies the Databricks runtime to use.
* Workers: --num-workers 5 sets the number of worker nodes to 5.
* Node Type: --node-type-id i3.xlarge defines the hardware configuration.
* Cluster Name: --cluster-name DataEngineer_cluster assigns a recognizable name to the cluster.
Evaluation of Options:
* Option A (databricks clusters create ...)
* Incorrect: databricks clusters create is not a valid command in the Databricks CLI v0.205.
* The correct CLI command for cluster creation is databricks compute create.
* Option B (databricks clusters add ...)
* Incorrect: databricks clusters add is not a valid CLI command.
* Option C (databricks compute add ...)
* Incorrect: databricks compute add is not a valid CLI command.
* Option D (databricks compute create ...)
* Correct: databricks compute create is the correct command for creating a cluster.
Conclusion:
The correct command to create a cluster with five workers, an i3.xlarge node type, and Databricks runtime
14.3.x-scala2.12 is:
databricks compute create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster Thus, the correct answer is D.
References:
Databricks CLI Documentation
NEW QUESTION # 57
A data engineer is using Lakeflow Declarative Pipeline to propagate row deletions from a source bronze table (user_bronze) to a target silver table (user_silver) . The engineer wants deletions in user_bronze to automatically delete corresponding rows in user_silver during pipeline execution.
Which configuration ensures deletions in the bronze table are propagated to the silver table?
Answer: A
Explanation:
According to Databricks documentation, Change Data Feed (CDF) allows pipelines to read incremental data changes, including inserts, updates, and deletes, from a Delta table. When deletions occur in the source table, reading the CDF stream ensures downstream consumers receive the deletion records. The Lakeflow Declarative Pipelines API provides the apply_changes() function (or auto-CDC pipelines) with the apply_as_deletes parameter to correctly apply those deletions to the target table. This enables automatic synchronization between bronze and silver layers. Options A and D either require manual handling or complete rebuilds, and C incorrectly applies CDF to the target rather than the source. Therefore, enabling CDF on the bronze table and using apply_as_deletes=True is the correct, Databricks-supported configuration.
NEW QUESTION # 58
The security team is exploring whether or not the Databricks secrets module can be leveraged for connecting to an external database.
After testing the code with all Python variables being defined with strings, they upload the password to the secrets module and configure the correct permissions for the currently active user. They then modify their code to the following (leaving all other variables unchanged).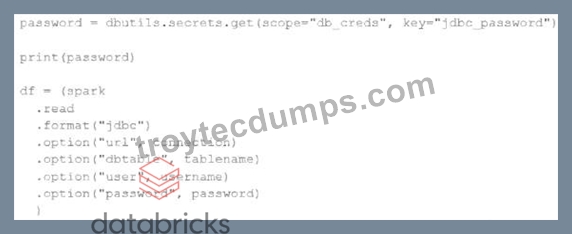
Which statement describes what will happen when the above code is executed?
Answer: B
Explanation:
This is the correct answer because the code is using the dbutils.secrets.get method to retrieve the password from the secrets module and store it in a variable. The secrets module allows users to securely store and access sensitive information such as passwords, tokens, or API keys. The connection to the external table will succeed because the password variable will contain the actual password value. However, when printing the password variable, the string "redacted" will be displayed instead of the plain text password, as a security measure to prevent exposing sensitive information in notebooks. Verified References: [Databricks Certified Data Engineer Professional], under "Security & Governance" section; Databricks Documentation, under
"Secrets" section.
NEW QUESTION # 59
Which statement describes integration testing?
Answer: E
Explanation:
This is the correct answer because it describes integration testing. Integration testing is a type of testing that validates interactions between subsystems of your application, such as modules, components, or services.
Integration testing ensures that the subsystems work together as expected and produce the correct outputs or results. Integration testing can be done at different levels of granularity, such as component integration testing, system integration testing, or end-to-end testing. Integration testing can help detect errors or bugs that may not be found by unit testing, which only validates behavior of individual elements of your application. Verified References: [Databricks Certified Data Engineer Professional], under "Testing" section; Databricks Documentation, under "Integration testing" section.
NEW QUESTION # 60
......
Databricks-Certified-Professional-Data-Engineer Vce Exam: https://www.troytecdumps.com/Databricks-Certified-Professional-Data-Engineer-troytec-exam-dumps.html