What's more, part of that BraindumpsVCE MLA-C01 dumps now are free: https://drive.google.com/open?id=1Cmr_HCaRMwdI9kf57Ru2XLpYkjtWPHVY
The passing rate of our study material is very high, and it is about 99%. We provide free download and tryout of the MLA-C01 question torrent, and we will update the MLA-C01 exam torrent frequently to guarantee that you can get enough test bank and follow the trend in the theory and the practice. We provide 3 versions for you to choose thus you can choose the most convenient method to learn. Our MLA-C01 Latest Questions are compiled by the experienced professionals elaborately. So it will be very convenient for you to buy our product and it will do a lot of good to you.
| Certification Vendor: | Amazon Web Services (AWS) |
|---|---|
| Exam Name: | AWS Certified Machine Learning Engineer - Associate |
| Exam Number: | MLA-C01 |
| Available Languages: | English, Simplified Chinese, Korean, Japanese |
| Passing Score: | 720 (scaled score 100–1000) |
| Related Certifications: | AWS Certified AI Practitioner AWS Certified Machine Learning - Specialty |
| Real Exam Qty: | 65 (50 scored, 15 unscored) |
| Exam Format: | Ordering, Case study, Multiple response, Multiple choice, Matching |
| Exam Price: | 150 USD |
| Exam Duration: | 130 minutes |
| Certificate Validity Period: | 3 years |
| Recommended Training: | AWS Certified Machine Learning Engineer - Associate Official Exam Guide AWS Training and Certification |
| Exam Registration: | Pearson VUE Registration AWS Certification Portal |
| Sample Questions: | Amazon MLA-C01 Sample Questions |
| Exam Way: | Online proctored or onsite at Pearson VUE testing centers |
| Pre Condition: | Recommended: 1+ year hands-on experience with AWS services and machine learning engineering; familiarity with Amazon SageMaker and related ML services. No mandatory prerequisite exams. |
| Official Syllabus URL: | https://docs.aws.amazon.com/aws-certification/latest/machine-learning-engineer-associate-01/machine-learning-engineer-associate-01.html |
For MLA-C01 test dumps, we give you free demo for you to try, so that you can have a deeper understanding of what you are going to buy. The pass rate is 98%, and we also pass guarantee and money back guarantee if you fail to pass it. MLA-C01 test dumps of us contain questions and answers, and it will help you to have an adequate practice. Besides we have free update for one year for you, therefore you can get the latest version in the following year if you buying MLA-C01 Exam Dumps of us. Buying them, and you will benefit from them in the next year.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 164
A company has developed a computer vision model. The company needs to deploy the model into production on Amazon SageMaker AI. The company has not hosted a model on SageMaker AI previously.
An ML engineer needs to implement a solution to track model versions. The solution also must provide recommendations about which Amazon EC2 instance types to use to host the model.
Which solution will meet these requirements?
Answer: B
Explanation:
Option C is correct because the requirement has two separate parts : first, the company must track model versions ; second, it needs recommendations for which instance types to use for hosting the model in SageMaker AI. AWS documentation identifies the SageMaker Model Registry as the SageMaker feature used to register and manage model packages and versions as part of the ML lifecycle. For hosting recommendations, AWS documentation says Amazon SageMaker Inference Recommender helps select the best instance type and configuration for ML models and workloads by automating benchmarking and load testing across SageMaker AI instances.
The AWS Inference Recommender documentation is especially important here because it explicitly says you can use it after you register a model to the SageMaker Model Registry with model artifacts. It also states that Inference Recommender helps choose the best endpoint type and configuration and returns recommendations that include the instance type in the resulting endpoint configuration. That is an exact match to the question's requirement to recommend hosting instance types for a model that has not yet been hosted on SageMaker AI.
The other options do not match AWS service purposes. Amazon ECR stores container images, not model versions. AWS Compute Optimizer is not the SageMaker-native service documented for inference benchmarking of ML models. SageMaker Autopilot is for automated model building, not inference instance recommendations. SageMaker Experiments tracks experiment metadata, trials, and runs, but it does not recommend deployment instance types. Therefore, the fully verified AWS-docs answer is C .
NEW QUESTION # 165
A company stores historical data in .csv files in Amazon S3. Only some of the rows and columns in the .csv files are populated. The columns are not labeled. An ML engineer needs to prepare and store the data so that the company can use the data to train ML models.
Select and order the correct steps from the following list to perform this task. Each step should be selected one time or not at all. (Select and order three.)
* Create an Amazon SageMaker batch transform job for data cleaning and feature engineering.
* Store the resulting data back in Amazon S3.
* Use Amazon Athena to infer the schemas and available columns.
* Use AWS Glue crawlers to infer the schemas and available columns.
* Use AWS Glue DataBrew for data cleaning and feature engineering.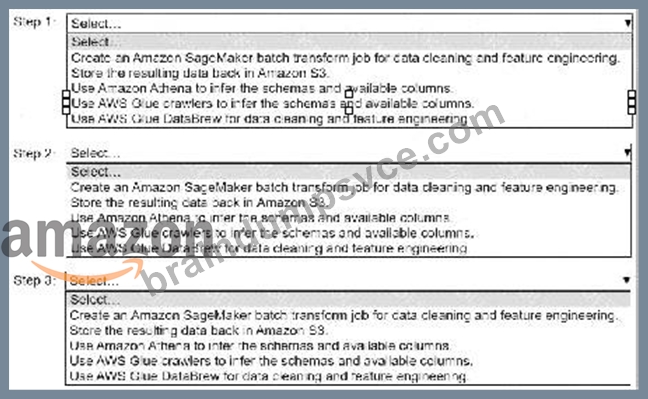
Answer:
Explanation: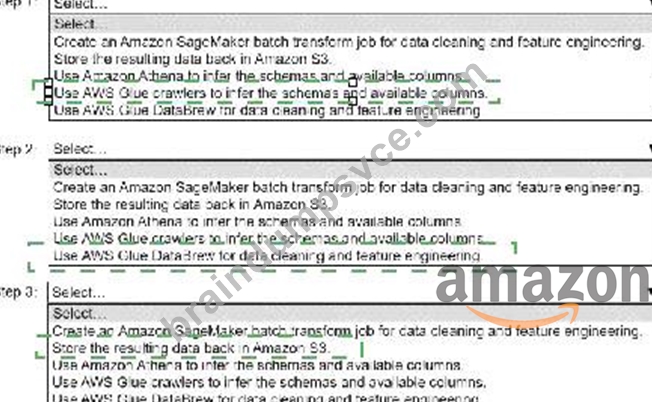
Explanation:
Step 1: Use AWS Glue crawlers to infer the schemas and available columns.
Step 2: Use AWS Glue DataBrew for data cleaning and feature engineering.
Step 3: Store the resulting data back in Amazon S3.
Step 1: Use AWS Glue Crawlers to Infer Schemas and Available Columns
Why? The data is stored in .csv files with unlabeled columns, and Glue Crawlers can scan the raw data in Amazon S3 to automatically infer the schema, including available columns, data types, and any missing or incomplete entries.
How? Configure AWS Glue Crawlers to point to the S3 bucket containing the .csv files, and run the crawler to extract metadata. The crawler creates a schema in the AWS Glue Data Catalog, which can then be used for subsequent transformations.
Step 2: Use AWS Glue DataBrew for Data Cleaning and Feature Engineering Why? Glue DataBrew is a visual data preparation tool that allows for comprehensive cleaning and transformation of data. It supports imputation of missing values, renaming columns, feature engineering, and more without requiring extensive coding.
How? Use Glue DataBrew to connect to the inferred schema from Step 1 and perform data cleaning and feature engineering tasks like filling in missing rows/columns, renaming unlabeled columns, and creating derived features.
Step 3: Store the Resulting Data Back in Amazon S3
Why? After cleaning and preparing the data, it needs to be saved back to Amazon S3 so that it can be used for training machine learning models.
How? Configure Glue DataBrew to export the cleaned data to a specific S3 bucket location. This ensures the processed data is readily accessible for ML workflows.
Order Summary:
Use AWS Glue crawlers to infer schemas and available columns.
Use AWS Glue DataBrew for data cleaning and feature engineering.
Store the resulting data back in Amazon S3.
This workflow ensures that the data is prepared efficiently for ML model training while leveraging AWS services for automation and scalability.
NEW QUESTION # 166
A retail company is analyzing customer purchase data to develop personalized product recommendations. The company wants to use Amazon SageMaker Clarify to assess fairness metrics across different customer groups to avoid potential bias in the recommendation system.
The recommendation system needs to identify if certain customer segments are underrepresented in the training data. The company needs to choose a pre-training bias metric in SageMaker Clarify.
Which metric meets these requirements?
Answer: B
Explanation:
The correct answer is C. Class imbalance ratio.
Amazon SageMaker Clarify provides both pre-training and post-training bias detection capabilities to help data scientists ensure fairness in ML models. Pre-training bias metrics specifically analyze the training dataset to detect underrepresentation of certain groups or features before a model is trained. The class imbalance ratio measures how evenly different classes or sensitive attributes are represented in the dataset. A high imbalance indicates that a particular segment of customers (e.g., certain age groups, genders, or ethnicities) may be underrepresented, which could lead to biased predictions when the model is deployed.
Feature attribution bias (Option B) and prediction distribution skew (Option A) are post-training metrics.
Feature attribution bias evaluates whether the model relies disproportionately on certain features for predictions, while prediction distribution skew examines whether the model's outputs are skewed for specific groups. Model performance gap (Option D) is also a post-training measure, focusing on differences in accuracy or other performance metrics between groups.
By using the class imbalance ratio during pre-training analysis, the company can identify and mitigate underrepresentation before training the model. Actions may include resampling the dataset, weighting underrepresented classes, or applying synthetic data augmentation to ensure that the model is trained on a balanced, fair dataset. This aligns with AWS best practices for ML solution monitoring, maintenance, and security, particularly for responsible AI and fairness assessment.
In summary, the class imbalance ratio allows proactive bias detection at the dataset level, preventing unfair recommendations and ensuring equitable treatment across all customer segments in the recommendation system.
NEW QUESTION # 167
A company is planning to use Amazon Redshift ML in its primary AWS account. The source data is in an Amazon S3 bucket in a secondary account.
An ML engineer needs to set up an ML pipeline in the primary account to access the S3 bucket in the secondary account. The solution must not require public IPv4 addresses.
Which solution will meet these requirements?
Answer: C
Explanation:
S3 Gateway Endpoint: Allows private access to S3 from within a VPC without requiring a public IPv4 address, ensuring that data transfer between the primary and secondary accounts is secure and private.
Bucket Policy Update: The S3 bucket policy in the secondary account must explicitly allow access from the primary account's IAM principals to provide the necessary permissions.
Interface VPC Endpoints: Required for private communication between the VPC and Amazon SageMaker and Amazon Redshift services, ensuring the solution operates without public internet access.
This configuration meets the requirement to avoid public IPv4 addresses and allows secure and private communication between the accounts.
NEW QUESTION # 168
A company has developed a new ML model. The company requires online model validation on 10% of the traffic before the company fully releases the model in production. The company uses an Amazon SageMaker endpoint behind an Application Load Balancer (ALB) to serve the model.
Which solution will set up the required online validation with the LEAST operational overhead?
Answer: D
Explanation:
Scenario:The company wants to perform online validation of a new ML model on 10% of the traffic before fully deploying the model in production. The setup must have minimal operational overhead.
Why Use SageMaker Production Variants?
* Built-In Traffic Splitting:Amazon SageMaker endpoints support production variants, allowing multiple models to run on a single endpoint. You can direct a percentage of incoming traffic to each variant by adjusting the variant weights.
* Ease of Management:Using production variants eliminates the need for additional infrastructure like separate endpoints or custom ALB configurations.
* Monitoring with CloudWatch:SageMaker automatically integrates with CloudWatch, enabling real- time monitoring of model performance and invocation metrics.
Steps to Implement:
* Deploy the New Model as a Production Variant:
* Update the existing SageMaker endpoint to include the new model as a production variant. This can be done via the SageMaker console, CLI, or SDK.
Example SDK Code:
import boto3
sm_client = boto3.client('sagemaker')
response = sm_client.update_endpoint_weights_and_capacities(
EndpointName='existing-endpoint-name',
DesiredWeightsAndCapacities=[
{'VariantName': 'current-model', 'DesiredWeight': 0.9},
{'VariantName': 'new-model', 'DesiredWeight': 0.1}
]
)
* Set the Variant Weight:
* Assign a weight of 0.1 to the new model and 0.9 to the existing model. This ensures 10% of traffic goes to the new model while the remaining 90% continues to use the current model.
* Monitor the Performance:
* Use Amazon CloudWatch metrics, such as InvocationCount and ModelLatency, to monitor the traffic and performance of each variant.
* Validate the Results:
* Analyze the performance of the new model based on metrics like accuracy, latency, and failure rates.
Why Not the Other Options?
* Option B:Setting the weight to 1 directs all traffic to the new model, which does not meet the requirement of splitting traffic for validation.
* Option C:Creating a new endpoint introduces additional operational overhead for traffic routing and monitoring, which is unnecessary given SageMaker's built-in production variant capability.
* Option D:Configuring the ALB to route traffic requires manual setup and lacks SageMaker's seamless variant monitoring and traffic splitting features.
Conclusion:Using production variants with a weight of 0.1 for the new model on the existing SageMaker endpoint provides the required traffic split for online validation with minimal operational overhead.
References:
* Amazon SageMaker Endpoints
* SageMaker Production Variants
* Monitoring SageMaker Endpoints with CloudWatch
NEW QUESTION # 169
......
MLA-C01 Test Collection Pdf: https://www.braindumpsvce.com/MLA-C01_exam-dumps-torrent.html
2026 Latest BraindumpsVCE MLA-C01 PDF Dumps and MLA-C01 Exam Engine Free Share: https://drive.google.com/open?id=1Cmr_HCaRMwdI9kf57Ru2XLpYkjtWPHVY