These Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam questions are a one-time investment to clear the DP-750 test in a short time. These DP-750 exam questions eliminate the need for candidates to study extra or irrelevant content, allowing them to complete their Microsoft test preparation quickly. By avoiding unnecessary information, you can save time and crack the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification exam in one go. Check out the features of the three formats.
| Section | Weight | Objectives |
|---|---|---|
| Deploy and manage data pipelines and workloads | 30-35% | - Pipeline design and orchestration
|
| Prepare and process data | 30-35% | - Data transformation and modeling
|
| Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
| Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
>> DP-750 Reliable Dumps Ebook <<
ExamDiscuss is a good website for Microsoft certification DP-750 exams to provide short-term effective training. And ExamDiscuss can guarantee your Microsoft certification DP-750 exam to be qualified. If you don't pass the exam, we will take a full refund to you. Before you choose to buy the ExamDiscuss products before, you can free download part of the exercises and answers about Microsoft Certification DP-750 Exam as a try, then you will be more confident to choose ExamDiscuss's products to prepare your Microsoft certification DP-750 exam.
NEW QUESTION # 43
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to profile a table to meet the following requirements:
* The count of null values per column must be evaluated repeatedly as new records are added to the table.
* Changes in the count of null values must be observable over the progression of the dataset.
Which type of profile should you create?
Answer: A
Explanation:
A time series profile repeatedly calculates data-quality metrics as a table changes and preserves those measurements over time. This makes it possible to observe whether the number of null values in each column is increasing, decreasing, or remaining stable as new records are added. A snapshot profile evaluates the table at a particular point in time and is therefore insufficient when the requirement is to analyze metric progression across multiple updates. Inference is associated with deriving information such as a schema or statistical characteristics; it is not the profile type used to maintain a historical sequence of monitoring measurements.
Because the question requires repeated evaluation and the ability to observe changes throughout the dataset's progression, the time series profile satisfies both requirements.
NEW QUESTION # 44
You need to configure compute for the ingestion of telemetry data. The solution must meet the data ingestion and processing requirements.
What should you do?
Answer: A
Explanation:
The correct answer is A. Photon is Azure Databricks' native vectorized query engine, written in C++, designed to accelerate data ingestion and SQL-heavy workloads significantly over the standard Spark JVM path. Enabling it on a job compute cluster directly addresses Contoso's requirement for 'fast and consistent performance for BI workloads' and 'production ingestion workloads that can scale automatically during telemetry spikes.' Photon integrates transparently - no code changes are needed - and pairs well with autoscaling job clusters to handle the bursty 40,000-sensor telemetry load.
Option B contradicts the isolation requirement: Contoso explicitly needs production and development separated, not merged onto shared compute. Option C with a fixed large node gives peak capacity at all times, driving up costs even during quiet periods. Option D disabling autoscaling is the opposite of what's needed - telemetry spikes require elastic scaling, not a locked node count.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/photon
NEW QUESTION # 45
You use Databricks Asset Bundles to manage two jobs and an app.
You need to deploy the bundle to development and production environments. The solution must meet the following requirements
* Deploy the app to both environments.
* Deploy only one job to development.
* Minimize administrative effort.
What should you use?
Answer: D
Explanation:
The correct answer is D - a targets node in databricks.yml.
Databricks Asset Bundles use a single databricks.yml to define all resources (jobs, apps, pipelines) once, and a targets node to define per-environment overrides. Within the development target, you can use the include
/exclude mechanism or resource-level overrides to deploy only one of the two jobs. The app and the second job are deployed to both environments through the shared resource definition.
Option B (separate databricks.yml files per environment) works technically but means duplicating the shared resource definitions across files - any change to a shared resource requires edits in multiple places, which is exactly the administrative overhead the question wants to avoid.
Option A (resources node) defines resources globally across all targets - it doesn't provide environment- specific filtering. Option C (variables node) parameterises values like cluster sizes or paths but doesn't control which resources are deployed to which environment.
Reference: https://learn.microsoft.com/en-us/azure/databricks/dev-tools/bundles/deployment-modes
NEW QUESTION # 46
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You plan to run the following PySpark code.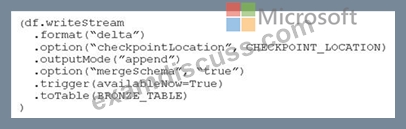
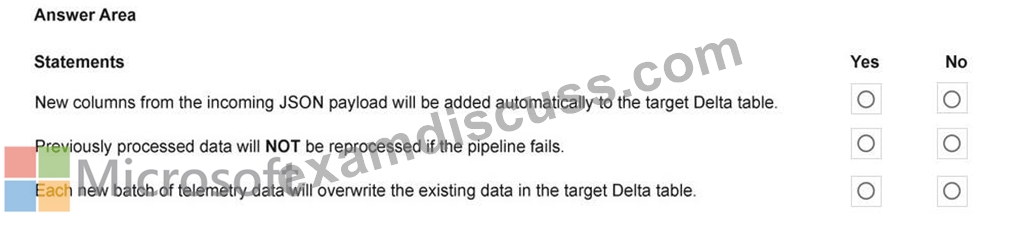
Answer:
Explanation: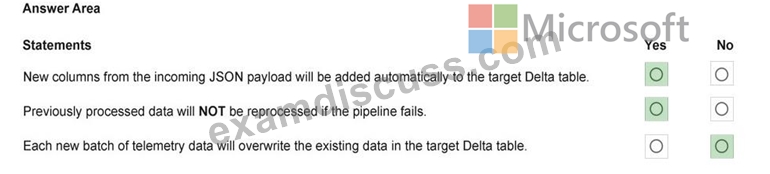
NEW QUESTION # 47
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains:
* A catalog named Finance
* A schema named Purchases in the Finance catalog
* A table named Transactions in the Purchases schema
You need to ensure that a user named finance_user can query the Transactions table. The solution must follow the principle of least privilege.
Which permission should you grant to finance_user for each object? To answer, drag the appropriate permissions to the correct objects. Each permission may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.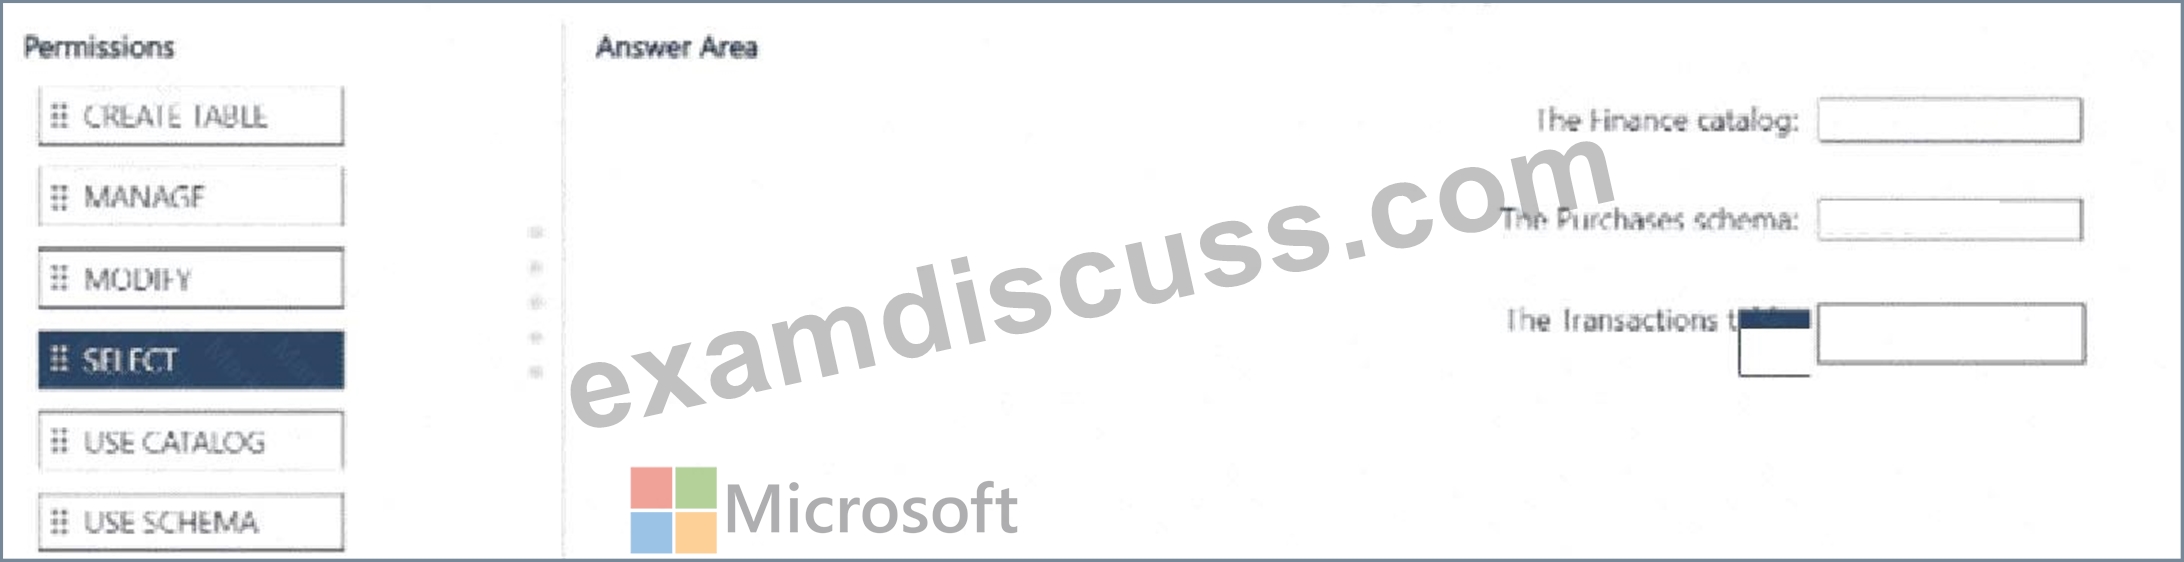
Answer:
Explanation: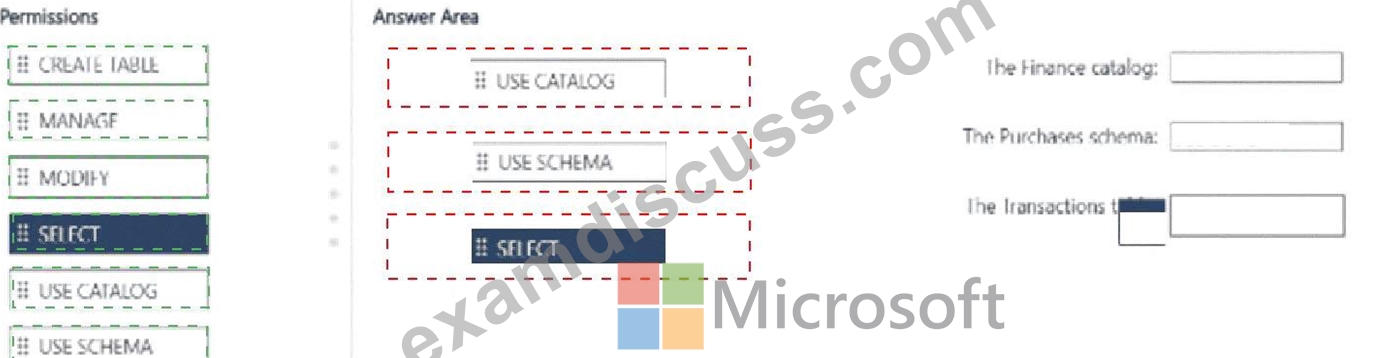
* The Finance catalog: USE CATALOG
* The Purchases schema: USE SCHEMA
* The Transactions table: SELECT
NEW QUESTION # 48
......
Before buying our DP-750 exam torrents some clients may be very cautious to buy our DP-750 test prep because they worry that we will disclose their privacy information to the third party and thus cause serious consequences. Our privacy protection is very strict and we won’t disclose the information of our clients to any person or any organization. The purpose of our product is to let the clients master the DP-750 Quiz torrent and not for other illegal purposes. Our system is well designed and any person or any organization has no access to the information of the clients. So please believe that we not only provide the best DP-750 test prep but also provide the best privacy protection. Take it easy.
DP-750 Valid Cram Materials: https://www.examdiscuss.com/Microsoft/exam/DP-750/