It will save you from the unnecessary mental hassle of wasting your valuable money and time. 2Pass4sure announces another remarkable feature to its users by giving them the Designing and Implementing Multi-Agent AI Solutions (AI-500) dumps updates until 1 year after purchasing the Designing and Implementing Multi-Agent AI Solutions (AI-500) certification exam pdf questions. It will provide them with the AI-500 Exam PDF questions updates free of charge if the AI-500 certification exam issues the latest changes. If you work hard using our top-rated, updated, and excellent Microsoft AI-500 pdf questions, nothing can refrain you from getting the Designing and Implementing Multi-Agent AI Solutions (AI-500) certificate on the maiden endeavor.
| Section | Weight | Objectives |
|---|---|---|
| Secure, govern, and deploy multi-agent solutions | 20–25% | - Deploy and maintain solutions
|
| Develop multi-agent solutions in Azure | 30–35% | - Implement agents using Azure AI services
|
| Architect multi-agent solutions | 15–20% | - Design logical architecture for multi-agent systems
|
| Evaluate, optimize, and monitor multi-agent solutions | 20–25% | - Assess performance and reliability
|
If you really want to pass the AI-500 exam faster, choosing a professional product is very important. Our AI-500 study materials can be very confident that we are the most professional in the industry's products. We are constantly improving and just want to give you the best AI-500 learning braindumps. And we have engaged for years to become a trustable study flatform for helping you pass the AI-500 exam.
NEW QUESTION # 55
You have a Microsoft Foundry multi-agent customer support solution. The solution includes an orchestrator that starts a single conversation trace when a user request arrives and can invoke two agents named Agent1 and Agent2 concurrently. Each agent can invoke Model Context Protocol (MCP)-hosted tools and dependent REST APIs.
The solution uses OpenTelemetry SDKs to emit logs, metrics, and traces via OTLP to an OpenTelemetry Collector. The solution emits the conversation ID, trace ID, and span ID for agent invocations, tool invocations, and external API calls.
You have a monitoring dashboard that includes:
* Latency
* Throughput
* Reliability
* Token usage
* Content safety triggers
* Time to First Token (TTFT)
Alert rules are configured for latency anomalies and tool invocation failures.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.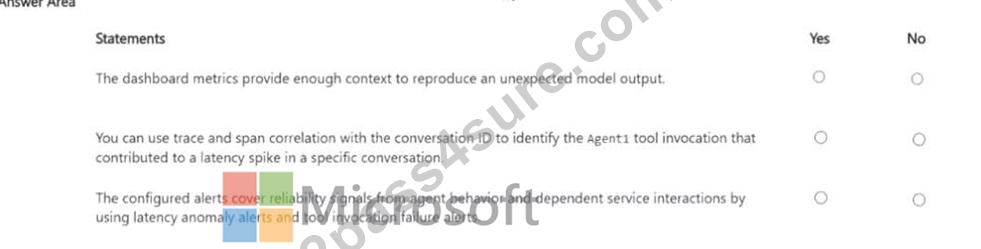
Answer:
Explanation: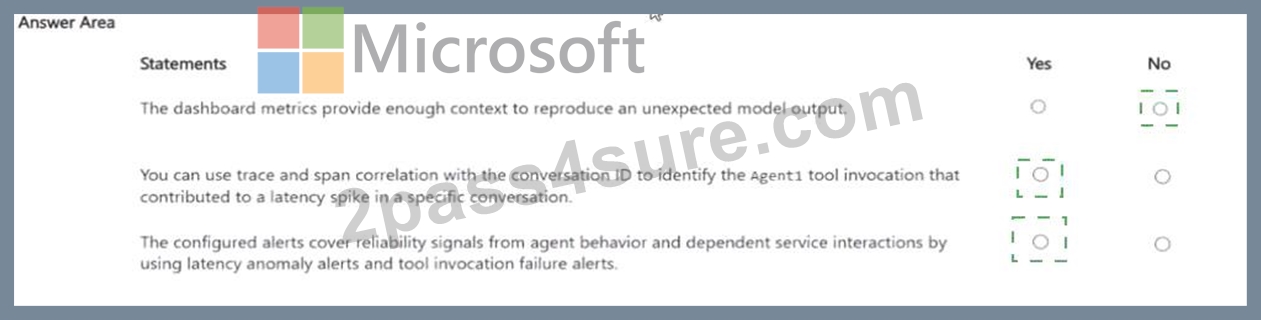
Explanation:
No / Yes / Yes
Aggregate dashboard metrics do not provide enough execution context to reproduce a specific unexpected model output, so the first statement is false. Reproduction normally requires detailed trace data such as model inputs/outputs, ordered agent spans, tool calls, and dependency results. The second statement is true because the solution emits conversation, trace, and span identifiers across agent, MCP tool, and REST API calls.
OpenTelemetry correlation can therefore isolate the Agent1 tool span that contributed to a latency spike in one conversation. The third statement is also true: latency-anomaly alerts and tool-invocation failure alerts cover important reliability signals from both agent execution and dependent service interactions. They are not the entire observability strategy, but they do address the reliability conditions described. The correct sequence is No, Yes, Yes. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Microsoft Foundry - agent tracing concepts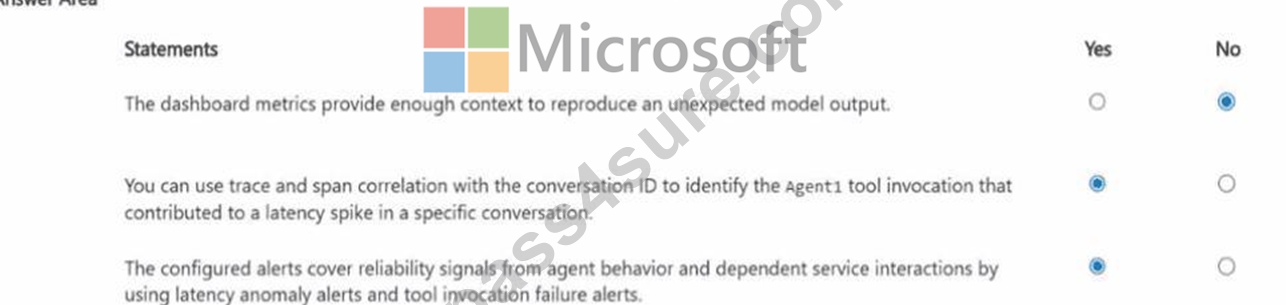
NEW QUESTION # 56
You have a Microsoft Foundry multi-agent solution that uses Microsoft Agent Framework and LangGraph.
Telemetry from the workload is sent to Application Insights.
You need to implement observability components to meet the following requirements:
* Support the investigation of user interactions across agents, models, tools, functions, and API boundaries without relying on verbose production logs.
* Produce recurring and comparable measurements of deployed response quality and safety over time.
What should you use? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.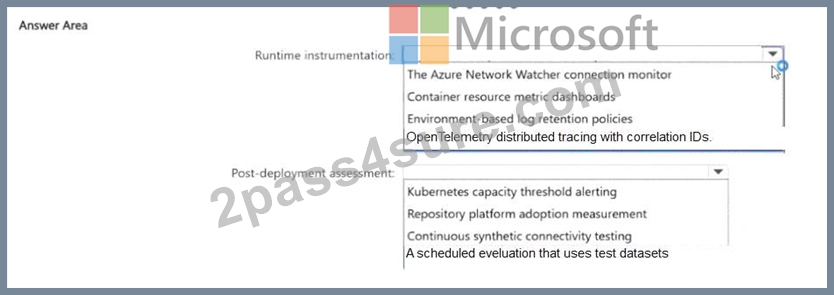
Answer:
Explanation: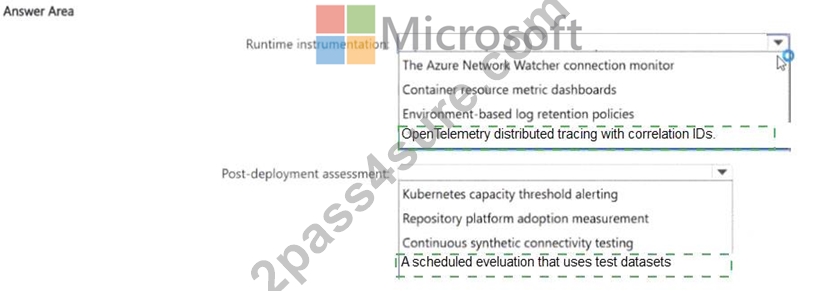
Explanation:
Runtime instrumentation: OpenTelemetry distributed tracing with correlation IDs; Post-deployment assessment: A scheduled evaluation that uses test datasets.
Distributed tracing is the correct runtime mechanism because the objective is to reconstruct a user interaction across agents, models, tools, functions, and API boundaries without relying on verbose log text. Microsoft Foundry uses OpenTelemetry-compatible traces and Application Insights so related spans can be correlated into one execution path. Correlation identifiers allow operators to isolate one conversation and inspect where latency, failures, or unexpected behavior originated. The second requirement is different: it asks for recurring, comparable measurements of deployed response quality and safety. Scheduled evaluations against stable test datasets provide that longitudinal benchmark and are more appropriate than ad hoc tracing or infrastructure- only dashboards. Together, OpenTelemetry answers "what happened in this run?" while scheduled evaluation answers "is behavior getting better or worse over time?" The selected pair therefore covers both operational diagnosis and quality regression monitoring. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry observability concepts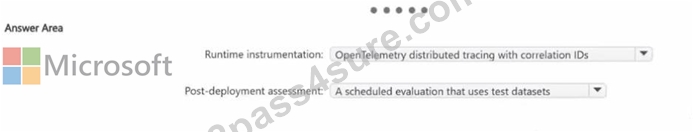
NEW QUESTION # 57
You have a Microsoft Foundry agent named Agent1.
You open Agent1 in the playground and update the instructions.
You need to run a full evaluation against the updated instructions. The solution must meet the following requirements:
* Test the changes by using a synthetic dataset.
* Ensure that the changes are available only for the development team that has access to Agent1.
What should you do first?
Answer: C
Explanation:
The instructions changed in the playground, but a full evaluation needs a stable, versioned agent definition.
Saving the changes as a new version creates an immutable snapshot that can be evaluated against a synthetic dataset while remaining inside the project for the development team. Publishing is a later lifecycle action that makes a version available to broader consumers or production endpoints and is not required for a private development evaluation. Previewing exercises the current playground configuration interactively but does not establish the versioned target needed for repeatable evaluation. Creating an evaluation before saving the new version risks evaluating the previous configuration instead of the intended update. Microsoft Foundry ' s development lifecycle separates edit, save/version, evaluate, and publish stages, so A is the correct first action. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator.
Official Microsoft reference: Microsoft Foundry agents - development lifecycle
NEW QUESTION # 58
You have a production-readiness review that includes the following Microsoft Foundry Agent Service Model Context Protocol (MCP) tool configuration, discovered MCP tool metadata, and quality-gate rules.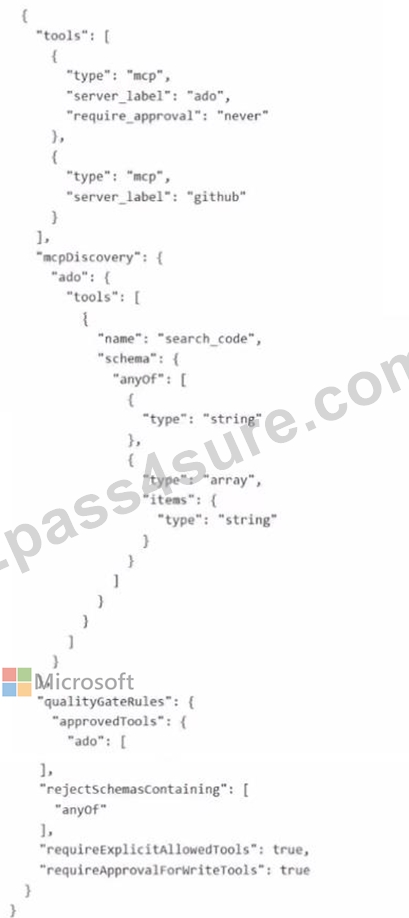
For each of the following statements, select Yes if the statement is true Otherwise, select No.
NOTE: Each correct selection is worth one point.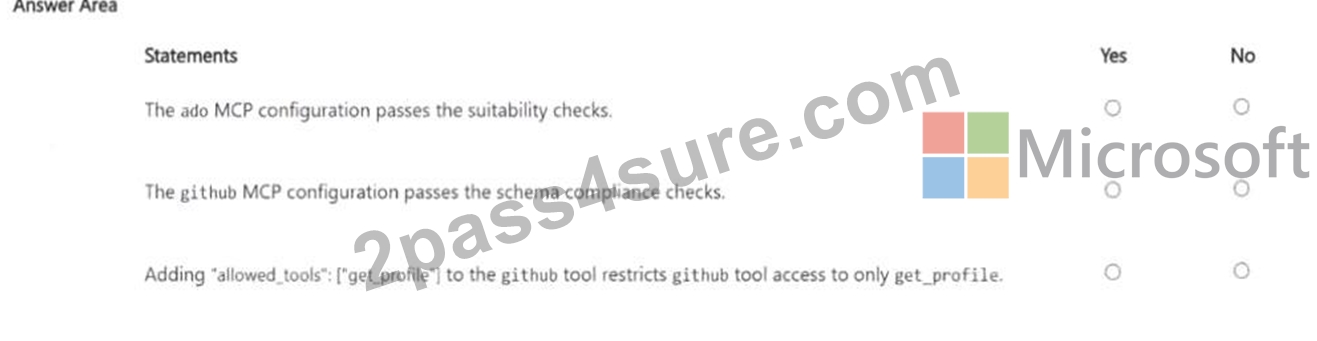
Answer:
Explanation: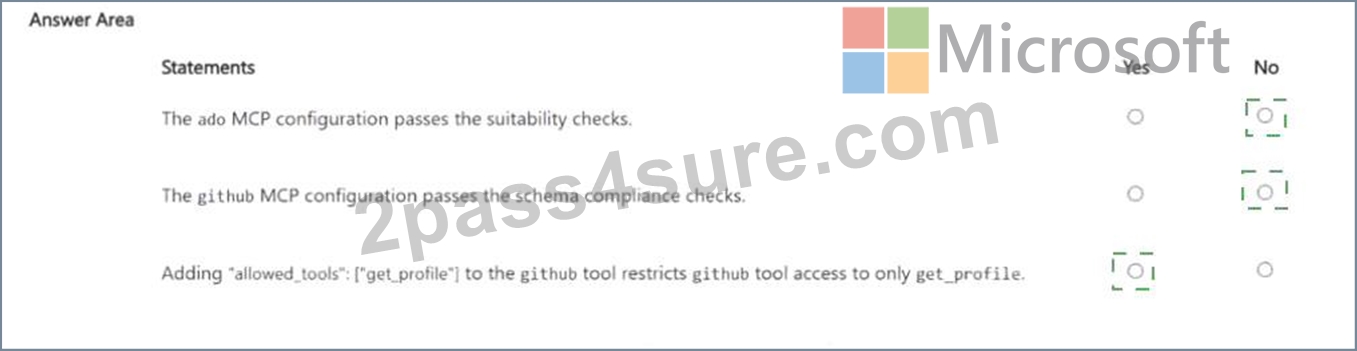
Explanation:
No / No / Yes
The ADO MCP configuration does not satisfy the stated production gate because it lacks the required allowed- tool restriction and disables approval; its discovered schema also conflicts with the gate ' s schema restrictions. The GitHub configuration likewise cannot be considered schema-compliant based on the shown metadata. The third statement, however, is true: Microsoft Foundry MCP tool configuration supports an
`allowed_tools` allowlist that limits which discovered MCP tools are exposed to the agent. Adding ` " allowed_tools " : [ " get_profile " ]` therefore restricts the GitHub MCP integration to that tool, assuming the name matches the discovered tool exactly. This control is materially stronger tha n relying on prompt instructions because excluded tools are not presented as available choices. The corrected sequence is No, No, Yes. The same configuration should be paired with auditable identity, trace, and evaluation data so reviewers can prove which principal acted, which policy was applied, and why a request was allowed or blocked. That is particularly important for production multi-agent systems with external tools.
Official Microsoft reference: Microsoft Foundry agents - Model Context Protocol tools
NEW QUESTION # 59
You have a Microsoft Foundry multi-agent solution. The solution includes a parent agent that can call an Azure logic app and delegate to two subagents.
You need to implement a review process for flagged interactions. The solution must meet the following requirements;
* Identify requests that call third-party services.
* Moderate the prompts, steps, and tool calls.
* Include a governance review.
What should you do?
Answer: C
Explanation:
The review process must cover the full sensitive interaction, including third-party calls, prompts, intermediate steps, and tool actions, and it must feed a governance review process. A centralized sensitive-use intake combined with guardrails and tracing provides the required evidence, while human reviewers must be able to approve, edit, or reject flagged interactions rather than reviewing only the final message. Content Safety alone does not provide full process governance over tool use. Routing only subagent findings or requiring approval only for the final response misses earlier third-party actions. CI/CD evaluation is important for release quality but does not control individual flagged production interactions. The source duplicated the label C for the final option; that final option should be labeled D. With that label correction, D is the best answer. From a security and governance perspective, the control should be enforced at the narrowest platform boundary that can deterministically block or constrain the action. Relying only on prompt text is weaker because the model can still be induced to behave unexpectedly.
Official Microsoft reference: AI-500 Study Guide - governance, guardrails, tracing, and HITL
NEW QUESTION # 60
......
The committed team of the 2Pass4sure is always striving hard to resolve any confusion among its users. The similarity between our Microsoft AI-500 exam questions and the real Microsoft AI-500 certification exam will amaze you. The similarity between the 2Pass4sure AI-500 pdf questions and the actual AI-500 certification exam will help you succeed in obtaining the highly desired Designing and Implementing Multi-Agent AI Solutions (AI-500) certification on the first go. You will notice the above features in the Microsoft AI-500 Web-based format too. There is no need to go through time-taking installations or agitating plugins to use this format.
AI-500 100% Exam Coverage: https://www.2pass4sure.com/Microsoft-Certified-Multi-Agent-AI-Solutions-Expert/AI-500-actual-exam-braindumps.html