Databricks-Certified-Data-Engineer-Professional Original Questions & Databricks-Certified-Data-Engineer-Professional Training Online & Databricks-Certified-Data-Engineer-Professional Dumps Torrent

P.S. Free 2026 Databricks Databricks-Certified-Data-Engineer-Professional dumps are available on Google Drive shared by DumpsKing: https://drive.google.com/open?id=1ee6VWA8sAB_4XeERzwoDVS7rIeLm4gmH
Among all marketers who actively compete to win customers, we sincerely offer help for exam candidates like you with our Databricks-Certified-Data-Engineer-Professional exam questions. To cater to the needs of exam candidates, our experts have been assiduously worked for their quality day and night. Databricks-Certified-Data-Engineer-Professional Training Materials can help you achieve personal goals about the Databricks-Certified-Data-Engineer-Professional exam successfully. So of course we received sincere feed-backs from exam candidates which are maximum benefits for us.
| Section | Weight | Objectives |
|---|
| Data Ingestion & Acquisition | 7% | - Handle incremental and batch data loads
- Ingest data from diverse sources
- Use Auto Loader and structured streaming
|
| Monitoring and Alerting | 10% | - Track data lineage and metrics
- Set up alerts and notifications
- Monitor pipeline performance and health
|
| Debugging and Deploying | 10% | - Implement CI/CD and DevOps practices
- Deploy using Asset Bundles, CLI, and APIs
- Troubleshoot and debug pipelines
|
| Ensuring Data Security and Compliance | 10% | - Secure data at rest and in transit
- Ensure data privacy and compliance
- Implement access control and permissions
|
| Data Transformation, Cleansing, and Quality | 10% | - Implement schema evolution and management
- Enforce data quality standards
- Apply data cleansing and validation rules
|
| Cost & Performance Optimisation | 13% | - Improve query and pipeline performance
- Apply cost management best practices
- Optimize compute and storage resources
|
| Data Sharing and Federation | 5% | - Manage cross-platform data access
- Use Delta Sharing for secure data sharing
- Implement Lakehouse Federation
|
| Data Governance | 7% | - Use Unity Catalog for governance
- Enforce data policies and standards
- Manage data assets and metadata
|
| Developing Code for Data Processing using Python and SQL | 22% | - Use Databricks-specific libraries and APIs
- Implement complex data processing logic
- Write efficient and maintainable code
|
| Data Modelling | 6% | - Optimize table design and partitioning
- Design Medallion Architecture
- Implement dimensional and relational models
|
>> Databricks-Certified-Data-Engineer-Professional Valid Exam Blueprint <<
Databricks-Certified-Data-Engineer-Professional Examinations Actual Questions & Databricks-Certified-Data-Engineer-Professional Mock Exam
Do you still worry about that you can’t find an ideal job and earn low wage? Do you still complaint that your working abilities can’t be recognized and you have not been promoted for a long time? You can try to obtain the Databricks-Certified-Data-Engineer-Professional certification and if you pass the exam you will have a high possibility to find a good job with a high income. If you buy our Databricks-Certified-Data-Engineer-Professional questions torrent you will pass the exam easily and successfully. Our Databricks-Certified-Data-Engineer-Professional Study Materials are compiled by experts and approved by professionals with experiences for many years. We provide 3 versions for the client to choose and free update. Different version boosts different advantage and please read the introduction of each version carefully before your purchase.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q70-Q75):
NEW QUESTION # 70
A data engineering team is implementing an append-only data pipeline using Delta Lake, and wants to ensure that data is never modified or deleted once written. Which Delta Lake feature should the data engineer enable to prevent modifications to existing data?
- A. Delta Time Travel
- B. Delta APPEND_ONLY
- C. Delta OPTIMIZE
- D. Delta VACUUM
Answer: B
Explanation:
Enabling the append-only table property enforces that data can only be inserted into the Delta table. Updates and deletes are blocked, ensuring that once data is written it is never modified or removed, which is essential for strict append-only pipeline guarantees.
NEW QUESTION # 71
A data engineer is attempting to execute the following PySpark code:
df = spark.read.table("sales")
result = df.groupBy("region").agg(sum("revenue"))
However, upon inspecting the execution plan and profiling the Spark job, they observe excessive data shuffling during the aggregation phase.
Which technique should be applied to reduce shuffling during the groupBy aggregation operation?
- A. Use coalesce() after the aggregation.
- B. Use broadcast join.
- C. Repartition by region before aggregation.
- D. Caching the DataFrame df.
Answer: C
Explanation:
Repartitioning the DataFrame by the grouping key ensures that records with the same region are colocated in the same partitions before the aggregation runs. This significantly reduces the amount of data shuffled during the groupBy operation, leading to more efficient execution.
NEW QUESTION # 72
A data engineer is running a groupBy aggregation on a massive user activity log grouped by user_id. A few users have millions of records, causing task skew and long runtimes. Which technique will fix the skew in this aggregation?
- A. Filter out the skewed users before the aggregation.
- B. Increase the Spark driver memory and retry.
- C. Use reduceByKey instead of groupBy to avoid shuffles.
- D. Use salting by adding a random prefix to skewed keys before aggregation, then aggregate again after removing the prefix.
Answer: D
Explanation:
Salting distributes records for heavily skewed keys across multiple partitions by adding a random prefix, which balances task execution during the aggregation. A second aggregation after removing the prefix correctly recombines the partial results, eliminating skew-related bottlenecks without losing accuracy.
NEW QUESTION # 73
Incorporating unit tests into a PySpark application requires upfront attention to the design of your jobs, or a potentially significant refactoring of existing code.
Which statement describes a main benefit that offset this additional effort?
- A. Troubleshooting is easier since all steps are isolated and tested individually
- B. Yields faster deployment and execution times
- C. Ensures that all steps interact correctly to achieve the desired end result
- D. Improves the quality of your data
- E. Validates a complete use case of your application
Answer: A
Explanation:
Unit tests are small, isolated tests that are used to check specific parts of the code, such as functions or classes.
NEW QUESTION # 74
A data engineer wants to refactor the following DLT code, which includes multiple table definitions with very similar code.
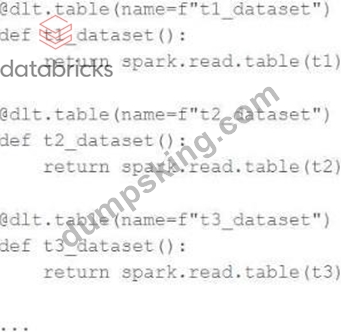
In an attempt to programmatically create these tables using a parameterized table definition, the data engineer writes the following code.
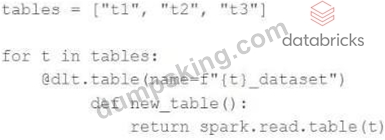
The pipeline runs an update with this refactored code, but generates a different DAG showing incorrect configuration values for these tables.
How can the data engineer fix this?
- A. Wrap the for loop inside another table definition, using generalized names and properties to replace with those from the inner table definition.
- B. Load the configuration values for these tables from a separate file, located at a path provided by a pipeline parameter.
- C. Convert the list of configuration values to a dictionary of table settings, using table names as keys.
- D. Move the table definition into a separate function, and make calls to this function using different input parameters inside the for loop.
Answer: D
Explanation:
In the provided refactored code, the for loop dynamically attempts to define multiple tables, but the use of a loop within the DLT (@dlt.table) decorator does not work properly because it results in a single function reference being overwritten for each iteration. This leads to an incorrect DAG because all the table definitions end up pointing to the last iteration of the loop.
NEW QUESTION # 75
......
There is no exaggeration that you can be confident about your coming exam just after studying with our Databricks-Certified-Data-Engineer-Professional preparation questions for 20 to 30 hours. Tens of thousands of our customers have benefited from our Databricks-Certified-Data-Engineer-Professional Exam Materials and passed their exams with ease. The data showed that our high pass rate is unbelievably 98% to 100%. Without doubt, your success is 100% guaranteed with our Databricks-Certified-Data-Engineer-Professional training guide.
Databricks-Certified-Data-Engineer-Professional Examinations Actual Questions: https://www.dumpsking.com/Databricks-Certified-Data-Engineer-Professional-testking-dumps.html
- Test Databricks-Certified-Data-Engineer-Professional King 🍑 Reliable Databricks-Certified-Data-Engineer-Professional Braindumps Ebook 🐶 Databricks-Certified-Data-Engineer-Professional Cert Exam ↩ Download ▶ Databricks-Certified-Data-Engineer-Professional ◀ for free by simply entering ➽ www.troytecdumps.com 🢪 website 🙎Databricks-Certified-Data-Engineer-Professional Instant Download
- Valid Databricks-Certified-Data-Engineer-Professional Exam Forum 💜 Official Databricks-Certified-Data-Engineer-Professional Study Guide 🍜 Databricks-Certified-Data-Engineer-Professional Latest Exam Price 👆 Open website 《 www.pdfvce.com 》 and search for ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ for free download 🔰Databricks-Certified-Data-Engineer-Professional Latest Exam Tips
- Databricks-Certified-Data-Engineer-Professional Dumps PDF: Databricks Certified Data Engineer Professional Exam - Databricks-Certified-Data-Engineer-Professional Test Questions - Databricks Certified Data Engineer Professional Exam Dumps Torrent 🦅 Open ▶ www.pdfdumps.com ◀ and search for ➡ Databricks-Certified-Data-Engineer-Professional ️⬅️ to download exam materials for free 🥼Databricks-Certified-Data-Engineer-Professional Latest Exam Price
- Update Databricks-Certified-Data-Engineer-Professional Exam Practice Questions keeps Latest Information of Databricks-Certified-Data-Engineer-Professional ⚾ Enter ➡ www.pdfvce.com ️⬅️ and search for ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ to download for free ♿Relevant Databricks-Certified-Data-Engineer-Professional Questions
- Pass Exam Without Hardships With Databricks Databricks-Certified-Data-Engineer-Professional Exam Questions 🔂 Search for { Databricks-Certified-Data-Engineer-Professional } and download it for free on ➤ www.testkingpass.com ⮘ website 🚹Official Databricks-Certified-Data-Engineer-Professional Study Guide
- Databricks-Certified-Data-Engineer-Professional Latest Exam Tips 🍈 Free Databricks-Certified-Data-Engineer-Professional Exam Questions 🌜 Databricks-Certified-Data-Engineer-Professional Latest Exam Tips ✍ Search for { Databricks-Certified-Data-Engineer-Professional } and obtain a free download on ▛ www.pdfvce.com ▟ 🤒Databricks-Certified-Data-Engineer-Professional Cert Exam
- Databricks-Certified-Data-Engineer-Professional Real Dump 🕒 Relevant Databricks-Certified-Data-Engineer-Professional Questions 👛 Official Databricks-Certified-Data-Engineer-Professional Study Guide 🎈 Immediately open { www.prep4sures.top } and search for ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ to obtain a free download 🐟Databricks-Certified-Data-Engineer-Professional Latest Exam Price
- Databricks-Certified-Data-Engineer-Professional Exam Preparation - Databricks-Certified-Data-Engineer-Professional Training Materials - Databricks-Certified-Data-Engineer-Professional Study Guide 🍇 Open ✔ www.pdfvce.com ️✔️ and search for ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ to download exam materials for free 😦Test Databricks-Certified-Data-Engineer-Professional King
- Databricks-Certified-Data-Engineer-Professional Exam Discount 🐮 Reliable Databricks-Certified-Data-Engineer-Professional Braindumps Ebook 😕 Official Databricks-Certified-Data-Engineer-Professional Study Guide 😐 Search for 【 Databricks-Certified-Data-Engineer-Professional 】 and obtain a free download on ➥ www.prepawayexam.com 🡄 📦Databricks-Certified-Data-Engineer-Professional Latest Exam Price
- Relevant Databricks-Certified-Data-Engineer-Professional Questions 🍯 Study Databricks-Certified-Data-Engineer-Professional Demo 🤷 Databricks-Certified-Data-Engineer-Professional Cert Exam 🗯 Search for ➤ Databricks-Certified-Data-Engineer-Professional ⮘ and obtain a free download on ➽ www.pdfvce.com 🢪 👮Databricks-Certified-Data-Engineer-Professional Latest Exam Tips
- 2026 Databricks-Certified-Data-Engineer-Professional Valid Exam Blueprint 100% Pass | Efficient Databricks-Certified-Data-Engineer-Professional Examinations Actual Questions: Databricks Certified Data Engineer Professional Exam 🤎 Search for 《 Databricks-Certified-Data-Engineer-Professional 》 on “ www.dumpsquestion.com ” immediately to obtain a free download 🎧Databricks-Certified-Data-Engineer-Professional Real Dump
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, kaeuchi.jp, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, customerscomm.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BONUS!!! Download part of DumpsKing Databricks-Certified-Data-Engineer-Professional dumps for free: https://drive.google.com/open?id=1ee6VWA8sAB_4XeERzwoDVS7rIeLm4gmH