BONUS!!! Download part of BootcampPDF SPS-C01 dumps for free: https://drive.google.com/open?id=1ngBR7-po8PwVEzMtUErIcXuBgv8R1gKw
We are all well aware that a major problem in the industry is that there is a lack of quality study materials. Our SPS-C01 braindumps provides you everything you will need to take a certification examination. Details are researched and produced by SPS-C01 Dumps Experts who are constantly using industry experience to produce precise, logical verify for the test. You may get SPS-C01 exam dumps from different web sites or books, but logic is the key.
| Section | Weight | Objectives |
|---|---|---|
| Snowpark API for Python | 30% | - Working with Semi-structured data - Establishing connections and session management - DataFrame creation and manipulation - User-Defined Functions (UDFs) and Stored Procedures - Reading and writing data |
| Snowpark Concepts | 15% | - Stored procedures and conditional logic - Transformations vs. Actions - Snowpark architecture and core concepts - Client-side vs. Server-side execution - Snowpark DataFrames and query plans - Snowpark Sessions and connection management |
| Data Transformations and DataFrame Operations | 35% | - Using built-in functions - Filtering, Aggregating, and Joining DataFrames - Persisting transformed data - Complex data pipelines - Window functions |
| Performance Optimization and Best Practices | 20% | - Caching strategies - Minimizing data transfer - Vectorized UDFs - Debugging and explain plans - Query pushdown and optimization - Warehouse sizing for Snowpark |
>> Verified SPS-C01 Answers <<
Maybe you will find that the number of its SPS-C01 test questions is several times of the traditional problem set, which basically covers all the knowledge points to be mastered in the exam or maybe you will find the number is the same with the real exam questions. You only need to review according to the content of our SPS-C01 practice quiz, no need to refer to other materials. With the help of our SPS-C01 study materials, your preparation process will be relaxed and pleasant.
NEW QUESTION # 353
You are developing a Snowpark stored procedure in Python that utilizes the 'requests' library to fetch data from an external API. Your Snowflake account is configured to use Anaconda packages. You encounter an error indicating that the 'requests' library is not found. Which of the following steps are MOST effective in ensuring the 'requests' library is available to your stored procedure?
Answer: D
Explanation:
The 'packages' argument in the 'CREATE OR REPLACE PROCEDURE statement is the correct way to specify dependencies on Anaconda packages. Snowflake will automatically resolve and make these packages available to the stored procedure. Option B is incomplete; while Anaconda integration is necessary, it doesn't automatically import the library. Options A, C and E are incorrect and not best practices.
NEW QUESTION # 354
You are working with a Snowpark DataFrame containing product review data'. The DataFrame has a 'review_text' column containing unstructured text reviews. Your task is to perform sentiment analysis on these reviews using Snowpark for Python. However, you are restricted to using only Snowpark built-in functions and UDFs; you cannot use external libraries like NLTK or TextBlob directly within your Snowpark code. Given this contraint, what is a valid approach to enrich your dataframe?
Answer: B,C,D,E
Explanation:
Options A, B, D and E are valid approaches given the constraints, since the task says enrich your dataframe, so we need some final column containing a score. Option A: The microservice approach, using 'call_udf and external function is a robust and scalable solution. It enables to leverage complex sentiment analysis models without directly integrating them into Snowflake. Option B: The Java UDF allows leveraging existing Java-based NLP libraries, extending the capabilities of Snowpark for sentiment analysis while adhering to the constraint of not using external Python libraries directly. Option D: Snowflake's External Functions are designed for calling external services. Passing 'review_text as an argument to pre-trained sentiment analysis model, and receive a result. Option E: This solution utilizes regular expression and UDFs. To search for sentiment indicative keywords and phrases and assigning the score using 'when' statements. Option C: This approach is the least efficient because it requires maintaining an internal vocabulary, which can be less accurate and harder to update compared to using pre-trained models or external services and it also does not generate a final new column to enrich the dataframe.
NEW QUESTION # 355
You have a Snowflake table 'raw_events' containing JSON data in a VARIANT column named 'event_data'. This column contains nested JSON objects representing user activity on a website. You need to extract specific nested values and load them into a new Snowflake table 'user_activity' with columns 'event_type' , and 'timestamp'. Which of the following Snowpark code snippets is the MOST efficient and correct way to achieve this, assuming you want to minimize data transfer and optimize performance? Consider the potential for null values within the JSON.





Answer: E
Explanation:
Option C is the most efficient because it uses Snowflake's native JSON path notation (using 'f) directly within the 'select' statement, which is optimized for Snowflake's internal JSON handling. The other options use function calls ('get' , 'col'), which can introduce overhead. Furthermore, the code uses try_to_timestamp() to avoid errors due to null values
NEW QUESTION # 356
You are tasked with operationalizing a Snowpark Python UDF for batch scoring of a large dataset. The UDF takes a set of feature columns and returns a prediction. You want to optimize performance and resource utilization. Select all the strategies that would effectively improve the operational efficiency and scalability of your UDF execution.
Answer: A,B,D
Explanation:
Partitioning the input DataFrame (A) allows Snowflake to distribute the UDF execution across multiple nodes, improving parallelism. The 'vectorized' argument (B) enables the UDF to process data in batches, reducing per-row overhead. Implementing retry logic (D) improves resilience when calling external APIs. is not configurable. Using a fixed 'X-Large' warehouse (E) is not cost-effective; right- sizing the warehouse based on workload is crucial.
NEW QUESTION # 357
Consider the following Snowpark Python code snippet intended to operationalize a stored procedure: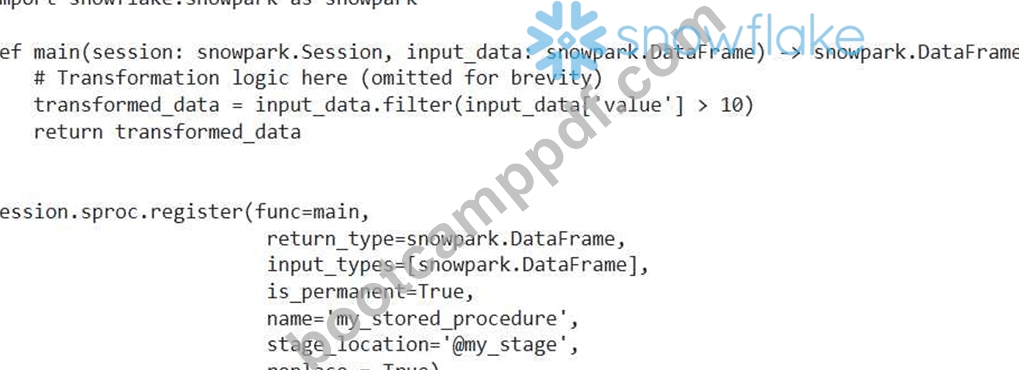
This code results in an error during registration. Which of the following actions would be MOST appropriate to fix the registration issue and ensure the stored procedure can be successfully operationalized?
Answer: C
Explanation:
Option C is the correct solution. The 'session.sproc.registefl method should be called outside of the 'main' function definition. The registration process is a separate step from the function definition itself. The 'sproc.register' will take the function definition and create an object in Snowflake. Since this must be outside of the function it needs to be outside the main function. All other options would not solve the error with the registration.
NEW QUESTION # 358
......
We provide varied functions to help the learners learn our SPS-C01 study materials and prepare for the exam. The SPS-C01 self-learning and self-evaluation functions help the learners check their learning results and the statistics. The timing function of our SPS-C01 guide questions help them adjust their speeds to answer the questions and the function of stimulating the exam can help the learners adapt themselves to the atmosphere and pace of the exam. Thus the learners can master our SPS-C01 Practice Engine fast, conveniently and efficiently and pass the SPS-C01 easily.
Valid SPS-C01 Test Sims: https://www.bootcamppdf.com/SPS-C01_exam-dumps.html
BONUS!!! Download part of BootcampPDF SPS-C01 dumps for free: https://drive.google.com/open?id=1ngBR7-po8PwVEzMtUErIcXuBgv8R1gKw