Our DP-750 study guide and training materials of BraindumpsPrep are summarized by experienced IT experts, who combine the DP-750 original questions and real answers. Due to our professional team, the passing rate of DP-750 test of our BraindumpsPrep is the highest in the DP-750 exam training. So, choosing BraindumpsPrep, choosing success.
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Prepare and process data | 30–35% | - Ingest and transform data
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
| Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
>> New DP-750 Test Question <<
People who appear in the test of the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification face the issue of not finding up-to-date and real exam questions. BraindumpsPrep is here to resolve all of your problems with its actual and latest Microsoft DP-750 Questions. You can successfully get prepared for the DP-750 examination in a short time with the aid of these Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam questions.
NEW QUESTION # 34
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to create an external volume named Volume1 in an existing schema. Volume1 must expose files from an Azure Storage container. The solution must meet the following requirements:
- Ensure that authentication does NOT require storing credentials in
Databricks.
- Ensure that users can access the files, but NOT modify the files.
- Follow the principle of least privilege.
Which type of authentication should you configure, and which permission should you grant to the users? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.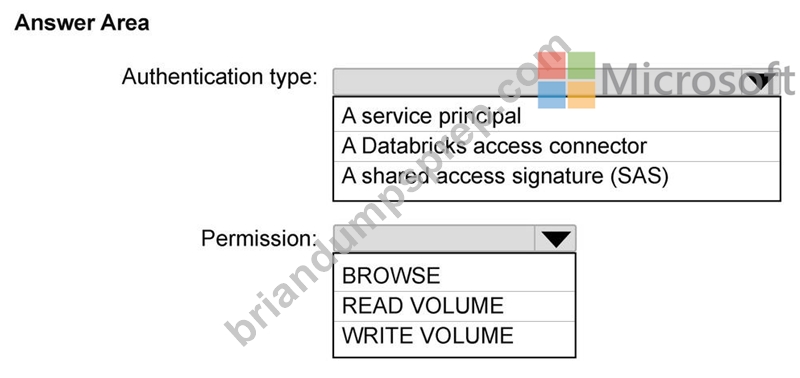
Answer:
Explanation: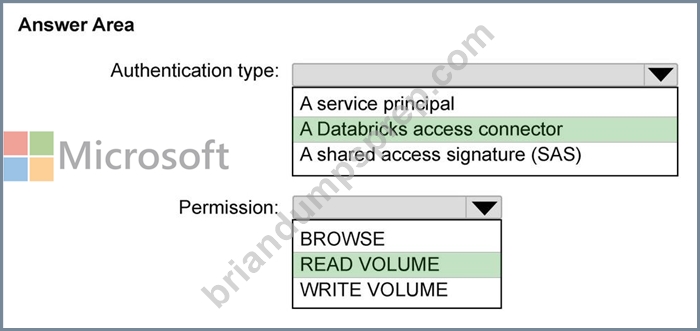
NEW QUESTION # 35
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Sales. Sales stores transaction data and contains the following columns:
* transactionjd (string)
* transaction date (date)
* amount (decimal)
You need to implement the following data quality requirements by using table-level data quality enforcement:
* amount must be greater than 0.
* transaction id must never be null.
* Invalid records must be rejected when data is written to the Sales table.
What should you do?
Answer: C
Explanation:
The correct answer is D - a NOT NULL constraint on transaction_id and a CHECK constraint on amount.
Delta Lake table constraints are enforced at write time by the Delta engine itself. A NOT NULL constraint rejects any INSERT or UPDATE that would place a null in transaction_id. A CHECK constraint with amount
> 0 rejects any row where amount is zero or negative. Combined, they implement exactly the stated quality rules: bad rows are rejected when data is written, not filtered away at read time.
Options A and C (SELECT with WHERE / views) are read-time constructs - they don ' t prevent invalid data from entering the table. A clever pipeline bypass could write directly to the table and skip the view entirely. Option B (row-level security with WHERE conditions) is an access-control feature for restricting which rows users see, not for enforcing data quality on writes. Table constraints are the only mechanism that genuinely blocks bad data at the storage layer.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-constraints
NEW QUESTION # 36
You have an Azure Databricks workspace named Workspace1 that contains a takehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
* The schemas and tables can be queried in Databricks.
* The schemas and tables appear alongside other Unity Catalog objects.
* The data is NOT copied into Databricks-managed storage.
Solution: You create a new native catalog in Unity Catalog. Does this meet the goal?
Answer: A
Explanation:
The correct answer is B - No.
A native catalog in Unity Catalog is a standard Databricks-managed catalog. Creating one provisions a metadata namespace inside Unity Catalog, but it has no connection whatsoever to DB1 or any external SQL Server database. There is no mechanism to point a native catalog at an external database - it simply doesn't serve that purpose.
The requirement is to expose an external SQL Server's schemas and tables inside Unity Catalog without copying the data. That requires a foreign catalog, which is created through Lakehouse Federation using a registered connection to the external database. A foreign catalog acts as a read-only, virtual mirror of the external database - queries run against the live external data in place.
Creating a native catalog and then trying to manually recreate DB1's structure inside it would involve copying all the data, violating the 'data is NOT copied' requirement.
Reference: https://learn.microsoft.com/en-us/azure/databricks/query-federation/lakehouse-federation
NEW QUESTION # 37
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two Delta tables named Table1 and Table2 of the same data type.
Table1 contains a column named Columnl. Table2 contains a column named Column2. You run the following query.
SELECT Column1
FROM Table1
GROUP BY Column1
HAVING COUNT(") > 1
INTERSECT
SELECT C0lumn2
FROM Table2
GROUP BY Column2
HAVING COUNT(') > 1;
What occurs when you run the query?
Answer: C
Explanation:
The correct answer is B - values appear in both tables more than once.
Reading the query from the inside out: each subquery identifies values that appear more than once within their own table. The first subquery returns Column1 values that are duplicated in Table1. The second returns Column2 values that are duplicated in Table2. INTERSECT then returns only the values that appear in both result sets - meaning values that are duplicated in Table1 AND also duplicated in Table2.
Option A describes a UNION result (values in either table), not INTERSECT. Option C only considers duplicates in Table1, ignoring the Table2 condition - that would be the first subquery in isolation. Option D describes values exclusive to Table2 (EXCEPT or MINUS), the opposite of INTERSECT's requirement that values appear in both sets.
INTERSECT always requires membership in both operands - that's its fundamental definition in standard SQL.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/sql-ref-syntax-qry-select- setops
NEW QUESTION # 38
You have an Azure Databricks workspace that contains the objects shown in the following table.
Name | Type
Catalog1 | Catalog
Schema1 | Schema
Sales1 | Table
Notebook1 | Notebook
Space1 | AI/BI Genie space
Users often use the following words to refer to a sale: transaction, event, order, and invoice.
You need to create a knowledge store. The solution must ensure that when the users use any of the words in Space1, Genie queries the Sales1 table. Any other Genie spaces must remain unaffected.
To which object should you add the instructions?
Answer: A
Explanation:
The instructions must be added to Space1 because a Genie knowledge store is scoped to the individual Genie space, now called a Genie Agent. Adding synonyms and business-language instructions there teaches Space1 that "transaction," "event," "order," and "invoice" refer to sales information in Sales1. The configuration affects only that Genie space, satisfying the requirement that other spaces remain unchanged. Adding instructions to Sales1 or Schema1 would modify shared Unity Catalog metadata and could affect other consumers of those objects. Notebook1 is unrelated to the semantic instructions used by Genie when converting natural-language questions into SQL. Genie knowledge stores contain space-specific definitions, synonyms, join relationships, SQL expressions, and prompt-matching guidance without changing the underlying Unity Catalog objects. Microsoft Learn
NEW QUESTION # 39
......
Additionally, all operating systems also support this format. The third format is the desktop DP-750 Practice Exam software. It is ideal for users who prefer offline Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam practice. This format is supported by Windows computers and laptops. You can easily install this software in your system to use it anytime to prepare for the examination.
DP-750 Instant Discount: https://www.briandumpsprep.com/DP-750-prep-exam-braindumps.html