P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by ITExamSimulator: https://drive.google.com/open?id=18mbWtUStkTbNUsvHGQP22BI-zpvT4Be7
Our website focus on helping candidates pass Snowflake certification exams with our Valid SPS-C01 Practice Questions and detailed test answers. The most reliable SPS-C01 dumps pdf are written by our professional IT experts who have rich experience in actual test. And you will be enjoyed one-year free updating after you make payment.
| Section | Objectives |
|---|---|
| Topic 1: DataFrame Operations and Data Processing | - Data transformation workflows
|
| Topic 2: Testing, Debugging, and Deployment | - Production readiness
|
| Topic 3: Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Topic 4: Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Topic 5: User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Topic 6: Data Engineering with Snowpark | - Pipeline development
|
The learning material of ITExamSimulator is in three different formats so the students can take full benefit from it and use it anywhere anytime while preparing for Snowflake Certified SnowPro Specialty - Snowpark exam questions. The Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) guarantees its customers that they will pass the Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) certification exams in a single try if they prepare with our product and if they fail to do it so then they can reclaim their money back according to terms and conditions.
NEW QUESTION # 147
You have a Python function, 'calculate metrics(df: snowpark.DataFrame, metric name: str) -> snowpark.DataFrame', that calculates various metrics on a Snowpark DataFrame. You want to deploy this function as a stored procedure in Snowflake. You need to ensure that the stored procedure has appropriate permissions to read data from a table named 'customer data' and write results to a table named 'metrics_table'. Which of the following steps are necessary to achieve this, assuming you are using the 'session.sproc.register' method?
Answer: B,C,D
Explanation:
Options B, C, and D are correct. B is required to give the stored procedure permissions to read and write data to the appropriate tables. C: Making the SP permanent allows you to grant ownership to a specific role. D: The packages argument is essential for including any external Python dependencies needed by the function. Option A provides access to the database and schemas but does not grant access to the tables themselves. Option E provides a way to pass files that need to be used inside the function.
NEW QUESTION # 148
You are using Snowpark in Python within a Jupyter Notebook environment to analyze sales data'. You've established a connection to Snowflake and loaded your data into a Snowpark DataFrame named 'sales ff. You need to calculate the cumulative sales for each product category over time. The 'sales_df' DataFrame has columns 'SALE DATE' (DATE), 'PRODUCT CATEGORY' (VARCHAR), and 'SALE AMOUNT' (NUMBER). Which of the following approaches, or combination of approaches, will correctly calculate the cumulative sales while optimizing for Snowflake's performance and scalability? (Select all that apply)
Answer: A,B,D
Explanation:
Options A, C, and E are correct. Option A utilizes Snowpark's DataFrame transformations with window functions, which are optimized for Snowflake's engine and can efficiently handle large datasets. This leverages Snowflake's parallel processing capabilities. Option C involves creating a stored procedure within Snowflake. This approach pushes the computation to the Snowflake server, potentially improving performance, especially if the cumulative sales calculation is complex. This also benefits from Snowflake's optimization capabilities. Option E executes a SQL query with a window function that's optimized. Option B is incorrect because iterating through rows in a Jupyter Notebook will be extremely slow and inefficient for large datasets. It defeats the purpose of using Snowpark for distributed data processing. Calculating cumulative sales this way doesn't leverage Snowflake's capabilities. Option D is partially correct in that it orders the data, but using a UDF for cumulative sum calculation will likely be less efficient than using native window functions within Snowflake.
NEW QUESTION # 149
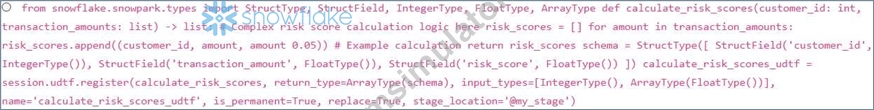
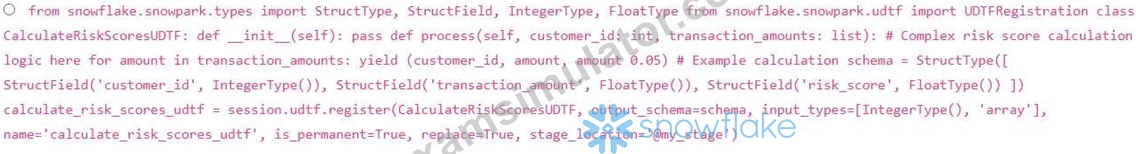
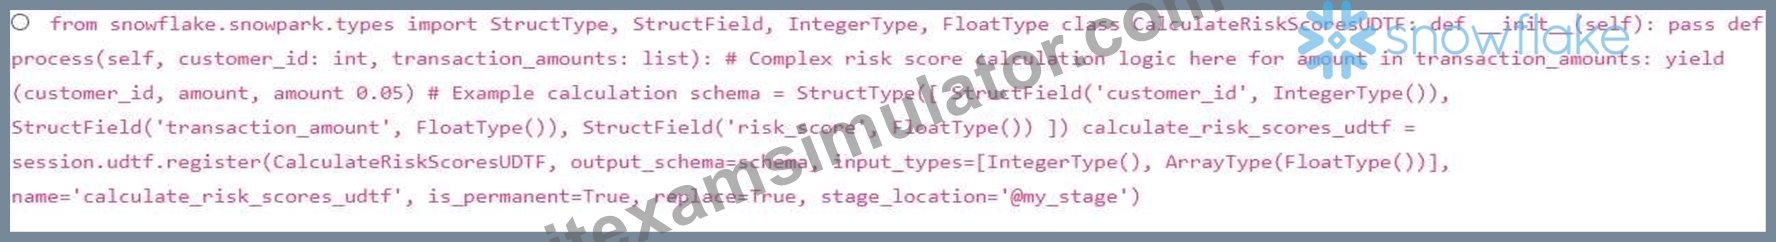
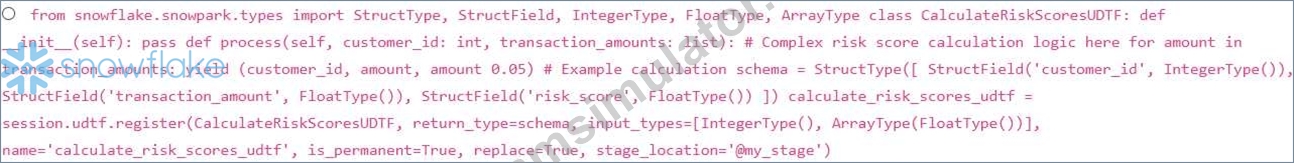
You have developed a Python function that performs complex data transformation on customer data'. You want to operationalize this function as a UDTF in Snowpark to process large datasets efficiently. The function takes a customer ID and a list of transaction amounts as input and returns a table with calculated risk scores for each transaction. Which of the following code snippets correctly defines and registers this UDTF in Snowpark, ensuring proper type handling and scalability?
Answer: C
Explanation:
Options B and C correctly defines the UDTF.Option B uses return_type and option C uses output_schema, both work. Option A is incorrect because a UDTF needs to be defined as a class with a 'process' method that yields rows, not as a function that returns a list. Option D uses an incorrect way to specify ArrayType ('array') . The other options are either syntactically incorrect or do not follow the correct UDTF definition pattern.
NEW QUESTION # 150
You have a Snowpark Python application that performs several data transformations. You need to implement error handling to catch exceptions during DataFrame operations and log them to a Snowflake table named 'error _ log'. You also need to ensure that if any exception occurs, the application continues to run and processes the remaining data. Which of the following approaches (or combination of approaches) would be MOST suitable?
Answer: C,D
Explanation:
Options B and C, when combined, provide the most robust error handling. Wrapping individual DataFrame operations in try-except blocks (B) allows you to catch specific exceptions and log them appropriately, preventing a single error from crashing the entire application. Implementing a UDF with error handling (C) encapsulates complex logic and allows you to return both processed data and error messages, making it easier to identify and address issues. A global try-except block (A) might catch errors, but it doesn't provide granular control or context. Relying solely on Snowflake's built-in mechanisms (D) is insufficient for custom error logging and continuing execution. While a Snowpark logging API (E) would be ideal, such an API doesn't currently exist and relies on an assumption.
NEW QUESTION # 151
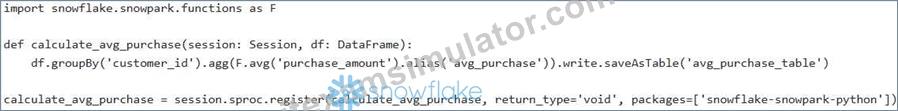
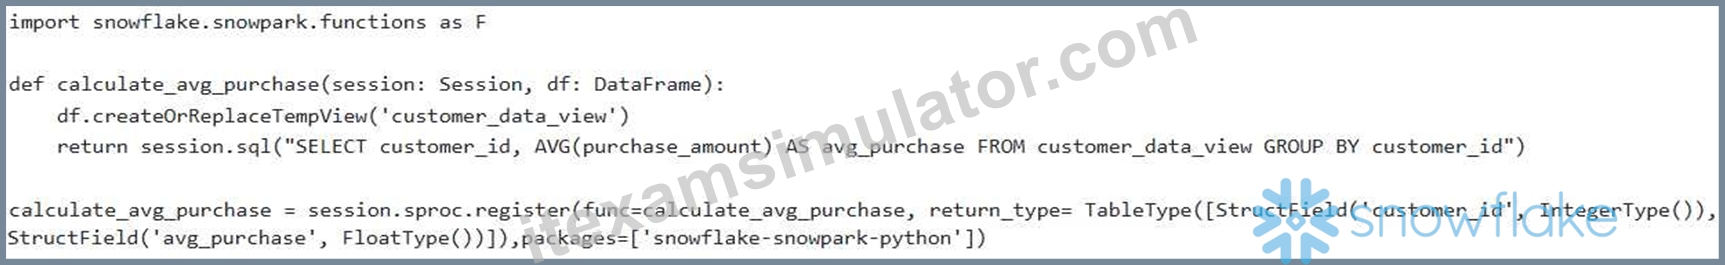
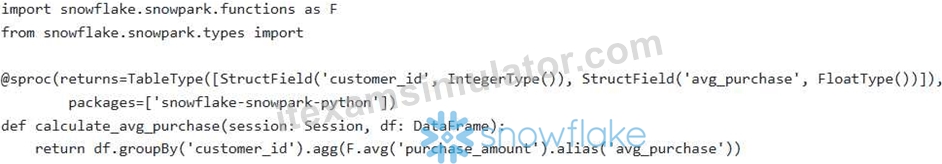
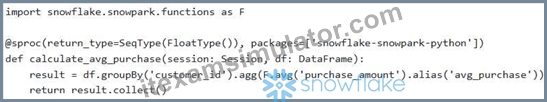
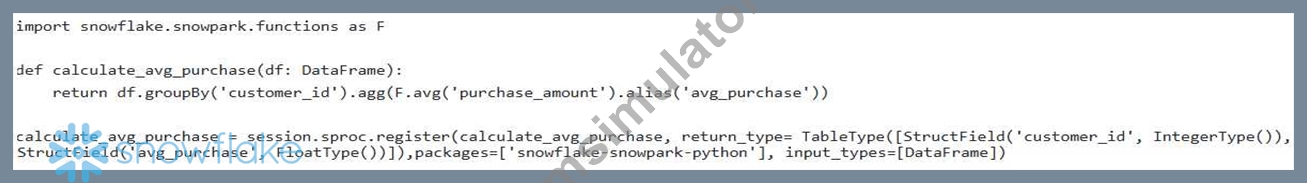
You have a Snowpark DataFrame named and want to create a stored procedure that calculates the average purchase amount for each customer. The stored procedure should accept the DataFrame as input, perform the aggregation, and return a new DataFrame with the results. Which of the following code snippets BEST demonstrates how to correctly define and deploy this stored procedure?
Answer: E
Explanation:
Option E is the most correct. It correctly registers the stored procedure using 'session.sproc.register' with the correct return type annotation for a DataFrame (using TableType and StructFields) and explicitly declares the input type to be DataFrame using 'input_types' parameter in registration. Option A uses the '@sproc' decorator which is the older API (still valid, but less explicit). Option B uses session.sql which is not appropriate for creating DataFrame based stored procedures. Option C is not correct because the return type SeqType(FloatType()) expects a sequence of float types instead of a DataFrame structure. Option D writes the result to a table, which is not the defined requirement to return a DataFrame.
NEW QUESTION # 152
......
The study material is made by professionals while thinking about our users. We have made the product user-friendly so it will be an easy-to-use learning material. We even guarantee our users that if they couldn't pass the Snowflake SPS-C01 Certification Exam on the first try with their efforts, they can claim a full refund of their payment from us (terms and conditions apply).
Exam SPS-C01 Success: https://www.itexamsimulator.com/SPS-C01-brain-dumps.html
BONUS!!! Download part of ITExamSimulator SPS-C01 dumps for free: https://drive.google.com/open?id=18mbWtUStkTbNUsvHGQP22BI-zpvT4Be7