DOWNLOAD the newest VCETorrent CT-AI PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1IspgU19uOrL1rv-R3UbtnN3NP4H0hLyg
Knowledge of the CT-AI real study guide contains are very comprehensive, not only have the function of online learning, also can help the user to leak fill a vacancy, let those who deal with qualification exam users can easily and efficient use of the CT-AI question guide. By visit our website, the user can obtain an experimental demonstration, free after the user experience can choose the most appropriate and most favorite CT-AI Exam Questions download. Users can not only learn new knowledge, can also apply theory into the CT-AI actual problem, so to grasp the opportunity!
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
| Topic 6 |
|
| Topic 7 |
|
Here, the VCETorrent empathizes with them for the extreme frustration they undergo due to not finding updated and actual ISTQB CT-AI exam dumps. It helps them by providing the exceptional ISTQB CT-AI Questions to get the prestigious ISTQB CT-AI certificate.
NEW QUESTION # 74
A mobile app start-up company is implementing an AI-based chat assistant for e-commerce customers. In the process of planning the testing, the team realizes that the specifications are insufficient.
Which testing approach should be used to test this system?
Answer: B
NEW QUESTION # 75
Upon testing a model used to detect rotten tomatoes, the following data was observed by the test engineer, based on certain number of tomato images.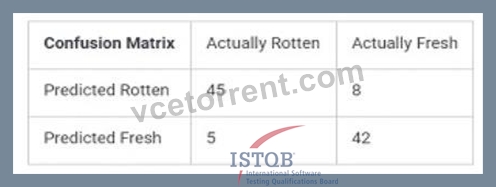
For this confusion matrix which combinations of values of accuracy, recall, and specificity respectively is CORRECT?
SELECT ONE OPTION
Answer: B
Explanation:
To calculate the accuracy, recall, and specificity from the confusion matrix provided, we use the following formulas:
* Confusion Matrix:
* Actually Rotten: 45 (True Positive), 8 (False Positive)
* Actually Fresh: 5 (False Negative), 42 (True Negative)
* Accuracy:
* Accuracy is the proportion of true results (both true positives and true negatives) in the total population.
* Formula: Accuracy=TP+TNTP+TN+FP+FN\text{Accuracy} = \frac{TP + TN}{TP + TN + FP + FN}Accuracy=TP+TN+FP+FNTP+TN
* Calculation: Accuracy=45+4245+42+8+5=87100=0.87\text{Accuracy} = \frac{45 + 42}{45 + 42
+ 8 + 5} = \frac{87}{100} = 0.87Accuracy=45+42+8+545+42=10087=0.87
* Recall (Sensitivity):
* Recall is the proportion of true positive results in the total actual positives.
* Formula: Recall=TPTP+FN\text{Recall} = \frac{TP}{TP + FN}Recall=TP+FNTP
* Calculation: Recall=4545+5=4550=0.9\text{Recall} = \frac{45}{45 + 5} = \frac{45}{50} = 0.9 Recall=45+545=5045=0.9
* Specificity:
* Specificity is the proportion of true negative results in the total actual negatives.
* Formula: Specificity=TNTN+FP\text{Specificity} = \frac{TN}{TN + FP}Specificity=TN+FPTN
* Calculation: Specificity=4242+8=4250=0.84\text{Specificity} = \frac{42}{42 + 8} = \frac{42}
{50} = 0.84Specificity=42+842=5042=0.84
Therefore, the correct combinations of accuracy, recall, and specificity are 0.87, 0.9, and 0.84 respectively.
References:
ISTQB CT-AI Syllabus, Section 5.1, Confusion Matrix, provides detailed formulas and explanations for calculating various metrics including accuracy, recall, and specificity.
"ML Functional Performance Metrics" (ISTQB CT-AI Syllabus, Section 5).
NEW QUESTION # 76
Which ONE of the following tests is MOST likely to describe a useful test to help detect different kinds of biases in ML pipeline?
SELECT ONE OPTION
Answer: C
Explanation:
Detecting biases in the ML pipeline involves various tests to ensure fairness and accuracy throughout the ML process.
Testing the distribution shift in the training data for inappropriate bias (A): This involves checking if there is any shift in the data distribution that could lead to bias in the model. It is an important test but not the most direct method for detecting biases.
Test the model during model evaluation for data bias (B): This is a critical stage where the model is evaluated to detect any biases in the data it was trained on. It directly addresses potential data biases in the model.
Testing the data pipeline for any sources for algorithmic bias (C): This test is crucial as it helps identify biases that may originate from the data processing and transformation stages within the pipeline. Detecting sources of algorithmic bias ensures that the model does not inherit biases from these processes.
Check the input test data for potential sample bias (D): While this is an important step, it focuses more on the input data and less on the overall data pipeline.
Hence, the most likely useful test to help detect different kinds of biases in the ML pipeline isB. Test the model during model evaluation for data bias.
ISTQB CT-AI Syllabus Section 8.3 on Testing for Algorithmic, Sample, and Inappropriate Bias discusses various tests that can be performed to detect biases at different stages of the ML pipeline.
Sample Exam Questions document, Question #32 highlights the importance of evaluating the model for biases.
NEW QUESTION # 77
Pairwise testing can be used in the context of self-driving cars for controlling an explosion in the number of combinations of parameters.
Which ONE of the following options is LEAST likely to be a reason for this incredible growth of parameters?
SELECT ONE OPTION
Answer: C
Explanation:
Pairwise testing is used to handle the large number of combinations of parameters that can arise in complex systems like self-driving cars. The question asks which of the given options isleast likelyto be a reason for the explosion in the number of parameters.
* Different Road Types (A): Self-driving cars must operate on various road types, such as highways, city streets, rural roads, etc. Each road type can have different characteristics, requiring the car's system to adapt and handle different scenarios. Thus, this is a significant factor contributing to the growth of parameters.
* Different Weather Conditions (B): Weather conditions such as rain, snow, fog, and bright sunlight significantly affect the performance of self-driving cars. The car's sensors and algorithms must adapt to these varying conditions, which adds to the number of parameters that need to be considered.
* ML Model Metrics to Evaluate Functional Performance (C): While evaluating machine learning (ML) model performance is crucial, it does not directly contribute to the explosion of parameter combinations in the same way that road types, weather conditions, and car features do. Metrics are used to measure and assess performance but are not themselves variable conditions that the system must handle.
* Different Features like ADAS, Lane Change Assistance, etc. (D): Advanced Driver Assistance Systems (ADAS) and other features add complexity to self-driving cars. Each feature can have multiple settings and operational modes, contributing to the overall number of parameters.
Hence, theleast likelyreason for the incredible growth in the number of parameters isC. ML model metrics to evaluate the functional performance.
References:
* ISTQB CT-AI Syllabus Section 9.2 on Pairwise Testing discusses the application of this technique to manage the combinations of different variables in AI-based systems, including those used in self- driving cars.
* Sample Exam Questions document, Question #29 provides context for the explosion in parameter combinations in self-driving cars and highlights the use of pairwise testing as a method to manage this complexity.
NEW QUESTION # 78
An e-commerce developer built an application for automatic classification of online products in order to allow customers to select products faster. The goal is to provide more relevant products to the user based on prior purchases.
Which of the following factors is necessary for a supervised machine learning algorithm to be successful?
Answer: D
Explanation:
Supervised machine learning requires correctly labeled data to train an effective model. The learning process relies on input-output mappings where each training example consists of an input (features) and a correctly labeled output (target variable). Incorrect labeling can significantly degrade model performance.
* Supervised Learning Process
* The algorithm learns from labeled data, mapping inputs to correct outputs during training.
* If labels are incorrect, the model will learn incorrect relationships and produce unreliable predictions.
* Quality of Training Data
* The accuracy of any supervised ML model ishighly dependent on the quality of labels.
* Poorly labeled data leads to mislabeled training sets, resulting inbiased or underperforming models.
* Error Minimization and Model Accuracy
* Incorrectly labeled data affects theconfusion matrix, reducing precision, recall, and accuracy.
* It leads to overfitting or underfitting, which decreases the model's ability to generalize.
* Industry Standard Practices
* Many AI development teams spend a significant amount of time ondata annotation and quality controlto ensure high-quality labeled datasets.
* (B) Minimizing the amount of time spent training the algorithm#(Incorrect)
* While reducing training time is important for efficiency, the quality of training is more critical. A well-trained model takes time to process large datasets and optimize its parameters.
* (C) Selecting the correct data pipeline for the ML training#(Incorrect)
* A good data pipeline helps, butit does not directly impact learning successas much as labeling does.Even a well-optimized pipeline cannot fix incorrect labels.
* (D) Grouping similar products together before feeding them into the algorithm#(Incorrect)
* This describesclustering, which is anunsupervised learning technique. Supervised learningrequires labeled examples, not just grouping of data.
* Labeled data is necessary for supervised learning."For supervised learning, it is necessary to have properly labeled data."
* Data labeling errors can impact performance."Supervised learning assumes that the data is correctly labeled by the data annotators.However, it is rare in practice for all items in a dataset to be labeled correctly." Why Labeling is Critical?Why Other Options are Incorrect?References from ISTQB Certified Tester AI Testing Study GuideThus,option A is the correct answer, ascorrectly labeled data is essential for supervised machine learning success.
NEW QUESTION # 79
......
The passing rate of our CT-AI guide materials is high as 98% to 100% and you don’t need to worry that you have spent money but can’t pass the test. We can’t list all the advantages with several words and please read the introduction of the features and advantages of our CT-AI training quiz in detail on the website. You will find that every button on the page is fast and convenient to use. And we also have the free demos of the CT-AI exam questions for you to download before purchase.
CT-AI Reliable Mock Test: https://www.vcetorrent.com/CT-AI-valid-vce-torrent.html
P.S. Free & New CT-AI dumps are available on Google Drive shared by VCETorrent: https://drive.google.com/open?id=1IspgU19uOrL1rv-R3UbtnN3NP4H0hLyg