Now passing Microsoft certification AB-100 exam is not easy, so choosing a good training tool is a guarantee of success. Real4exams will be the first time to provide you with exam information and exam practice questions and answers to let you be fully prepared to ensure 100% to pass Microsoft Certification AB-100 Exam. Real4exams can not only allow you for the first time to participate in the Microsoft certification AB-100 exam to pass it successfully, but also help you save a lot of valuable time.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> AB-100 Latest Exam Forum <<
These Microsoft AB-100 questions will give you an accurate foresight of the Microsoft AB-100 examination format. This Microsoft AB-100 is easily downloadable and even printable, this way you can also pursue paper study if that is your preferred method. The portability of this material makes it handier since you can access it on any smart device such as smart phones, laptops, tablets, etc. These Microsoft AB-100 features make this prep method the most comfortable one.
NEW QUESTION # 90
You are designing a testing solution for Microsoft Copilot Studio agents.
You need to validate prompt engineering best practices to ensure that the agents generate accurate and contextually relevant responses. Which prompt validation techniques and metrics should you include in the solution? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.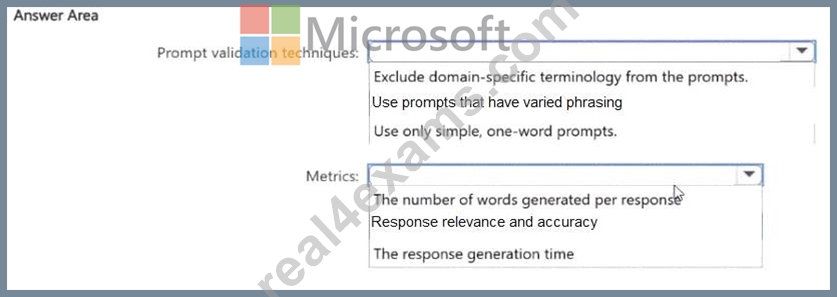
Answer:
Explanation: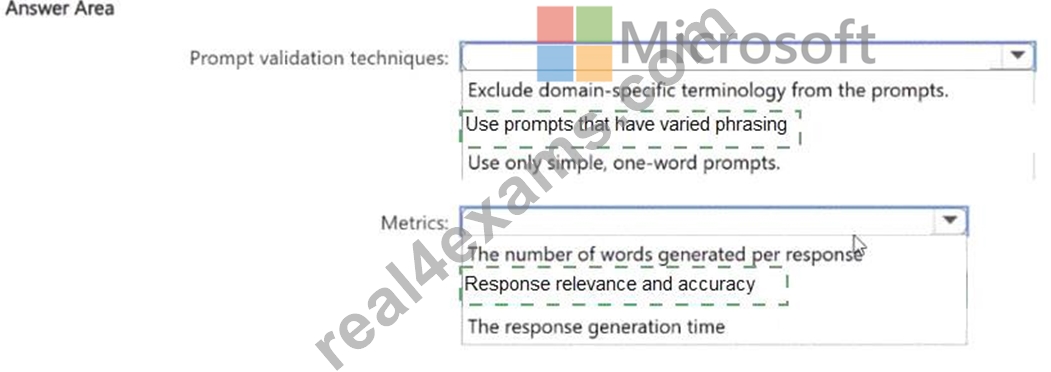
Explanation:
To validate prompt engineering for Microsoft Copilot Studio agents , the goal is to confirm that the agent responds correctly even when users ask the same thing in different ways, and to measure whether the responses are actually useful and correct.
For the prompt validation technique , the correct choice is Use prompts that have varied phrasing . This is a core best practice because real users do not ask questions in one fixed form. They may use different wording, sentence structure, synonyms, or levels of detail. Testing with varied phrasing checks whether the prompt design is robust and whether the agent can still produce the right response across natural language variation.
For the metric , the correct choice is Response relevance and accuracy . Since the requirement is to ensure responses are accurate and contextually relevant , this is the most appropriate measure. It directly evaluates whether the output answers the user's need correctly and in the right context.
Why the other options are not correct:
* Exclude domain-specific terminology from the prompts is not a best practice in business AI solutions. In many enterprise scenarios, domain-specific terms are essential for accuracy.
* Use only simple, one-word prompts does not reflect real-world usage and would weaken testing coverage.
* The number of words generated per response does not tell you whether the response is correct or contextually appropriate.
* The response generation time is a performance metric, not the best metric for validating prompt quality.
NEW QUESTION # 91
A company has an AI solution built by using Microsoft Copilot Studio and Power Platform. The solution is used by the company ' s sales, marketing, and customer service teams.
You are performing a return on AI investment (ROAI) analysis to evaluate the impact of the solution.
You need to identify which measurable business drivers to include in the analysis.
Which two business drivers should you identify? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,D
Explanation:
Comprehensive and Detailed Explanation From Agentic AI Business Solutions Topics:
The correct answers are A. the reduced average case resolution time and D. increased employee productivity.
This question is asking for measurable business drivers for a ROAI analysis of a Copilot Studio and Power Platform solution used by operational teams.
For ROAI, the strongest business drivers are those that are:
directly attributable to the AI solution
operationally measurable
tied to business outcomes
relevant across teams
Why A is correct
Reduced average case resolution time is a strong measurable driver because it reflects a direct operational improvement in customer service and support workflows.
This metric can be quantified clearly by comparing:
baseline resolution time before AI
resolution time after deployment
That makes it ideal for ROAI because faster case resolution often leads to:
lower service cost
higher throughput
better customer experience
more efficient staffing
Why D is correct
Increased employee productivity is another core ROAI driver because AI solutions in sales, marketing, and customer service are often deployed specifically to reduce manual work and improve output per employee.
This can be measured through indicators such as:
more tasks completed per agent or employee
reduced manual effort
increased throughput
faster response cycles
more time spent on higher-value work
From an AI business solutions perspective, productivity improvement is one of the most common and valid drivers in ROAI analysis.
Why the other options are incorrect
B). market capitalization
This is too broad and influenced by many external factors. It is not a practical direct business driver for evaluating the specific impact of one AI business solution.
C). economic market predictability
This is not a direct business driver created by the solution and is too external to the organization's operational AI ROI calculation.
E). brand awareness
Brand awareness can matter strategically, but it is less directly attributable and less operationally measurable than resolution time and productivity for this kind of internal business solution.
Expert reasoning
For ROAI questions, prefer metrics that are:
operational
attributable
measurable before and after deployment
That leads to:
reduced average case resolution time
increased employee productivity
So the correct choices are:
NEW QUESTION # 92
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
A company has a team that analyzes its customers by using a manual process.
You are designing an AI-based agent to automate and improve the process.
You need to recommend on which platform to build the agent.
The solution must meet the following requirements:
* Use generative AI to answer common questions.
* Provide analytics to review AI performance.
* Identify customer demographics.
* Minimize custom development.
Solution: You recommend Microsoft Copilot Studio.
Does this meet the goal?
Answer: B
NEW QUESTION # 93
A company uses multiple Microsoft Copilot Studio agents across different channels.
You need to recommend a monitoring solution that provides comprehensive telemetry data and performance insights for the agents.
What should you include in the recommendation?
Answer: C
Explanation:
To achieve comprehensive monitoring, telemetry, and performance insights for Microsoft Copilot Studio agents across different channels, you should integrate them with Azure Application Insights.
Integrating Application Insights provides a centralized view of agent health, user interactions, topic performance, and latency, which is crucial for monitoring multi-channel deployments.
Reference:
https://learn.microsoft.com/en-us/azure/azure-monitor/app/agents-view
NEW QUESTION # 94
You are designing a testing solution for a Microsoft Copilot Studio agent that integrates with Microsoft Dynamics 365 Customer Service and Dynamics 365 Sales.
You need to design end-to-end scenarios to test the agent ' s ability to perform the following actions:
Coordinate tasks and data interactions across both Dynamics 365 apps.
Interpret user input and provide contextually relevant outputs.
Which test scenario and metric should you include in the design? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Test scenario # Run task-based scenarios that involve both apps; Metric # Track the successful completion of cross-app tasks Comprehensive and Detailed Explanation From Agentic AI Business Solutions Topics:
The correct answer is D :
* Test scenario # Run task-based scenarios that involve both apps
* Metric # Track the successful completion of cross-app tasks
Why this test scenario is correct
The question explicitly asks for an end-to-end testing design for a Copilot Studio agent that integrates with both:
* Dynamics 365 Customer Service
* Dynamics 365 Sales
The required capabilities are:
* coordinating tasks and data interactions across both apps
* interpreting user input and returning contextually relevant outputs
That means the testing approach cannot be isolated to one app at a time. It must validate the agent's behavior across the full multi-application business workflow.
That is why the correct test scenario is:
Run task-based scenarios that involve both apps
This kind of test validates whether the agent can successfully move through realistic business processes such as:
* reading customer context from one app
* updating or retrieving related sales information in the other
* maintaining context through the workflow
* responding appropriately based on user intent across systems
From an agentic AI business solutions perspective, this is the right design because true enterprise agent validation must focus on workflow execution , not just component-level checks.
Why this metric is correct
The best metric is:
Track the successful completion of cross-app tasks
This is the most direct way to measure whether the agent is actually achieving the intended business outcome across both Dynamics 365 applications.
Why this matters:
* The requirement is about coordination across apps
* The test is end-to-end
* The goal is not just speed or UI consistency
* The agent must complete business tasks successfully across systems
A cross-app completion metric shows whether the agent can:
* understand the user's request
* maintain context
* retrieve or update the right information
* finish the workflow correctly across app boundaries
This is much more meaningful than measuring clicks or simple response time.
Why the other options are incorrect
A). In each app, test isolated tasks without using workflows / Measure initial prompt response time This fails the end-to-end requirement. Isolated tasks do not validate cross-app orchestration, and response time does not prove successful workflow execution.
B). Run task-based scenarios that involve both apps / Track average click rate across both apps The scenario part is good, but average click rate is not the right success metric for Copilot task orchestration.
Clicks do not reliably measure whether the business process was completed correctly.
C). Test visual consistency across both apps / Track successful completion of cross-app tasks The metric is good, but the test scenario is wrong. Visual consistency is a UI concern, not an end-to-end functional validation of cross-app agent behavior.
Expert reasoning
For exam questions like this:
* If the requirement says end-to-end across multiple apps , choose task-based scenarios involving both apps
* If the goal is business workflow success, choose a metric tied to task completion , not visual design, click rate, or raw response speed
NEW QUESTION # 95
......
May be you still strange to our AB-100 dumps pdf, you can download the free demo of the dump torrent before you buy. If you have any questions to our Microsoft exam questions torrent, please feel free to contact us and we will give our support immediately. You will be allowed to updating AB-100 Learning Materials one-year once you bought pdf dumps from our website.
AB-100 Latest Test Report: https://www.real4exams.com/AB-100_braindumps.html