Reliable Certified-Data-Engineer-Professional Test Camp & Certified-Data-Engineer-Professional Passed

If you are a person who desire to move ahead in the career with informed choice, then the Databricks training material is quite beneficial for you. The Certified-Data-Engineer-Professional pdf vce is designed to boost your personal ability in your industry. It just needs to spend 20-30 hours on the Certified-Data-Engineer-Professional Preparation, which can allow you to face with Certified-Data-Engineer-Professional actual test with confidence. You will always get the latest and updated information about Certified-Data-Engineer-Professional training pdf for study due to our one year free update policy after your purchase.
| Section | Objectives |
|---|
| Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- Monitoring
- 1. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 2. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 3. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 4. Use Query Profile and Spark UI to monitor workloads
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Develop User-Defined Functions using Pandas/Python UDF
- 3. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 2. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 3. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 4. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 5. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 6. Create pipeline components using control flow operators such as if/else and foreach
- 7. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 8. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
|
| Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Configure Lakehouse Federation with appropriate governance across supported source systems
- 3. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
|
| Debugging and Deploying | - Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
- Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 2. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 3. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
|
| Data Modeling | - Design and optimize data models
- 1. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 2. Design dimensional models for analytical workloads with efficient querying and aggregation
- 3. Design and implement scalable data models using Delta Lake to manage large datasets
- 4. Simplify data layout decisions and optimize query performance using liquid clustering
|
| Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
- Applying Data Security Mechanisms
- 1. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 2. Use row filters and column masks to protect sensitive table data
- 3. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 2. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 3. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 4. Apply Change Data Feed to address streaming table limitations and improve latency
- 5. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
|
>> Reliable Certified-Data-Engineer-Professional Test Camp <<
Databricks Reliable Certified-Data-Engineer-Professional Test Camp Exam Latest Release | Updated Certified-Data-Engineer-Professional Passed
Studying from an updated practice material is necessary to get success in the Databricks Certified-Data-Engineer-Professional certification test on the first try. If you don't adopt this strategy, you will not be able to clear the Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) examination. Failure in the Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) test will lead to loss of confidence, time, and money.
Databricks Certified Data Engineer Professional Sample Questions (Q216-Q221):
NEW QUESTION # 216
Two of the most common data locations on Databricks are the DBFS root storage and external object storage mounted with dbutils.fs.mount().
Which of the following statements is correct?
- A. The DBFS root stores files in ephemeral block volumes attached to the driver, while mounted directories will always persist saved data to external storage between sessions.
- B. DBFS is a file system protocol that allows users to interact with files stored in object storage using syntax and guarantees similar to Unix file systems.
- C. Neither the DBFS root nor mounted storage can be accessed when using %sh in a Databricks notebook.
- D. By default, both the DBFS root and mounted data sources are only accessible to workspace administrators.
- E. The DBFS root is the most secure location to store data, because mounted storage volumes must have full public read and write permissions.
Answer: B
Explanation:
DBFS is a file system protocol that allows users to interact with files stored in object storage using syntax and guarantees similar to Unix file systems. DBFS is not a physical file system, but a layer over the object storage that provides a unified view of data across different data sources. By default, the DBFS root is accessible to all users in the workspace, and the access to mounted data sources depends on the permissions of the storage account or container. Mounted storage volumes do not need to have full public read and write permissions, but they do require a valid connection string or access key to be provided when mounting. Both the DBFS root and mounted storage can be accessed when using %sh in a Databricks notebook, as long as the cluster has FUSE enabled. The DBFS root does not store files in ephemeral block volumes attached to the driver, but in the object storage associated with the workspace. Mounted directories will persist saved data to external storage between sessions, unless they are unmounted or deleted.
NEW QUESTION # 217
A DLT pipeline includes the following streaming tables:
Raw_lot ingest raw device measurement data from a heart rate tracking device.
Bpm_stats incrementally computes user statistics based on BPM measurements from raw_lot.
How can the data engineer configure this pipeline to be able to retain manually deleted or updated records in the raw_iot table while recomputing the downstream table when a pipeline update is run?
- A. Set the pipelines, reset, allowed property to false on bpm_stats
- B. Set the skipChangeCommits flag to true on bpm_stats
- C. Set the SkipChangeCommits flag to true raw_lot
- D. Set the pipelines, reset, allowed property to false on raw_iot
Answer: D
Explanation:
In Databricks Lakehouse, to retain manually deleted or updated records in the raw_iot table while recomputing downstream tables when a pipeline update is run, the property pipelines.reset.allowed should be set to false. This property prevents the system from resetting the state of the table, which includes the removal of the history of changes, during a pipeline update. By keeping this property as false, any changes to the raw_iot table, including manual deletes or updates, are retained, and recomputation of downstream tables, such as bpm_stats, can occur with the full history of data changes intact.
NEW QUESTION # 218
An external object storage container has been mounted to the location /mnt/finance_eda_bucket.
The following logic was executed to create a database for the finance team:
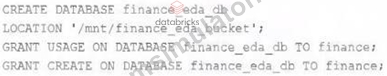
After the database was successfully created and permissions configured, a member of the finance team runs the following code:
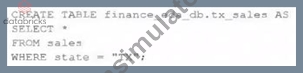
If all users on the finance team are members of the finance group, which statement describes how the tx_sales table will be created?
- A. An managed table will be created in the storage container mounted to /mnt/finance_eda_bucket.
- B. An external table will be created in the storage container mounted to /mnt/finance eda bucket.
- C. A logical table will persist the query plan to the Hive Metastore in the Databricks control plane.
- D. A logical table will persist the physical plan to the Hive Metastore in the Databricks control plane.
- E. A managed table will be created in the DBFS root storage container.
Answer: A
Explanation:
https://docs.databricks.com/en/data-governance/unity-catalog/create-schemas.html#language-SQL
NEW QUESTION # 219
A data engineer has created a transactions Delta table on Databricks that should be used by the analytics team. The analytics team wants to use the table with another tool that requires Apache Iceberg format. What should the data engineer do?
- A. Require the analytics team to use a tool that supports Delta table.
- B. Create an Iceberg copy of the transactions Delta table which can be used by the analytics team.
- C. Enable uniform on the transactions table to 'iceberg' so that the table can be read as an Iceberg table.
- D. Convert the transactions Delta table to Iceberg and enable uniform so that the table can be read as a Delta table.
Answer: D
Explanation:
Delta Lake introduced Delta Universal Format (Delta UniForm), which allows seamless interoperability between Delta Lake and Apache Iceberg. This means a Delta table can be converted into an Iceberg table while maintaining Delta capabilities.
NEW QUESTION # 220
A Delta table of weather records is partitioned by date and has the below schema:
date DATE, device_id INT, temp FLOAT, latitude FLOAT, longitude FLOAT
To find all the records from within the Arctic Circle, you execute a query with the below filter:
latitude > 66.3
Which statement describes how the Delta engine identifies which files to load?
- A. The Hive metastore is scanned for min and max statistics for the latitude column
- B. All records are cached to an operational database and then the filter is applied
- C. The Delta log is scanned for min and max statistics for the latitude column
- D. All records are cached to attached storage and then the filter is applied
- E. The Parquet file footers are scanned for min and max statistics for the latitude column
Answer: C
Explanation:
This is the correct answer because Delta Lake uses a transaction log to store metadata about each table, including min and max statistics for each column in each data file. The Delta engine can use this information to quickly identify which files to load based on a filter condition, without scanning the entire table or the file footers. This is called data skipping and it can improve query performance significantly. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; [Databricks Documentation], under "Optimizations - Data Skipping" section.
In the Transaction log, Delta Lake captures statistics for each data file of the table. These statistics indicate per file:
- Total number of records
- Minimum value in each column of the first 32 columns of the table
- Maximum value in each column of the first 32 columns of the table
- Null value counts for in each column of the first 32 columns of the table When a query with a selective filter is executed against the table, the query optimizer uses these statistics to generate the query result. it leverages them to identify data files that may contain records matching the conditional filter.
For the SELECT query in the question, The transaction log is scanned for min and max statistics for the price column.
NEW QUESTION # 221
......
When preparing for the Certified-Data-Engineer-Professional exam, a good source of information is what candidates need most, and the price of the materials is one of the important factors to be considered when a candidate choosing. In contrast to most exam preparation materials available online, our Certified-Data-Engineer-Professional exam materials of ITExamSimulator can be obtained at a reasonable price so that each candidate who prepares to take the Certified-Data-Engineer-Professional exam can afford it. It will not let any one of the candidates be worried about the price issue, and its quality and advantages exceed all our competitors' similar products. We will never reduce the quality of our Certified-Data-Engineer-Professional Exam Questions because the price is easy to bear by candidates and the quality of our exam questions will not let you down. They will prove the best choice for your time and money.
Certified-Data-Engineer-Professional Passed: https://www.itexamsimulator.com/Certified-Data-Engineer-Professional-brain-dumps.html
- Related Certified-Data-Engineer-Professional Certifications 🧤 Certified-Data-Engineer-Professional Latest Dump 🦟 Certified-Data-Engineer-Professional Exam Engine 🐸 【 www.practicevce.com 】 is best website to obtain ▷ Certified-Data-Engineer-Professional ◁ for free download ⚔Latest Certified-Data-Engineer-Professional Exam Preparation
- Certified-Data-Engineer-Professional Latest Test Bootcamp 🤧 Certified-Data-Engineer-Professional Exam Engine 🧹 Latest Certified-Data-Engineer-Professional Exam Testking 🌸 Search on 《 www.pdfvce.com 》 for ( Certified-Data-Engineer-Professional ) to obtain exam materials for free download 🤧Valid Test Certified-Data-Engineer-Professional Vce Free
- Valid Certified-Data-Engineer-Professional Exam Experience 🧹 Valid Test Certified-Data-Engineer-Professional Vce Free 🚀 Certified-Data-Engineer-Professional Actual Exams 🤦 Search for ➥ Certified-Data-Engineer-Professional 🡄 and easily obtain a free download on [ www.torrentvce.com ] 🥠Latest Certified-Data-Engineer-Professional Exam Preparation
- Top Reliable Certified-Data-Engineer-Professional Test Camp | High Pass-Rate Certified-Data-Engineer-Professional Passed: Databricks Certified Data Engineer Professional 😝 Download ▶ Certified-Data-Engineer-Professional ◀ for free by simply entering ➽ www.pdfvce.com 🢪 website 😩Related Certified-Data-Engineer-Professional Certifications
- Valid Certified-Data-Engineer-Professional Test Syllabus 💃 Related Certified-Data-Engineer-Professional Certifications 🗜 Certified-Data-Engineer-Professional Reliable Exam Topics 😣 Enter ▶ www.examcollectionpass.com ◀ and search for ☀ Certified-Data-Engineer-Professional ️☀️ to download for free 🐽Accurate Certified-Data-Engineer-Professional Test
- Realistic Reliable Certified-Data-Engineer-Professional Test Camp - 100% Pass Databricks Databricks Certified Data Engineer Professional Passed ➡ Simply search for ⏩ Certified-Data-Engineer-Professional ⏪ for free download on ➤ www.pdfvce.com ⮘ 😮Certified-Data-Engineer-Professional Latest Dump
- Amazing Certified-Data-Engineer-Professional Exam Simulation: Databricks Certified Data Engineer Professional give you the latest Practice Dumps - www.practicevce.com 🆔 Search for ⏩ Certified-Data-Engineer-Professional ⏪ and download exam materials for free through ☀ www.practicevce.com ️☀️ 🐘Latest Certified-Data-Engineer-Professional Exam Testking
- Free PDF Quiz 2026 Databricks Accurate Certified-Data-Engineer-Professional: Reliable Databricks Certified Data Engineer Professional Test Camp 🌋 Open 「 www.pdfvce.com 」 and search for ⮆ Certified-Data-Engineer-Professional ⮄ to download exam materials for free 🌶Valid Certified-Data-Engineer-Professional Exam Experience
- Free Download Reliable Certified-Data-Engineer-Professional Test Camp | Easy To Study and Pass Exam at first attempt - Valid Databricks Databricks Certified Data Engineer Professional 💦 Go to website 【 www.prep4sures.top 】 open and search for ⏩ Certified-Data-Engineer-Professional ⏪ to download for free 🎏Flexible Certified-Data-Engineer-Professional Testing Engine
- Valid Certified-Data-Engineer-Professional test answers - Databricks Certified-Data-Engineer-Professional exam pdf - Certified-Data-Engineer-Professional actual test 🐧 Search for ▷ Certified-Data-Engineer-Professional ◁ on ☀ www.pdfvce.com ️☀️ immediately to obtain a free download 🕓Valid Certified-Data-Engineer-Professional Test Syllabus
- Free Download Reliable Certified-Data-Engineer-Professional Test Camp | Easy To Study and Pass Exam at first attempt - Valid Databricks Databricks Certified Data Engineer Professional 🔪 Simply search for ➡ Certified-Data-Engineer-Professional ️⬅️ for free download on ▛ www.validtorrent.com ▟ 🧾Accurate Certified-Data-Engineer-Professional Test
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes