What's more, part of that VerifiedDumps DAA-C01 dumps now are free: https://drive.google.com/open?id=1LbSYeWBK3WIxNM2tbXqALYrDqfCOmhod
The DAA-C01 certificate is one of the popular IT certificates. Success in the DAA-C01 credential examination enables you to advance your career at a rapid pace. You become eligible for many high-paying jobs with the DAA-C01 certification. To pass the DAA-C01 test on your first sitting, you must choose reliable SnowPro Advanced: Data Analyst Certification Exam exam study material. Don’t worry about DAA-C01 test preparation, because VerifiedDumps is offering DAA-C01 actual exam questions at an affordable price. Hundreds of IT aspirants have cracked the DAA-C01 examination by just preparing with our real test questions. If you also want to become a DAA-C01 certified without any anxiety, download Snowflake updated test questions and start preparing today. These real DAA-C01 Dumps come in desktop practice exam software, web-based practice test, and DAA-C01 PDF document. Below are specifications of these three formats.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Use Built-in Functions and Create UDFs | 10–15% | - User-Defined Functions (UDFs) - Scalar, aggregate, table, system functions |
| Topic 2: Prepare and Load Data | 15–20% | - External tables and data validation - File formats: CSV, JSON, Parquet, Avro - Data ingestion methods: COPY INTO, stages, Snowpipe |
| Topic 3: Prepare and Present Data | 10–15% | - Data visualization and reporting - Snowsight dashboards and sharing results - Align outputs with business requirements |
| Topic 4: Perform Descriptive and Diagnostic Analysis | 10–15% | - Exploratory and ad-hoc analysis - Statistical summarization and trend analysis - Anomaly detection and root cause analysis |
| Topic 5: Perform Predictive Analysis | 5–10% | - Using Snowflake ML and built-in analytics - Forecasting and predictive modeling |
| Topic 6: Build and Troubleshoot Advanced SQL Queries | 20–25% | - Semi-structured data processing - Complex joins, subqueries, window functions - Query optimization and troubleshooting |
| Topic 7: Perform Simple Data Transformations for Analysis | 15–20% | - Data cleansing, standardization, type conversion - Views, materialized views, CTEs - Handling NULLs and structuring datasets |
>> Test DAA-C01 Cram Review <<
The company is preparing for the test candidates to prepare the DAA-C01 Study Materials professional brand, designed to be the most effective and easiest way to help users through their want to get the test DAA-C01 certification and obtain the relevant certification. In comparison with similar educational products, our training materials are of superior quality and reasonable price, so our company has become the top enterprise in the international market.
NEW QUESTION # 53
There are two similarly-structured and sized tables, Table_a and Table_b, in a schema with data populated in both tables. A Data Analyst is running queries as part of a preliminary analysis of the data to check the MAX value of a numeric column named num which is present in both the tables:
* Query 1: SELECT MAX(num) FROM Table_a;
* Query 2: SELECT MAX(num) FROM Table_b;
After running the queries, the Analyst observed that Query 2 ran significantly slower than Query 1. Why is this occurring?
Answer: B
Explanation:
In Snowflake, the performance of a metadata-based query (like MAX, MIN, or COUNT) is typically near- instantaneous because Snowflake maintains constant-time statistics in its Cloud Services layer. For a standard table, SELECT MAX(num) does not even require a virtual warehouse to be active; it simply reads the value from the table's metadata.
However, when a Row Access Policy (RAP) is applied to a table, the query's behavior changes fundamentally. A row access policy is a security feature that restricts which rows are visible to a user based on their role or other attributes. To enforce this policy, Snowflake can no longer rely on the high-level metadata of the entire table because it must first determine which specific rows the user is authorized to see.
Consequently, the query engine must scan the individual micro-partitions and evaluate the policy logic for every row (or block of rows) to filter out unauthorized data before calculating the maximum value. This turns a "metadata-only" operation into a data-scanning operation, which requires a running warehouse and significantly more time.
Evaluating the Options:
* Option A is incorrect because the prompt states the tables are "similarly-sized." Even if it were slightly larger, a metadata lookup for a standard table would still be nearly instant.
* Option C is incorrect because a multi-cluster warehouse helps with concurrency (multiple users), not the raw execution speed of a single simple aggregate query.
* Option D is incorrect because USE_CACHED_RESULT refers to the Query Result Cache. While turning it off would prevent a "0ms" response from a previous run, it wouldn't explain a "significant" slowdown compared to a standard metadata fetch.
* Option B is the 100% correct answer. The presence of a Row Access Policy forces a full data scan and policy evaluation, which is the most common reason for performance degradation in otherwise simple metadata queries.
NEW QUESTION # 54
You are tasked with retrieving data from a source system that outputs a large stream of semi-structured JSON data'. The data contains nested arrays and deeply nested objects. The data needs to be transformed before being loaded into Snowflake to flatten the structure and extract relevant fields. Which approach is most efficient and scalable for retrieving and preparing this data?
Answer: B
Explanation:
Option C is the most efficient and scalable. Using an external stream processing framework allows for real-time or near real-time transformation and flattening of the JSON data before it even reaches Snowflake, offloading the processing burden. Options A and B might struggle with very large and complex JSON structures. The SnowSQL script in option A will be complex and less efficient. Transforming within a view in option B delays the transformation and can impact query performance. Option D might face performance issues as passing each record to a Python UDF can be overhead heavy. External tables (option E) are generally best for read-only access and might not be suitable for complex transformations.
NEW QUESTION # 55
What role does operationalizing data play in maintaining reports and dashboards for business requirements?
Answer: D
Explanation:
Operationalizing data ensures consistent and efficient usage of reports and dashboards.
NEW QUESTION # 56
Your organization stores clickstream data in Parquet files in an external stage 's3://your-bucket/clickstreamP. The data includes nested JSON structures representing user activity. You need to create a Snowflake table to query this data efficiently, extracting specific fields from the nested JSON. The challenge is to optimize query performance by leveraging Parquet's columnar storage and schema evolution capabilities. Which of the following approaches offers the BEST combination of performance and flexibility for querying the data in Snowflake, considering potential schema changes in the Parquet files over time?
Answer: D
Explanation:
Materialized Views offer the best performance as they pre-compute and store the results, leveraging Snowflake's caching. They also adapt to schema changes in underlying Parquet files (within limits). External tables alone can be slow because of on-the-fly processing. Loading into VARIANT loses the advantage of Parquet's columnar structure. Predefined columns are rigid and don't handle schema evolution well. Creating standard views on external tables also does not provide the pre-computed benefits of the materialized views.
NEW QUESTION # 57
You need to create a UDF in Snowflake to mask personally identifiable information (PII) in a 'customers' table. The UDF should take a string as input (e.g., email address, phone number) and return a masked version. For email addresses, it should replace everything before the '@' symbol with ' For phone numbers (assuming a simple format like '123-456-7890'), it should mask all but the last four digits with 'X'. Which of the following UDF definitions is MOST efficient and correctly implements this logic using Snowflake's JavaScript UDF capabilities and appropriate error handling?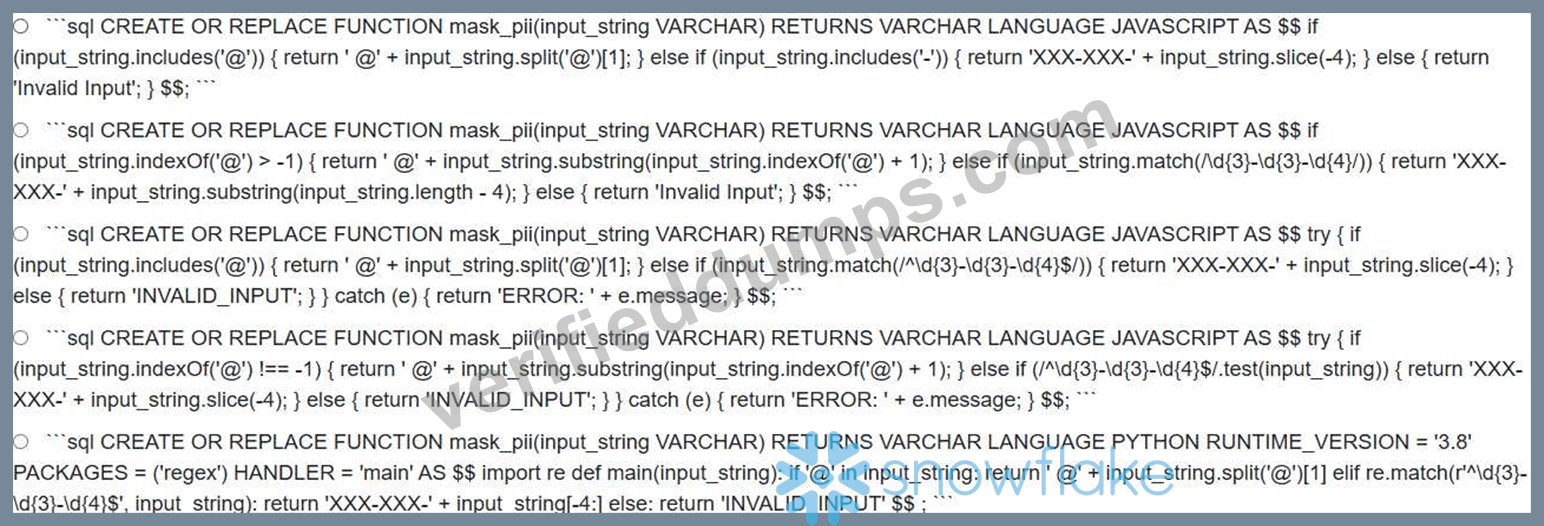
Answer: B
Explanation:
Option D is the most efficient and robust. It uses 'indexOf and regular expressions ('test()') for more reliable string matching, includes error handling using a 'try...catch' block, and correctly handles the different masking scenarios. The regex ensures that the phone number format is strictly validated before masking. Options A and B lack error handling and use less precise matching techniques (e.g., 'includes' which could lead to unintended behavior). Option C is similar to option D but utilizes javascript includes which is not reliable as indexof in finding exact position. Option E is a Python UDF, which, while valid, would be less performant than javascript UDF as specified in question.
NEW QUESTION # 58
......
You can also be a part of this wonderful community. To do this you just need to pass the Snowflake DAA-C01 certification exam. Are you ready to accept this challenge? Looking for the proven and easiest way to crack the Snowflake DAA-C01 Certification Exam? If your answer is yes then you do not need to go anywhere. Just download VerifiedDumps DAA-C01 exam practice questions and start SnowPro Advanced: Data Analyst Certification Exam (DAA-C01) exam preparation without wasting further time.
DAA-C01 Latest Version: https://www.verifieddumps.com/DAA-C01-valid-exam-braindumps.html
DOWNLOAD the newest VerifiedDumps DAA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1LbSYeWBK3WIxNM2tbXqALYrDqfCOmhod