DOWNLOAD the newest TestBraindump AI-500 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1OYKwfi1G_I7hpj-42IJ1hg8EYB8vuIyb
The passing rate of our AI-500 training braindump is 99% which means that you almost can pass the AI-500 test with no doubts. The reasons why our AI-500 test guide’ passing rate is so high are varied. That is because our test bank includes two forms and they are the PDF test questions which are selected by the senior lecturer, published authors and professional experts and the practice test software which can test your mastery degree of our AI-500 study question at any time. The two forms cover the syllabus of the entire AI-500 test. You will pass the AI-500 exam with it.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Evaluate, optimize, and monitor multi-agent solutions | 20–25% | - Assess performance and reliability
|
| Topic 2: Develop multi-agent solutions in Azure | 30–35% | - Implement agents using Azure AI services
|
| Topic 3: Secure, govern, and deploy multi-agent solutions | 20–25% | - Apply security and compliance
|
| Topic 4: Architect multi-agent solutions | 15–20% | - Design logical architecture for multi-agent systems
|
The web-based Microsoft AI-500 practice test software is designed explicitly for the Designing and Implementing Multi-Agent AI Solutions exam. It is a well-known self-preparation tool that contains AI-500 Exam Questions approved by Microsoft Certified Professionals. Our Microsoft AI-500 exam questions are periodically updated and are similar to the real Designing and Implementing Multi-Agent AI Solutions exam questions. The Microsoft AI-500 Practice Test has a close resemblance with the actual Microsoft AI-500 exam. Multiple This Microsoft certification exam needs to be finished in a certain time duration, therefore Microsoft AI-500 practice test allows candidates to practice in the allocated time set according to their own needs.
NEW QUESTION # 33
You have a Microsoft Foundry ticket-triage solution that uses connected agents. Each subagent prompt includes instructions for allowed tools and a JSON handoff.
You need to add automated prompt evaluations. The solution must identify changes that cause the subagents to do the following:
* Skip mandated evidence gathering.
* Return payloads that downstream agents cannot process.
* Handle work outside their assigned responsibilities.
How should you configure the evaluation suite? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Mandated evidence/tool behavior: Replay cases and assert tool-call and citation presence; Agent responsibility boundaries: Test in-scope responses and out-of-scope refusals; Workflow handoff contract: Replay fixtures and validate schema-conforming payloads.
The three regressions target different interfaces and should be evaluated with tests that directly observe those interfaces. Required evidence gathering is a process behavior, so replayed cases should assert that mandated tool calls and citations occur. Responsibility boundaries are best tested with both positive and negative prompts: in-scope cases must be handled, while out-of-scope work should be refused or redirected. The JSON handoff is an interface contract, so replay fixtures should be validated against the expected schema to catch missing fields, renamed properties, and type changes before downstream agents fail. Microsoft Foundry ' s agent evaluators and evaluation datasets support process-level tool checks, task-adherence checks, and structured regression testing. The supplied mappings therefore correctly align each evaluation technique with the failure it is intended to detect. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - built-in evaluators and evaluation datasets
NEW QUESTION # 34
You have a Microsoft Foundry agent named Agent1.
You open Agent1 in the playground and update the instructions.
You need to run a full evaluation against the updated instructions. The solution must meet the following requirements:
* Test the changes by using a synthetic dataset.
* Ensure that the changes are available only for the development team that has access to Agent1.
What should you do first?
Answer: C
Explanation:
The instructions changed in the playground, but a full evaluation needs a stable, versioned agent definition.
Saving the changes as a new version creates an immutable snapshot that can be evaluated against a synthetic dataset while remaining inside the project for the development team. Publishing is a later lifecycle action that makes a version available to broader consumers or production endpoints and is not required for a private development evaluation. Previewing exercises the current playground configuration interactively but does not establish the versioned target needed for repeatable evaluation. Creating an evaluation before saving the new version risks evaluating the previous configuration instead of the intended update. Microsoft Foundry ' s development lifecycle separates edit, save/version, evaluate, and publish stages, so A is the correct first action. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator.
Official Microsoft reference: Microsoft Foundry agents - development lifecycle
NEW QUESTION # 35
You have a multi-agent Retrieval-Augmented Generation (RAG) solution that uses a Foundry IQ knowledge base. The solution includes a support agent and a policy agent.
You have an evaluation dataset that contains the following for each user query
* The expected source IDs
* Retrieved chunks in rank order
* The final agent response
You discover that an embedding model change and a custom analyzer change cause the failed traces shown in the following table.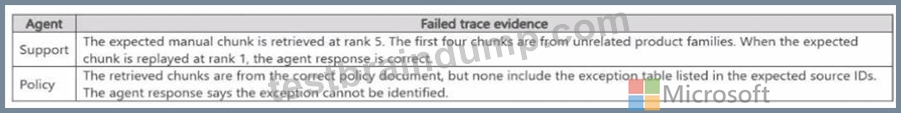
You need to isolate the failing parts of the RAG pipeline.
Which evaluator should you use for each agent? To answer, drag the appropriate evaluators to the correct agents. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.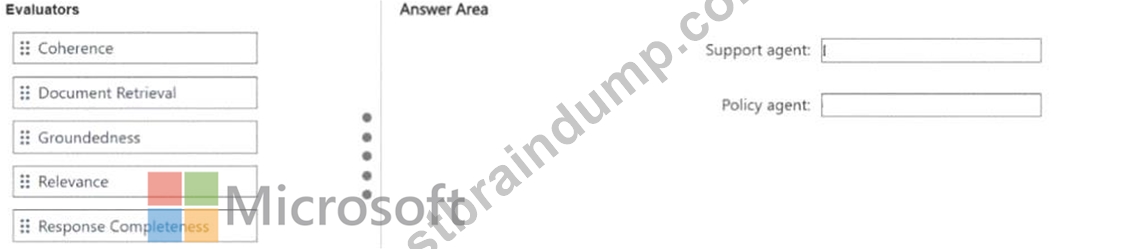
Answer:
Explanation:
Explanation:
Support agent: Document Retrieval; Policy agent: Document Retrieval.
Both failures are retrieval failures and should therefore be diagnosed with the Document Retrieval evaluator.
The dataset includes expected source IDs and ranked retrieved chunks, which provides the retrieval ground truth required by that evaluator. For the support agent, the expected source appears too low in the ranking after unrelated chunks. For the policy agent, the required exception-table source is missing entirely.
Groundedness would evaluate whether the final response is supported by the context it actually received; it could therefore pass even when the retrieval stage failed to fetch a required source. Microsoft Foundry ' s Document Retrieval evaluator compares retrieved documents against labeled ground truth and reports ranking
/search metrics such as NDCG and Fidelity. The corrected answer is Document Retrieval for both agents. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators
NEW QUESTION # 36
You have a Microsoft Foundry project that contains a multi-agent customer support solution. The solution includes a final response agent.
You need to provide reviewers with the ability to assess agent responses in the preview web app and record a completion score for each agent response. The solution must follow the principle of least privilege.
Which roles should you assign to the reviewers?
Answer: D
Explanation:
Microsoft ' s human-evaluation guidance for the Foundry preview web app requires reviewers to have Foundry User permissions on the project plus Reader access on the Foundry account/resource. That combination gives the reviewer enough project-level access to open the agent experience and record evaluation feedback while avoiding project-management or account-management privileges. Application Insights Reader alone only grants telemetry visibility and does not provide the Foundry interaction permissions needed to score responses. Foundry User alone does not satisfy the documented account-level visibility requirement for this preview experience. Foundry Project Manager would be broader than necessary and violate the least-privilege objective. Therefore C is the documented reviewer role combination. The same configuration should be paired with auditable identity, trace, and evaluation data so reviewers can prove which principal acted, which policy was applied, and why a request was allowed or blocked. That is particularly important for production multi-agent systems with external tools. Least privilege remains the governing principle: grant only the identity, data, tool, or deployment access required for the specific operation. The selected answer preserves that boundary while still allowing the workflow to satisfy its functional requirement.
Official Microsoft reference: Microsoft Foundry - Human evaluation
NEW QUESTION # 37
You have a Microsoft Foundry agent that completes benefits enrollment during a single user conversation The agent collects the required enrollment fields during 15 turns. Users can correct earlier values before final submission. The current implementation sends the complete transcript with every model request.
You need to change the context accumulation strategy for the active enrollment. The solution must meet the following requirements:
* Preserve the latest value for each required enrollment field until submission.
* Bound the maximum number of tokens sent with each model request
* Preserve user corrections until submission.
* Prevent durable cross-session memory.
What should you do?
Answer: C
Explanation:
The application must preserve the latest authoritative value of each enrollment field even when the user corrects an earlier value, while also placing a firm bound on prompt size. A session-scoped enrollment-state snapshot provides deterministic structured state: each correction overwrites the previous field value. A recent- turn sliding window then preserves enough conversational context for natural interaction without resending the full 15-turn transcript. Response chaining with a fixed number of prior turns can lose an important field once it falls outside the retained history. Summarization can omit or distort corrected values, and automatic truncation likewise offers no guarantee that the latest value of every required field survives. Because the state is scoped only to the active enrollment and is not written to long-term memory, the design also avoids durable cross-session memory. Therefore A is correct. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Microsoft Agent Framework - workflow state and context management
NEW QUESTION # 38
......
Improvement in AI-500 science and technology creates unassailable power in the future construction and progress of society. As we can see, the rapid progression of the whole world is pushing people forward and the competitiveness among people who are fighting on the first line is growing intensely. Numerous advantages of AI-500 training materials are well-recognized, such as 99% pass rate in the exam, free trial before purchasing, secure privacy protection and so forth. From the customers’ point of view, our AI-500 Test Question put all candidates’ demands as the top priority. We treasure every customer’ reliance and feedback to the optimal AI-500 practice test.
Online AI-500 Tests: https://www.testbraindump.com/AI-500-exam-prep.html
P.S. Free & New AI-500 dumps are available on Google Drive shared by TestBraindump: https://drive.google.com/open?id=1OYKwfi1G_I7hpj-42IJ1hg8EYB8vuIyb