2026 Latest Exam4Labs AI-300 PDF Dumps and AI-300 Exam Engine Free Share: https://drive.google.com/open?id=1wL99DwpbNcEPihOXbGagb0LQeJUvpZbG
Keep making progress is a very good thing for all people. If you try your best to improve yourself continuously, you will that you will harvest a lot, including money, happiness and a good job and so on. The AI-300 preparation exam from our company will help you keep making progress. Choosing our AI-300 Study Material, you will find that it will be very easy for you to overcome your shortcomings and become a persistent person. Just come and buy our AI-300 learning guide!
| Section | Weight | Objectives |
|---|---|---|
| Implement generative AI quality assurance and observability | 10–15% | - Monitor generative AI systems
|
| Design and implement a GenAIOps infrastructure | 20–25% | - Set up Microsoft Foundry environment
|
| Implement machine learning model lifecycle and operations | 25–30% | - Deploy models to production
|
| Optimize generative AI systems and model performance | 15–20% | - Optimize model selection and configuration
|
| Design and implement an MLOps infrastructure | 15–20% | - Create and manage Machine Learning workspace resources and assets
|
>> Reliable AI-300 Study Notes <<
Before clients buy our AI-300 questions torrent they can download them and try out them freely. The pages of our product provide the demo and the aim is to let the client know part of our titles before their purchase and what form our AI-300 guide torrent is. You can visit our website and read the pages of our product. The pages introduce the quantity of our questions and answers of our AI-300 Guide Torrent, the time of update, the versions for you to choose and the price of our product. After you try out the free demo you could decide whether our AI-300 exam torrent is worthy to buy or not. So you needn’t worry that you will waste your money or our AI-300 exam torrent is useless and boosts no values.
NEW QUESTION # 125
A team is validating a generative AI assistant for a company. The assistant generates responses by using internal knowledge sources.
The company requires assurance that responses are accurate, supported by sources, and related to the user prompts before enabling production access.
You need to implement quality metrics that confirm the assistant produces reliable and meaningful responses.
Which two evaluation metrics should you use? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: B,C
Explanation:
To ensure your Azure Machine Learning generative AI assistant (which utilizes a Retrieval- Augmented Generation or RAG architecture) produces reliable and meaningful responses before going live, you should use the RAG Triad of built-in quality evaluation metrics.
These primary automated metrics-Groundedness, Relevance, and Response Completeness- directly measure accuracy, connection to internal knowledge sources, and alignment with user prompts.
The Primary Metrics (The RAG Triad)
These metrics are evaluated on a 1-to-5 scale using Azure Machine Learning's built-in, AI- assisted "LLM-as-a-judge" evaluators:
Groundedness: Measures how well the assistant's generated answer aligns only with the information retrieved from your internal knowledge sources. Even if a response is factually correct in the real world, it is penalized if the information cannot be verified inside the retrieved context document. This is your primary defense against hallucinations.
Relevance: Assesses how pertinently the model's generated response directly addresses the user's specific prompt. This checks whether the system understood the user's intent or if it provided an off-topic or distracted response.
Response Completeness: Focuses on the "recall" aspect of the assistant. It measures whether the generated text effectively answers all parts of the user prompt using the ground truth data, ensuring no critical insights or data points are omitted.
Reference:
https://medium.com/thedeephub/a-deep-dive-into-evaluation-in-azure-prompt-flow-dd898ebb158c
NEW QUESTION # 126
You manage a Retrieval-Augmented Generation (RAG) system that uses Azure AI Search to retrieve documents from an indexed knowledge base.
The system must support the following retrieval requirements:
Queries that include exact policy identifiers must return matching documents even when semantic similarity is low.
Natural-language questions must prioritize semantically relevant documents even when keywords are not an exact match.
You need to configure the retrieval approach to meet the requirements.
How should you configure the retrieval behavior for each requirement? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.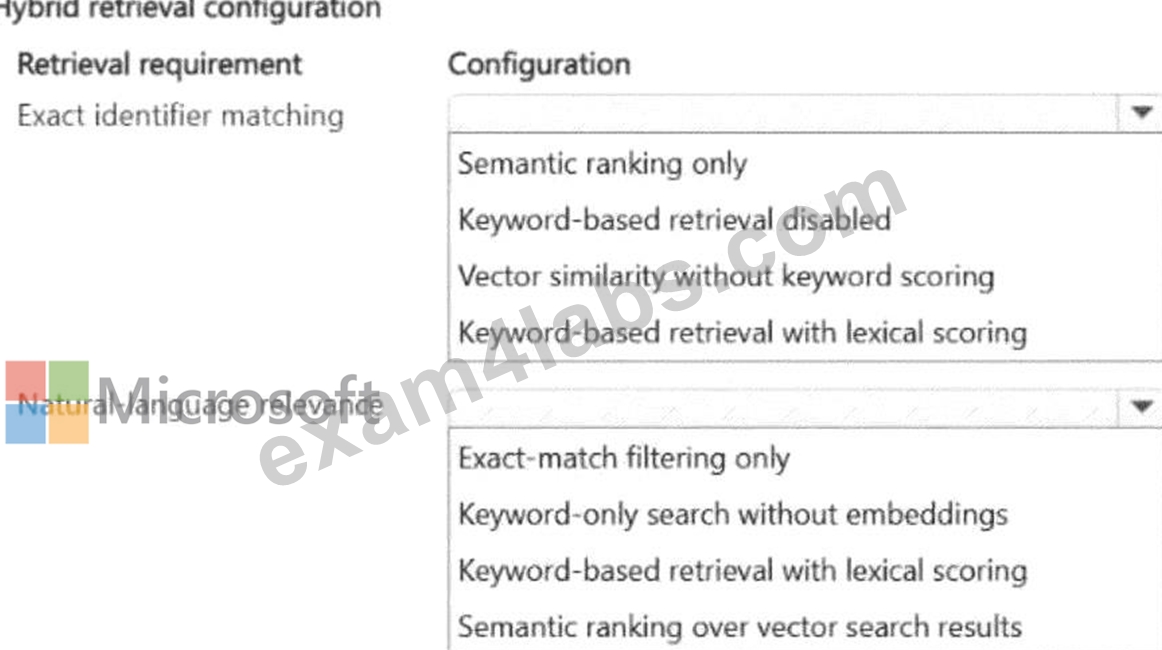
Answer:
Explanation: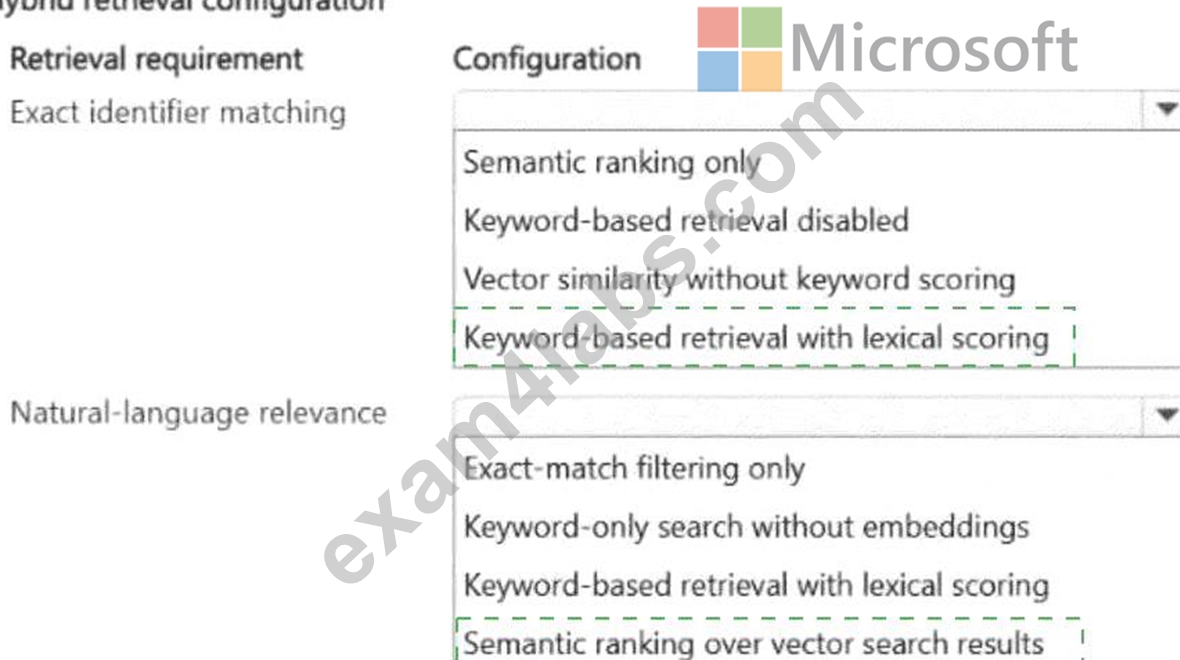
Explanation:
Different query types require fundamentally different retrieval algorithms. For queries that include exact policy identifiers, keyword or BM25 search is the correct choice because BM25 scores documents based on term frequency and inverse document frequency - an exact match on a specific policy identifier such as POL-
2024-HR-042 scores very highly regardless of semantic context. This is the right approach when semantic similarity is low but exact term matching is critical. For natural-language questions where keywords may not be an exact match, semantic or vector search is the correct choice because vector embeddings capture meaning rather than exact tokens, finding relevant documents even when the user ' s vocabulary differs from the document ' s terminology. Azure AI Search supports both modes through its hybrid search capability, and the correct configuration maps each query type to its optimal retrieval algorithm.
Microsoft Learn Reference Topic: Configure hybrid search in Azure AI Search - BM25 keyword search vs.
semantic vector search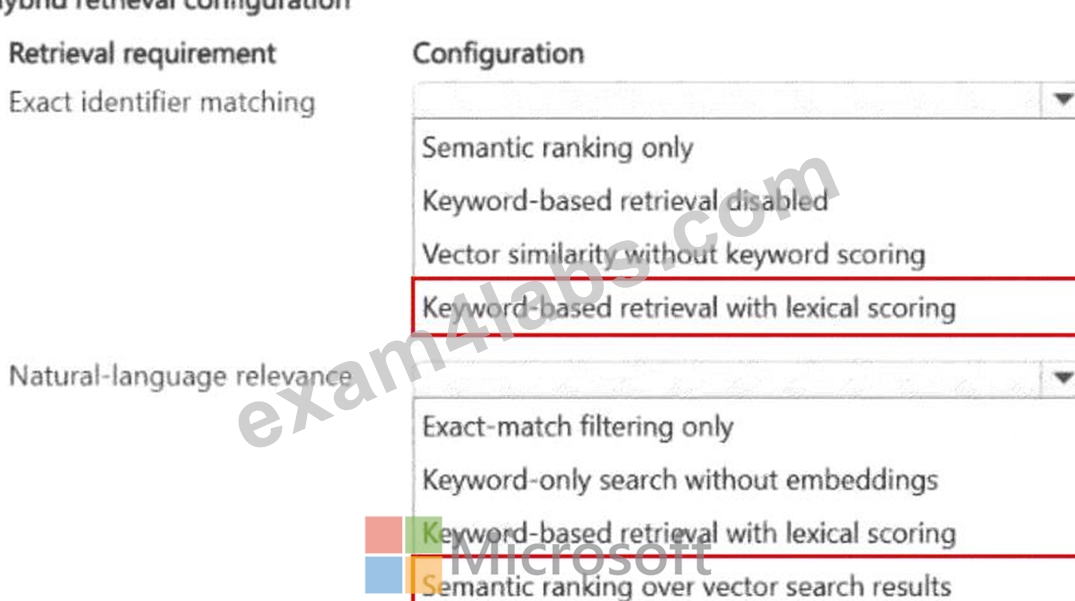
NEW QUESTION # 127
Hotspot Question
You manage an Azure Machine Learning workspace named workspace1.
You must register an Azure Blob storage datastore in workspace1 by using an access key. You develop Python SDK v2 code to import all modules required to register the datastore.
You need to complete the Python SDK v2 code to define the datastore.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.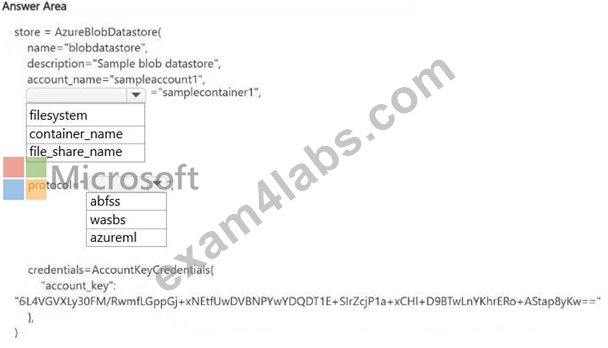
Answer:
Explanation: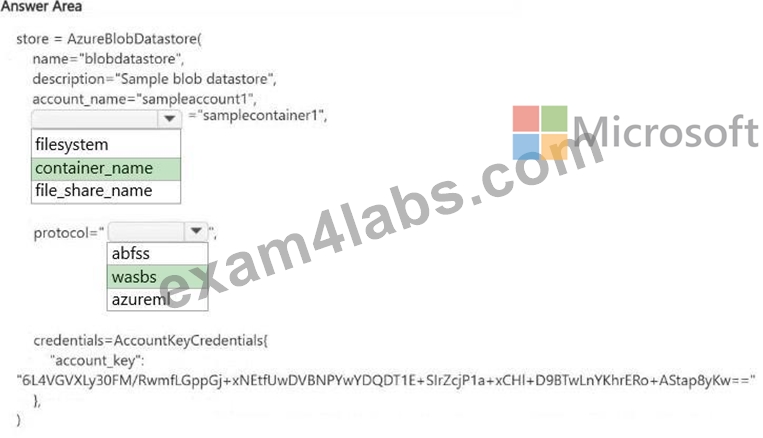
Explanation:
How should you complete the code?
Box 1: container_name
container_name specifies the parameter name used in the AzureBlobDatastore constructor to identify your target blob storage container.
Box 2: wasbs
Correct Code Formats
Depending on your preference for the storage connection protocol, your completed line of code should look like one of the following variations:
Using the standard HTTPS protocol (Default).
-> Using the WASBS (Windows Azure Storage Blob Secure).
Reference:
https://stackoverflow.com/questions/75275875/create-an-azureblobdatastore-with-sdk-v2
NEW QUESTION # 128
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You work in Microsoft Foundry with a prompt flow.
You must manually evaluate prompts and compare results across prompt variants.
You need to capture the inputs, outputs, token usage, and latencies for each flow run for the evaluation.
Solution: Use the prompt flow SDK to enable tracing for the flow before executing runs. Then run the flow to generate traceable results.
Does the solution meet the goal?
Answer: A
Explanation:
Enabling tracing via the prompt flow SDK alone does not guarantee that all four required dimensions - inputs, outputs, token usage, and latencies - are captured and surfaced in the Microsoft Foundry portal ' s trace viewer in a way that allows manual comparison across runs. While the prompt flow SDK does support tracing configuration, the portal-based Tracing activation is the complete, supported path for this specific capture requirement. The correct and complete solution as confirmed by the next question in this series is to use the Tracing toggle directly in the Microsoft Foundry portal for the project, then execute test runs. This portal-side Tracing feature is purpose-built to instrument all four dimensions and store them in a queryable trace store accessible through the Foundry interface.
Microsoft Learn Reference Topic: Enable tracing for prompt flows in Microsoft Foundry portal - Capturing run telemetry
NEW QUESTION # 129
A real-time endpoint experiences sporadic latency spikes. Investigation reveals instances scale down to zero during inactivity. You need to reduce latency without significantly increasing cost.
What should you configure?
Answer: B
NEW QUESTION # 130
......
Our Operationalizing Machine Learning and Generative AI Solutions (AI-300) practice exam simulator mirrors the AI-300 exam experience, so you know what to anticipate on AI-300 certification exam day. Our Operationalizing Machine Learning and Generative AI Solutions (AI-300) practice test software features various question styles and levels, so you can customize your Microsoft AI-300 exam questions preparation to meet your needs.
Reliable AI-300 Test Cram: https://www.exam4labs.com/AI-300-practice-torrent.html
BTW, DOWNLOAD part of Exam4Labs AI-300 dumps from Cloud Storage: https://drive.google.com/open?id=1wL99DwpbNcEPihOXbGagb0LQeJUvpZbG