Reliable Databricks-Certified-Data-Analyst-Associate Actualtest bring you Verified Visual Databricks-Certified-Data-Analyst-Associate Cert Exam for Databricks Databricks Certified Data Analyst Associate Exam

BTW, DOWNLOAD part of PassExamDumps Databricks-Certified-Data-Analyst-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1ziSRoeAjJi2Q7vD5BiJ4yGiWbzCLRGSc
We aim to provide our candidates with real Databricks vce dumps and learning materials to help you pass real exam with less time and money. Our valid Databricks-Certified-Data-Analyst-Associate top questions are written by our IT experts who are specialized in Databricks-Certified-Data-Analyst-Associate Study Guide for many years and check the updating of Databricks-Certified-Data-Analyst-Associate vce files everyday to make sure the best preparation material for you.
| Section | Weight | Objectives |
|---|
| Topic 1: Analyzing Queries | 15% | - Query Analysis
- 1. Monitoring Query Execution
- 2. Reading Query Plans
- 3. Performance Tuning
|
| Topic 2: Securing Data | 8% | - Security and Access Control
- 1. Data Access Policies
- 2. Unity Catalog Security
- 3. Permissions and Roles
|
| Topic 3: Creating Dashboards and Visualizations | 16% | - Visualization
- 1. Dashboards
- 2. Charts and Graphs
- 3. Alerts and Filters
- 4. Sharing and Publishing
|
| Topic 4: Managing Data | 8% | - Data Management
- 1. Handling Missing and Invalid Data
- 2. Discovering Data Assets
- 3. Tagging and Lineage
- 4. Cleaning Data with SQL
|
| Topic 5: Importing Data | 5% | - Data Import
- 1. Uploading Files
- 2. Loading CSV and JSON Data
- 3. Creating Tables from Imported Data
|
| Topic 6: Understanding of Databricks Data Intelligence Platform | 11% | - Platform Components
- 1. Lakeflow Jobs
- 2. Mosaic AI
- 3. Databricks SQL
- 4. Delta Lake
- 5. Unity Catalog
- Catalog and Governance
- 1. Catalogs and Schemas
- 2. Data Lineage
- 3. Views and Certified Tables
- 4. Managed and External Tables
|
| Topic 7: Data Modeling with Databricks SQL | 5% | - Modeling Concepts
- 1. Data Organization
- 2. Fact and Dimension Tables
- 3. Views and Relationships
|
| Topic 8: Developing AI/BI Genie Spaces | 12% | - AI and BI Features
- 1. Natural Language Queries
- 2. AI/BI Genie
- 3. Workspace Configuration
|
| Topic 9: Executing Queries Using Databricks SQL and SQL Warehouses | 20% | - SQL Querying
- 1. Query Optimization
- 2. SQL Warehouses
- 3. Writing SQL Queries
- 4. Filtering and Aggregation
- 5. Joins and Subqueries
|
>> Databricks-Certified-Data-Analyst-Associate Actualtest <<
Visual Databricks-Certified-Data-Analyst-Associate Cert Exam & Databricks-Certified-Data-Analyst-Associate Reliable Exam Camp
It is known to us that having a good job has been increasingly important for everyone in the rapidly developing world; it is known to us that getting a Databricks Certified Data Analyst Associate Exam certification is becoming more and more difficult for us. That is the reason that I want to introduce you our Databricks-Certified-Data-Analyst-Associate prep torrent. I promise you will have no regrets about reading our introduction. I believe that after you try our products, you will love it soon, and you will never regret it when you buy it.
Databricks Certified Data Analyst Associate Exam Sample Questions (Q11-Q16):
NEW QUESTION # 11
Which of the following should data analysts consider when working with personally identifiable information (PII) data?
- A. Organization-specific best practices for Pll data
- B. None of these considerations
- C. All of these considerations
- D. Legal requirements for the area in which the data was collected
- E. Legal requirements for the area in which the analysis is being performed
Answer: C
Explanation:
Data analysts should consider all of these factors when working with PII data, as they may affect the data security, privacy, compliance, and quality. PII data is any information that can be used to identify a specific individual, such as name, address, phone number, email, social security number, etc. PII data may be subject to different legal and ethical obligations depending on the context and location of the data collection and analysis. For example, some countries or regions may have stricter data protection laws than others, such as the General Data Protection Regulation (GDPR) in the European Union. Data analysts should also follow the organization-specific best practices for PII data, such as encryption, anonymization, masking, access control, auditing, etc. These best practices can help prevent data breaches, unauthorized access, misuse, or loss of PII data. References:
* How to Use Databricks to Encrypt and Protect PII Data
* Automating Sensitive Data (PII/PHI) Detection
* Databricks Certified Data Analyst Associate
NEW QUESTION # 12
Consider the following two statements:
Statement 1:
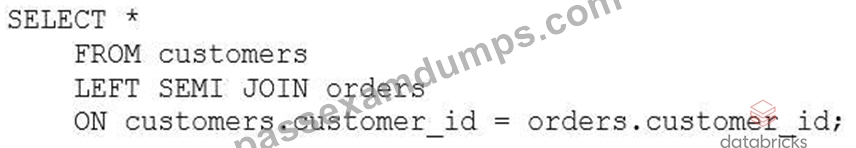
Statement 2:
Which of the following describes how the result sets will differ for each statement when they are run in Databricks SQL?
- A. The first statement will return all data from the customers table and matching data from the orders table. The second statement will return all data from the orders table and matching data from the customers table. Any missing data will be filled in with NULL.
- B. Both statements will fail because Databricks SQL does not support those join types.
- C. There is no difference between the result sets for both statements.
- D. When the first statement is run, only rows from the customers table that have at least one match with the orders table on customer_id will be returned. When the second statement is run, only those rows in the customers table that do not have at least one match with the orders table on customer_id will be returned.
- E. When the first statement is run, all rows from the customers table will be returned and only the customer_id from the orders table will be returned. When the second statement is run, only those rows in the customers table that do not have at least one match with the orders table on customer_id will be returned.
Answer: D
Explanation:
Based on the images you sent, the two statements are SQL queries for different types of joins between the customers and orders tables. A join is a way of combining the rows from two table references based on some criteria. The join type determines how the rows are matched and what kind of result set is returned. The first statement is a query for a LEFT SEMI JOIN, which returns only the rows from the left table reference (customers) that have a match with the right table reference (orders) on the join condition (customer_id). The second statement is a query for a LEFT ANTI JOIN, which returns only the rows from the left table reference (customers) that have no match with the right table reference (orders) on the join condition (customer_id).
Therefore, the result sets for the two statements will differ in the following way:
* The first statement will return a subset of the customers table that contains only the customers who have placed at least one order. The number of rows returned will be less than or equal to the number of rows in the customers table, depending on how many customers have orders. The number of columns returned will be the same as the number of columns in the customers table, as the LEFT SEMI JOIN does not include any columns from the orders table.
* The second statement will return a subset of the customers table that contains only the customers who have not placed any order. The number of rows returned will be less than or equal to the number of rows in the customers table, depending on how many customers have no orders. The number of columns returned will be the same as the number of columns in the customers table, as the LEFT ANTI JOIN does not include any columns from the orders table.
The other options are not correct because:
* A. The first statement will not return all data from the customers table, as it will exclude the customers who have no orders. The second statement will not return all data from the orders table, as it will exclude the orders that have a matching customer. Neither statement will fill in any missing data with NULL, as they do not return any columns from the other table.
* C. There is a difference between the result sets for both statements, as explained above. The LEFT SEMI JOIN and the LEFT ANTI JOIN are not equivalent operations and will produce different outputs.
* D. Both statements will not fail, as Databricks SQL does support those join types. Databricks SQL supports various join types, including INNER, LEFT OUTER, RIGHT OUTER, FULL OUTER, LEFT SEMI, LEFT ANTI, and CROSS. You can also use NATURAL, USING, or LATERAL keywords to specify different join criteria.
* E. The first statement will not return only the customer_id from the orders table, as it will return all columns from the customers table. The second statement is correct, but it is not the only difference between the result sets.
References: JOIN | Databricks on AWS, JOIN - Azure Databricks - Databricks SQL | Microsoft Learn, array_join function | Databricks on AWS, Hints | Databricks on AWS
NEW QUESTION # 13
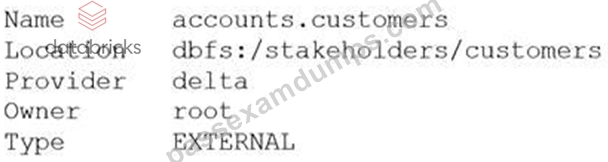
After running DESCRIBE EXTENDED accounts.customers;, the following was returned:
Now, a data analyst runs the following command:
DROP accounts.customers;
Which of the following describes the result of running this command?
- A. The accounts.customers table is removed from the metastore, but the underlying data files are untouched.
- B. The accounts.customers table is removed from the metastore, and the underlying data files are deleted.
- C. Running SELECT * FROM accounts.customers will return all rows in the table.
- D. Running SELECT * FROM delta. `dbfs:/stakeholders/customers` results in an error.
- E. All files with the .customers extension are deleted.
Answer: A
Explanation:
the accounts.customers table is an EXTERNAL table, which means that it is stored outside the default warehouse directory and is not managed by Databricks. Therefore, when you run the DROP command on this table, it only removes the metadata information from the metastore, but does not delete the actual data files from the file system. This means that you can still access the data using the location path (dbfs:/stakeholders
/customers) or create another table pointing to the same location. However, if you try to query the table using its name (accounts.customers), you will get an error because the table no longer exists in the metastore. References: DROP TABLE | Databricks on AWS, Best practices for dropping a managed Delta Lake table - Databricks
NEW QUESTION # 14
A data analyst has created a Query in Databricks SQL, and now wants to create two data visualizations from that Query and add both of those data visualizations to the same Databricks SQL Dashboard.
Which step will the data analyst need to take when creating and adding both data visualizations to the Databricks SQL Dashboard?
- A. Copy the Query and create one data visualization per query.
- B. Decide on a single data visualization to add to the dashboard.
- C. Add two separate visualizations to the dashboard based on the same Query.
- D. Alter the Query to return two separate sets of results.
Answer: C
Explanation:
Databricks SQL allows you to create multiple visualizations from a single query result. These visualizations can be customized independently and each can be added to a dashboard. This feature is explicitly supported and recommended in Databricks' documentation on dashboards and visualization workflows, enabling flexible reporting without duplicating queries.
NEW QUESTION # 15
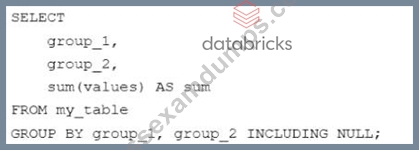
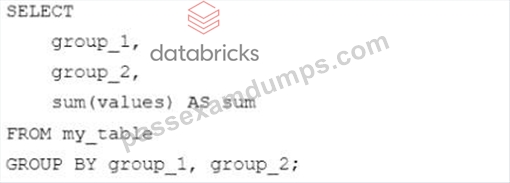
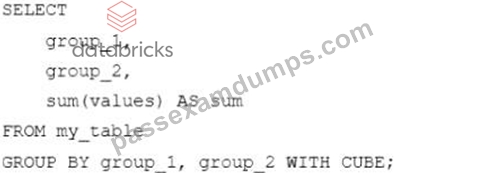
A data analyst is processing a complex aggregation on a table with zero null values and the query returns the following result:
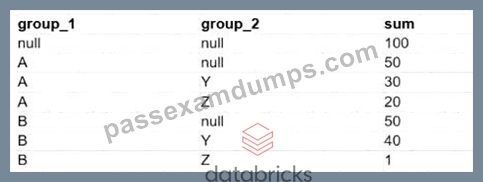
Which query did the analyst execute in order to get this result?
Answer: C
Explanation:
Option D is correct because the table has zero real null values, but the result contains null values representing subtotal and grand-total rows. That behavior is produced by WITH CUBE, which creates aggregations for combinations of grouping columns, including (group_1, group_2), (group_1), (group_2), and the grand total ().
The Databricks SQL documentation states that GROUP BY supports advanced aggregations through CUBE, and that CUBE is shorthand for grouping sets. Option A only returns detailed groups. Options B and C use invalid syntax in Databricks SQL. Reference: Databricks GROUP BY clause documentation.
NEW QUESTION # 16
......
In this era of the latest technology, we should incorporate interesting facts, figures, visual graphics, and other tools that can help people read the Databricks Certified Data Analyst Associate Exam (Databricks-Certified-Data-Analyst-Associate) exam questions with interest. PassExamDumps uses pictures that are related to the Databricks Certified Data Analyst Associate Exam (Databricks-Certified-Data-Analyst-Associate) certification exam and can even add some charts, and graphs that show the numerical values. It will not let the reader feel bored with the Databricks Certified Data Analyst Associate Exam (Databricks-Certified-Data-Analyst-Associate) practice test. They can engage their attention in the Databricks Databricks-Certified-Data-Analyst-Associate exam visual effects and pictures that present a lot of.
Visual Databricks-Certified-Data-Analyst-Associate Cert Exam: https://www.passexamdumps.com/Databricks-Certified-Data-Analyst-Associate-valid-exam-dumps.html
- Databricks Databricks-Certified-Data-Analyst-Associate Dumps PDF - Right Preparation Method [2026] 🏌 Easily obtain free download of ✔ Databricks-Certified-Data-Analyst-Associate ️✔️ by searching on ⏩ www.pdfdumps.com ⏪ 👇Reliable Databricks-Certified-Data-Analyst-Associate Braindumps
- Databricks-Certified-Data-Analyst-Associate Clearer Explanation 🦓 Databricks-Certified-Data-Analyst-Associate Valid Exam Dumps 🎇 Databricks-Certified-Data-Analyst-Associate Latest Exam Book 😿 The page for free download of ➡ Databricks-Certified-Data-Analyst-Associate ️⬅️ on [ www.pdfvce.com ] will open immediately 🦹Databricks-Certified-Data-Analyst-Associate Latest Exam Book
- Databricks-Certified-Data-Analyst-Associate Detailed Study Dumps 🙎 Databricks-Certified-Data-Analyst-Associate Training For Exam 👹 New Databricks-Certified-Data-Analyst-Associate Exam Preparation 😟 Copy URL ▛ www.practicevce.com ▟ open and search for ⇛ Databricks-Certified-Data-Analyst-Associate ⇚ to download for free 🐶Reliable Databricks-Certified-Data-Analyst-Associate Braindumps
- New Databricks-Certified-Data-Analyst-Associate Exam Preparation 🔶 Databricks-Certified-Data-Analyst-Associate Latest Exam Book 🥱 Reliable Databricks-Certified-Data-Analyst-Associate Braindumps 🚟 Easily obtain free download of ☀ Databricks-Certified-Data-Analyst-Associate ️☀️ by searching on ▶ www.pdfvce.com ◀ ☁Authentic Databricks-Certified-Data-Analyst-Associate Exam Questions
- New Databricks-Certified-Data-Analyst-Associate Test Cram 🧜 Databricks-Certified-Data-Analyst-Associate Certification Training 😲 Exam Databricks-Certified-Data-Analyst-Associate Vce 🚞 Go to website [ www.pdfdumps.com ] open and search for 「 Databricks-Certified-Data-Analyst-Associate 」 to download for free 🙃Databricks-Certified-Data-Analyst-Associate Test Centres
- Reliable Databricks-Certified-Data-Analyst-Associate Braindumps 🏹 Databricks-Certified-Data-Analyst-Associate Detailed Study Dumps 🥜 New Databricks-Certified-Data-Analyst-Associate Exam Preparation ⏸ { www.pdfvce.com } is best website to obtain ➡ Databricks-Certified-Data-Analyst-Associate ️⬅️ for free download 🐆Databricks-Certified-Data-Analyst-Associate Dumps Torrent
- Latest Databricks-Certified-Data-Analyst-Associate Exam Test 😸 Databricks-Certified-Data-Analyst-Associate Detailed Study Dumps 🍲 New Databricks-Certified-Data-Analyst-Associate Test Cram ☎ Open website ➥ www.validtorrent.com 🡄 and search for ✔ Databricks-Certified-Data-Analyst-Associate ️✔️ for free download 👄Databricks-Certified-Data-Analyst-Associate Exam Paper Pdf
- Databricks-Certified-Data-Analyst-Associate Detailed Study Dumps ☂ Databricks-Certified-Data-Analyst-Associate Clearer Explanation 🌭 New Databricks-Certified-Data-Analyst-Associate Test Cram 🔐 Search on ▶ www.pdfvce.com ◀ for ▷ Databricks-Certified-Data-Analyst-Associate ◁ to obtain exam materials for free download ⭕Databricks-Certified-Data-Analyst-Associate Pdf Demo Download
- 100% Pass Databricks-Certified-Data-Analyst-Associate - Databricks Certified Data Analyst Associate Exam –Valid Actualtest 🌕 Search for ⇛ Databricks-Certified-Data-Analyst-Associate ⇚ and obtain a free download on ▷ www.pass4test.com ◁ 🪔Databricks-Certified-Data-Analyst-Associate Latest Exam Book
- Databricks-Certified-Data-Analyst-Associate Detailed Study Dumps 🔕 Databricks-Certified-Data-Analyst-Associate Training For Exam 🗾 Databricks-Certified-Data-Analyst-Associate Dumps Torrent ⏏ Easily obtain free download of ✔ Databricks-Certified-Data-Analyst-Associate ️✔️ by searching on 「 www.pdfvce.com 」 🕰Databricks-Certified-Data-Analyst-Associate Valid Exam Dumps
- Databricks-Certified-Data-Analyst-Associate torrent vce - Databricks-Certified-Data-Analyst-Associate latest dumps - Databricks-Certified-Data-Analyst-Associate practice pdf 🅰 Open ▛ www.prepawaypdf.com ▟ and search for ⏩ Databricks-Certified-Data-Analyst-Associate ⏪ to download exam materials for free 🖤Valid Databricks-Certified-Data-Analyst-Associate Test Materials
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
What's more, part of that PassExamDumps Databricks-Certified-Data-Analyst-Associate dumps now are free: https://drive.google.com/open?id=1ziSRoeAjJi2Q7vD5BiJ4yGiWbzCLRGSc