お客様は、AI-300試験問題を迅速に受けることができます。クライアントは、製品のバージョンを選択し、正しいメールに記入し、AI-300有用なテストガイドの料金を支払うだけです。その後、彼らは5〜10分でメールを受け取ります。クライアントがリンクをクリックすると、すぐにAI-300学習資料を使用できます。クライアントがメールを受信できない場合は、オンラインカスタマーサービスに連絡して、問題の解決を支援します。購入手順は簡単で、AI-300学習ツールの配布は迅速です。
| Section | Objectives |
|---|---|
| Topic 1: Design and implement generative AI solutions | - Large language model integration
|
| Topic 2: Plan and design AI solutions using Azure AI services | - Requirements gathering and solution architecture
|
| Topic 3: Operationalizing machine learning solutions | - Deployment and monitoring
|
| Topic 4: Implement secure and scalable AI systems | - Scalability and performance optimization
|
弊社は、当社のAI-300試験エンジンを学習ツールとして使用する方法で、候補者とのさらなる協力を目指して、大きな集中的な進歩を遂げました。 AI-300試験軍隊により多くの人々が参加することで、私たちは国際市場でトップクラスのトレーニング資料プロバイダーになりました。 さらに、私たちは常に「相互開発と利益」の原則を順守し、学習の過程で必要なときはいつでもAI-300実践教材がタイムリーで効果的な支援を提供できると信じています。
質問 # 105
An organization is deploying generative AI solutions by using Microsoft Foundry to support multiple production workloads.
The organization has the following workload requirements:
* One workload must be real-time, latency-sensitive, and have predictable global usage patterns that demand consistent performance.
* One workload must have variable performance and be optimized for cost-efficient operation.
You need to select a global deployment type for each workload.
Which type of deployment should you use for each workload requirement? To answer, move the appropriate deployment types to the correct requirements. You may use each deployment type once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.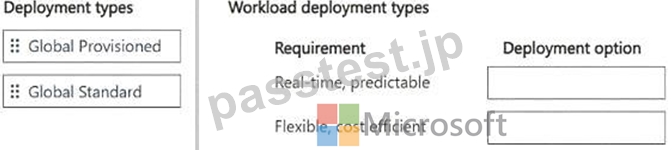
正解:
解説: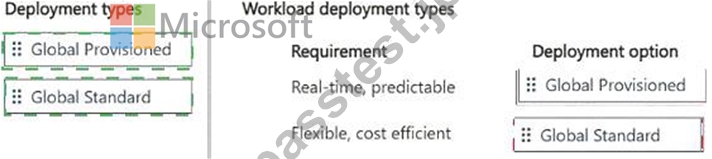
Explanation:
Real-time, predictable: Global Provisioned
Flexible, cost efficient: Global Standard
For the real-time, latency-sensitive workload with predictable global demand , use Global Provisioned .
Microsoft Foundry defines Global Provisioned deployments as providing reserved model processing capacity and predictable throughput through provisioned throughput units (PTUs). Because capacity is reserved, this deployment type provides lower and more consistent latency than Global Standard and is specifically recommended for sustained, predictable, high-throughput production workloads.
For the workload requiring flexibility and cost-efficient operation , use Global Standard . Global Standard operates on a pay-per-token model and dynamically routes requests across Azure ' s global infrastructure.
Microsoft recommends it as the starting deployment type for most workloads because it offers the lowest price, broad regional availability, and high default quota without requiring the customer to reserve PTU capacity. This makes it appropriate when demand varies and paying for permanently reserved throughput would be inefficient.
The architectural distinction is therefore straightforward: Global Provisioned trades reserved-capacity cost for predictable throughput and reduced latency variance, while Global Standard provides elastic, consumption-based operation with greater latency variability under sustained high load. Microsoft's deployment overview likewise identifies provisioned throughput for predictable low-latency performance and standard deployment for general hosted workloads.
Study Guide Reference: Design and implement a GenAIOps infrastructure - Microsoft Foundry deployment types, Global Standard, Global Provisioned, PTUs, latency predictability, throughput, and cost optimization.
質問 # 106
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a mid-sized healthcare analytics company that provides population health dashboards and predictive insights to regional hospital systems across the United States.
Fabrikam Inc. customers rely on near real time analytics to monitor patient flow, staffing needs, and readmission risks. They use multiple traditional forecasting machine learning models for predictions.
Fabrikam Inc. has an established Microsoft Azure footprint. The company uses Jupyter Notebooks that run on a local server as the primary development environment. The data science team is experiencing scalability, asset management and code management issues with the current development platform. Fabrikam Inc. plans to migrate to a cloud-based development environment to mitigate the issues.
Additionally, the company plans to implement a Retrieval-Augmented Generation (RAG)-based chat application for client support. Leadership requires the application to be developed and deployed with a low operational risk.
Current Environment
Fabrikam Inc. operates a single Azure subscription that has the following components:
* Azure Data Lake Storage Gen2 that contains de-identified clinical and operational datasets
* Azure AI Search indexing curated analytical documents and reference materials
* A small set of Python-based training scripts maintained by data scientists
* Azure OpenAI Service with deployed foundational models
* A Microsoft Foundry resource for building a RAG-based solution
Evaluation data has manually defined expected responses.
The current challenges faced by the data science team include the following:
* Model training jobs are run manually from notebooks.
* Experiment tracking is inconsistent
* Model versions are registered without standardized metadata.
* Deployment is performed manually by data scientists, with limited rollback capability.
* The team has no standardized evaluation process for generative AI outputs.
The environment currently allows public network access. Authentication relies on user accounts rather than managed identities. Compute targets are manually created and shared across experiments. This has led to resource contention during peak usage.
Business Requirements
Fabrikam Inc. has the following business requirements for the modernization initiative:
* Provide a conversational interface that answers analytics questions by using internal documents and datasets.
* Ensure that sensitive healthcare-related data is not exposed outside the Fabrikam Inc. Azure tenant.
* Enable repeatable and auditable model training and deployment processes.
* Support experimentation to compare prompt strategies and fine-tuned models.
* Align the model with the ranked preferences and optimize behavior for the long term.
* Minimize disruption to existing analytics workloads during rollout.
Technical Requirements
To support the business goals, Fabrikam Inc. identifies these technical requirements:
* Use Azure Machine Learning workspaces to centrally manage data assets, models, and environments.
* Implement experiment tracking and model versioning for all training jobs.
* Orchestrate training and evaluation by using pipelines rather than manually running notebooks.
* Deploy traditional machine learning models with support for staged rollout and rollback.
* Improve RAG-based solution output quality.
* Use the existing evaluation datasets that are based on real data with input-output pairs.
* Apply advanced fine-tuning techniques only when prompt engineering is insufficient Issues and Constraints Fabrikam Inc. must comply with internal security policies that require the company to restrict network access and avoid long-lived secrets. The data science team has limited Azure DevOps experience, so solutions must favor managed services and automation over custom infrastructure.
Cost predictability is important. Leadership prefers serverless or managed compute options where possible but is willing to approve dedicated compute for stable production workloads.
Problem Statement
Fabrikam Inc. must design and implement an Azure-based AI operations solution that enables reliable training, evaluation, deployment, and iteration of generative AI models. The solution must support experimentation and gradual rollout while ensuring governance, security, and operational stability. The data science and platform teams must collaborate to deliver this solution by using Azure Machine Learning and Microsoft Foundry capabilities.
You need to standardize how Fabrikam Inc. manages machine learning assets. Which action should you perform first?
正解:D
解説:
Scenario: To support the business goals, Fabrikam Inc. identifies these technical requirements:
Use Azure Machine Learning workspaces to centrally manage data assets, models, and environments.
To centrally manage data assets, models, and environments across multiple Azure Machine Learning workspaces, you should Create a shared Azure Machine Learning workspace first.
The workspace serves as the top-level resource for your machine learning activities, providing a centralized place to view and manage the artifacts you create. While Registries are used to share assets (like models and environments) across existing workspaces, you must have a workspace as a prerequisite to create or use those assets in a project context.
Key Management Options
Azure provides several ways to organize and centralize your machine learning operations:
Shared Workspace: The primary container for managing data, compute, and experiments within a project team.
Registries: Used specifically for MLOps to decouple assets from specific workspaces, allowing them to be promoted through development, test, and production environments.
Hub Workspaces: A newer feature that groups multiple project workspaces under a single "hub" to share security settings, connections, and compute resources.
Reference:
https://docs.azure.cn/en-us/machine-learning/concept-workspace
質問 # 107
A Retrieval-Augmented Generation (RAG) solution returns incomplete answers because relevant content is inconsistently retrieved from the knowledge source.
You need to improve RAG accuracy without changing the embedding model currently in use. You need to achieve this goal while minimizing operational costs.
Which two actions should you perform? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point. Choose two .
正解:C、D
解説:
Microsoft ' s RAG optimization guidance identifies two high-impact, low-cost improvements for retrieval quality that do not require changing the embedding model. First, tuning chunk size and overlap (option A):
chunk size determines how much context each retrieved piece contains - too large and irrelevant content dilutes the signal; too small and answers may be split across chunks. Adjusting these parameters requires only re-indexing the documents with zero additional compute cost. Second, implementing a re-ranker (option B): a re-ranker is a cross-encoder model that takes the top-N retrieved chunks and re-scores them based on their specific relevance to the query, significantly improving precision by filtering out contextually irrelevant chunks. Re-rankers add modest compute cost but are far cheaper than changing the embedding model, which would require re-embedding the entire knowledge base. Increasing token limits (option C) and optimizing embedding vector length (option D) do not address retrieval accuracy without an embedding model change.
Microsoft Learn Reference Topic: Optimize RAG pipelines - Chunk size tuning and re-ranking in Azure AI Search and Azure Machine Learning
質問 # 108
Drag and Drop Question
You manage an Azure Machine Learning workspace. You train a model named model1.
You must identify the features to modify for a differing model prediction result.
You need to configure the Responsible AI (RAI) dashboard for model1.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.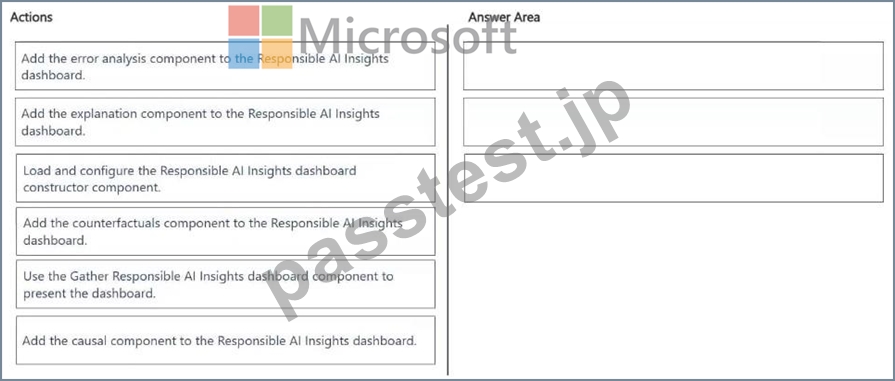
正解:
解説: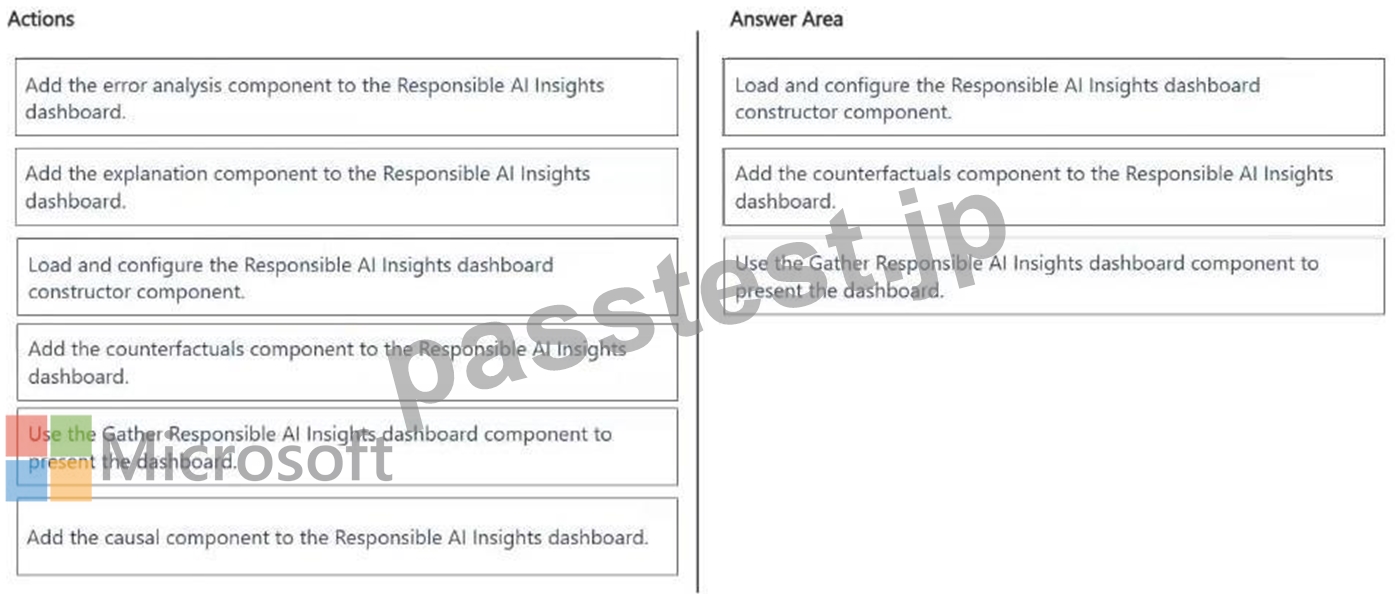
Explanation:
To setup the Responsible AI (RAI) dashboard in Azure Machine Learning and specifically analyze minimal feature modifications needed to change a prediction result, you must use Counterfactual Analysis.
Here are the specific sequential steps you need to take:
Step 1: Load and configure the Responsible AI Insights dashboard constructor component.
Initialize the RAI Insights Dashboard Constructor
1. Create the root pipeline component that acts as the container for your tools.
2. Call the RAI Insights dashboard constructor component.
3. Pass your registered model and your test dataset as the mandatory inputs to this component.
Step 2: Add the Counterfactuals to Responsible AI Insights dashboard
Configure Counterfactual Analysis
1. Add the specific component required to identify what features to modify for a differing prediction.
2. Call the Add Counterfactuals to RAI Insights dashboard component.
3. Link its input to the output of the constructor component initialized in Step 1 above.
4. Configure the parameter variables, including the number of counterfactual examples you want to generate per data point.
Step 3: Use the Gather Responsible AI Insights dashboard component to present the dashboard.
Assemble and Submit the Dashboard Pipeline
1. Gather the components into a cohesive Azure ML pipeline job to execute them.
-> 2. Call the Gather RAI Insights dashboard component to aggregate the constructor and the counterfactual tool outputs.
3. Submit the pipeline job to your Azure Machine Learning workspace compute cluster for processing.
Reference:
https://oneuptime.com/blog/post/2026-02-16-how-to-implement-responsible-ai-dashboards-in-azure-machine-learning/view
質問 # 109
A team deploys a classification model to production and scores incoming customer data daily.
After several weeks, business stakeholders report unexpected changes in prediction behavior, even though the endpoint remains healthy.
You need to determine whether data drift is occurring and if it is, identify the appropriate actions.
Which action should you perform for each observed signal? To answer, move the appropriate actions to the correct observed signals. You may use each action once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.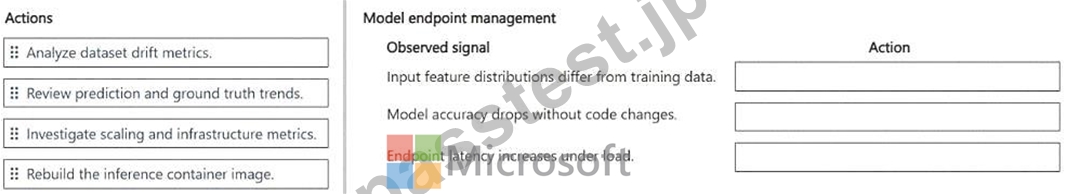
正解:
解説: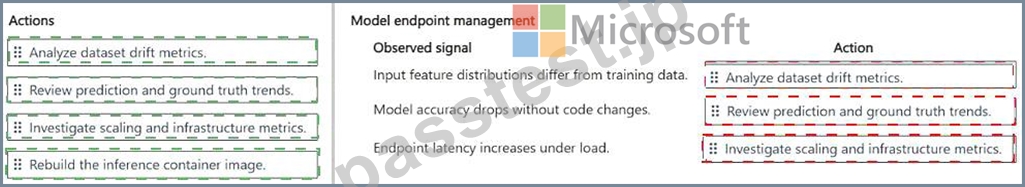
Explanation:
Input feature distributions differ from training data: Analyze dataset drift metrics Model accuracy drops without code changes: Review prediction and ground truth trends Endpoint latency increases under load: Investigate scaling and infrastructure metrics When input feature distributions differ from training data , the correct action is to analyze dataset drift metrics . Azure Machine Learning model monitoring detects data drift by comparing the statistical distributions of production model inputs against reference data, commonly the original training dataset.
Supported measures include Population Stability Index, Jensen-Shannon distance, normalized Wasserstein distance, and statistical tests such as Kolmogorov-Smirnov.
When model accuracy drops without code changes , the next investigation should focus on prediction and ground-truth trends . Azure Machine Learning model-performance monitoring compares production predictions with collected actual outcomes and can calculate classification metrics such as accuracy, precision, and recall. A declining score without deployment changes may indicate concept drift, prediction drift, or changing relationships between input features and target outcomes.
When endpoint latency increases under load , the issue is operational rather than primarily statistical. The team should investigate scaling and infrastructure metrics , including request latency, requests per minute, CPU/memory utilization, throttling, and replica capacity. Microsoft recommends using endpoint metrics to determine whether compute must scale up or out.
Rebuild the inference container image is not indicated by any of the observed signals.
Study Guide Reference: Implement machine learning model lifecycle and operations - production monitoring, data drift, model-performance monitoring, endpoint observability, and scaling.
質問 # 110
......
私たちのウェブサイトから見ると、AI-300学習教材は3つのバージョンがあります。PDF、ソフトウェアとオンライン版です。AI-300 PDF版は印刷できます。ソフトウェアとオンライン版はコンピュータで使用できます。コンピュータで学ぶことが難しい場合は、AI-300学習教材の印刷資料で勉強できます。また、AI-300学習教材の価格は合理的に設定されています。
AI-300関連復習問題集: https://www.passtest.jp/Microsoft/AI-300-shiken.html