P.S. Free & New Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by ITdumpsfree: https://drive.google.com/open?id=1N4r7MmlOcho8MEUvsCNV-5MU_IDX1MR3
To find better job opportunities you have to learn new and in-demand skills and upgrade your knowledge. With the Databricks Certified Generative AI Engineer Associate Databricks-Generative-AI-Engineer-Associate Exam you can do this job nicely and quickly. To do this you just need to get registered in the ITdumpsfree Databricks Certified Generative AI Engineer Associate exam and put all your efforts to pass this challenging Databricks Certified Generative AI Engineer Associate exam with good scores. However, you should keep in mind that the Databricks Certified Generative AI Engineer Associate exam is a valuable credential and will play an important role in your career advancement
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Generative AI Engineer Associate |
| Exam Number: | Databricks-Generative-AI-Engineer-Associate |
| Exam Price: | USD 200 |
| Available Languages: | English |
| Exam Format: | Multiple choice, Multiple select |
| Certificate Validity Period: | 2 years |
| Real Exam Qty: | 45-60 |
| Exam Duration: | 90 minutes |
| Related Certifications: | Databricks Certified Data Engineer Associate Databricks Certified Machine Learning Associate |
| Recommended Training: | Mosaic AI Documentation Databricks Academy - Generative AI Courses |
| Exam Registration: | Databricks Certification Portal |
| Sample Questions: | Databricks Databricks-Generative-AI-Engineer-Associate Sample Questions |
| Exam Way: | Online proctored exam |
| Pre Condition: | No strict prerequisites, but experience with Python, machine learning fundamentals, and Databricks platform is recommended. |
| Official Syllabus URL: | https://www.databricks.com/learn/certification |
>> Databricks-Generative-AI-Engineer-Associate Training Pdf <<
Desktop Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) practice exam software also keeps track of the earlier attempted Databricks Databricks-Generative-AI-Engineer-Associate practice test so you can know mistakes and overcome them at each and every step. The Desktop Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) practice exam software is created and updated in a timely by a team of experts in this field. If any problem arises, a support team is there to fix the issue.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 75
A company has a typical RAG-enabled, customer-facing chatbot on its website.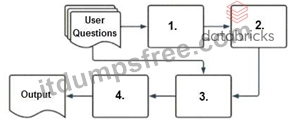
Select the correct sequence of components a user's questions will go through before the final output is returned. Use the diagram above for reference.
Answer: C
Explanation:
To understand how a typical RAG-enabled customer-facing chatbot processes a user's question, let's go through the correct sequence as depicted in the diagram and explained in option A:
* Embedding Model (1):The first step involves the user's question being processed through an embedding model. This model converts the text into a vector format that numerically represents the text. This step is essential for allowing the subsequent vector search to operate effectively.
* Vector Search (2):The vectors generated by the embedding model are then used in a vector search mechanism. This search identifies the most relevant documents or previously answered questions that are stored in a vector format in a database.
* Context-Augmented Prompt (3):The information retrieved from the vector search is used to create a context-augmented prompt. This step involves enhancing the basic user query with additional relevant information gathered to ensure the generated response is as accurate and informative as possible.
* Response-Generating LLM (4):Finally, the context-augmented prompt is fed into a response- generating large language model (LLM). This LLM uses the prompt to generate a coherent and contextually appropriate answer, which is then delivered as the final output to the user.
Why Other Options Are Less Suitable:
* B, C, D: These options suggest incorrect sequences that do not align with how a RAG system typically processes queries. They misplace the role of embedding models, vector search, and response generation in an order that would not facilitate effective information retrieval and response generation.
Thus, the correct sequence isembedding model, vector search, context-augmented prompt, response- generating LLM, which is option A.
NEW QUESTION # 76
A Generative AI Engineer has created a RAG application which can help employees retrieve answers from an internal knowledge base, such as Confluence pages or Google Drive. The prototype application is now working with some positive feedback from internal company testers. Now the Generative Al Engineer wants to formally evaluate the system's performance and understand where to focus their efforts to further improve the system.
How should the Generative AI Engineer evaluate the system?
Answer: D
Explanation:
* Problem Context: After receiving positive feedback for the RAG application prototype, the next step is to formally evaluate the system to pinpoint areas for improvement.
* Explanation of Options:
* Option A: While cosine similarity scores are useful, they primarily measure similarity rather than the overall performance of an RAG system.
* Option B: This option provides a systematic approach to evaluation by testing both retrieval and generation components separately. This allows for targeted improvements and a clear understanding of each component's performance, using MLflow's metrics for a structured and standardized assessment.
* Option C: Benchmarking multiple LLMs does not focus on evaluating the existing system's components but rather on comparing different models.
* Option D: Using an LLM as a judge is subjective and less reliable for systematic performance evaluation.
OptionBis the most comprehensive and structured approach, facilitating precise evaluations and improvements on specific components of the RAG system.
NEW QUESTION # 77
A Generative Al Engineer is using an LLM to classify species of edible mushrooms based on text descriptions of certain features. The model is returning accurate responses in testing and the Generative Al Engineer is confident they have the correct list of possible labels, but the output frequently contains additional reasoning in the answer when the Generative Al Engineer only wants to return the label with no additional text.
Which action should they take to elicit the desired behavior from this LLM?
Answer: D
Explanation:
The LLM classifies mushroom species accurately but includes unwanted reasoning text, and the engineer wants only the label. Let's assess how to control output format effectively.
* Option A: Use few shot prompting to instruct the model on expected output format
* Few-shot prompting provides examples (e.g., input: description, output: label). It can work but requires crafting multiple examples, which is effort-intensive and less direct than a clear instruction.
* Databricks Reference:"Few-shot prompting guides LLMs via examples, effective for format control but requires careful design"("Generative AI Cookbook").
* Option B: Use zero shot prompting to instruct the model on expected output format
* Zero-shot prompting relies on a single instruction (e.g., "Return only the label") without examples. It's simpler than few-shot but may not consistently enforce succinctness if the LLM's default behavior is verbose.
* Databricks Reference:"Zero-shot prompting can specify output but may lack precision without examples"("Building LLM Applications with Databricks").
* Option C: Use zero shot chain-of-thought prompting to prevent a verbose output format
* Chain-of-Thought (CoT) encourages step-by-step reasoning, which increases verbosity-opposite to the desired outcome. This contradicts the goal of label-only output.
* Databricks Reference:"CoT prompting enhances reasoning but often results in detailed responses"("Databricks Generative AI Engineer Guide").
* Option D: Use a system prompt to instruct the model to be succinct in its answer
* A system prompt (e.g., "Respond with only the species label, no additional text") sets a global instruction for the LLM's behavior. It's direct, reusable, and effective for controlling output style across queries.
* Databricks Reference:"System prompts define LLM behavior consistently, ideal for enforcing concise outputs"("Generative AI Cookbook," 2023).
Conclusion: Option D is the most effective and straightforward action, using a system prompt to enforce succinct, label-only responses, aligning with Databricks' best practices for output control.
NEW QUESTION # 78
A Generative AI Engineer is managing prompt templates using MLflow v3.x for a document summarization pipeline. A regulatory audit requires the team to demonstrate exactly which prompt version was used to generate outputs on a specific date three months ago, including the exact prompt text and any variables used at that time.
Which combination of MLflow v3.x capabilities allows the engineer to satisfy this audit requirement?
Answer: A
Explanation:
The Prompt Registry preserves identifiable prompt versions, allowing the team to recover the exact template associated with a historical execution. Linking inference activity to the prompt's name and version establishes which registered template the application actually used. MLflow also supports lineage between prompt versions, application versions, and execution traces. However, satisfying the entire audit requires retaining the actual runtime variable values or the fully rendered prompt in the relevant execution records. Registry history alone preserves the template, not every value substituted into it. Therefore, D is the best option, provided the logging captures those inputs. Model webhooks, experiment tags, or table history alone do not provide the same explicit prompt-version lineage and complete historical reconstruction. Databricks documentation
NEW QUESTION # 79
A Generative Al Engineer would like an LLM to generate formatted JSON from emails. This will require parsing and extracting the following information: order ID, date, and sender email. Here's a sample email: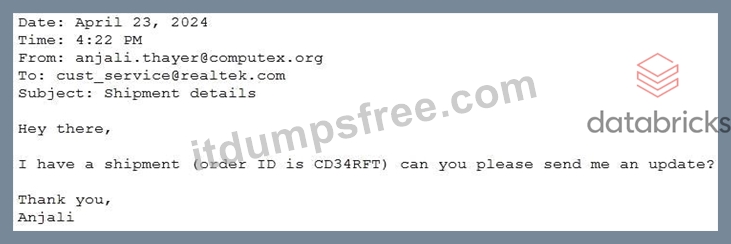
They will need to write a prompt that will extract the relevant information in JSON format with the highest level of output accuracy.
Which prompt will do that?
Answer: A
Explanation:
Problem Context: The goal is to parse emails to extract certain pieces of information and output this in a structured JSON format. Clarity and specificity in the prompt design will ensure higher accuracy in the LLM' s responses.
Explanation of Options:
* Option A: Provides a general guideline but lacks an example, which helps an LLM understand the exact format expected.
* Option B: Includes a clear instruction and a specific example of the output format. Providing an example is crucial as it helps set the pattern and format in which the information should be structured, leading to more accurate results.
* Option C: Does not specify that the output should be in JSON format, thus not meeting the requirement.
* Option D: While it correctly asks for JSON format, it lacks an example that would guide the LLM on how to structure the JSON correctly.
Therefore,Option Bis optimal as it not only specifies the required format but also illustrates it with an example, enhancing the likelihood of accurate extraction and formatting by the LLM.
NEW QUESTION # 80
......
New Databricks-Generative-AI-Engineer-Associate Exam Papers: https://www.itdumpsfree.com/Databricks-Generative-AI-Engineer-Associate-exam-passed.html
What's more, part of that ITdumpsfree Databricks-Generative-AI-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1N4r7MmlOcho8MEUvsCNV-5MU_IDX1MR3