我相信不論在哪個行業工作的人都希望自己有很好的職業前景。當然在競爭激烈的IT行業裏面也不例外。在IT行業中工作的專業人士也希望自己有個很好的提升機會和很大的提升空間。很多專業的IT人士都知道Microsoft DP-750 認證考試可以幫你滿足這些願望的。而VCESoft是一個能幫助你成功通過Microsoft DP-750 的網站。
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Prepare and process data | 30-35% | - Ingest and transform data
|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
根據過去的考試題和答案的研究,VCESoft提供的Microsoft DP-750練習題和真實的考試試題有緊密的相似性。VCESoft是可以承諾您能100%通過你第一次參加的Microsoft DP-750 認證考試。
問題 #89
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Sales. Sales stores transaction data and contains the following columns:
* transactionjd (string)
* transaction date (date)
* amount (decimal)
You need to implement the following data quality requirements by using table-level data quality enforcement:
* amount must be greater than 0.
* transaction id must never be null.
* Invalid records must be rejected when data is written to the Sales table.
What should you do?
答案:B
解題說明:
The correct answer is D - a NOT NULL constraint on transaction_id and a CHECK constraint on amount.
Delta Lake table constraints are enforced at write time by the Delta engine itself. A NOT NULL constraint rejects any INSERT or UPDATE that would place a null in transaction_id. A CHECK constraint with amount
> 0 rejects any row where amount is zero or negative. Combined, they implement exactly the stated quality rules: bad rows are rejected when data is written, not filtered away at read time.
Options A and C (SELECT with WHERE / views) are read-time constructs - they don't prevent invalid data from entering the table. A clever pipeline bypass could write directly to the table and skip the view entirely.
Option B (row-level security with WHERE conditions) is an access-control feature for restricting which rows users see, not for enforcing data quality on writes. Table constraints are the only mechanism that genuinely blocks bad data at the storage layer.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-constraints
問題 #90
You have an Azure Databricks workspace.
You have an Azure key vault named kv-secure that stores a secret named storageKey. The value of storageKey is managed and updated by the cloud security team at your company.
You need to enable a Databricks notebook named Notebook 1 to retrieve the value of storageKey securely at runtime. The solution must follow the principle of least privilege and always retrieve the latest value.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.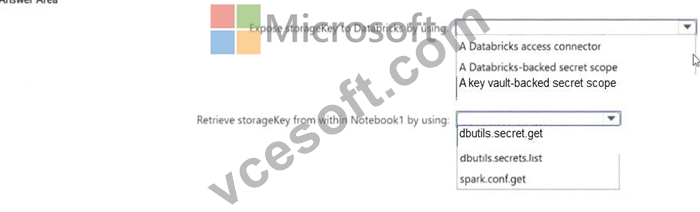
答案:
解題說明: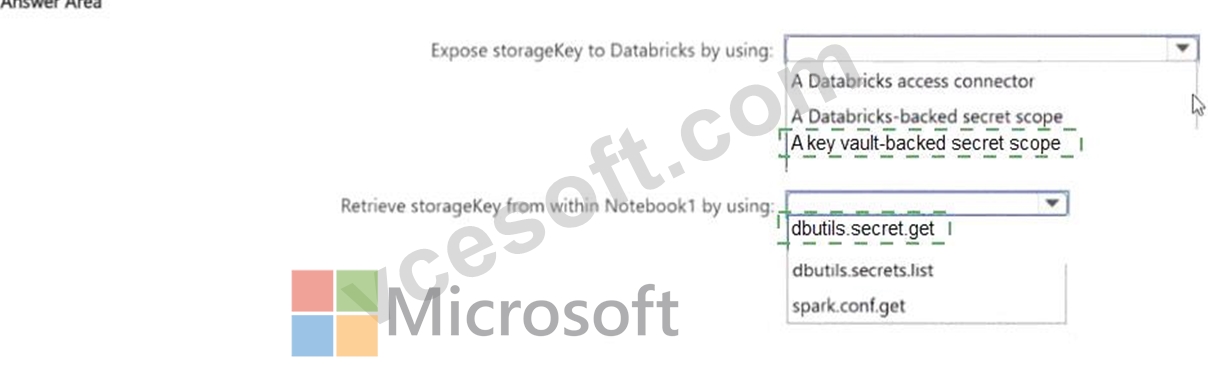
Explanation:
The solution is a Key Vault-backed secret scope combined with dbutils.secrets.get() in the notebook.
An Azure Key Vault-backed secret scope does not copy the secret value into Databricks. Every call to dbutils.
secrets.get() fetches the live current value directly from Key Vault at runtime. This means when the cloud security team rotates storageKey in Key Vault, the notebook automatically picks up the new value on its next run - no Databricks configuration changes needed. That satisfies 'always retrieve the latest value.' The principle of least privilege is upheld because only the secret scope has read access to Key Vault through a service principal or managed identity, and individual users never see the raw secret value - Databricks redacts it in logs automatically.
A Databricks-backed scope stores a copy of the secret inside Databricks, so it wouldn't automatically reflect Key Vault updates. Hardcoding or using environment variables would expose the secret in plain text.
Reference: https://learn.microsoft.com/en-us/azure/databricks/security/secrets/secret-scopes
問題 #91
You have an Azure Databricks workspace that uses Databricks SQL.
You have a table named sales_goals_source that contains the following columns:
* Salesperson
* Item
* 2019
* 2020
* 2021
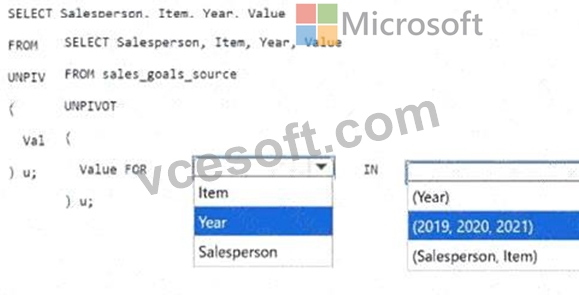
You need to transform the year columns into rows and return the columns Salesperson, Item, Year, and Value.
How should you complete the SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
SELECT Salesperson, Item, Year, Value
FROM sales_goals_source
UNPIVOT
(
Value FOR [first dropdown] IN [second dropdown]
);
答案:
解題說明: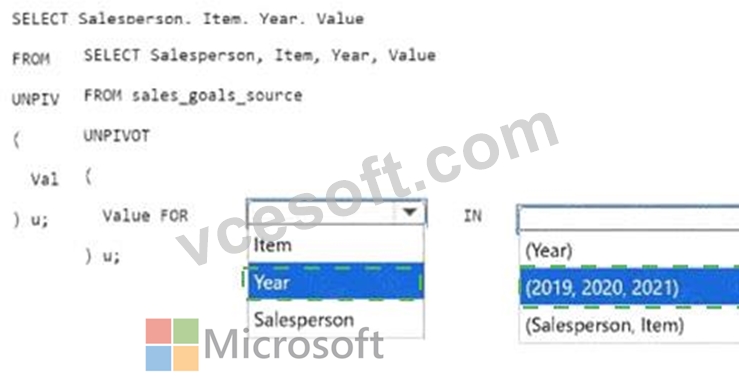
Explanation:
First dropdown: Year
Second dropdown: (2019, 2020, 2021)
The UNPIVOT operator converts the separate 2019, 2020, and 2021 columns into rows. Value becomes the output column containing the values previously stored in those year columns. Year becomes the output name column that identifies the original column from which each value came. Therefore, the expression must use Value FOR Year IN (2019, 2020, 2021). The Salesperson and Item columns are not included in the IN list because they remain identifier columns and are repeated for every resulting year row. A single source row consequently produces three output rows-one for each listed year. Selecting (Year) would reference an output name rather than the source columns that must be rotated.
問題 #92
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.filter(df.order_amount != None)
Does this meet the goal?
答案:A
解題說明:
The correct answer is B - No.
This is a common Python-to-PySpark trap. In pure Python, comparing a value to None with != works as expected. In PySpark, null comparisons follow SQL null semantics: any comparison involving NULL returns NULL (not True or False). So df.filter(df.order_amount != None) doesn't evaluate to True for non-null rows
- the comparison itself returns NULL for null values, and Spark interprets NULL in a filter as False, effectively dropping null rows. But the behaviour is undefined in edge cases and is not the documented approach.
More practically, Python's None and Spark's SQL NULL are different concepts. PySpark Column objects don't support Python's native equality/inequality semantics for null checking. The result is typically an empty DataFrame or incorrect filtering behaviour.
Always use .isNotNull() or .isNull() for null checks in PySpark column expressions. These methods are specifically designed for SQL-null-aware comparisons and produce correct, predictable results.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
問題 #93
You need to complete the PySpark code for the Spark Structured Streaming pipelines. The solution must meet the data ingestion and processing requirements.
How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.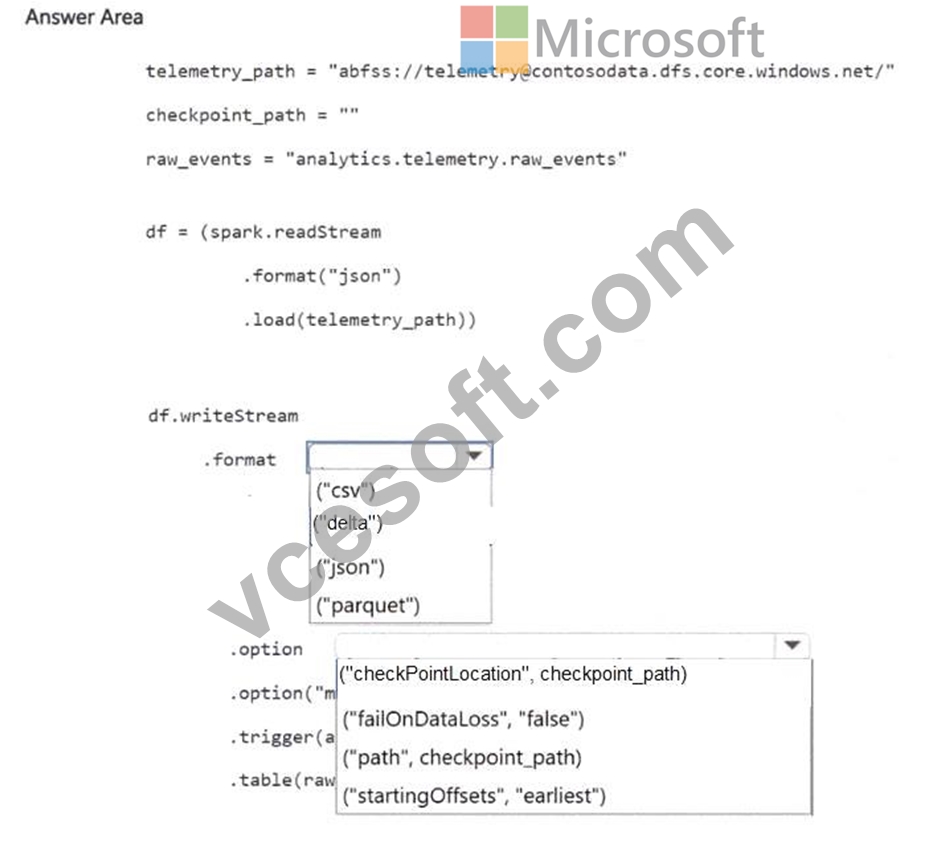
答案:
解題說明: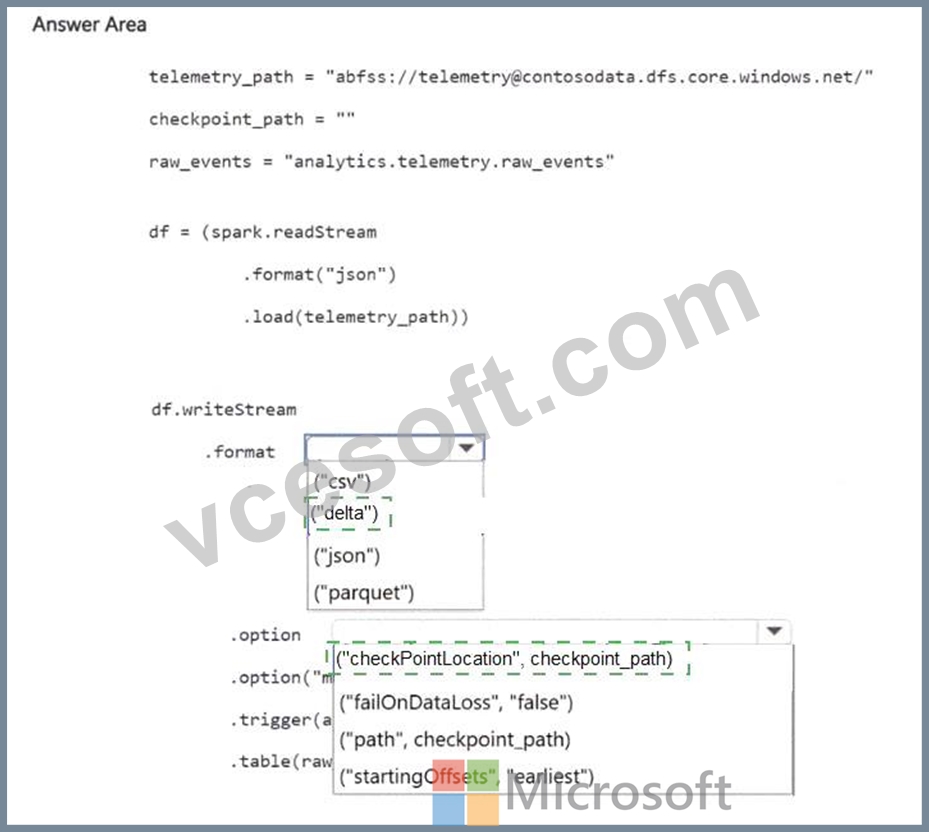
Explanation:
The solution requires spark.readStream with format('cloudFiles') for Auto Loader, paired with .writeStream using mergeSchema=true and a checkpointLocation.
Auto Loader's cloudFiles source incrementally processes new JSON files without rescanning the entire directory. The mergeSchema option handles schema drift - when sensors add new fields, the target Delta table schema expands automatically instead of throwing a parse error. This directly addresses Contoso's requirement to 'support schema drift.' The checkpointLocation is what gives the pipeline its resilience. Databricks writes the stream's committed offset and schema state to that path. If the cluster restarts, the engine reads the checkpoint and picks up exactly where it left off - no events are reprocessed, satisfying 'exactly-once semantics' and 'resume processing after failures without reprocessing the data.' Without a checkpoint, the stream would restart from the beginning on every cluster bounce, which is precisely the problem Contoso is trying to eliminate.
Reference: https://learn.microsoft.com/en-us/azure/databricks/ingestion/auto-loader/schema
問題 #94
......
這幾年IT行業發展非常之迅速,那麼學IT的人也如洪水猛獸般迅速多了起來,他們為了使自己以後有所作為而不斷的努力,Microsoft的DP-750考試認證是IT行業必不可少的認證,許多人為想通過此認證而感到苦惱。今天我告訴大家一個好辦法,就是選擇VCESoft Microsoft的DP-750考試認證培訓資料,它可以幫助你們通過考試獲得認證,而且我們可以保證通過率100%,如果沒有通過,我們將保證退還全部購買費用,不讓你們有任何損失。
DP-750試題: https://www.vcesoft.com/DP-750-pdf.html