P.S. Free 2026 Microsoft DP-100 dumps are available on Google Drive shared by CertkingdomPDF: https://drive.google.com/open?id=17DBuriqrLF1NaYOHJ2bqCzs8tuHvB-a3
Allowing for your problems about passing the exam, our experts made all necessary points into our DP-100 training materials, making it the most efficient way to achieve success. They can alleviate your pressure, relieve you of tremendous knowledge and master the key points with the least time. As customer-oriented company, we believe in satisfying the customers at any costs. Instead of focusing on profits, we determined to help every customer harvest desirable outcomes by our DP-100 Training Materials. So our staff and after-sales sections are regularly interacting with customers for their further requirements and to know satisfaction levels of them.
| Section | Objectives |
|---|---|
| Optimize and manage models | - Track experiments and manage model lifecycle - Improve model performance |
| Deploy and consume models | - Monitor deployed models and endpoints - Deploy models to endpoints |
| Explore and analyze data | - Ingest and prepare data for modeling - Perform exploratory data analysis |
| Design and prepare a machine learning solution | - Plan and configure Azure Machine Learning workspace - Select appropriate Azure services for machine learning workloads - Manage compute and data assets |
| Train machine learning models | - Train models using Azure Machine Learning - Tune hyperparameters and evaluate models |
CertkingdomPDF gives a guarantee to our customers that they can pass the Microsoft DP-100 Certification Exam on the first try by preparing from the CertkingdomPDF and if they fail to pass it despite their efforts they can claim their payment back as per terms and conditions. CertkingdomPDF facilitates customers with a 24/7 support system which means whenever they get stuck somewhere they don't struggle and contact the support system which will assist them in the right way. A lot of students have prepared from practice material and rated it positively.
NEW QUESTION # 189
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are using Azure Machine Learning to run an experiment that trains a classification model.
You want to use Hyperdrive to find parameters that optimize the AUC metric for the model. You configure a HyperDriveConfig for the experiment by running the following code: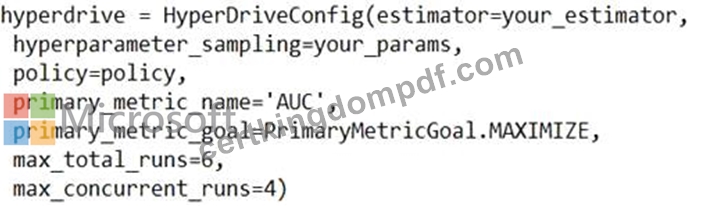
You plan to use this configuration to run a script that trains a random forest model and then tests it with validation data. The label values for the validation data are stored in a variable named y_test variable, and the predicted probabilities from the model are stored in a variable named y_predicted.
You need to add logging to the script to allow Hyperdrive to optimize hyperparameters for the AUC metric.
Solution: Run the following code: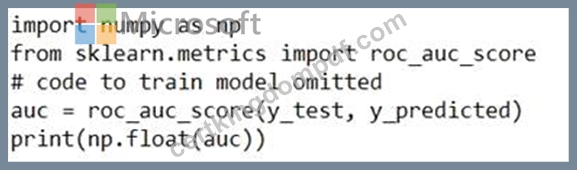
Does the solution meet the goal?
Answer: A
Explanation:
Explanation
Use a solution with logging.info(message) instead.
Note: Python printing/logging example:
logging.info(message)
Destination: Driver logs, Azure Machine Learning designer
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-debug-pipelines
NEW QUESTION # 190
You create a binary classification model. The model is registered in an Azure Machine Learning workspace. You use the Azure Machine Learning Fairness SDK to assess the model fairness.
You develop a training script for the model on a local machine.
You need to load the model fairness metrics into Azure Machine Learning studio.
What should you do?
Answer: B
Explanation:
import azureml.contrib.fairness package to perform the upload:
from azureml.contrib.fairness import upload_dashboard_dictionary, download_dashboard_by_upload_id Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-machine-learning-fairness-aml
NEW QUESTION # 191
You manage an Azure Machine Learning workspace named workspace1.
You must register an Azure Blob storage datastore in workspace1 by using an access key. You develop Python SDK v2 code to import all modules required to register the datastore.
You need to complete the Python SDK v2 code to define the datastore.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.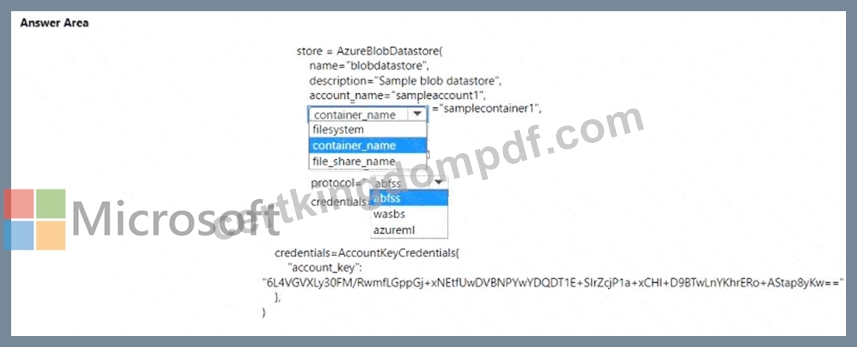
Answer:
Explanation: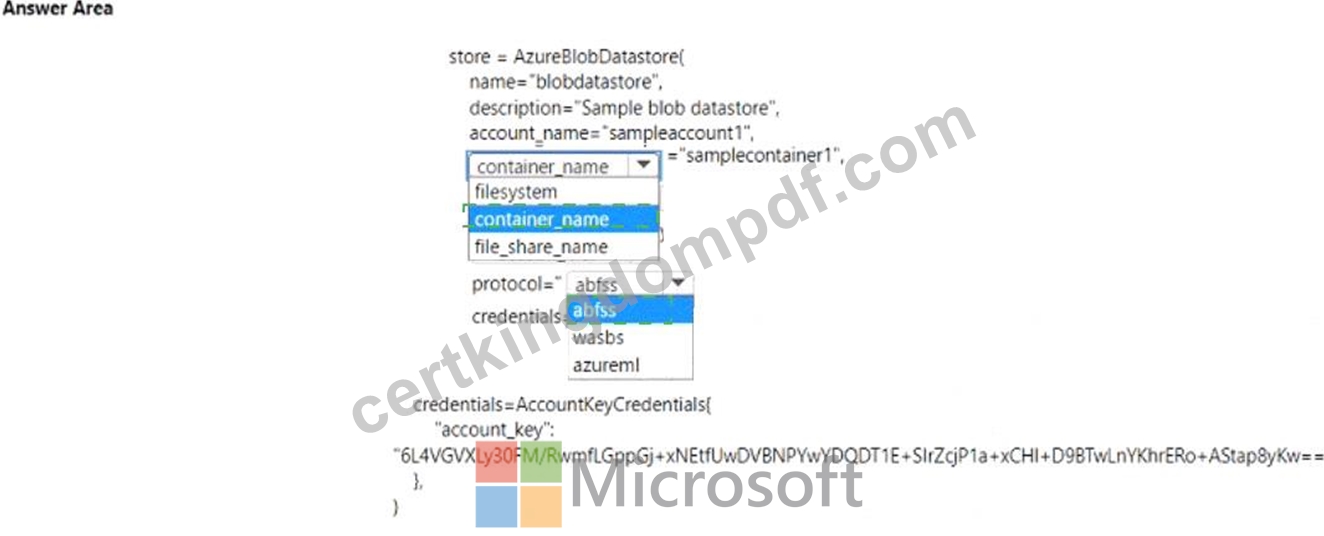
Explanation: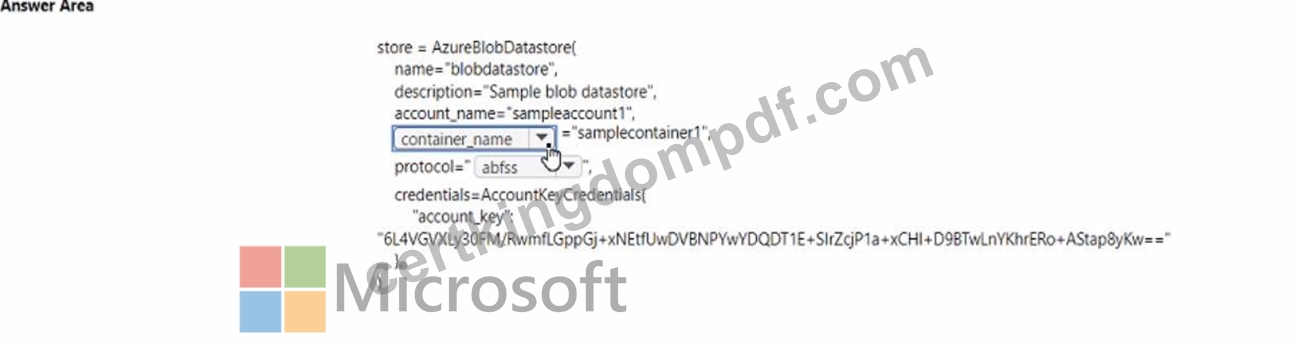
NEW QUESTION # 192
space and set up a development environment. You plan to train a deep neural network (DNN) by using the Tensorflow framework and by using estimators to submit training scripts.
You must optimize computation speed for training runs.
You need to choose the appropriate estimator to use as well as the appropriate training compute target configuration.
Which values should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.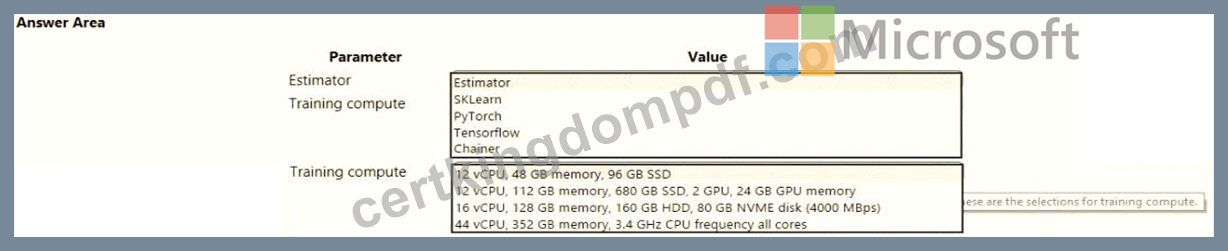
Answer:
Explanation: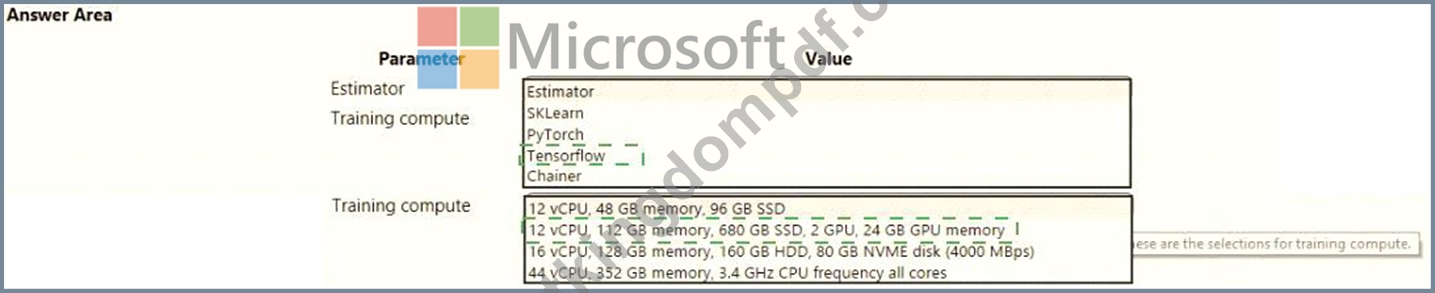
Explanation: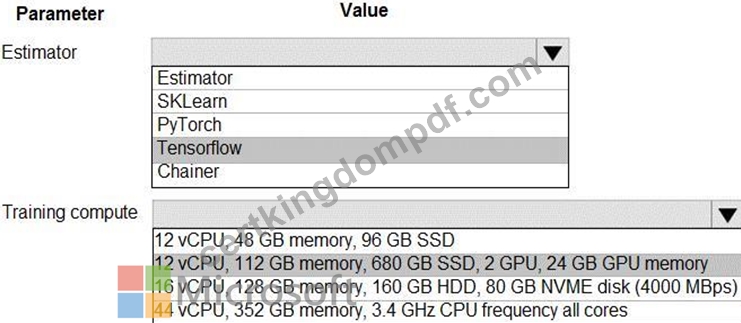
Box 1: Tensorflow
TensorFlow represents an estimator for training in TensorFlow experiments.
Box 2: 12 vCPU, 112 GB memory..,2 GPU,..
Use GPUs for the deep neural network.
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-train-core/azureml.train.dnn
NEW QUESTION # 193
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You create an Azure Machine Learning service datastore in a workspace. The datastore contains the following files:
/data/2018/Q1.csv
/data/2018/Q2.csv
/data/2018/Q3.csv
/data/2018/Q4.csv
/data/2019/Q1.csv
All files store data in the following format:
id,f1,f2,I
1,1,2,0
2,1,1,1
3,2,1,0
4,2,2,1
You run the following code: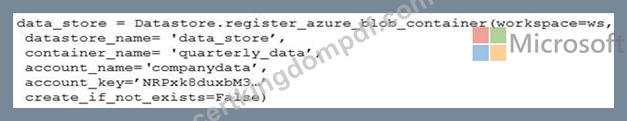
You need to create a dataset named training_data and load the data from all files into a single data frame by using the following code:
Solution: Run the following code:
Does the solution meet the goal?
Answer: A
Explanation:
Use two file paths.
Use Dataset.Tabular_from_delimeted, instead of Dataset.File.from_files as the data isn't cleansed.
Note:
A FileDataset references single or multiple files in your datastores or public URLs. If your data is already cleansed, and ready to use in training experiments, you can download or mount the files to your compute as a FileDataset object.
A TabularDataset represents data in a tabular format by parsing the provided file or list of files.
This provides you with the ability to materialize the data into a pandas or Spark DataFrame so you can work with familiar data preparation and training libraries without having to leave your notebook. You can create a TabularDataset object from .csv, .tsv, .parquet, .jsonl files, and from SQL query results.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-create-register-datasets
NEW QUESTION # 194
......
Generally speaking, every candidate wants to pass the exam just one time. DP-100 learning materials of us can do that for you. Since we have a professional team to collect and research the latest information for the exam, and therefore the quality can be guaranteed. We offer you free demo for DP-100 Exam Materials to have a try, so that you can know what the complete version is like. Besides, we also pass guarantee and money back guarantee, and if you fail to pass the exam after using DP-100 exam materials of us, we will give you refund.
DP-100 Reliable Braindumps Free: https://www.certkingdompdf.com/DP-100-latest-certkingdom-dumps.html
What's more, part of that CertkingdomPDF DP-100 dumps now are free: https://drive.google.com/open?id=17DBuriqrLF1NaYOHJ2bqCzs8tuHvB-a3