What's more, part of that PDF4Test DP-750 dumps now are free: https://drive.google.com/open?id=1xRpF3JX-atgeZM2EKHBVyzYPn6hPqoYX
Our DP-750 questions answers study guide is the best option for you to pass exam easily. Our experts are busy in providing the most updated content that could ensure your 100% success in DP-750 actual test. The up-to-date Microsoft exam dumps consist of latest practice questions answers and explanations. We are devoted to take appropriate steps in improving our products like DP-750 Pass Guide.
| Section | Weight | Objectives |
|---|---|---|
| Prepare and process data | 30–35% | - Ingest and transform data
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
| Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
PDF4Test provides accurate and up-to-date Microsoft DP-750 Exam Questions that ensure exam success. With these Microsoft DP-750 practice questions, you can pass the DP-750 exam on the first try. PDF4Test understands the stress and anxiety that exam candidates experience while studying. As a result, they provide personalized Microsoft DP-750 Practice Exam material to assist you in efficiently preparing for the exam.
NEW QUESTION # 45
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two managed Delta tables named sales.schema1.table1 and sales.schema1.table2.
sales.schema1.table1 contains sales data from the current year.
sales.schema1.table2 contains historical data.
You need to load all the rows from sales.schema1.table1 into sales.schema1.table2. The solution must preserve any existing data in sales.schema1.table2 and minimize processing effort.
Which command should you run?
Answer: A
Explanation:
The correct answer is A - INSERT INTO.
INSERT INTO appends all rows from the source to the target. Existing rows in table2 are untouched - the historical data stays intact - and the current year's rows from table1 are added. That is exactly what the requirement asks: 'preserve any existing data and minimise processing effort.' Option B (CREATE TABLE AS SELECT) would fail if table2 already exists, or if used with CREATE OR REPLACE it wipes table2 entirely before writing - historical data gone. Option C (INSERT OVERWRITE) replaces the entire table content with only the table1 rows, also destroying table2's existing data. Option D (CREATE OR REPLACE TABLE AS SELECT) explicitly drops and recreates the table, eliminating all historical records.
INSERT INTO is deliberately the simplest possible command here - one line, no special options, no risk of accidental data loss.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/delta-insert-into
NEW QUESTION # 46
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named Catalog1. Catalog1 contains a table named Transactions. Transactions contains the following columns:
- transaction_id
- customer_name
- email_address
- credit_card_number
- transaction_amount
You need to ensure that business analysts can query all the rows in the Transactions table. The solution must meet the following requirements:
- Prevent the analysts from seeing the full values in the email_address and credit_card_number columns.
- Ensure that the analysts can see only the values after the @
character in each email address.
- Ensure that the analysts can see only the last four digits of each
credit card number.
- Enable the analysts to query the table without errors.
- Follow the principle of least privilege.
What should you do?
Answer: A
Explanation:
To protect sensitive customer information while allowing a specific group to run queries, use Unity Catalog's Dynamic Column Masking. This grants the group table access while applying User- Defined Functions (UDFs) to redact the email addresses and credit card numbers dynamically.
Here is the exact SQL implementation to apply:
1. Create the masking SQL UDFs
Define functions to apply the exact partial masking rules requested.
2. Apply the column masks to the tableAlter the transaction table to attach these UDFs to the respective columns.
3. Grant least privilege permissionsGrant the group the SELECT permission on the table, along with the foundational permissions to access the catalog and schema.
Reference:
https://docs.databricks.com/aws/en/data-governance/unity-catalog/filters-and-masks
NEW QUESTION # 47
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
- The schemas and tables can be queried in Databricks.
- The schemas and tables appear alongside other Unity Catalog objects.
- The data is NOT copied into Databricks-managed storage.
Solution: You create a Lakeflow Connect pipeline and connect it to DB1.
Does this meet the goal?
Answer: B
Explanation:
Correct:
* You create a foreign catalog in Catalog Explorer.
You should create a Foreign Catalog using Lakehouse Federation.
Data Copying: Lakehouse Federation queries data directly in the source SQL Server without moving or copying it.
Seamless Integration: The database schemas and tables appear right inside Unity Catalog alongside your other data objects.Real-time Access: It provides immediate access to live SQL Server data.
Incorrect:
* You create a Databricks access connector.
* You create a Lakeflow Connect pipeline and connect it to DB1.
Data Copying: Lakeflow Connect is an ingestion tool that physically replicates and copies data into Databricks-managed storage (Delta tables).
Storage Costs: It violates your requirement to keep data out of Databricks storage.
* You create a new native catalog in Unity Catalog.
Note:
To expose the external SQL Server database in Unity Catalog without copying the data, you must use Lakehouse Federation.
Here are the step-by-step actions you need to take:
1. Create a Connection
Create a securable object in Unity Catalog that specifies the path and credentials to access the SQL Server database.
Go to Catalog Explorer or use SQL.
Select External Data > Connections.
Create a connection using the SQL Server connection details (URL, host, port, and database credentials).
*-> 2. Create a Foreign Catalog
Create a specific type of catalog in Unity Catalog that mirrors the external database.
Use the CREATE FOREIGN CATALOG SQL command or the Catalog Explorer UI.
Link this foreign catalog directly to the connection you created in step 1.
3. Query the DataOnce the foreign catalog is created, Unity Catalog automatically syncs the schemas and tables from SQL Server.
Reference:
https://docs.databricks.com/gcp/en/database-objects/
NEW QUESTION # 48
A data engineer notices slow query performance on a large Delta table in Azure Databricks. The table has frequent updates and deletes. Which action best improves query performance?
Answer: D
Explanation:
OPTIMIZE compacts small files into larger ones, reducing file scan overhead. ZORDER improves data skipping by co-locating related column values. This combination significantly improves query performance on frequently filtered columns. Increasing cluster size does not address file fragmentation. Converting to Parquet removes Delta benefits like ACID transactions.
NEW QUESTION # 49
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job! runs every hour.
Occasionally, the job run takes longer than one hour to complete. Overlapping runs must be prevented to avoid data corruption.
You need to configure the job scheduling behavior.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.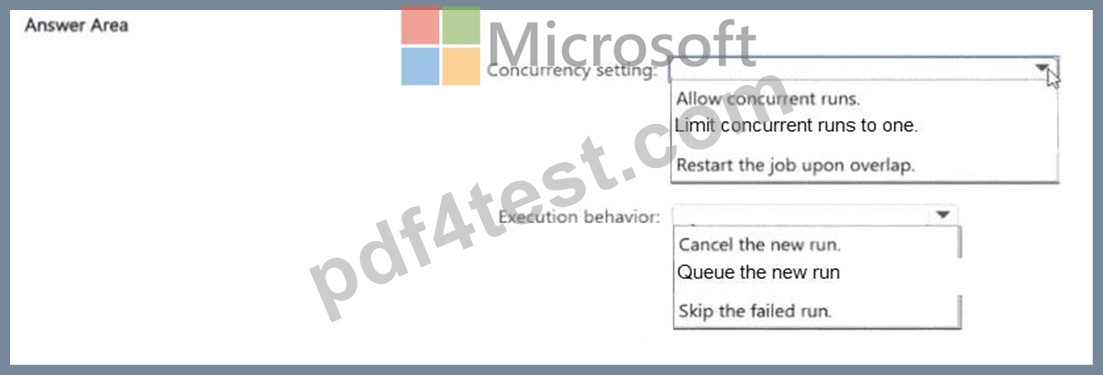
Answer:
Explanation: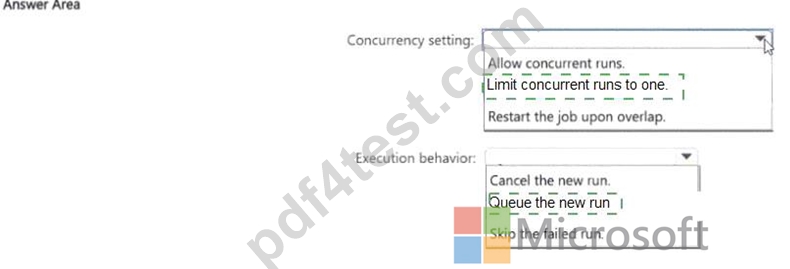
Explanation:
Two settings address the overlapping-run problem:
Concurrent Runs policy set to 'Skip' (or 'Allow only one concurrent run'). When a new scheduled trigger fires while the previous run is still in progress, the new run is skipped rather than starting alongside the ongoing one. This prevents two runs from writing to the same tables at the same time - which is the data corruption risk the question highlights.
Cron-based schedule for the hourly trigger. A cron expression defines the regular execution cadence.
Combined with the concurrency setting, the job runs hourly but never overlaps.
An alternative to 'Skip' is 'Wait' (queue the new run), which ensures every scheduled run eventually executes
- but for this scenario where overlapping is the primary concern, skipping the missed run is typically preferable to building up a queue of back-to-back executions.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/configure-jobs#concurrent-runs
NEW QUESTION # 50
......
There are three versions of our DP-750 study questions on our website: the PDF, Software and APP online. And our online test engine and the windows software of the DP-750 guide materials are designed more carefully. During our researching and developing, we always obey the principles of conciseness and exquisiteness. All pages of the DP-750 Exam simulation are simple and beautiful. As long as you click on them, you can find the information easily and fast.
DP-750 New Study Plan: https://www.pdf4test.com/DP-750-dump-torrent.html
2026 Latest PDF4Test DP-750 PDF Dumps and DP-750 Exam Engine Free Share: https://drive.google.com/open?id=1xRpF3JX-atgeZM2EKHBVyzYPn6hPqoYX