BONUS!!! Download part of Exam-Killer AI-300 dumps for free: https://drive.google.com/open?id=1jxRyhkicF8vu8A552MAFXIpB9fsXMnLR
With our numerous advantages of our AI-300 latest questions and service, what are you hesitating for? Our company always serves our clients with professional and precise attitudes on our AI-300 exam questions, and we know that your satisfaction is the most important thing for us. We always aim to help you pass the AI-300 Exam smoothly and sincerely hope that all of our candidates can enjoy the tremendous benefit of our AI-300 exam material, which might lead you to a better future! And the high pass rate of AI-300 learning material as 99% to 100% won't let you down.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Optimize generative AI systems and model performance | 15–20% | - Improve efficiency and cost-effectiveness
|
| Topic 2: Implement machine learning model lifecycle and operations | 25–30% | - Register, version, and package models
|
| Topic 3: Implement generative AI quality assurance and observability | 10–15% | - Monitor generative AI systems
|
| Topic 4: Design and implement an MLOps infrastructure | 15–20% | - Implement infrastructure as code for Machine Learning
|
| Topic 5: Design and implement a GenAIOps infrastructure | 20–25% | - Implement infrastructure for generative AI workloads
|
>> Valid AI-300 Exam Review <<
We have harmonious cooperation with exam candidates. The relation comes from the excellence of our AI-300 training materials. We never avoid our responsibility of offering help for exam candidates like you, so choosing our AI-300 practice dumps means you choose success. Moreover, without the needs of waiting, you can download the AI-300 Study Guide after paying for it immediately. And we have patient and enthusiastic staff offering help on our AI-300 learning prep.
NEW QUESTION # 155
Hotspot Question
You are monitoring a fine-tuned large language model deployed in Microsoft Foundry.
You evaluate the model before and after fine-tuning by using the same evaluation dataset.
You review the following evaluation results: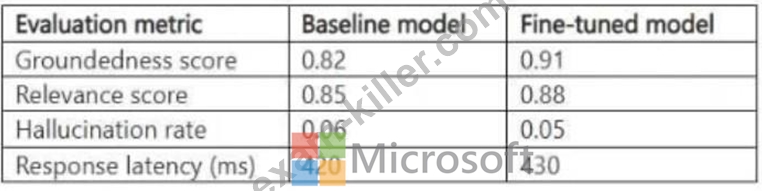
You need to determine whether the fine-tuned model shows improved performance without introducing regression. For each of the following statements, select Yes if the statement is true.
Otherwise, select No.
NOTE: Each correct selection is worth one point.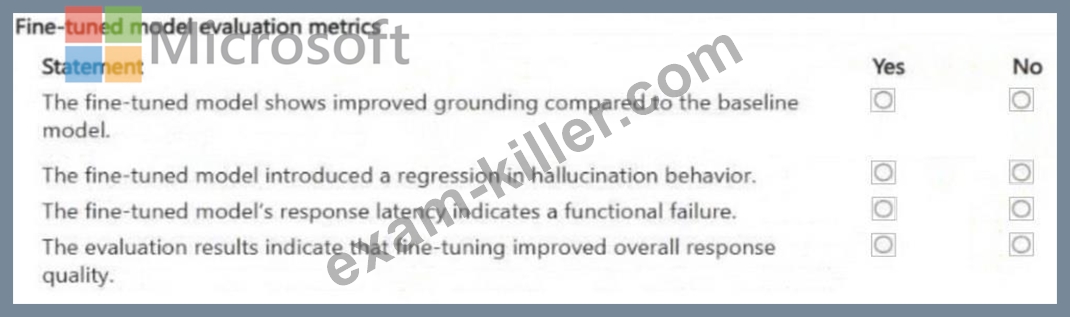
Answer:
Explanation: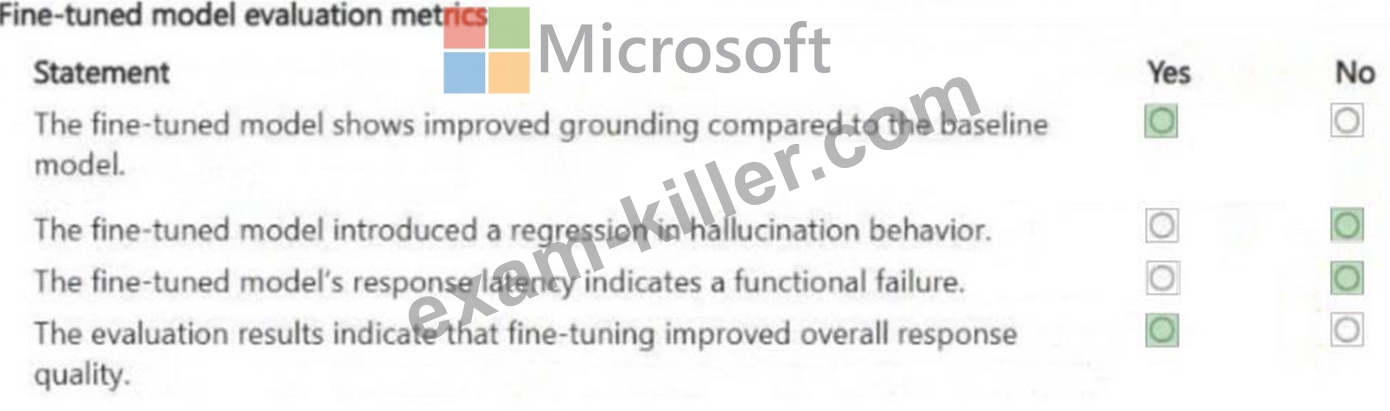
NEW QUESTION # 156
You have an Azure Machine Learning workspace that includes an AmICompute cluster and a batch endpoint.
You clone a repository that contains an MLflow model to your local computer. You need to ensure that you can deploy the model to the batch endpoint.
Solution: Create a data asset in the workspace.
Does the solution meet the goal?
Answer: A
NEW QUESTION # 157
You deploy a new model version to a managed online endpoint. You must test it with 10% traffic and automatically roll back if latency or error rate increases beyond threshold. What should you configure?
Answer: D
NEW QUESTION # 158
A team is building a Retrieval-Augmented Generation (RAG) system.
The team observes that the retrieved documents are often irrelevant or incomplete.
You need to improve retrieval accuracy.
What should you adjust?
Answer: D
Explanation:
Chunk size and overlap directly affect the precision and completeness of information retrieved in a RAG architecture. Microsoft identifies effective chunking as a critical part of successful RAG implementation. If chunks are too large, they can contain excessive unrelated information, reducing retrieval precision because the vector representation covers multiple concepts. Conversely, chunks that are too small can omit necessary surrounding context or separate related information across chunk boundaries, resulting in incomplete retrieval.
Overlap helps preserve semantic continuity between adjacent chunks. Microsoft recommends using overlap particularly with fixed-size chunking because relevant facts or concepts can span chunk boundaries. The optimal chunk size and overlap should therefore be evaluated against representative documents and queries rather than treated as fixed constants. Microsoft specifically notes that larger chunks can preserve contextual richness, while appropriately configured overlap prevents contextual information from being lost at segmentation boundaries.
Temperature controls generation variability , not document retrieval. Token limits constrain how much content a model processes but do not inherently make retrieval more relevant. Embedding strategy can also influence retrieval quality, but given the stated symptom of irrelevant or incomplete retrieved passages , tuning chunk size and overlap is the directly targeted remediation.
Study Guide Reference: Optimize generative AI systems and model performance - RAG optimization, document chunking, retrieval precision, contextual completeness, and grounding.
NEW QUESTION # 159
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals.
You have an Azure Machine Learning workspace. You connect to a terminal session from the Notebooks page in Azure Machine Learning studio.
You plan to add a new Jupyter kernel that will be accessible from the same terminal session.
You need to perform the task that must be completed before you can add the new kernel.
Solution: Delete the Python 3.8 - AzureML kernel.
Does the solution meet the goal?
Answer: A
Explanation:
No. Deleting an existing Azure Machine Learning kernel is neither required nor appropriate before adding another Jupyter kernel. Azure Machine Learning compute instances are explicitly designed to support multiple kernels simultaneously . Microsoft states that notebooks automatically discover the Jupyter kernels installed on the connected compute instance, allowing users to switch between them from the kernel selector.
To add a kernel, the supported process is to create a new Conda environment, activate it, install pip and ipykernel, and then register that environment by using python -m ipykernel install --user. Existing kernels do not need to be removed.
More importantly, Microsoft warns against deleting Conda environments or Jupyter kernels that you did not create , because doing so can damage Jupyter or JupyterLab functionality on the Azure Machine Learning compute instance. This makes removal of a built-in AzureML kernel particularly inappropriate as a prerequisite for creating another kernel.
The correct approach is therefore to leave the existing kernel intact and create a separate environment/kernel for the new workload.
Study Guide Reference: Design and implement an MLOps infrastructure - Azure Machine Learning notebook environments, kernel management, compute instances, and dependency isolation.
NEW QUESTION # 160
......
In order to let you have a deep understanding of our AI-300 learning guide, our company designed the free demos for our customers. We will provide you with free demos of our study materials before you buy our products. If you want to know our AI-300 training materials, you can download them from the web page of our company. If you use the free demos of our AI-300 study engine, you will find that our products are very useful for you to pass your AI-300 exam and get the certification.
Most AI-300 Reliable Questions: https://www.exam-killer.com/AI-300-valid-questions.html
DOWNLOAD the newest Exam-Killer AI-300 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1jxRyhkicF8vu8A552MAFXIpB9fsXMnLR