In order to gain the certification quickly, people have bought a lot of study materials, but they also find that these materials don’t suitable for them and also cannot help them. If you also don’t find the suitable DP-750 test guide, we are willing to recommend that you should use our study materials. Because our products will help you solve the problem, it will never let you down if you decide to purchase and practice our DP-750 latest question.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30-35% | - Data ingestion
|
| Topic 2: Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Topic 3: Deploy and manage data pipelines and workloads | 30-35% | - Operational reliability
|
| Topic 4: Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
>> DP-750 Latest Exam Experience <<
If you want to get a desirable opposition and then achieve your career dream, you are a right place now. Our DP-750 study tool can help you pass the exam. So, don't be hesitate, choose the DP-750 test torrent and believe in us. Let's strive to our dreams together. Life is short for us, so we all should cherish our life. Our DP-750 Guide Torrent can help you to save your valuable time and let you have enough time to do other things you want to do. Just buy our DP-750 exam questions, then you will pass the DP-750 exam easily.
NEW QUESTION # 66
You have an Azure Databricks workspace that contains multiple all-purpose clusters. You discover that some clusters remain idle for long periods after users finish their work. You need to reduce compute costs without affecting active workloads. What should you do?
Answer: C
Explanation:
The correct answer is D - configure automatic termination.
The problem is specific: clusters sit idle after users finish working but nobody manually shuts them down.
Automatic termination solves this directly - once a cluster has been idle for the configured period (no running commands, no attached notebooks with active execution), it shuts itself down. You eliminate the idle cost without any manual intervention and without affecting any workload that is actually running.
Option A (convert to job clusters) would force users off interactive all-purpose clusters, disrupting their development workflow. Option B (spot instances) reduces the hourly rate while a cluster is running but does nothing about the idle-time problem - a cheaper idle cluster is still waste. Option C (enable autoscaling) reduces the number of workers during light load but keeps the cluster alive at the minimum node count. It saves some cost but doesn't fully eliminate idle spend the way auto-termination does.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/configure#auto-termination
NEW QUESTION # 67
You have an Azure Databricks workspace that is enabled for Unity Catalog You have a complex job named Job1 that contains eight tasks. Job! takes multiple hours to complete During the last job run, the final task fails due to a transient issue.
You need to retry the last task without rerunning tasks that have already completed.
What should you do?
Answer: C
Explanation:
The correct answer is B - Repair the current job run.
Repair Run is designed for exactly this situation: a long-running job where most tasks succeeded but the final task failed due to a transient issue. Instead of restarting the entire eight-task job from the beginning - wasting hours of compute - Repair Run re-executes only the failed task and any dependents that were skipped as a result. All tasks that completed successfully are marked done and their outputs are reused.
Option A (update job parameters) changes configuration for future runs but doesn't re-execute the failed task in the current run. Option C (Restart Job1) re-runs every task from the start - precisely what the question says to avoid. Option D (disable and re-enable the schedule) creates a brand-new run on the next schedule trigger, again starting from the beginning rather than repairing the existing run.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/repair-job-failures
NEW QUESTION # 68
You have an Azure Databricks account that contains workspaces enabled for Unity Catalog.
You need to implement audit logging to meet the following requirements:
* Capture audit logs for all the workspaces in the account.
* Retain the audit logs for 90 days.
* Minimize storage and ingestion costs.
The logs will be reviewed only during security investigations and will NOT be queried regularly.
To where should you send the audit logs?
Answer: B
Explanation:
An Azure Storage account provides durable, comparatively low-cost retention for diagnostic and audit logs that are accessed infrequently. A lifecycle or retention policy can preserve the logs for 90 days and then remove them automatically. This matches an investigation-only access pattern without paying the ingestion and indexing charges associated with Log Analytics. Azure Monitor metrics stores numerical monitoring measurements, not the complete audit-event records required here. Azure Event Hubs is a streaming transport intended to forward events to consumers and is not the final long-term retention destination. Log Analytics is appropriate when teams need frequent querying, dashboards, and alerting, but those capabilities introduce unnecessary cost for logs reviewed only during occasional investigations. Storage therefore best satisfies centralized retention and cost requirements.
NEW QUESTION # 69
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named CatalogV Catalog1 contains a schema named Schema! and a table named Table1.
You need to ensure that access to the data in Table1 is controlled by using attribute based access control (ABAC).
What should you apply to Table1, and how should you control access for users? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.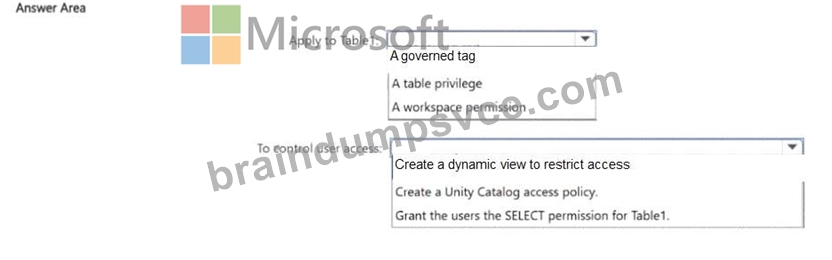
Answer:
Explanation: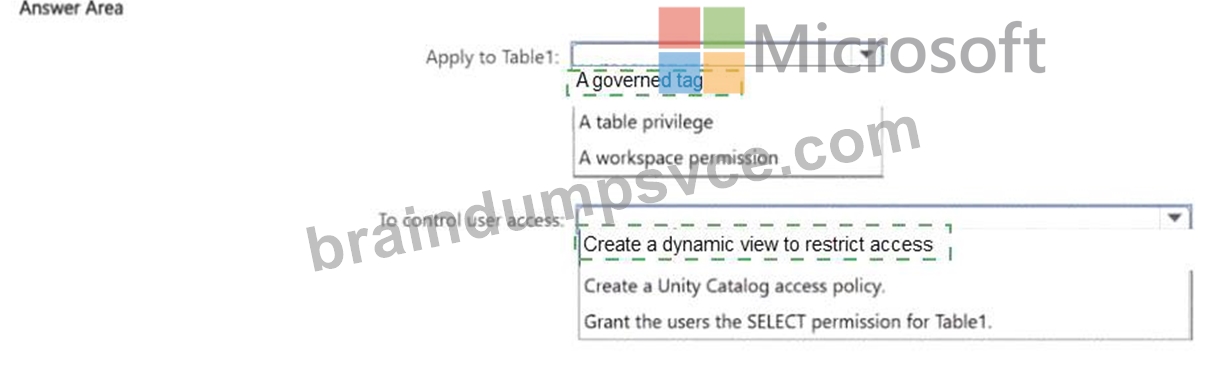
Explanation:
Attribute-based access control (ABAC) in Unity Catalog is implemented through row filters. A row filter is a SQL function registered on a table that evaluates the identity or group membership of the querying user and returns only the rows they're entitled to see.
The key functions are CURRENT_USER() (returns the logged-in user's email) and IS_ACCOUNT_GROUP_MEMBER() (returns true if the user belongs to a specified group). By building filter logic around these, you create access rules that are data-driven - a user in the 'EMEA' group sees EMEA rows, a user in 'APAC' sees APAC rows - without maintaining separate table-level grants per data segment.
This is what distinguishes ABAC from role-based access control: decisions are based on the user's attributes evaluated at query time, not on static grant lists. The filter is transparent to end users - they query the table normally and only receive rows the policy allows.
Reference: https://learn.microsoft.com/en-us/azure/databricks/data-governance/unity-catalog/row-and-column- filters
NEW QUESTION # 70
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Table1.
Table1 stores customer profile data.
Business users must analyze how customer profile records change over time. They must also be able to query earlier versions of the table.
You need to implement a solution that:
* Maintains persistent historical versions of customer profile records for long-term analysis.
* Allows users to query earlier versions of the Delta table.
* Minimizes maintenance effort.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.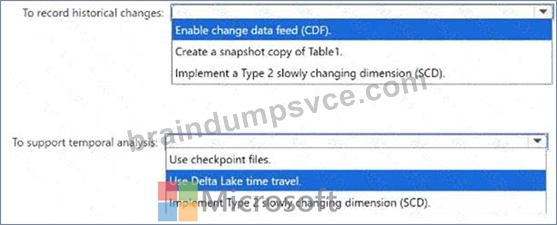
Answer:
Explanation: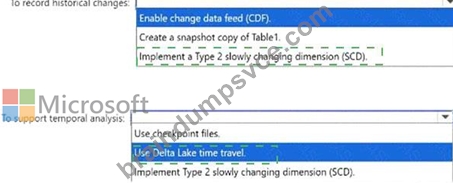
Explanation:
To record historical changes: Implement a Type 2 slowly changing dimension (SCD).
To support temporal analysis: Use Delta Lake time travel.
A Type 2 slowly changing dimension preserves customer-profile history by inserting a new record whenever a tracked attribute changes instead of overwriting the existing record. Effective dates, expiration dates, version values, or current-record indicators can identify which version applied during a particular period. This provides persistent business history for long-term analysis. Delta Lake time travel supports temporal analysis of the physical table by allowing users to query an earlier version with VERSION AS OF or TIMESTAMP AS OF. Time travel is useful for auditing and reproducing previous results, but its availability depends on retained Delta log entries and data files. Therefore, it should not replace a Type 2 SCD for permanent customer history. Together, the two features satisfy the historical-record and earlier-version requirements.
NEW QUESTION # 71
......
We will provide you with comprehensive study experience by give you DP-750 free study material & Microsoft exam prep torrent. The questions & answers from the Microsoft practice torrent are all valid and accurate, made by the efforts of a professional IT team. The authority and validity of Microsoft DP-750 training practice are the guarantee for all the IT candidates. We arrange our experts to check the update every day. Once there is any new technology about DP-750 Exam Dumps, we will add the latest questions into the DP-750 study pdf, and remove the useless study material out, thus to ensure the DP-750 exam torrent you get is the best valid and latest. So 100% pass is our guarantee.
DP-750 Latest Test Online: https://www.braindumpsvce.com/DP-750_exam-dumps-torrent.html