BONUS!!! Download part of VerifiedDumps DAA-C01 dumps for free: https://drive.google.com/open?id=1LbSYeWBK3WIxNM2tbXqALYrDqfCOmhod
We assume all the responsibilities that our practice materials may bring. They are a bunch of courteous staff waiting for offering help 24/7. You can definitely contact them when getting any questions related with our DAA-C01 practice materials. If you haplessly fail the exam, we treat it as our responsibility then give you full refund and get other version of practice material for free. That is why we win a great deal of customers around the world. Especially for those time-sensitive and busy candidates, all three versions of DAA-C01 practice materials can be chosen based on your preference. Such as app version, you can learn it using your phone everywhere without the limitation of place or time.
| Section | Objectives |
|---|---|
| Topic 1: Snowflake Architecture and Data Platform Fundamentals | - Snowflake architecture concepts
|
| Topic 2: Data Modeling and Performance Optimization | - Modeling approaches in Snowflake
|
| Topic 3: Security, Governance, and Data Sharing | - Access control and security
|
| Topic 4: Data Loading and Unloading | - Data ingestion methods
|
| Topic 5: Data Transformation and Analysis | - Analytical workloads
|
>> DAA-C01 Certification Exam Dumps <<
The PDF version of the VerifiedDumps Snowflake DAA-C01 prep material is easily accessible. This format is ideal for someone who is constantly on the move, as you can prepare for your SnowPro Advanced: Data Analyst Certification Exam (DAA-C01) exam whether you are using your smartphone, tablet, or laptop. You can study anywhere, at any time, without having to worry about installing anything. Furthermore, you can study with a hard copy by printing all of your SnowPro Advanced: Data Analyst Certification Exam (DAA-C01) PDF questions. We offer regular updates in PDF format to improve SnowPro Advanced: Data Analyst Certification Exam (DAA-C01) questions according to changes in the exam.
NEW QUESTION # 24
You're working with a Snowflake database containing sales transaction data'. The 'SALES' table includes columns 'transaction id' , product id', 'customer id', 'transaction_date', and 'sales amount'. The Bl team needs to analyze sales trends, identify top-selling products, and segment customers based on their purchase behavior. They also need to support ad-hoc queries with various filtering and aggregation criteria'. The data volume is significant, and query performance is a key concern. Consider the following Snowflake table definition (simplified):
Which of the following SQL queries, combined with appropriate data modeling techniques, will provide the BEST performance for analyzing monthly sales trends by product category, assuming a separate 'PRODUCTS table exists with 'product_id' and 'category' columns?





Answer: D
Explanation:
Option B provides the best performance because it uses a materialized view to pre- compute the monthly sales trends by product category. Subsequent queries to the materialized view will be significantly faster than re-calculating the aggregation each time. Option A performs the join and aggregation every time the query is executed. Option C uses a correlated subquery, which is generally less performant than a join. Option D uses , which might provide the same result but doesn't address the performance issue of recalculating the aggregation every time. Option E uses a temporary table which is unncessary because a materialized view can be created directly from the SALES and PRODUCTS table.
NEW QUESTION # 25
What actions are involved in performing general DML (Data Manipulation Language) operations in Snowflake? (Select all that apply)
Answer: B,C,D
Explanation:
General DML operations in Snowflake include inserting, updating, and deleting data.
NEW QUESTION # 26
Why would a Data Analyst use a dimensional model rather than a single flat table to meet BI requirements for a virtual warehouse? (Select TWO).
Answer: A,B
Explanation:
In the field of data warehousing and business intelligence (BI), choosing the right data model is crucial for long-term maintainability and user accessibility. While a single flat table might seem simple initially, dimensional modeling (typically using Star or Snowflake schemas) provides distinct advantages for enterprise analytics.
1. Scalability and Flexibility (Option C)
Combining all attributes into a single flat table creates a highly rigid structure. Every time a new attribute is added to a dimension (e.g., adding a "Promotion Category" to a product), the entire flat table must be rewritten or altered, which is inefficient for large datasets. Furthermore, flat tables often contain redundant data, leading to "update anomalies" where a change in a dimension attribute must be propagated across millions of rows. A dimensional model separates changing business processes (Facts) from the context of those processes (Dimensions), allowing the schema to scale and evolve independently.
2. Ad-hoc Analysis for Power Users (Option D)
Dimensional models are specifically designed to be intuitive for business users and BI tools. By organizing data into Facts (measurable metrics) and Dimensions (descriptive attributes), power users can easily "slice and dice" data across different hierarchies. For example, a user can quickly run an ad-hoc query to compare "Total Sales" (Fact) by "Store Region" (Dimension) and "Calendar Month" (Dimension). This structure provides a predictable and standardized "language" for the data, making it easier for users to build their own reports without needing a Data Analyst to create a custom flat table for every specific request.
Evaluating the Distractors:
* Option A and E: These are common misconceptions. Modern cloud data warehouses like Snowflake are often highly optimized for wide "flat" tables due to columnar storage and sophisticated pruning. In many cases, a flat table may actually outperform a multi-table join (dimensional model) because it avoids the computational overhead of the join itself.
* Option B: This is factually incorrect. Flat tables are denormalized (repeating data), which generally takes more storage space. Dimensional modeling is a form of normalization that saves space by storing descriptive strings once in a dimension table rather than repeating them for every transaction in a fact table.
NEW QUESTION # 27
You have a Snowflake table 'RAW DATA containing a 'VARIANT column called 'json_data'. This column stores JSON objects representing customer orders. The structure includes a nested array of items within each order. You need to create a flattened table called 'ORDER ITEMS with the following columns: 'order_id', and However, the field is not directly present in the JSON data'. Instead, it needs to be derived by concatenating the 'order_id' with the index (ordinal position) of the item within the 'items' array. The structure looks like this: { "order_id": "ORD-123", "customer_id": "CUST-456", "items": [ { "item_name": "Laptop", "item_price": 1200 }, { "item_name": "Mouse", "item_price": 25 } ] } Which of the following SQL statements correctly creates the 'ORDER ITEMS table?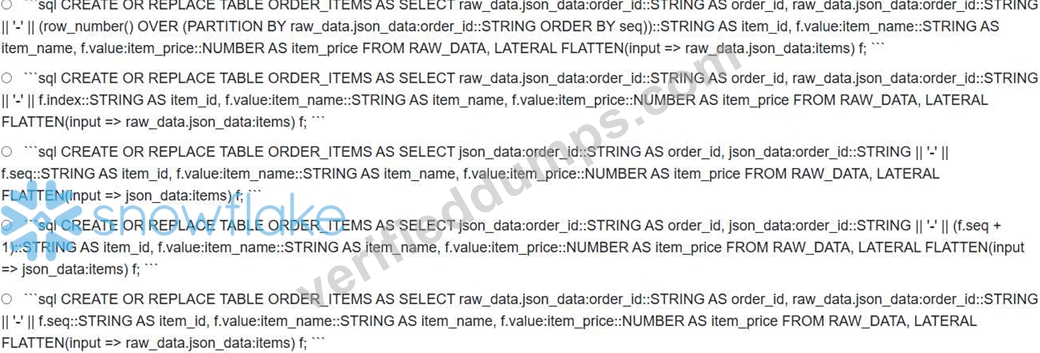
Answer: E
Explanation:
Option E correctly uses the 'LATERAL FLATTEN' function to unnest the 'items' array. The key is using 'f.seq' (sequence number) provided by 'FLATTEN' function, which is the ordinal position of the item in the array (starting from 1), to create the item_id. It concatenates the order_id with the sequence number to generate a unique item_id. Option A is wrong because row_number is an aggregate function, and needs Group by to execute. Option B uses f.index, which does not exist in the output of Lateral flatten. Options C is correct in most of the parameters, however, 'raw_data' alias is missing, as a result the result will be error. Option D also uses seq, however it adds 1, which changes the index to start from 1, which might be wrong.
NEW QUESTION # 28
You are tasked with ingesting data from a REST API that returns data in JSON format. The API requires authentication via an API key passed in the header and returns a large dataset, potentially exceeding Snowflake's recommended file size for optimal loading. Furthermore, the API has rate limits, and exceeding them results in temporary blocking. What is the MOST efficient and reliable way to retrieve this data into Snowflake?
Answer: B,E
Explanation:
Options B and D offer the most robust solutions. Option B, using a Python script with Snowpark, allows for fine-grained control over authentication, rate limiting, and data partitioning before loading into Snowflake. Option D, utilizing a dedicated ETL tool, provides a pre-built and often more scalable solution for complex data ingestion scenarios, including handling authentication, rate limits, and data transformation. Option A is less scalable and maintainable. Option C is incorrect because Snowpipe is designed for continuous loading from cloud storage, not directly from REST APIs. Option E is less efficient because it uses Java UDF inside stored procedure.
NEW QUESTION # 29
......
The dynamic society prods us to make better. Our services on our Snowflake DAA-C01 exam questions are also dependable in after-sales part with employees full of favor and genial attitude towards job. So our services around the Snowflake DAA-C01 Training Materials are perfect considering the needs of exam candidates all-out.
DAA-C01 Preparation: https://www.verifieddumps.com/DAA-C01-valid-exam-braindumps.html
P.S. Free & New DAA-C01 dumps are available on Google Drive shared by VerifiedDumps: https://drive.google.com/open?id=1LbSYeWBK3WIxNM2tbXqALYrDqfCOmhod