大家在準備考試的時候,可以結合本網站最新的 Microsoft DP-750 擬真試題去認真地做練習,這樣的話,可以為你的考試節省很多的時間。Microsoft 的 DP-750 考試整體來說還是不算複雜的,只要事先將擬真試題看好就沒有問題了。還有,做實驗題是要一定要多想想,這樣的話,才能將自身的一些素質提高上去。我們的考題網剛更新 DP-750 題庫能確保考生能順利通過 DP-750 考試,獲得 Microsoft 認證證照。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Topic 2: Prepare and process data | 30-35% | - Ingest and transform data
|
| Topic 3: Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Topic 4: Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
當你感到悲哀痛苦時,最好是去學東西,學習會使你永遠立於不敗之地。KaoGuTi Microsoft的DP-750考試培訓資料同樣可以幫助你立於不敗之地。有了這個培訓資料,你將獲得國際上認可及接受的Microsoft的DP-750認證,這樣你的全部生活包括金錢地位都會提升很多,到那時,你還會悲哀痛苦嗎?不會,你會很得意,你應該感謝KaoGuTi網站為你提供這樣一個好的培訓資料,在你失落的時候幫助了你,讓你不僅提高自身的素質,也幫你展現了你完美的人生價值。
問題 #68
You have an Azure Databricks workspace.
You need to ingest streaming data from Azure Event Hubs by using Apache Spark Structured Streaming The solution must authenticate to Event Hubs and read the event payload.
How should you complete the PySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.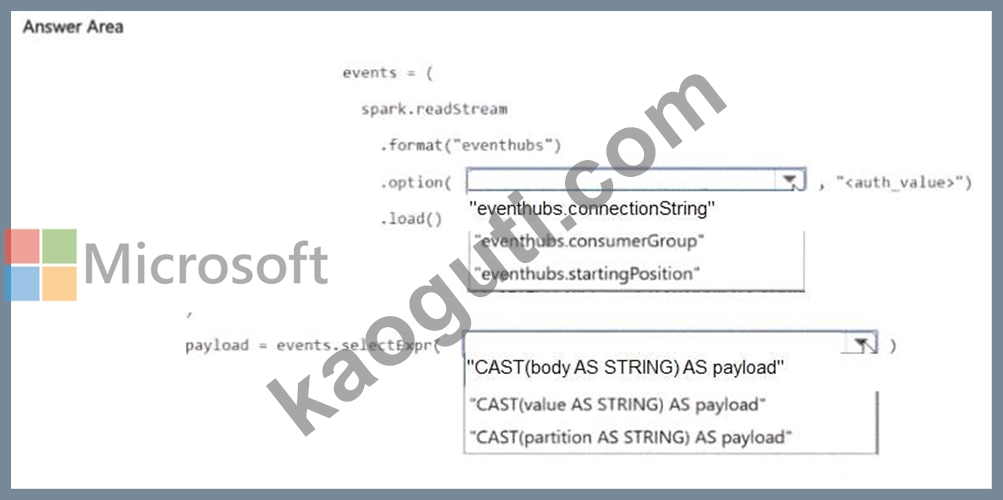
答案:
解題說明: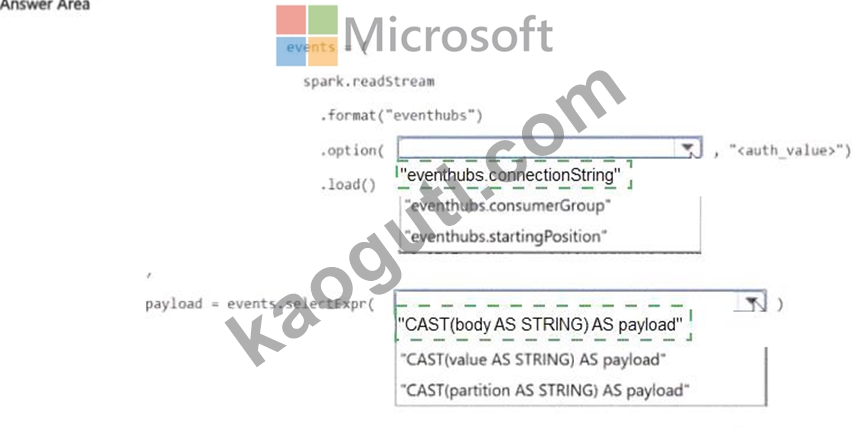
Explanation:
Reading from Azure Event Hubs in Spark Structured Streaming requires three things:
An EventHubsConf object built with the Event Hubs connection string (eventhubs.connectionString). This object is then converted to a map with .toMap before being passed to Spark.
spark.readStream.format('eventhubs').options(**ehConf).load() to create the streaming DataFrame. The
'eventhubs' format is provided by the azure-eventhubs-spark connector library.
A cast('string') on the body column to decode the binary payload. Event Hubs delivers messages with the raw event bytes in a column called body - without the cast, you get binary data rather than the readable JSON or text payload.
This is the standard, documented integration pattern for connecting Azure Databricks to Event Hubs with Structured Streaming, providing the checkpoint-based exactly-once semantics required by the Contoso telemetry pipeline.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/storage/events/eventhubs
問題 #69
You have an Azure Databricks workspace and a remote Git repository named Repo1. Repo1 contains two branches named main and Branch1.
You are on a development team that works in Repo1.
You commit changes to Branch1 and must merge the changes into main.
Before completing the merge, you need to meet the following requirements:
* Ensure that Branch1 includes the changes committed to main since Branch1 was created.
* Ensure that merge conflicts are detected and resolved.
What should you do first?
答案:D
解題說明:
The latest remote changes from main must first be retrieved so that the development environment has the current main-branch state. After pulling those updates, main can be merged into Branch1, and any conflicts can be detected and resolved before Branch1 is proposed for integration into main. Immediately merging a stale local copy of main into Branch1 could omit commits added remotely after Branch1 was created. Pulling Branch1 only synchronizes the feature branch and does not retrieve the required main-branch changes.
Creating a pull request before updating and testing Branch1 would defer conflict discovery until later in the integration process. Pulling the latest main changes is therefore the correct first operation in the sequence.
Microsoft Learn
問題 #70
You need to deploy Declarative Automation Bundles to a development environment. The solution must support automated and repeatable deployments across environments.
What should you use?
答案:D
解題說明:
The Databricks CLI contains the bundle command group for validating, deploying, and running Declarative Automation Bundles. CLI commands can be executed consistently from developer terminals or CI/CD pipelines, making deployments automated, repeatable, and suitable for multiple target environments. The Databricks SDK for Python can manage workspace APIs programmatically, but it is not the standard bundle deployment interface required here. Git folders provide source-control integration inside the workspace but do not deploy bundle-defined resources. The Jobs UI supports interactive creation and management of jobs, which introduces manual steps and does not provide the same infrastructure-as-code workflow. Using commands such as databricks bundle validate and databricks bundle deploy -t dev directly satisfies the automated development deployment requirement. Microsoft Learn
問題 #71
A Delta table receives new fields in incoming JSON data. You want to automatically adapt without breaking pipelines. What should you enable?
答案:C
解題說明:
Auto Loader supports schema inference and schema evolution, allowing new columns to be added automatically during ingestion. This reduces pipeline maintenance and avoids failures due to schema drift. Disabling enforcement is unsafe and risks data corruption. Overwrite mode deletes existing data. Manual updates are not scalable.
問題 #72
You have an Azure Databricks workspace that is enabled for Unity Catalog. You plan to run the following PySpark code.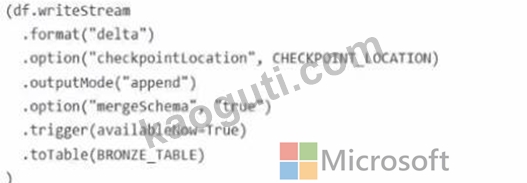
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.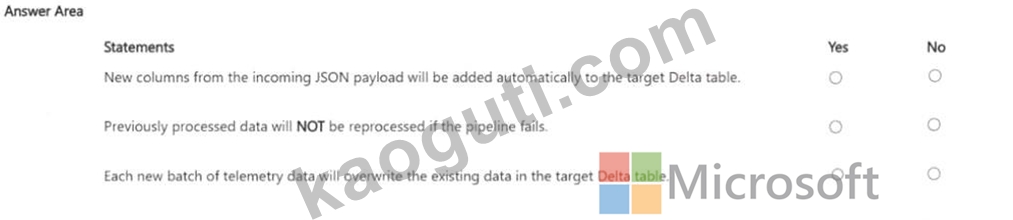
答案:
解題說明: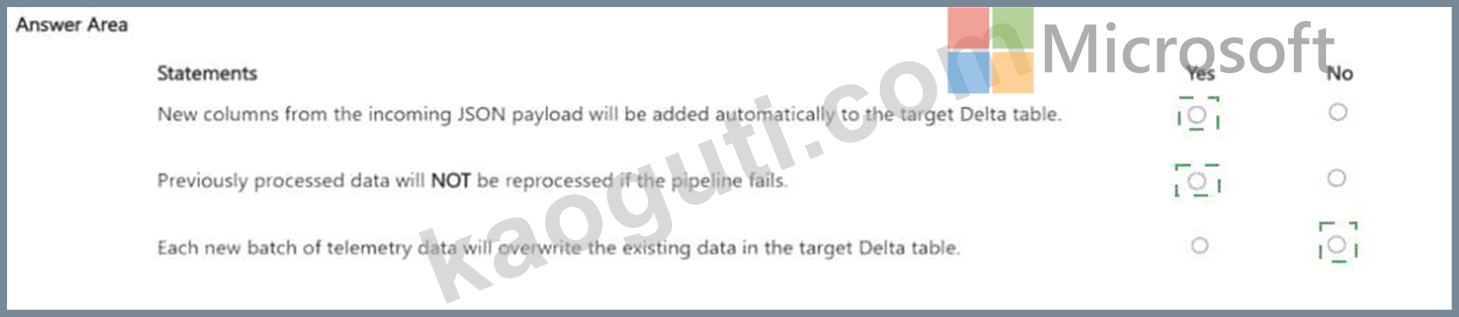
Explanation:
For HOTSPOT questions, each statement must be evaluated against the actual PySpark code shown in the answer area. Key evaluation principles:
DataFrames are immutable - every transformation returns a new DataFrame; the original is unchanged.
Transformations (filter, select, groupBy, join) are lazy and only execute when an action (show, count, write) is called.
Null handling: df.filter(col != None) is incorrect in PySpark due to SQL null semantics; use col.isNotNull() or dropna() instead. Schema changes: using mergeSchema=true or schema evolution handles new columns.
Write modes: 'overwrite' replaces existing data; 'append' adds to it.
Always check whether the code uses the correct Delta format (.format('delta')), Unity Catalog three-part naming, and whether write operations include a checkpointLocation for streaming queries. Evaluate each statement strictly on what the code does, not on what it might intend to do.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
問題 #73
......
DP-750資格認證考試是非常熱門的一項考試,雖然很難通過,但是你只要找准了切入點,考試合格並不是什麼難題。KaoGuTi就是你最好的選擇。KaoGuTi命中率高達100%的資料,可以幫你解決DP-750考試上的任何難題,只要你認真學習資料上的問題,相信一切難題都可以迎刃而解,你購買了考古題以後還可以得到一年的免費更新服務,一年之內,只要你想更新你擁有的資料,那麼你就可以得到最新版。快點來體驗一下吧。
最新DP-750考題: https://www.kaoguti.com/DP-750_exam-pdf.html