2026 Latest PracticeVCE SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=1dHFgNmiD_vp0faCuCuAi3ERt9stv5NNI
During nearly ten years, our company has kept on improving ourselves, and now we have become the leader in this field. And now our SPS-C01 training materials have become the most popular SPS-C01 practice materials in the international market. There are so many advantages of our SPS-C01 Study Materials, and as long as you free download the demos on our website, then you will know that how good quality our SPS-C01 exam questions are in! You won't regret for your wise choice if you buy our SPS-C01 learning guide!
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Snowpark API and Development | 30% | - Multi-language support
|
| Topic 2: Performance and Best Practices | 10% | - Optimization techniques
|
| Topic 3: Snowpark Concepts and Architecture | 25% | - Session management and connection
|
| Topic 4: Data Transformations and Operations | 35% | - Advanced operations
|
>> SPS-C01 Latest Exam Pattern <<
As you see, all of the three versions are helpful for you to get the SPS-C01 certification: the PDF, Software and APP online. So there is another choice for you to purchase the comprehensive version which contains all the three formats, it is the Value Pack. Besides, the price for the Value Pack is quite favorable. And no matter which format of SPS-C01 study engine you choose, we will give you 24/7 online service and one year's free updates on the SPS-C01 practice questions.
NEW QUESTION # 44
You have written a Snowpark Python function that utilizes a UDF to perform complex string manipulation on a DataFrame containing customer reviews. When deploying this function using '@sproc.test_utils.mock_snowflake environment, the test fails with a 'ModuleNotFoundError' indicating that a custom Python library (e.g., is not available. You have already confirmed that the library is installed in your local development environment. What is the MOST reliable way to ensure the UDF has access to this dependency during local testing?
Answer: D
Explanation:
Option C is the most reliable solution for local testing with . The function explicitly makes the library available to the Snowpark session during execution, simulating how dependencies are handled in the Snowflake environment. Option A might work locally, but it's not a reliable deployment strategy. Option B is a temporary workaround and not a structured solution. Option D makes the library globally available, defeating the purpose of isolating dependencies for testing. Option E is a valid approach but less explicit and may affect other Python environments on the system. Using 'add_import' ensures that the correct version and dependencies are included in the deployment package.
NEW QUESTION # 45
You are developing a Snowpark application that needs to connect to Snowflake using account identifiers. Your organization's Snowflake account is configured with federated authentication (Okta). Which of the following methods is the most secure and recommended way to establish a Snowpark session in this scenario, avoiding hardcoding credentials in your application and leveraging existing authentication mechanisms?
Answer: A
Explanation:
Using OAuth with an external identity provider like Okta is the most secure and recommended method for federated authentication. It avoids storing credentials directly in the application and leverages the organization's existing authentication mechanisms. Options A, B, and D are less secure due to the risk of exposing credentials. Option E does not address the federated authenication requirment.
NEW QUESTION # 46
You have a Snowpark DataFrame 'df with a column 'transaction_date' of STRING type, containing dates in 'YYYY-MM-DD' format, and a 'transaction_amount' column of STRING type, containing currency values like '$1 ,234.56'. You need to create a new DataFrame 'df_transformed' that contains the 'transaction_date' as a DATE type and 'transaction_amount' as a DOUBLE type. What Snowpark Python code snippet will accomplish this transformation most efficiently and handle potential errors during the cast?
Answer: E
Explanation:
Option C is the most robust because it uses and , which handle potential conversion errors by returning NULL instead of throwing exceptions. It also correctly uses 'regexp_replace' to remove both '$ and ',' from the 'transaction_amount' string before casting. Option A doesn't handle the format string for 'to_date' or special characters in amount. Option B doesnt remove special charcaters from transaction amount.Option D will not return other existing Columns, and also it doesn't handle the format string for 'to_date' or special characters in amount. Option E will not handle errors gracefully and redundantly imports 'snowflake.snowpark.functions as sf, and it also requires providing a format string for 'to_date' .
NEW QUESTION # 47
You are working with a Snowpark DataFrame called 'customer df that contains customer data, including a column named 'registration_date' of data type TIMESTAMP NTZ. You need to filter the DataFrame to only include customers who registered in the year 2023. Which of the following Snowpark code snippets represents the MOST efficient and correct way to accomplish this filtering, considering potential timezone issues?





Answer: B
Explanation:
Option C is the most efficient and accurate. It directly compares the 'registration_date' (TIMESTAMP_NTZ) to the date range using string literals, avoiding unnecessary function calls Cyear', 'to_date', 'to_varchar', that could impact performance or introduce subtle errors related to timezone conversions. Since TIMESTAMP_NTZ has no timezone, direct comparison is safe and optimal. Options A and E, while seemingly straightforward, involve function calls for each row, which can be slower. Option B uses 'like' on a date converted to string, which is less efficient and can be problematic with different date formats. Option D converts the date to a VARCHAR, which is unnecessary and impacts performance.
NEW QUESTION # 48
Consider a Snowflake table 'orders' with columns 'order_id', 'customer_id', 'order_date', and 'status'. You need to update the 'status' of all orders placed before January 1, 2023, to 'Archived'. Which of the following approaches is the most efficient and idiomatic way to achieve this using Snowpark DataFrames, assuming 'orders df DataFrame represents the 'orders' table?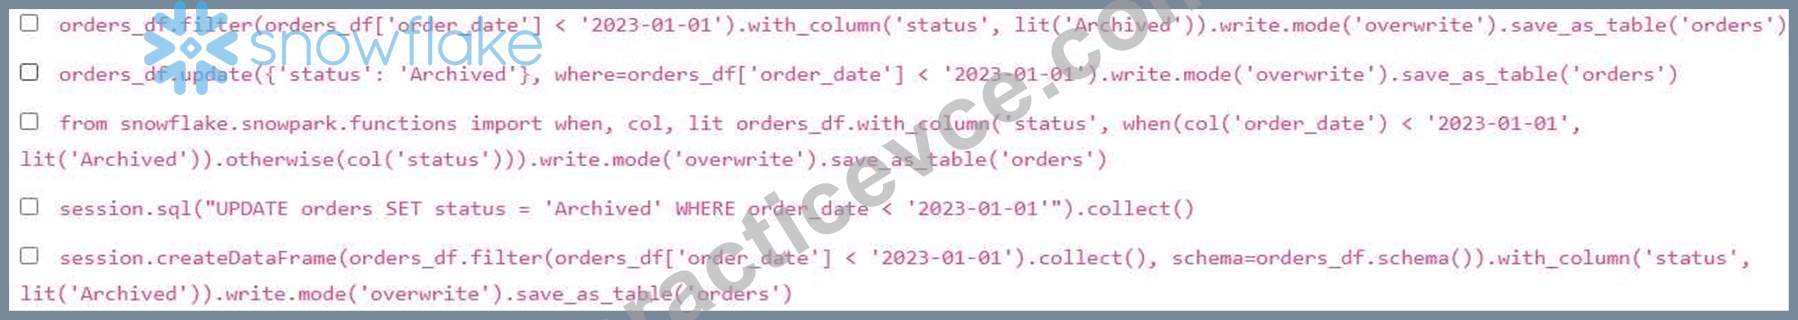
Answer: B,C
Explanation:
Options C and D are both valid and efficient solutions. Option C leverages Snowpark's 'with_column' and 'when' functions to conditionally update the 'status' column within the DataFrame and persists the changes back to the table using 'save_as_table'. Using lit function makes sure that 'Archived' status is passed as a literal. Option D uses a direct SQL update statement executed through the Snowpark session. This bypasses DataFrame operations but directly modifies the table, which can sometimes be more efficient for simple update operations. Option A is almost correct but the with_column and filter are applied separately. Option B doesn't work due to the way update functions are implemented in Snowpark. Option E unnecessarily collects the filtered data back to the driver, creating a new DataFrame from the collected data, then applying 'with_column'. This is an inefficient approach.
NEW QUESTION # 49
......
If you prefer to have your practice online, then you can choose us. SPS-C01 PDF version is printable and you can print them into hard one and take some notes on them. In addition, SPS-C01 exam dumps have free demo for you to have a try, so that you can have a deeper understanding of what you are going to buy. You can receive your download link and password within ten minutes for SPS-C01 Exam Dumps. We have online and offline chat service stuff for SPS-C01 exam materials, and if you have any questions, you can have a conversation with us, and we will give you reply as soon as we can.
SPS-C01 Reliable Test Answers: https://www.practicevce.com/Snowflake/SPS-C01-practice-exam-dumps.html
2026 Latest PracticeVCE SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=1dHFgNmiD_vp0faCuCuAi3ERt9stv5NNI