New Databricks-Machine-Learning-Professional Valid Test Notes | High Pass-Rate Databricks-Machine-Learning-Professional Exam Study Solutions: Databricks Certified Machine Learning Professional

What's more, part of that Actual4Labs Databricks-Machine-Learning-Professional dumps now are free: https://drive.google.com/open?id=1ZRMuLCJmbZHDRIQPCYvXpEoSKLnp2u0y
Perhaps you haven't heard of our company's brand yet, although we are becoming a leader of Databricks-Machine-Learning-Professional exam questions in the industry. But it doesn't matter. It's never too late to know it from now on. Our Databricks-Machine-Learning-Professional study guide may not be as famous as other brands for the time being, but we can assure you that we won't lose out on quality. We have free demos of our Databricks-Machine-Learning-Professional Practice Engine that you can download before purchase, and you will be surprised to find its good quality.
| Topic | Details |
|---|
| Topic 1 | - Identify the requirements for tracking nested runs
- Describe an MLflow flavor and the benefits of using MLflow flavors
|
| Topic 2 | - Create, overwrite, merge, and read Feature Store tables in machine learning workflows
- View Delta table history and load a previous version of a Delta table
|
| Topic 3 | - Identify live serving benefits of querying precomputed batch predictions
- Describe Structured Streaming as a common processing tool for ETL pipelines
|
| Topic 4 | - Identify that data can arrive out-of-order with structured streaming
- Identify how model serving uses one all-purpose cluster for a model deployment
|
| Topic 5 | - Describe the advantages of using the pyfunc MLflow flavor
- Manually log parameters, models, and evaluation metrics using MLflow
|
| Topic 6 | - Describe concept drift and its impact on model efficacy
- Describe summary statistic monitoring as a simple solution for numeric feature drift
|
| Topic 7 | - Identify which code block will trigger a shown webhook
- Describe the basic purpose and user interactions with Model Registry
|
| Topic 8 | - Identify a use case for HTTP webhooks and where the Webhook URL needs to come
- Identify advantages of using Job clusters over all-purpose clusters
|
| Topic 9 | - Identify JIT feature values as a need for real-time deployment
- Describe how to list all webhooks and how to delete a webhook
|
| Topic 10 | - Describe model serving deploys and endpoint for every stage
- Identify scenarios in which feature drift and
- or label drift are likely to occur
|
>> Databricks-Machine-Learning-Professional Valid Test Notes <<
Databricks-Machine-Learning-Professional Exam Study Solutions & Databricks-Machine-Learning-Professional Test Cram
For candidates who will buy the Databricks-Machine-Learning-Professional exam materials, they care more about their privacy. If you choose Databricks-Machine-Learning-Professional training materials from us, your personal information such as your name and email address will be protected well. Once the order finishes, your information will be concealed. If you choose us, you can just put your heart at rest. Besides, Databricks-Machine-Learning-Professional Exam Dumps of us have free demo for you to have a try, so that you can know the mode of the complete version. We also pass guarantee and money back guarantee if you fail to pass the exam.
Databricks Certified Machine Learning Professional Sample Questions (Q47-Q52):
NEW QUESTION # 47
A machine learning engineer needs a python_model to access a collection of files using its load_context operation. The collection of files being accessed by python_model.load_context needs to be saved when the model is being logged. A dictionary of the names and paths of these files is properly stored in my_dict.
The machine learning engineer has written the following incomplete block of code:
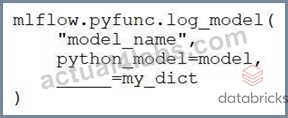
Which lines of code can be used to fill in the blank to successfully complete the code block to accomplish the task?
- A. model_context
- B. context
- C. artifacts
- D. None of these lines of code can be used to successfully complete the code block
Answer: C
Explanation:
When logging a custom Python model with mlflow.pyfunc.log_model(), the artifacts parameter is used to specify a dictionary (my_dict) of file names and their paths that the model may need to access during loading or inference. These files are stored as model artifacts and become available to the model through the load_context method.
NEW QUESTION # 48
Which of the following lists all of the model stages are available in the MLflow Model Registry?
- A. None. Staging. Production
- B. Staging. Production. Archived
- C. None. Staging. Production. Archived
- D. Development. Staging. Production
- E. Development. Staging. Production. Archived
Answer: D
NEW QUESTION # 49
A Machine Learning Engineer has automated a model retraining job in Databricks. Each scheduled run trains multiple candidate models with new sales data and logs all runs with MLflow.
The goal is to select and register the best-performing model at the end of each cycle to ensure optimal forecast accuracy. Which approach will meet this goal?
- A. Register the best model based on the primary evaluation metric.
- B. Register the first model that has an evaluation metric better than the previously deployed model.
- C. Register the model with the lowest training loss regardless of validation metrics.
- D. Register all models from the run since all of them are trained on newer data and hence will be more accurate.
Answer: A
Explanation:
Selecting and registering the model that performs best on the primary evaluation metric ensures that only the highest-quality model is promoted at each retraining cycle. This approach aligns with MLOps best practices by basing promotion decisions on objective performance criteria rather than training order or assumptions about data freshness.
NEW QUESTION # 50
A data scientist is utilizing MLflow to track their machine learning experiments. After completing a series of runs for the experiment with experiment ID exp_id, the data scientist wants to programmatically work with the experiment run data in a Spark DataFrame. They have an active MLflow Client client and an active Spark session spark. Which of the following lines of code can be used to obtain run-level results for exp_id in a Spark DataFrame?
- A. mlflow.search_runs(exp_id)
- B. client.list_run_infos(exp_id)
- C. spark.read.format("mlflow-experiment").load(exp_id)
- D. spark.read.format("delta").load(exp_id)
- E. There is no way to programmatically return row-level results from an MLflow Experiment.
Answer: D
NEW QUESTION # 51
A machine learning engineer has a machine learning pipeline where predictions are updated annually. The final prediction dataset contains millions of rows, and that dataset is irregularly accessed. Which solution should the machine learning engineer use to maintain cost efficiency?
- A. Cloud-based object storage
- B. Cloud-based in-memory instance of a Spark DataFrame
- C. Cloud-based low latency database
- D. On-premises low-latency database
Answer: A
Explanation:
For data that is large in size, infrequently accessed, and updated only periodically, cloud-based object storage (such as AWS S3, Azure Blob Storage, or Google Cloud Storage) is the most cost- efficient option. It offers durable, scalable, and inexpensive storage compared to in-memory or low-latency databases, which are optimized for frequent access and real-time performance rather than long-term, infrequent retrieval.
NEW QUESTION # 52
......
Continuous improvement is a good thing. If you keep making progress and transcending yourself, you will harvest happiness and growth. The goal of our Databricks-Machine-Learning-Professional latest exam guide is prompting you to challenge your limitations. People always complain that they do nothing perfectly. The fact is that they never insist on one thing and give up quickly. Our Databricks-Machine-Learning-Professional Study Dumps will assist you to overcome your shortcomings and become a persistent person. Once you have made up your minds to change, come to purchase our Databricks-Machine-Learning-Professional training practice.
Databricks-Machine-Learning-Professional Exam Study Solutions: https://www.actual4labs.com/Databricks/Databricks-Machine-Learning-Professional-actual-exam-dumps.html
- Accurate Databricks-Machine-Learning-Professional Valid Test Notes | Easy To Study and Pass Exam at first attempt - Authoritative Databricks-Machine-Learning-Professional: Databricks Certified Machine Learning Professional 🍗 Search for ⏩ Databricks-Machine-Learning-Professional ⏪ and download it for free on { www.examcollectionpass.com } website 🤡Databricks-Machine-Learning-Professional Pdf Exam Dump
- Databricks-Machine-Learning-Professional Excellect Pass Rate 🙄 Databricks-Machine-Learning-Professional Learning Mode 🟣 Databricks-Machine-Learning-Professional Latest Braindumps Questions 🥇 Search for [ Databricks-Machine-Learning-Professional ] and download it for free immediately on ⏩ www.pdfvce.com ⏪ 📓Test Databricks-Machine-Learning-Professional Engine
- Authoritative Databricks-Machine-Learning-Professional Valid Test Notes - Easy and Guaranteed Databricks-Machine-Learning-Professional Exam Success 🔼 Easily obtain free download of ➽ Databricks-Machine-Learning-Professional 🢪 by searching on ▛ www.troytecdumps.com ▟ 😋Databricks-Machine-Learning-Professional Reliable Source
- Easy to Use Pdfvce Databricks Databricks-Machine-Learning-Professional Practice Questions Formats 🔧 Search for ➤ Databricks-Machine-Learning-Professional ⮘ and obtain a free download on ☀ www.pdfvce.com ️☀️ 🐚Databricks-Machine-Learning-Professional Excellect Pass Rate
- Pass Guaranteed Quiz Databricks-Machine-Learning-Professional - Databricks Certified Machine Learning Professional Perfect Valid Test Notes 🍀 Easily obtain free download of 【 Databricks-Machine-Learning-Professional 】 by searching on ➠ www.troytecdumps.com 🠰 😮Databricks-Machine-Learning-Professional Pdf Exam Dump
- Best Quality Databricks Databricks-Machine-Learning-Professional Exam Questions 🥫 Easily obtain free download of 《 Databricks-Machine-Learning-Professional 》 by searching on { www.pdfvce.com } 🔱Databricks-Machine-Learning-Professional Excellect Pass Rate
- Best Quality Databricks Databricks-Machine-Learning-Professional Exam Questions ⏲ Search for ➽ Databricks-Machine-Learning-Professional 🢪 and obtain a free download on “ www.exam4labs.com ” 🍮Databricks-Machine-Learning-Professional Exam Quick Prep
- Databricks Certified Machine Learning Professional reliable practice torrent - Databricks-Machine-Learning-Professional exam guide dumps - Databricks Certified Machine Learning Professional test training vce 🔺 The page for free download of ➡ Databricks-Machine-Learning-Professional ️⬅️ on 《 www.pdfvce.com 》 will open immediately 🗻Databricks-Machine-Learning-Professional Exam Passing Score
- Best Quality Databricks Databricks-Machine-Learning-Professional Exam Questions 🏔 Search for 【 Databricks-Machine-Learning-Professional 】 on 「 www.troytecdumps.com 」 immediately to obtain a free download 🙋Latest Databricks-Machine-Learning-Professional Braindumps Free
- Databricks-Machine-Learning-Professional Reliable Braindumps Files 🆑 Reliable Databricks-Machine-Learning-Professional Test Prep ⏏ Test Databricks-Machine-Learning-Professional Engine 📗 Search for ⏩ Databricks-Machine-Learning-Professional ⏪ and obtain a free download on 【 www.pdfvce.com 】 🧥Simulation Databricks-Machine-Learning-Professional Questions
- Latest Databricks-Machine-Learning-Professional Braindumps Free 🖕 Test Databricks-Machine-Learning-Professional Engine ✡ Databricks-Machine-Learning-Professional Trustworthy Source 🍭 Download ▛ Databricks-Machine-Learning-Professional ▟ for free by simply entering ▷ www.prep4away.com ◁ website ➡Reliable Databricks-Machine-Learning-Professional Exam Book
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, forums.filatelija.lv, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
BONUS!!! Download part of Actual4Labs Databricks-Machine-Learning-Professional dumps for free: https://drive.google.com/open?id=1ZRMuLCJmbZHDRIQPCYvXpEoSKLnp2u0y