SPS-C01유효한인증시험덤프완벽한시험공부

BONUS!!! DumpTOP SPS-C01 시험 문제집 전체 버전을 무료로 다운로드하세요: https://drive.google.com/open?id=15PkTlzQcN6PRNqfmonP4jTPdCg1UcRQ1
DumpTOP의Snowflake인증 SPS-C01덤프는 몇십년간 IT업계에 종사한 전문가들이Snowflake인증 SPS-C01 실제 시험에 대비하여 제작한 시험준비 공부가이드입니다. Snowflake인증 SPS-C01덤프공부가이드로 시험준비공부를 하시면 시험패스가 쉬워집니다. 공부하는 시간도 적어지고 다른 공부자료에 투자하는 돈도 줄어듭니다. DumpTOP의Snowflake인증 SPS-C01덤프는 Snowflake인증 SPS-C01시험패스의 특효약입니다.
Snowflake SPS-C01 Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Topic 1: Data Transformations and Operations | 35% | - DataFrame manipulation
- 1. Joins, unions, set operations
- 2. Selection, projection, renaming, casting
- 3. Filtering, sorting, grouping, aggregation
- Advanced operations
- 1. Semi-structured data processing
- 2. Window functions and analytics
- 3. Pivot and unpivot transformations
- User-defined logic
- 1. UDFs, UDAFs, UDTFs
- 2. Stored procedures with Snowpark
|
| Topic 2: Snowpark Concepts and Architecture | 25% | - Snowpark architecture and execution model
- 1. Lazy evaluation and DAG execution
- 2. Client-side vs server-side processing
- 3. Transformations vs actions
- Session management and connection
- 1. Authentication and connection settings
- 2. Create and configure Snowpark sessions
|
| Topic 3: Performance and Best Practices | 10% | - Optimization techniques
- 1. Query pushdown and execution plans
- 2. Minimizing data movement
- 3. Caching and warehouse sizing
- Security and governance
- 1. Access control and permissions
- 2. Data protection and compliance
|
| Topic 4: Snowpark API and Development | 30% | - Multi-language support
- 1. Environment setup and dependencies
- 2. Java and Scala API basics
- Python API fundamentals
- 1. DataFrame creation from tables, views, SQL
- 2. Data persistence and writing results
- 3. Column operations and functions
|
>> SPS-C01유효한 인증시험덤프 <<
SPS-C01유효한 인증시험덤프최신버전 인증공부
DumpTOP에서는 Snowflake인증 SPS-C01시험을 도전해보시려는 분들을 위해 퍼펙트한 Snowflake인증 SPS-C01덤프를 가벼운 가격으로 제공해드립니다.덤프는Snowflake인증 SPS-C01시험의 기출문제와 예상문제로 제작된것으로서 시험문제를 거의 100%커버하고 있습니다. DumpTOP제품을 한번 믿어주시면 기적을 가져다 드릴것입니다.
최신 Snowflake Certification SPS-C01 무료샘플문제 (Q293-Q298):
질문 # 293
You are using Snowpark Python to process a large dataset. You need to persist a DataFrame to a Snowflake table but want to ensure the operation is as efficient as possible and minimizes the data transfer overhead. The table already exists with the appropriate schema. Which of the following strategies would be the MOST efficient way to write the DataFrame to the existing table?
- A. Use 'df.write.insertlnto('existing_table')'.
- B. Use with the default save mode (which is 'append').
- C. Use 'df.write.mode('overwrite').saveAsTable('existing_table'Y.
- D. Write the DataFrame to a stage location as Parquet files and then use a 'COPY INTO existing_table FROM command.
- E. Create a temporary table, load the DataFrame into it using , and then use a 'CREATE OR REPLACE TABLE AS SELECT FROM temp_table' statement.
정답:A
설명:
is generally the most efficient method for appending data to an existing Snowflake table using Snowpark. It directly inserts the data into the table without the overhead of creating a new table or overwriting the existing one. with the default 'append' mode (A) might work, but 'insertlnto' is more explicit and potentially optimized for this specific scenario. (B) would replace the entire table, which is not efficient if you only want to add new data. Creating a temporary table and then using 'CREATE OR REPLACE TABLE AS SELECT (D) involves unnecessary steps and data transfer. Writing to a stage and then using 'COPY INTO' (E) is also less efficient than directly inserting the data using Snowpark.
질문 # 294
You have a Snowpark Python stored procedure that reads data from a Snowflake table, performs a complex calculation using Pandas, and then writes the results back to another Snowflake table. You are experiencing performance issues, and you suspect the data transfer between Snowpark and Pandas is a bottleneck. Which of the following techniques could significantly improve the performance of this stored procedure? (Select two)
- A. Use the 'TABLE function in Snowpark to directly access the source table instead of reading the entire table into a Snowpark DataFrame at once.
- B. Convert the Pandas DataFrame to a Dask DataFrame for distributed computation.
- C. Increase the warehouse size to the largest possible value before executing the stored procedure.
- D. Leverage Snowpark's optimized functions and UDFs wherever possible to perform transformations within Snowflake's engine instead of transferring data to Pandas.
- E. Utilize vectorized operations within Pandas to minimize explicit looping and improve calculation speed.
정답:D,E
설명:
Options B and D are the most effective. Vectorized operations (B) significantly speed up Pandas calculations. Performing transformations within Snowflake (D) avoids unnecessary data transfer between Snowpark and Pandas, reducing the bottleneck. A is useful, but secondary. C only affects Snowflake side processing, but it may help. E would be useful, but not as helpful as pushing as much as possible down to Snowflake processing.
질문 # 295
You have a Snowpark application processing streaming data from an event table. You observe that the application frequently fails with transient errors related to network connectivity or Snowflake service unavailability. You want to implement a robust error handling strategy to ensure the application can recover from these transient failures without losing data'. Which of the following approaches would be MOST appropriate and effective in this scenario, ensuring idempotent processing?
- A. Utilize Snowpark's 'cache()' method to cache the intermediate DataFrame results in memory, reducing the impact of transient failures.
- B. Implement exponential backoff and jitter in your retry logic when catching exceptions during Snowpark operations. Store the last successfully processed event ID in a metadata table and resume processing from that point after a retry. Ensure all operations are idempotent.
- C. Implement a try-except block around the Snowpark DataFrame operations, logging the error and retrying the entire application from the beginning upon failure.
- D. Use Snowflake's built-in retry mechanism for SQL queries by setting the 'CLIENT_SESSION PARAMETER to a non-zero value.
- E. Implement a message queue (e.g., Kafka, SQS) to buffer the incoming event data. The Snowpark application consumes data from the queue, allowing for retries and ensuring no data is lost during transient failures.
정답:B,E
설명:
Implementing a message queue provides a buffer that isolates the Snowpark application from transient data source failures. E is correct because adding an exponential backoff mechanism with jitter is crucial to prevent overwhelming the system with retries and helps to ensure idempotent processing. Option B can address some internal Snowflake errors, but not connectivity issues. The other approaches do not address data loss or idempotent operation.
질문 # 296
You are developing a Snowpark stored procedure in Python that utilizes the 'requests' library to fetch data from an external API. Your Snowflake account is configured to use Anaconda packages. You encounter an error indicating that the 'requests' library is not found. Which of the following steps are MOST effective in ensuring the 'requests' library is available to your stored procedure?
- A. Enable Anaconda integration for your Snowflake account, ensuring 'requests' is available in the Snowflake Anaconda channel, and then create the stored procedure using 'imports=['snowflake://packages/requests/']'.
- B. Specify the 'requests library in the stored procedure's 'packages argument during creation: 'CREATE OR REPLACE PROCEDURE
- C. Include the 'requests' library directly in the stored procedure code using a base64 encoded string.
- D. Install the 'requestS library directly onto the Snowflake compute nodes using SnowSQL's command.
- E. Manually upload the 'requests' library's ' .py' files to an internal stage and import them within the stored procedure.
정답:B
설명:
The 'packages' argument in the 'CREATE OR REPLACE PROCEDURE statement is the correct way to specify dependencies on Anaconda packages. Snowflake will automatically resolve and make these packages available to the stored procedure. Option B is incomplete; while Anaconda integration is necessary, it doesn't automatically import the library. Options A, C and E are incorrect and not best practices.
질문 # 297
Consider the following Snowpark Python code snippet that defines and applies a UDF:
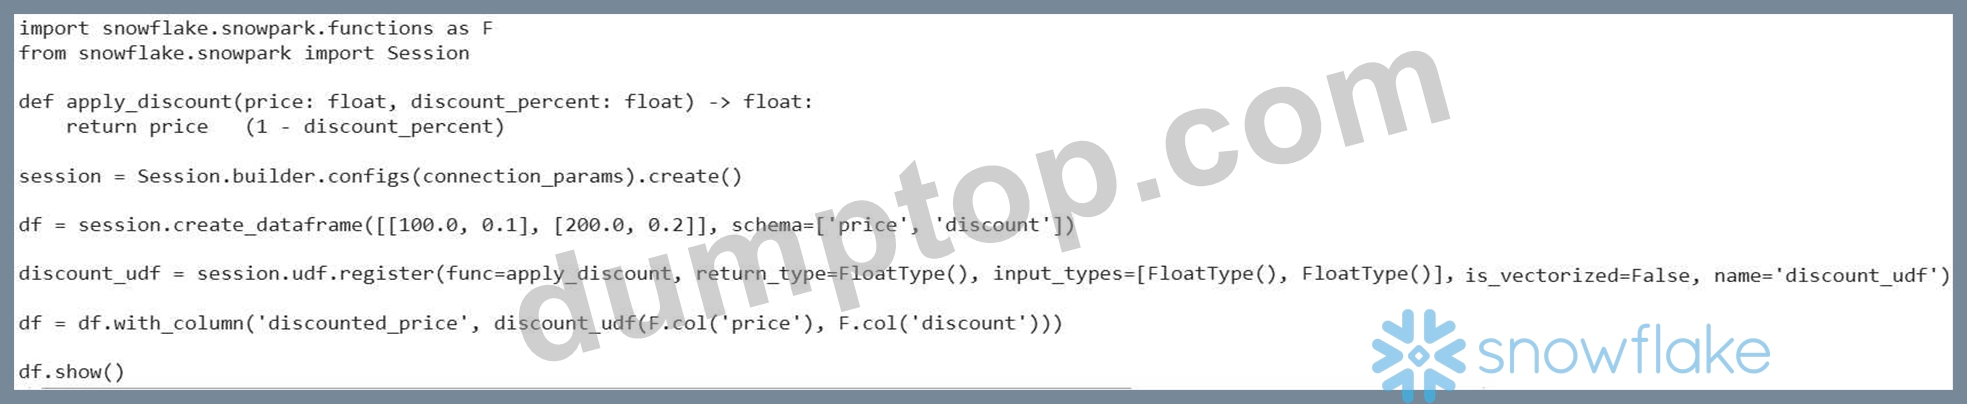
Which of the following modifications would MOST likely improve the performance of this code, assuming the DataFrame 'df contains a large number of rows?
- A. Specify a different warehouse size when creating the Snowpark session using 'session = Session.builder.config('warehouse', 'XLARGE').configs(connection_params).create()'.
- B. Use and F.lit(0.2Y instead of 0.1 and 0.2 while creating the dataframe.
- C. Change to in the "session.udf.register' call, ensuring the function is updated to handle batches of data.
- D. Rewrite the 'apply_discount' function to use NumPy arrays internally for vectorized calculations, ensuring compatibility with vectorized UDF execution. The function signature will also need to accept arrays.
- E. Remove the 'input_types' argument from 'session.udf.register' . Snowflake can automatically infer the input types.
정답:C,D
설명:
Setting tells Snowpark to treat the UDF as a vectorized UDE However, simply setting the flag is not sufficient. E is also required because Vectorized UDF requires functions that accept and process arrays as inputs, not single scalar values. The function needs to be modified to handle arrays using NumPy or similar libraries. The code also need to be rewritten to work with arrays. B has nothing to do with performance. Increasing Warehouse size might help but not on the scale of vectorization.
질문 # 298
......
DumpTOP Snowflake SPS-C01덤프의 질문들과 답변들은 100%의 지식 요점과 적어도 98%의 시험 문제들을 커버하는,수년동안 가장 최근의Snowflake SPS-C01시험 요점들을 컨설팅 해 온 시니어 프로 IT 전문가들의 그룹에 의해 구축 됩니다. DumpTOP의 IT전문가들이 자신만의 경험과 끊임없는 노력으로 최고의Snowflake SPS-C01학습자료를 작성해 여러분들이Snowflake SPS-C01시험에서 패스하도록 도와드립니다.
SPS-C01참고덤프: https://www.dumptop.com/Snowflake/SPS-C01-dump.html
- SPS-C01유효한 인증시험덤프 최신 인기 인증 시험덤프 🏠 지금[ kr.fast2test.com ]에서《 SPS-C01 》를 검색하고 무료로 다운로드하세요SPS-C01예상문제
- 시험패스 가능한 SPS-C01유효한 인증시험덤프 덤프데모문제 보기 🐵 ✔ www.itdumpskr.com ️✔️웹사이트에서➽ SPS-C01 🢪를 열고 검색하여 무료 다운로드SPS-C01완벽한 시험공부자료
- SPS-C01최신 업데이트 시험덤프 😏 SPS-C01퍼펙트 덤프 최신 데모 🍪 SPS-C01시험대비덤프 ✊ 무료 다운로드를 위해{ SPS-C01 }를 검색하려면▶ kr.fast2test.com ◀을(를) 입력하십시오SPS-C01시험대비 덤프자료
- SPS-C01 100%시험패스 공부자료 🎀 SPS-C01시험준비 ⬇ SPS-C01최신 시험 최신 덤프자료 🚌 「 www.itdumpskr.com 」웹사이트에서《 SPS-C01 》를 열고 검색하여 무료 다운로드SPS-C01시험대비 최신 공부자료
- SPS-C01시험응시 🍮 SPS-C01시험대비 최신 공부자료 📳 SPS-C01퍼펙트 덤프 최신버전 💼 ▛ www.passtip.net ▟웹사이트에서➡ SPS-C01 ️⬅️를 열고 검색하여 무료 다운로드SPS-C01예상문제
- SPS-C01최신 시험덤프자료 🕋 SPS-C01시험대비 덤프자료 💇 SPS-C01최신 시험 최신 덤프자료 📋 ➡ www.itdumpskr.com ️⬅️웹사이트를 열고➤ SPS-C01 ⮘를 검색하여 무료 다운로드SPS-C01시험패스 가능한 인증공부자료
- 최신 업데이트된 SPS-C01유효한 인증시험덤프 시험덤프 🔥 무료 다운로드를 위해【 SPS-C01 】를 검색하려면▷ www.pass4test.net ◁을(를) 입력하십시오SPS-C01시험준비
- 시험대비 SPS-C01유효한 인증시험덤프 최신버전 덤프데모 문제 🌺 「 SPS-C01 」를 무료로 다운로드하려면➥ www.itdumpskr.com 🡄웹사이트를 입력하세요SPS-C01퍼펙트 덤프 최신버전
- SPS-C01완벽한 시험공부자료 🪓 SPS-C01합격보장 가능 덤프 📶 SPS-C01완벽한 시험공부자료 🖐 ▶ www.itdumpskr.com ◀에서➥ SPS-C01 🡄를 검색하고 무료로 다운로드하세요SPS-C01적중율 높은 덤프자료
- 시험패스 가능한 SPS-C01유효한 인증시험덤프 덤프 최신 샘플 🏳 ⮆ www.itdumpskr.com ⮄의 무료 다운로드【 SPS-C01 】페이지가 지금 열립니다SPS-C01퍼펙트 최신 덤프공부
- 시험패스 가능한 SPS-C01유효한 인증시험덤프 덤프 최신 샘플 ⏹ 무료 다운로드를 위해▷ SPS-C01 ◁를 검색하려면▷ www.koreadumps.com ◁을(를) 입력하십시오SPS-C01 100%시험패스 공부자료
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
참고: DumpTOP에서 Google Drive로 공유하는 무료, 최신 SPS-C01 시험 문제집이 있습니다: https://drive.google.com/open?id=15PkTlzQcN6PRNqfmonP4jTPdCg1UcRQ1